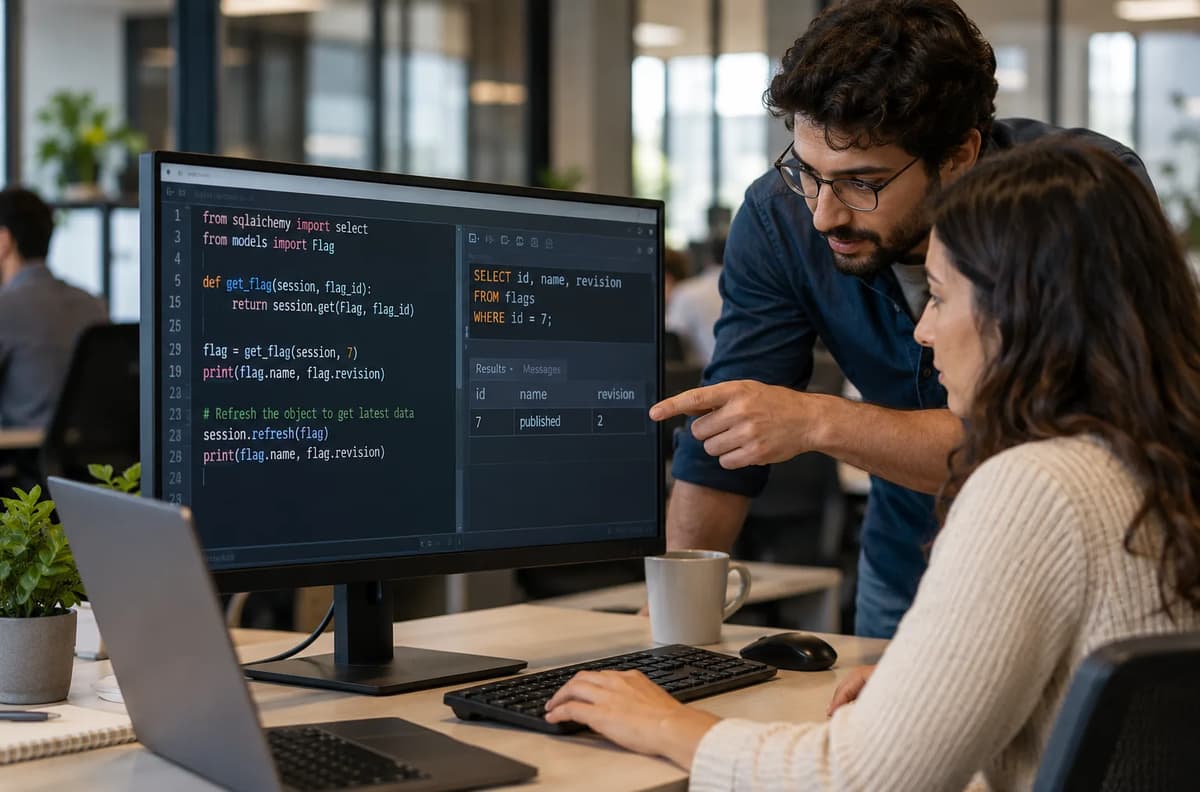
A database row can be provably committed, a fresh scalar query can return the new revision, and the ORM object your caller still holds can nevertheless show the earlier values. That is the operational shape of SQLAlchemy stale objects that this article qualifies. The discrepancy is not evidence that the database ignored the update, nor that the SELECT failed. It can be the normal consequence of an identity-mapped object retaining already-loaded attributes while a later ORM query matches the same database identity. SQLAlchemy 2.0 documents that a Session maintains one object per identity and that ordinary ORM loading generally does not overwrite already-populated state unless an explicit refresh mechanism is requested.
The repair therefore starts with evidence, not with another arbitrary query. We need three separate observations: the committed row seen independently, the values returned by the candidate SQL or scalar read, and the attributes on the exact Python object reference that downstream code will use. Only then can we decide whether to refresh a clean object, stop because pending work belongs to someone else, or deliberately replace the reference.
The supplied sequential laboratory fixes that question to CPython 3.12.14, SQLAlchemy 2.0.55 and linked SQLite 3.53.1, using owned temporary files and no overlapping reader/writer transactions. SQLAlchemy’s 2.0 documentation currently identifies 2.0.55 as the October 16, 2026 maintenance release in the 2.0 documentation family; it is not presented here as the newest SQLAlchemy release across branches. The primary contracts checked on October 28, 2026 were SQLAlchemy 2.0.55 Session Basics, State Management, ORM API Features for Querying, Session API, and the SQLite dialect documentation. A local ACCEPT_REFRESHED_READ proves only that the tested caller reference was repaired under this controlled visibility boundary.
Identify the object whose freshness matters
Before selecting a refresh API, name the object whose values must be current. In the fixture, that object is the original Flag instance loaded by the reader as primary key 7. Call it old. The committed baseline is (7, 'baseline', 1), and the writer later commits (7, 'published', 2). The critical downstream question is not “did some query somewhere return revision 2?” It is “what attributes are on the exact reference the caller will dereference after the repair?”
A reviewer should identify four roles explicitly: the reader Session, the independent writer, the owner of pending ORM state, and the downstream caller retaining or receiving the reference. SQLAlchemy’s guidance frames Session objects around a transactional workspace and identity map; Session.get() is specifically optimized around that map.
For this article, the operational decisions are deliberately narrow. ACCEPT_REFRESHED_READ means the exact retained object under test now carries the published scalar state after an owned refresh path. REPAIR means the attempted read did not repair that retained reference. HOLD_PENDING_WORK means local changes exist and the refresh must not decide their fate. ACCEPT_NEW_OBJECT_ONLY means a different object is current, but the caller must receive that different reference. These decisions are about object lifecycle ownership, not universal database freshness.
For broader prerequisites around persistence boundaries and API/data-layer reasoning, see Refonte Learning’s backend persistence foundations. That page discusses persistence layers generally; this article stays on the narrower identity-map refresh problem.
Separate a committed row from a populated ORM object
An identity map does not mean SQLAlchemy caches arbitrary query results. SQLAlchemy’s Session Basics documentation says the identity map stores objects by primary key, while an ordinary query still has to issue SQL, obtain rows, and then reconcile returned identities with objects already present in the map. It explicitly distinguishes this from query caching.
The ORM Querying Guide says mapped objects are normally loaded once; when a later row has the same primary key, it is ordinarily not re-applied to the existing object. populate_existing=True is the explicit override that refreshes matching instances.
So “the SELECT ran” and “the object was repopulated” are different assertions. A scalar-column SELECT can prove what the database returned without asking SQLAlchemy to populate an entity instance. An ORM SELECT can match a row and return the already-existing Python instance. That instance can still expose the values loaded earlier if it was not expired and no refresh/populate-existing mechanism replaced its attributes. This explains why a SQLAlchemy SELECT can appear to return old values: the SQL is not necessarily old; the object attributes may be.
Do not mix this with a missing-write diagnosis. Refonte Learning’s separate article on JSON mutation tracking failures deals with changes that may never reach the database. Here the laboratory first proves that the independent observer sees the committed revision, so the writer side is already established.
Track database values and Python attributes separately
The acceptance ledger has three layers.
Evidence layer | What it answers | Required value in this fixture |
Independent committed-row observation | Did another connection observe the writer’s committed row? | (7, 'published', 2) |
Candidate SQL/scalar result | What did the reader-side SQL actually return? | Where measured, (7, 'published', 2) |
Held object attributes | What does the exact retained Python object expose? | Depends on the candidate path |
The baseline constants are declared before any query output is collected: BASE = (7, 'baseline', 1) and PUBLISHED = (7, 'published', 2). That matters because a test should not derive its expected value from the same result it is validating.
Python object identity is a separate dimension again. found is old proves that SQLAlchemy returned the same Python instance; it does not prove the instance is fresh. Conversely, newer is not old proves a reference change, not that the old object was repaired. The ORM object identity versus database row distinction is therefore something to record, not infer from a successful query call.
Freeze the runtime and the transaction timeline
The supplied execution record fixes CPython 3.12.14, SQLAlchemy 2.0.55, linked SQLite 3.53.1, Linux x86_64/glibc 2.39, one owned temporary file per case, autoflush=False, and connect_args={'autocommit': False}. SQLAlchemy documents the latter as the direct Python 3.12+ route to modern sqlite3 transaction control; ORM autoflush is a separate ORM layer.
Ten cases use expire_on_commit=False; S07 alone uses the default-style commit expiration control with expire_on_commit=True. SQLAlchemy documents that commit normally expires attached objects so that subsequent access can load state in a new transaction, and that setting expire_on_commit=False disables this automatic expiration. That is why disabling commit-time expiration can leave stale attributes in this fixture: disabling expiration allows already-loaded attributes to survive the owned transaction boundary.
The fixture keeps a strong Python reference to old for the duration of each case. SQLAlchemy notes that Session identity-map references are weak by default, so this experiment should not be generalized to an object that has been garbage-collected and then reconstructed later.
For a different problem involving an active WAL reader whose snapshot predates a competing commit, see SQLite snapshot retry boundaries. That article’s transaction-lifetime issue is deliberately excluded here. SQLAlchemy likewise cautions that expire() or refresh() cannot be assumed to reveal externally changed data when the active database transaction’s isolation rules do not make that data visible.
End the old read before starting the writer
The transaction order is the most important control in the laboratory:
The reader loads Flag(7) and verifies baseline attributes.
The reader calls commit() and asserts not reader.in_transaction().
Only then does the independent writer transaction update label='published' and revision=2 and commit.
A separate observer connection reads the row and must see PUBLISHED.
Only after that proof does the candidate reader trace begin.
SQLAlchemy documents that a Session transaction begins on use through autobegin and that in_transaction() reports whether transactional state is active. It also documents that commit closes the current transaction and, unless disabled, expires associated objects.
This ordering removes the old-reader-snapshot explanation from the supplied cases: the original read transaction ends before the writer starts. It does not prove that refresh() universally bypasses an active snapshot on every database. SQLAlchemy explicitly warns that refresh and expiration still operate within the Session’s current transactional context. Nor does the ordering justify committing a shared Session merely to obtain fresher values. Commit is a transaction-owner action and, as SQLAlchemy documents, unconditionally performs a flush before COMMIT when pending changes exist.
Run the complete eleven-case laboratory
The fixture below is the complete supplied test. Save it as sqlalchemy_identity_fixture.py. The source hash recorded for the supplied execution is 7b12342299b034aebd8b5e9d934f8c56443b5d40965e09ace7a5b44a24f6cbe2.
"""Owned sequential ORM read-refresh experiment; no production database."""
import hashlib, json, platform, sqlite3, tempfile
from datetime import datetime, timezone
from pathlib import Path
import sqlalchemy as sa
from sqlalchemy.orm import DeclarativeBase, Session, mapped_column

BASE = (7, 'baseline', 1)
PUBLISHED = (7, 'published', 2)

def require(ok, message):
    if not ok:
        raise AssertionError(message)

class Base(DeclarativeBase):
    pass

class Flag(Base):
    tablename = 'flags'
    id = mapped_column(sa.Integer, primary_key=True)
    label = mapped_column(sa.String, nullable=False)
    revision = mapped_column(sa.Integer, nullable=False)

class PendingState(RuntimeError):
    pass

def guarded_refresh(session, obj):
    if session.new or session.dirty or session.deleted:
        raise PendingState('Resolve pending ORM work before refresh')
    session.refresh(obj)

def values(obj):
    return (obj.id, obj.label, obj.revision)

def case(identity, operation, expire_on_commit=False):
    with tempfile.TemporaryDirectory(prefix='identity-refresh-') as td:
        engine = sa.create_engine('sqlite:///' + str(Path(td) / 'owned.db'),
                                  connect_args={'autocommit': False})
        try:
            Base.metadata.create_all(engine)
            with engine.begin() as seed:
                seed.execute(sa.insert(Flag), dict(id=7, label='baseline', revision=1))
            with Session(engine, expire_on_commit=expire_on_commit,
                         autoflush=False) as reader:
                old = reader.get(Flag, 7)
                require(values(old) == BASE, identity + ' baseline')
                reader.commit()  # End the original read transaction first.
                require(not reader.in_transaction(), identity + ' boundary')
                with engine.begin() as writer:
                    writer.execute(sa.update(Flag).where(Flag.id == 7)
                                   .values(label='published', revision=2))
                with engine.connect() as observer:
                    observed = tuple(observer.execute(
                        sa.select(Flag.id, Flag.label, Flag.revision)).one())
                require(observed == PUBLISHED, identity + ' committed writer')
                trace = []
                def log(conn, cursor, statement, parameters, context, many):
                    trace.append({'sql': statement, 'parameters': repr(parameters)})
                sa.event.listen(engine, 'before_cursor_execute', log)
                row = {'case': identity, 'operation': operation,
                       'committed_observer': observed,
                       'expire_on_commit': expire_on_commit}
                try:
                    if operation == 'get':
                        found = reader.get(Flag, 7)
                        require(found is old and values(found) == BASE, identity)
                        require(not trace, identity + ' get unexpectedly queried')
                        row.update(object=values(found), same_object=True, decision='REPAIR')
                    elif operation == 'select':
                        found = reader.scalars(sa.select(Flag).where(Flag.revision == 2)).one()
                        scalar = tuple(reader.execute(sa.select(
                            Flag.id, Flag.label, Flag.revision).where(Flag.id == 7)).one())
                        require(found is old and values(found) == BASE and scalar == PUBLISHED,
                                identity + ' identity-map distinction')
                        row.update(object=values(found), scalar_row=scalar,
                                   same_object=True, decision='REPAIR')
                    elif operation in {'refresh', 'populate', 'expire', 'get_populate',
                                       'default_expiration'}:
                        if operation == 'refresh':
                            guarded_refresh(reader, old)
                        elif operation == 'populate':
                            found = reader.scalars(sa.select(Flag).where(Flag.id == 7)
                                .execution_options(populate_existing=True)).one()
                            require(found is old, identity + ' identity changed')
                        elif operation == 'expire':
                            reader.expire(old)
                            require(not trace, identity + ' expire unexpectedly queried')
                            row['queries_before_attribute_access'] = 0
                        elif operation == 'get_populate':
                            require(reader.get(Flag, 7, populate_existing=True) is old, identity)
                        current = values(old)
                        require(current == PUBLISHED, identity + ' stale refresh')
                        row.update(object=current, decision='ACCEPT_REFRESHED_READ')
                    elif operation == 'dirty_populate':
                        old.label = 'local-draft'
                        row['pending_before'] = values(old)
                        require(old in reader.dirty, identity + ' no pending state')
                        reader.scalars(sa.select(Flag).where(Flag.id == 7)
                            .execution_options(populate_existing=True)).one()
                        require(values(old) == PUBLISHED, identity + ' draft not discarded')
                        row.update(object=values(old), decision='REJECT_UNOWNED_DISCARD')
                    elif operation == 'guard_dirty':
                        old.label = 'local-draft'
                        try:
                            guarded_refresh(reader, old)
                        except PendingState as error:
                            row['error'] = type(error).__name__
                        else:
                            raise AssertionError(identity + ' guard accepted pending edit')
                        require(old.label == 'local-draft' and not trace, identity)
                        row.update(object=values(old), decision='HOLD_PENDING_WORK')
                    elif operation == 'new_session':
                        with Session(engine, autoflush=False) as fresh:
                            newer = fresh.get(Flag, 7)
                            require(newer is not old and values(newer) == PUBLISHED, identity)
                            row['new_object'] = values(newer)
                        require(values(old) == BASE, identity + ' old reference changed')
                        row.update(old_object=values(old), same_object=False,
                                   decision='ACCEPT_NEW_OBJECT_ONLY')
                    elif operation == 'expunge':
                        reader.expunge(old)
                        newer = reader.get(Flag, 7)
                        require(newer is not old and values(newer) == PUBLISHED,
                                identity + ' expunge reload')
                        require(values(old) == BASE, identity + ' detached reference changed')
                        row.update(old_object=values(old), new_object=values(newer),
                                   detached_old=sa.inspect(old).detached,
                                   decision='REPAIR_REFERENCE_HANDOFF')
                    else:
                        raise ValueError(operation)
                    require(not any(x['sql'].lstrip().upper().startswith(
                            ('UPDATE', 'INSERT', 'DELETE')) for x in trace),
                            identity + ' read path emitted DML')
                    row['sql_trace'] = list(trace)
                    row['select_count'] = sum(x['sql'].lstrip().upper().startswith('SELECT')
                                              for x in trace)
                    row['status'] = 'PASS'
                finally:
                    sa.event.remove(engine, 'before_cursor_execute', log)
            with engine.connect() as final:
                require(tuple(final.execute(sa.select(Flag.id, Flag.label,
                        Flag.revision)).one()) == PUBLISHED, identity + ' final row changed')
            return row
        finally:
            engine.dispose()

if name == '__main__':
    started = datetime.now(timezone.utc).isoformat()
    actions = ['get', 'select', 'refresh', 'populate', 'expire', 'get_populate',
               'default_expiration', 'dirty_populate', 'guard_dirty',
               'new_session', 'expunge']
    rows = [case('S%02d' % (i+1), op, op == 'default_expiration')
            for i, op in enumerate(actions)]
    require(len(rows) == 11, 'Incomplete inventory')
    print(json.dumps({'status': 'PASS_11_CASES', 'started_utc': started,
        'finished_utc': datetime.now(timezone.utc).isoformat(),
        'python': platform.python_version(), 'sqlalchemy': sa.__version__,
        'sqlite': sqlite3.sqlite_version, 'platform': platform.platform(),
        'driver_autocommit': False, 'session_autoflush': False,
        'source_sha256': hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
        'cases': rows}, indent=2))
Reproduce it only in a new owned environment. The declared run used the stated Python version; installing SQLAlchemy does not install or pin the SQLite library embedded in that interpreter. The script records sqlite3.sqlite_version precisely so that distinction is visible.
python -m venv .venv
. .venv/bin/activate
python -m pip install SQLAlchemy==2.0.55
python sqlalchemy_identity_fixture.py > sqlalchemy-results.json
Before comparing a new result with the supplied ledger, verify the JSON manifest, source SHA-256 and full case inventory. SQLAlchemy’s documentation confirms the 2.0.55 release date as October 16, 2026; the supplied experiment is dated October 28, 2026.
The supplied run completed with PASS_11_CASES: all eleven declared assertions held, including negative controls. S08 passes because it demonstrates unsafe discard; S09 passes because the guard refuses to query and preserves the draft.
Each case owns its temporary directory and database file. Setup creates the schema and seed row, the independent writer performs the committed update, and teardown disposes the engine. The SQL listener is intentionally attached only after the independent observer has proven PUBLISHED. Accordingly, the recorded candidate traces should not be misread as traces of the entire fixture. Setup and writer DML happen before the measured reader trace.
A new execution is a new observation. If its source hash, runtime manifest, case count or assertions differ, do not silently substitute the supplied expected result. Treat an incomplete inventory, setup failure or assertion failure as HOLD until the discrepancy is explained. The supplied record supports the decisions below only for the declared sequential environment.
Observe when Session.get emits no SQL
S01 isolates the cached-object path through Session.get(). The reader already holds an unexpired instance for primary key 7, and expire_on_commit=False allowed its baseline attributes to survive the transaction boundary. After the external writer commits, reader.get(Flag, 7) returns the same old object, preserves (7, 'baseline', 1), and emits zero measured SELECTs.
That observation matches the documented Session.get() contract. SQLAlchemy states that get() first looks directly in the local identity map and, when the requested identity is present and not fully expired, returns that object without emitting SQL. If the object is absent, or present but expired, get() may issue a SELECT. Therefore, “get() uses no SQL” is not a universal rule; it is conditional on identity-map presence and expiration state.
This is why S01 is REPAIR, not a database-freshness failure. The candidate did exactly what the API is designed to do. It answered “give me the Session’s current instance for primary key 7,” not “force the database to repopulate that instance.” The forced-loading form, get(..., populate_existing=True), is evaluated separately in S06.
Capture the query boundary without changing the experiment
The trace listener begins after the writer commit and after the independent observer validates (7, 'published', 2). Thus S01’s zero count means zero candidate-path SELECTs, not zero SQL statements in the whole case.
That measurement boundary matters when reproducing the test. Accessing an expired attribute for logging, repr() output or ad hoc debugging can itself trigger a load and contaminate the intended count. SQLAlchemy documents that expired column attributes load on access.
In production diagnostics, capture statement class, timing boundary and parameter shape only to the degree operationally necessary. Do not turn this laboratory’s verbose trace into a prescription to log sensitive customer values. The experiment needs enough SQL evidence to distinguish “no query” from “query ran”; it does not require business data disclosure.
Explain the SELECT that still returns old attributes
S02 is the core discrepancy between database values and identity-mapped object state. The reader executes an ORM SELECT filtered by Flag.revision == 2. The database matches the published row. Yet reader.scalars(...).one() resolves that row to the identity already present in the Session, so found is old and values(found) remains (7, 'baseline', 1).
Immediately afterward, the same reader executes a scalar-column SELECT for Flag.id, Flag.label and Flag.revision. That result is (7, 'published', 2). Two measured SELECTs therefore produce two distinct evidence forms: the ORM entity query returns the existing Python identity with old attributes, while the scalar row exposes the published database values.
This behavior is directly aligned with SQLAlchemy’s documentation. Session Basics says ordinary queries still issue SQL, then reconcile returned primary keys against the local identity map. The ORM Querying Guide adds that, by default, a subsequent result row for an already-loaded identity is not applied to that object. The identity map is not a server-side query-result cache, and S02 gives no reason to diagnose one.
The important operational conclusion is precise: a fresh ORM SELECT can establish that a row matches the predicate without establishing that the retained object’s already-loaded attributes were replaced. A scalar SELECT can prove what the reader transaction sees at the SQL-value layer while the held instance remains stale at the Python-object layer.
A SQL predicate does not rewrite an existing instance
Conceptually, the measured operations are equivalent to these two statements:
SELECT flags.id, flags.label, flags.revision
FROM flags
WHERE flags.revision = 2;

SELECT flags.id, flags.label, flags.revision
FROM flags
WHERE flags.id = 7;
The first is consumed as an ORM entity result. The second is consumed as scalar columns. In S02, both SQL operations can observe the published row, yet only the scalar result is represented directly as returned values. The ORM path resolves the primary key to old and leaves its existing attributes intact because no population override is requested.
That is why a predicate such as revision == 2 should not be used as proof that obj.revision has become 2. The predicate qualifies rows; object population is a separate ORM lifecycle decision. When diagnosing a SQLAlchemy SELECT that appears to return old values, inspect both layers instead of assuming the database returned stale columns.
Refresh a clean object through an owned path
For a clean instance whose owner authorizes replacement of loaded state, three cases produce the published attributes on the same retained object.
S03 calls the fixture’s guarded_refresh(reader, old). Because the Session has no pending new, dirty or deleted objects in this case, the guard calls Session.refresh(old). SQLAlchemy documents that refresh() emits an immediate SELECT and reloads the object; the supplied trace measures one SELECT, after which values(old) == PUBLISHED. This is the clearest way to refresh an existing SQLAlchemy instance when the target is one known object and the caller must keep that exact reference.
S04 performs an ORM SELECT with .execution_options(populate_existing=True). SQLAlchemy documents this ORM-level option as forcing matching instances to be refreshed from result rows. In the supplied case, found is old remains true and one SELECT produces the published attributes. This path is useful when the refresh should be expressed as part of a query that selects the objects to repopulate.
S06 uses reader.get(Flag, 7, populate_existing=True). The Session API documents that this form unconditionally emits SQL and refreshes the object even if it is already present in the identity map. The fixture again measures one SELECT and the same retained object becomes PUBLISHED.
These three local results do not establish a latency ranking, nor do they make a blanket “refresh helper” safe. The choice is semantic. Use refresh() when one owned, clean instance must be immediately reloaded. Use populate_existing on an ORM statement when query selection itself defines the refresh set. Use get(..., populate_existing=True) when the target is a known primary key and the caller wants get() semantics plus forced repopulation. In every case, visibility is still bounded by the Session’s active transaction.
Decide when expiration should perform the load
S05 separates invalidation from loading. reader.expire(old) marks the mapped attributes as expired and, by itself, emits no measured SQL. The fixture records queries_before_attribute_access = 0. Only when values(old) later touches mapped attributes does SQLAlchemy emit the SELECT, reload the row, and produce (7, 'published', 2). SQLAlchemy documents this exact contract: expire() marks attributes out of date, and the next access issues a query in the Session’s current transactional context.
That timing difference is the practical meaning of lazy reloading after Session.expire(). refresh() says “reload now.” expire() says “do not trust these values; reload when code next needs them.” The latter can be useful when ownership is clear but eager I/O is unnecessary. It is not safer for pending data: SQLAlchemy documents that both expiration and refresh discard unflushed changes on the affected object.
S07 is the commit-expiration control. Unlike the other ten cases, its Session uses expire_on_commit=True. The reader’s initial commit() therefore expires the object. After the writer commits and the observer proves PUBLISHED, the candidate path merely evaluates values(old). That attribute access triggers one SELECT and loads the published values. SQLAlchemy documents commit-time expiration as the normal default behavior and expire_on_commit=False as the switch that disables it.
Do not convert S07 into a recommendation to call commit() as a freshness command. Commit is a transaction boundary, not a read invalidation primitive, and SQLAlchemy documents that it flushes pending changes before committing. If a shared Session contains work owned by another component, committing it to obtain fresh values may publish work that was not yours to publish.
Finally, expiration only creates an opportunity to load what the current transaction can see. SQLAlchemy warns that a highly isolated active transaction can return the same previously visible values even after expiration. The supplied acceptance is valid because the old reader transaction ended before the writer started and the independent observer established visibility conditions for this local sequential run.
Refuse to erase unowned pending edits
Freshness is not the only correctness property. The more important question in a shared or layered backend is often: who owns the pending work that a refresh would erase?
S08 deliberately makes old dirty by assigning old.label = 'local-draft'. ORM autoflush is disabled, so the candidate query does not first push that draft to the database. The fixture asserts that old is in reader.dirty, then executes an ORM SELECT with populate_existing=True. The result is technically successful: one SELECT runs, and the object becomes (7, 'published', 2). Operationally, that case is rejected because the local draft has been overwritten.
The ORM Querying Guide states that populate_existing erases existing data, including pending changes; State Management gives the same warning for expire() and refresh(). A successful fresh read can therefore be a failed ownership decision.
S09 exercises the opposite policy. After setting old.label = 'local-draft', the fixture calls guarded_refresh. The helper checks session.new, session.dirty and session.deleted; because the dirty collection is non-empty, it raises PendingState before any SELECT. The trace count is zero, and the object retains (7, 'local-draft', 1). The decision is HOLD_PENDING_WORK.
That is the right operational posture when the candidate read path does not own the draft. A freshness mechanism should not silently decide that another unit of work may be discarded. The guard is conservative, not complete. SQLAlchemy documents Session.dirty as an optimistic collection: an object can appear dirty even if flush-time history comparison later finds no net change. Therefore dirty is a useful refusal signal in this narrow helper, not a complete history or ownership audit.
The related Refonte article on pending work before a savepoint addresses a different transaction-boundary problem, but the ownership principle is the same: unexpected pending state is not permission for a helper to clean up or publish someone else’s work.
Let the owner resolve pending work before refreshing
The guard is intentionally simple:
def guarded_refresh(session, obj):
    if session.new or session.dirty or session.deleted:
        raise PendingState('Resolve pending ORM work before refresh')
    session.refresh(obj)
Only the dirty refusal is separately exercised by S09. The fixture code also checks new and deleted, but no test case independently establishes those branches. They should remain implementation intent until separately qualified.
There is another limit: empty new, dirty and deleted collections do not prove that a Session has no ownership obligations. Work may have been flushed already and still be uncommitted; application-level intent may exist outside these collections; and transaction ownership cannot be inferred from emptiness alone. SQLAlchemy’s dirty documentation itself makes clear that the collection is an optimistic state indicator, not a transaction-history ledger.
The lifecycle owner must choose what to do with pending work: explicitly flush/commit it, merge it elsewhere, discard it, or roll back according to the application’s transaction contract. A read-refresh helper must not select among those policies on its own. In particular, neither commit() nor rollback() is a harmless freshness reset on a shared Session: each is a transaction-owner action with state consequences. SQLAlchemy documents commit’s unconditional flush behavior, and State Management documents transaction-end expiration separately from application ownership.
Hand a new object to the caller explicitly
Sometimes the safest repair is not to mutate the old instance at all. S10 and S11 show why that strategy must include an explicit reference handoff.
In S10, a completely new Session loads primary key 7. Because that Session has no prior identity for the row, fresh.get(Flag, 7) produces a different object whose attributes are (7, 'published', 2). The fixture verifies newer is not old. After the fresh Session closes, the original old object still exposes (7, 'baseline', 1). The decision is ACCEPT_NEW_OBJECT_ONLY.
This explains why a fresh SQLAlchemy Session does not update an old reference: a new Session can give you a correct new instance without changing a reference retained elsewhere. Opening a fresh Session is therefore not a refresh of old. It is an alternate read and a new object-lifetime boundary.
S11 performs a reference replacement inside the original Session. reader.expunge(old) removes the object from the Session; SQLAlchemy documents expunge() as removing an instance from the Session. A subsequent reader.get(Flag, 7) has no current identity-map object for that key and loads a new instance with PUBLISHED. The old instance is detached and remains baseline. The decision is REPAIR_REFERENCE_HANDOFF, not “refresh succeeded.”
This distinction prevents a subtle production bug: code can log or inspect the newly loaded instance, conclude that the system is current, and then return or continue using the old object that some caller already holds. The repair is complete only when the authorized owner deliberately hands the current reference to downstream code.
Detaching the old instance does not update its consumers
expunge(old) changes Session association, not Python references that already exist in other scopes. Any variable, closure, container or caller that still points at old keeps pointing at that same detached object. Its scalar attributes do not mutate just because the Session no longer owns it. SQLAlchemy’s API contract is removal from the Session, not in-place refresh.
Therefore, reference replacement needs an explicit handoff contract: return newer, replace the owning field, emit a DTO built from newer, or otherwise ensure the downstream consumer receives the intended object. Do not call expunge() a refresh path.
The owner that controls the consumer-facing reference should make this choice before releasing the result. The problem is local object lifetime, not distributed cache invalidation. Relationships, graph traversal and second-level caching are outside this fixture and require separate qualification.
Reconcile the row, SQL trace and object ledger
The supplied evidence ledger keeps the three layers visible. In every case, the independent observer sees (7, 'published', 2) before the candidate operation, and a final independent read confirms that persisted row is still published after the case. The measured candidate traces contain no INSERT, UPDATE or DELETE; that statement applies only to the traced reader path, because setup and writer DML occur before tracing begins.
Case | Candidate operation | Held/new object observation | Reader SELECTs | Decision |
S01 | get | Same old object, baseline | 0 | REPAIR |
S02 | ORM SELECT revision=2, then scalar SELECT | Same old object baseline; scalar row published | 2 | REPAIR |
S03 | guarded refresh, clean object | Published values | 1 | ACCEPT_REFRESHED_READ |
S04 | ORM populate_existing | Same object, published | 1 | ACCEPT_REFRESHED_READ |
S05 | expire, then attribute access | Published after access; zero queries before access | 1 | ACCEPT_REFRESHED_READ |
S06 | get(populate_existing=True) | Same object, published | 1 | ACCEPT_REFRESHED_READ |
S07 | expire_on_commit=True control | Published after later attribute access | 1 | ACCEPT_REFRESHED_READ |
S08 | dirty object plus populate_existing | local-draft overwritten by published | 1 | REJECT_UNOWNED_DISCARD |
S09 | guarded refresh, dirty object | PendingState; local-draft preserved | 0 | HOLD_PENDING_WORK |
S10 | new Session | New object published; retained old object baseline | 1 | ACCEPT_NEW_OBJECT_ONLY |
S11 | expunge then get | New object published; detached old object baseline | 1 | REPAIR_REFERENCE_HANDOFF |
The API contracts support the interpretation, but the counts and exact values are laboratory observations. SQLAlchemy documents that get() can avoid SQL when an unexpired identity is already local, that populate_existing overwrites matched instances, that refresh() immediately queries, that expire() defers loading until access, and that default commit behavior expires state. The one-SELECT and two-SELECT counts above are not claimed as universal performance characteristics.
Before trusting a summary generated by another run, verify all of the following together: source SHA-256, runtime versions, driver_autocommit=False, session_autoflush=False, eleven cases present, all assertions passing, observer row equal to PUBLISHED, no candidate DML, and final persisted row unchanged. A green top-level label without a complete inventory is insufficient. A negative-control PASS means the expected bad behavior was detected; it does not approve that operation for deployment.
Choose a repair from the evidence
The repair decision should follow ownership and reference requirements, not convenience.
Evidence state | Owned action | Decision |
Published row is visible; retained object is clean; caller must keep same reference | refresh(obj), ORM populate_existing, or get(..., populate_existing=True) according to selection needs | ACCEPT_REFRESHED_READ only after the exact reference shows expected values |
Published row is visible; local pending edits exist and refresh ownership is unclear | Do not refresh, expire, populate-existing, commit or roll back as a shortcut | HOLD_PENDING_WORK |
New Session returns a current different object | Return/hand off the new reference explicitly | ACCEPT_NEW_OBJECT_ONLY |
Old object is expunged and a new object is loaded | Treat as reference replacement, not refresh | REPAIR_REFERENCE_HANDOFF until handoff is proven |
Candidate scalar read is fresh but retained ORM object is old | Use an explicit owned population path | REPAIR |
Required visibility is blocked by an active transaction boundary | Diagnose transaction visibility separately | HOLD for this playbook |
Runtime, source hash, inventory or assertions are incomplete/contradictory | Stop acceptance | HOLD |
The clean-object path is the most direct SQLAlchemy refresh acceptance test: first prove the committed row is visible, then verify there is no unowned pending state, perform an owned refresh operation, and finally assert the exact caller reference exposes the expected scalar values. That acceptance is local. SQLAlchemy explicitly warns that refresh and expiration see data through the current transaction, so no test here guarantees latest global database state across arbitrary isolation, replicas or concurrent activity.
The pending-work path is stricter. populate_existing, refresh() and expire() can discard unflushed changes, so the component that owns those changes must decide their fate. Rollback is not a harmless retry primitive; it may discard transaction work and must remain an owner decision.
If the scalar read itself cannot see the expected committed row, do not use this identity-map playbook to explain the discrepancy. That is a visibility/transaction question and belongs in a separately qualified investigation such as the SQLite snapshot case already linked above.
Assign the freshness gate to an operational owner
A production-quality handoff should make the freshness decision auditable without turning every incident into an ORM tutorial. Record a compact contract containing the runtime and source hash, transaction timeline, target database identity, independent observer row, candidate SQL evidence, retained-reference attributes, pending-work check, final decision and the component or maintainer who owns the next state transition.
The minimum evidence bundle looks like this:
runtime: CPython / SQLAlchemy / linked DB library
fixture-or-code-hash: ...
identity: Flag(id=7)
old-reader-ended-before-writer: yes/no
committed-observer: (...)
candidate-sql: SELECT count + relevant row/scalar values
held-reference: object id/identity + mapped scalar values
pending-work-check: clean / dirty / unknown
decision: ACCEPT_REFRESHED_READ / REPAIR / HOLD_PENDING_WORK / ...
owner: component or transaction owner authorized to act
That form makes troubleshooting directional. Wrong observer data points to the write or visibility boundary; correct scalar SQL plus a wrong object points to identity-map population; pending work requires ownership resolution; a correct different object requires handoff. An authorized refresh is accepted only when the exact retained reference and local controls pass.
For wider service-level concerns beyond this ORM state gate, Refonte Learning’s broader API reliability practices cover topics such as authentication, validation and error handling. Those concerns are adjacent, not evidence for the identity-map behavior qualified here.
Keep the scope disciplined. The supplied run does not qualify concurrent reader/writer overlap, production isolation differences, AsyncSession, relationships, replicas, distributed caches, crash durability or performance. Changing any of those dimensions creates a new acceptance problem and should produce its own runtime manifest, controls and expected evidence.
Build the backend judgment behind the repair
The durable skill here is not memorizing that refresh() exists. It is learning to separate transaction ownership, database visibility, SQL results and Python object state, then proving that a repair updates the reference the application actually uses. SQLAlchemy’s own documentation makes those lifecycle distinctions explicit, while the supplied fixture turns them into an operational gate.
Refonte Learning’s Backend Development programme is a broader route for readers who want structured practice around persistence and service engineering. The current programme page lists a three-month schedule at 10 to 12 hours per week and includes MongoDB and SQL database management, RESTful APIs/microservices, and backend testing/debugging among its stated competencies. Those are relevant foundations for reasoning about database-backed application behavior, but the page does not establish that this SQLAlchemy 2.0.55 laboratory, SQLite 3.53.1, or Python ORM specialization is part of the syllabus.
The same page lists “basic understanding of programming concepts” under programme specifics, while a separate admissions section says applicants must be working toward a bachelor’s or higher-level degree; readers should confirm the current requirement that applies to them. It also describes completion certificates, but certificate recognition, mentor cadence and internship placement conditions should be confirmed directly rather than inferred from the page.
For maintainers reviewing SQLAlchemy stale objects today, the operational discipline remains simple: prove the committed row, prove what the candidate SQL saw, inspect the exact held object, and let the state owner decide whether to refresh, hold, or replace the reference.