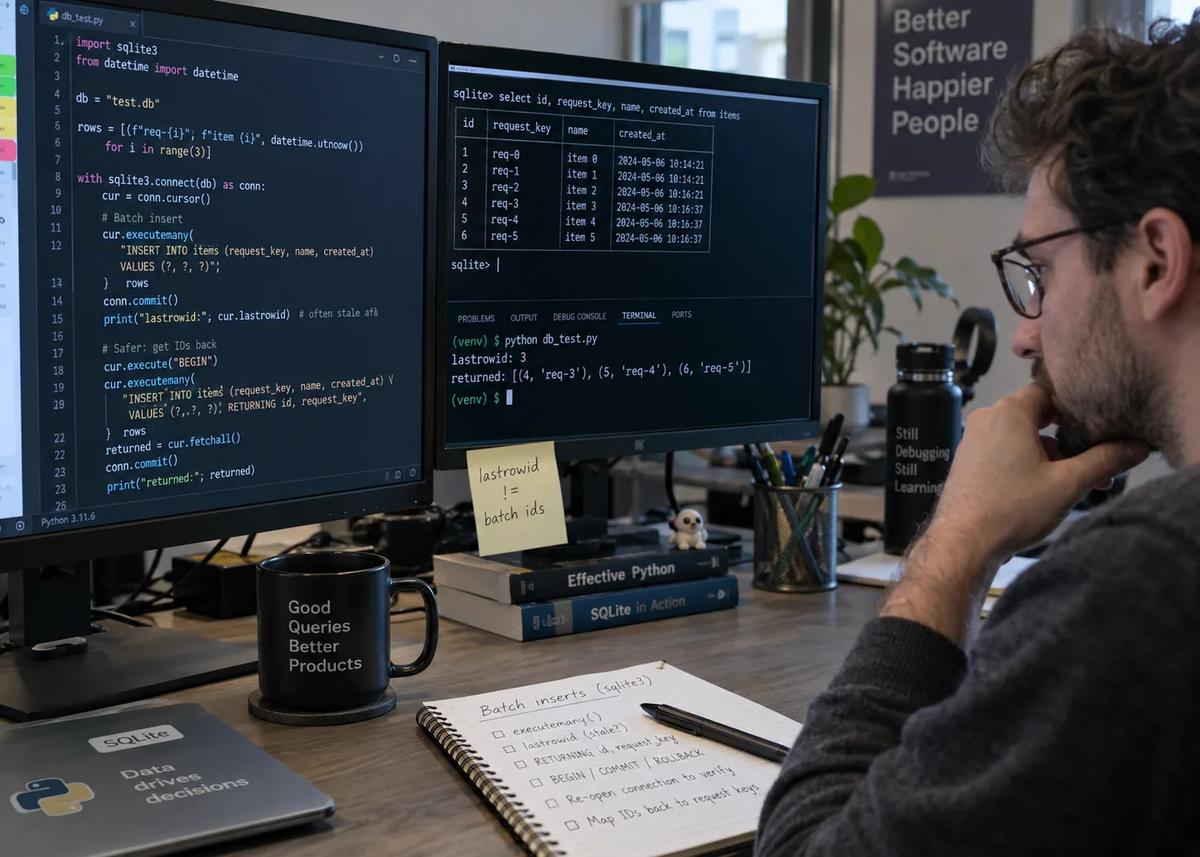
A batch insert can finish without an exception, persist every requested row, and still fail the interface that called it. The misleading signal is cursor.lastrowid: after Python sqlite3.executemany(), it may remain None, or it may continue naming a row inserted earlier through the same cursor. Neither outcome tells a caller which generated identifier belongs to req-c, req-a, or req-b.
This article addresses that boundary for intermediate and senior Python backend engineers, database administrators, and reviewers. The scope is deliberately narrow: CPython sqlite3, one writer, one disposable local database per case, an ordinary table with INTEGER PRIMARY KEY, a unique request_key, and explicit SQL transactions. The commissioning record supplied for this article reports a run on CPython 3.12.14 with SQLite 3.53.1 on Linux x86_64 on October 12, 2026. The six-case fixture exited successfully with PASS_6_CASES; that is a bounded observation, not a universal compatibility claim.
The decision is also narrow. A writes-only path may remain when identifiers are not part of its contract. A receipt-producing path must instead return a complete keyed mapping, validate it against independent expected keys and payloads, commit the transaction, reopen the database, and publish only the mapping that still agrees. Missing, duplicate, stale, provisional, or otherwise ambiguous receipts produce a HOLD - not an invented ID reconstruction.
Define the receipt a batch caller actually needs
The caller's requirement is not "three rows changed." It is one authoritative association for every accepted request:
request_key -> generated database ID, with the expected payload still attached to the same key.
For the synthetic batch, the admitted inputs are req-c/gamma, req-a/alpha, and req-b/beta. Their input sequence is intentionally not alphabetical. That makes it easier to expose an implementation that silently assumes result position equals request position.
A writes-only API can have a smaller contract. It may accept a list, commit the rows, and return no identifiers. Under that contract, a successful executemany() can be adequate. The caller must not later infer that the absence of receipts is a defect if IDs were never promised.
An ID-returning API is different. Its success condition includes all of the following:
exactly one receipt for every expected request key;
a positive integer ID in every receipt;
no duplicate request keys or duplicate IDs;
payload agreement for each key;
a committed database state that reproduces the same mapping.
That contract is about grain and identity, not merely affected-row count. The broader discipline to define SQL grain and key contracts is useful background: state what one receipt represents and which key makes it independently identifiable before choosing an insertion API.
Successful insertion alone cannot close the ID-bearing contract. A scalar naming one row is not a ledger for three rows, and three generated integers without request keys are not a trustworthy mapping. The central sqlite3 executemany lastrowid question is therefore not whether SQLite wrote data. It is whether the application can prove which committed ID belongs to every admitted request.
Keep the driver, engine and transaction mode explicit
"SQLite version" and "Python version" are separate evidence fields. CPython supplies the sqlite3 driver interface; that module is linked to an SQLite runtime whose version is available through sqlite3.sqlite_version. The Python interpreter version does not uniquely imply the embedded engine version.
The commissioning baseline was CPython 3.12.14 and SQLite 3.53.1. The linked primary technical sources were accessed on October 12, 2026; living pages are treated as current documentation at that access date unless they state a separate release date. The versioned Python 3.12 sqlite3 documentation displayed a 3.12.15 page label when accessed on October 12, 2026, while the executed interpreter remained 3.12.14. Those are not contradictory facts: one identifies the documentation branch as displayed at access; the other identifies the recorded runtime. The documentation also exposes the runtime SQLite version separately.
Every canonical case creates a fresh database file. That prevents one case's rows, cursor state, or rollback from contaminating another. The table has only id INTEGER PRIMARY KEY, request_key TEXT NOT NULL UNIQUE, and payload TEXT NOT NULL. The experiment has one writer and deliberately excludes ORMs, triggers, foreign keys, conflict upserts, concurrent get-or-create behavior, WAL backup workflows, maintenance, cascades, and distributed delivery.
The connections use autocommit=True, but the batch boundary is still explicit SQL: BEGIN, then the writes and validation, then COMMIT or ROLLBACK. In this mode, Python's Connection.commit() and Connection.rollback() methods do nothing, so substituting them would not express the intended boundary. The Python transaction-control documentation states that behavior directly.
Record the environment before opening the first case
A reviewable run records:
sys.version and platform.platform();
sqlite3.sqlite_version and SELECT sqlite_source_id();
the UTC start and finish timestamps;
a SHA-256 of the exact fixture;
the initial db.in_transaction state;
one result object per expected case.
The fixture refuses CPython older than 3.12 because it uses the explicit autocommit connection argument, and it refuses SQLite older than 3.35.0 because RETURNING is unavailable there. The SQLite RETURNING documentation records support since 3.35.0, released March 12, 2021.
The supplied fixture hash is 47ac02ddf8d5ab40452026861b45f0f8619a0488ac0daf41380cba96b9c35596. A different hash is not automatically wrong, but it is a different artifact and must not inherit the recorded result without rerunning. Likewise, an unexpected initial transaction state is a reason to stop the case, because transaction assumptions are part of the receipt protocol.
Separate cursor state from row identity
Four values that may look related are materially different:
Evidence item | What it can show | What it cannot show |
cursor.lastrowid | The cursor's last recorded row ID under its documented update rules | A per-request batch mapping or commit |
SELECT last_insert_rowid() | The connection-level latest successful rowid insertion | Which ID belongs to every batch request |
A RETURNING row | Values reported for a row directly modified by that statement | That the surrounding transaction later committed |
Reopened keyed rows | The mapping visible after commit from a new read-only connection | Future row lifetime, backup completeness, or power-loss testing |
Python documents Cursor.lastrowid as initially None. It is updated after successful INSERT or REPLACE through execute(), but left unchanged after executemany(), executescript(), other statements, or a failed insertion. This is the documented basis for the Python sqlite3 stale lastrowid counterexample, not an accidental interpretation of one output. See the Python 3.12 sqlite3 API reference.
The fresh-cursor case begins with None; after three successful plain inserts through executemany(), the cursor scalar remains None. The reused-cursor case first inserts an explicit seed row with ID 97 through execute(). That makes cur.lastrowid == 97. After the later three-row executemany(), all new request rows exist, but the same cursor still reports 97. The scalar names the older seed, not any member of the new batch.
The engine-level scalar answers another question. The SQLite last-insert-rowid reference describes sqlite3_last_insert_rowid() - also exposed through SQL as last_insert_rowid() - as the rowid of the most recent successful insertion on the connection. It also states that an insertion still counts for this scalar even if it is subsequently rolled back. Therefore the sqlite3 last_insert_rowid difference matters: connection recency is neither batch identity nor commit evidence.
No arithmetic repair follows from these scalars. Subtracting batch length from the latest ID assumes allocation behavior, uninterrupted sequences, and ordering that the receipt contract never established. Generated integers observed in this fixture are sample outcomes only. The independent request keys - not guessed numeric adjacency - must anchor reconciliation.
Declare the independent request manifest
The oracle must exist before the database chooses any IDs. Input order and expected identity are therefore declared separately:
Input position | request_key | Expected payload |
1 | req-c | gamma |
2 | req-a | alpha |
3 | req-b | beta |
The ordered BATCH drives writes. The separately constructed EXPECTED dictionary defines accepted key/payload content without relying on returned order:
BATCH = [("req-c", "gamma"), ("req-a", "alpha"), ("req-b", "beta")]
EXPECTED = {"req-a": "alpha", "req-b": "beta", "req-c": "gamma"}
The validator checks exact cardinality, positive integer IDs, unique IDs, unique keys, and exact key/payload equality. It then produces a dictionary keyed by request_key. That is the core of sqlite3 batch ID reconciliation: the database-generated value is accepted only when attached to an independently expected business key and payload.
Create a fresh writable directory, save the following unchanged as sqlite_receipts_lab.py, and run it with a qualifying interpreter:
mkdir sqlite-receipts-lab
cd sqlite-receipts-lab
python3 sqlite_receipts_lab.py
The script creates a new uniquely named run directory beside itself, six database files, and results.json. It does not open an existing application database. No third-party Python package is required. On failure it records the exception and traceback, writes the partial report, and exits nonzero because the exception is re-raised.
"""Synthetic sqlite3 receipt experiment; CPython 3.12+, SQLite 3.35+."""
import hashlib
import json
import platform
import sqlite3
import sys
import tempfile
import traceback
from datetime import datetime, timezone
from pathlib import Path

BATCH = [("req-c", "gamma"), ("req-a", "alpha"), ("req-b", "beta")]
EXPECTED = {"req-a": "alpha", "req-b": "beta", "req-c": "gamma"}
CASE_IDS = ["single_execute", "many_fresh_cursor", "many_reused_cursor",
            "loop_receipts", "loop_rollback", "multi_values_receipts"]
DDL = "CREATE TABLE jobs(id INTEGER PRIMARY KEY, request_key TEXT NOT NULL UNIQUE, payload TEXT NOT NULL)"
INSERT = "INSERT INTO jobs(request_key,payload) VALUES(?,?) RETURNING id,request_key,payload"

def require(condition, message):
    if not condition:
        raise RuntimeError(message)

def validate(rows, expected):
    require(len(rows) == len(expected), "Receipt cardinality mismatch")
    ids = [r[0] for r in rows]
    keys = [r[1] for r in rows]
    require(all(type(i) is int and i > 0 for i in ids), "Bad identifier")
    require(len(ids) == len(set(ids)), "Duplicate receipt identifier")
    require(len(keys) == len(set(keys)), "Duplicate receipt key")
    require({r[1]: r[2] for r in rows} == expected, "Receipt key/payload mismatch")
    return {key: (ident, payload) for ident, key, payload in rows}

def snapshot(db):
    return db.execute("SELECT id,request_key,payload FROM jobs ORDER BY request_key").fetchall()

def reopened(path):
    db = sqlite3.connect(path.as_uri() + "?mode=ro", uri=True, autocommit=True)
    try:
        return snapshot(db)
    finally:
        db.close()

def run_case(directory, name, entry):
    path = directory / (name + ".db")
    db = sqlite3.connect(path, autocommit=True)
    cur = db.cursor()
    try:
        require(not db.in_transaction, "Unexpected initial transaction")
        db.execute(DDL)
        if name == "many_reused_cursor":
            cur.execute("INSERT INTO jobs(id,request_key,payload) VALUES(97,'seed','seed')")
            require(cur.lastrowid == 97, "Seed cursor state missing")
        before = cur.lastrowid
        db.execute("BEGIN")
        require(db.in_transaction, "BEGIN did not open transaction")
        if name == "single_execute":
            returned = cur.execute(INSERT, ("req-a", "alpha")).fetchall()
            mapping = validate(returned, {"req-a": "alpha"})
            entry.update(returned=returned, cursor_lastrowid=cur.lastrowid)
            db.execute("COMMIT")
            persisted = reopened(path)
            require(validate(persisted, {"req-a": "alpha"}) == mapping, "Committed mapping mismatch")
            entry.update(persisted=persisted, published_receipts=returned)
        elif name in ("many_fresh_cursor", "many_reused_cursor"):
            cur.executemany("INSERT INTO jobs(request_key,payload) VALUES(?,?)", BATCH)
            returned = cur.fetchall()
            after = cur.lastrowid
            entry.update(returned=returned, lastrowid_before=before,
                         lastrowid_after=after, rowcount_diagnostic=cur.rowcount,
                         engine_last_insert_rowid=db.execute("SELECT last_insert_rowid()").fetchone()[0])
            require(returned == [], "Expected no result rows from plain INSERT executemany")
            require(after == before, "Expected unchanged cursor lastrowid")
            expected = dict(EXPECTED)
            if name == "many_reused_cursor":
                expected["seed"] = "seed"
            validate(snapshot(db), expected)
            db.execute("COMMIT")
            persisted = reopened(path)
            validate(persisted, expected)
            entry.update(persisted=persisted, published_receipts=[],
                         operational_decision="HOLD_RECEIPT_CONTRACT_RECONCILE_BY_REQUEST_KEY")
        elif name == "loop_receipts":
            receipts = []
            for request in BATCH:
                one = cur.execute(INSERT, request).fetchall()
                require(len(one) == 1, "Missing single-row receipt")
                receipts.extend(one)
            mapping = validate(receipts, EXPECTED)
            require(validate(snapshot(db), EXPECTED) == mapping, "Precommit mapping mismatch")
            entry["provisional_receipts"] = list(receipts)
            db.execute("COMMIT")
            persisted = reopened(path)
            require(validate(persisted, EXPECTED) == mapping, "Committed mapping mismatch")
            entry.update(persisted=persisted, published_receipts=receipts)
        elif name == "loop_rollback":
            provisional = []
            error_name = None
            try:
                for request in [("req-c", "gamma"), ("req-c", "changed"), ("req-a", "alpha")]:
                    provisional.extend(cur.execute(INSERT, request).fetchall())
            except sqlite3.IntegrityError as exc:
                error_name = exc.sqlite_errorname
            entry.update(error_name=error_name, provisional_receipts=list(provisional),
                         rows_before_rollback=snapshot(db))
            require(error_name == "SQLITE_CONSTRAINT_UNIQUE", "Wrong failure category")
            require(len(provisional) == 1, "Wrong provisional receipt count")
            provisional_mapping = validate(provisional, {"req-c": "gamma"})
            require(validate(entry["rows_before_rollback"], {"req-c": "gamma"}) == provisional_mapping,
                    "Provisional receipt does not match pre-rollback row")
            require(db.in_transaction, "Expected open transaction before recovery")
            db.execute("ROLLBACK")
            entry["engine_last_insert_rowid_after_rollback"] = db.execute("SELECT last_insert_rowid()").fetchone()[0]
            require(entry["engine_last_insert_rowid_after_rollback"] == provisional[0][0], "Unexpected last-insert scalar")
            persisted = reopened(path)
            require(persisted == [], "Rolled-back row survived")
            entry.update(persisted=persisted, published_receipts=[],
                         operational_decision="ROLLBACK_AND_DISCARD_PROVISIONAL_RECEIPTS")
        else:
            sql = "INSERT INTO jobs(request_key,payload) VALUES (?,?),(?,?),(?,?) RETURNING id,request_key,payload"
            parameters = tuple(value for row in BATCH for value in row)
            receipts = cur.execute(sql, parameters).fetchall()
            mapping = validate(receipts, EXPECTED)
            reversed_receipts = list(reversed(receipts))
            require(validate(reversed_receipts, EXPECTED) == mapping, "Keyed mapping depends on order")
            sorted_receipts = sorted(receipts, key=lambda row: row[1])
            positional = {request[0]: row[0] for request, row in zip(BATCH, sorted_receipts)}
            keyed = {key: record[0] for key, record in mapping.items()}
            require(positional != keyed, "Permutation control did not expose positional coupling")
            duplicate_rejected = False
            try:
                validate([receipts[0], receipts[0], receipts[2]], EXPECTED)
            except RuntimeError:
                duplicate_rejected = True
            require(duplicate_rejected, "Validator accepted duplicate receipts")
            entry.update(returned=receipts, controlled_permutation=sorted_receipts,
                         positional_mapping=positional, correct_mapping=keyed,
                         duplicate_receipts_rejected=duplicate_rejected)
            db.execute("COMMIT")
            persisted = reopened(path)
            require(validate(persisted, EXPECTED) == mapping, "Committed mapping mismatch")
            entry.update(persisted=persisted, published_receipts=receipts)
        require(not db.in_transaction, "Transaction left open")
        entry["case_result"] = "EXPECTED_BEHAVIOR_CONFIRMED"
    finally:
        cur.close()
        if db.in_transaction:
            db.execute("ROLLBACK")
        db.close()

directory = Path(tempfile.mkdtemp(prefix="sqlite-receipts-", dir=Path(__file__).parent)).resolve()
report = {"status": "HOLD", "started_at": datetime.now(timezone.utc).isoformat(),
          "python": sys.version, "platform": platform.platform(),
          "sqlite": sqlite3.sqlite_version, "fixture_sha256": hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
          "independent_manifest": EXPECTED, "cases": []}
try:
    require(sys.version_info >= (3, 12), "CPython 3.12+ required for explicit autocommit")
    require(sqlite3.sqlite_version_info >= (3, 35, 0), "SQLite RETURNING unavailable")
    probe = sqlite3.connect(":memory:", autocommit=True)
    report["sqlite_source_id"] = probe.execute("SELECT sqlite_source_id()").fetchone()[0]
    probe.close()
    for name in CASE_IDS:
        entry = {"case_id": name, "case_result": "HOLD"}
        report["cases"].append(entry)
        run_case(directory, name, entry)
    require([c["case_id"] for c in report["cases"]] == CASE_IDS, "Case coverage mismatch")
    require(all(c["case_result"] == "EXPECTED_BEHAVIOR_CONFIRMED" for c in report["cases"]), "Incomplete case")
    report["status"] = "PASS_6_CASES"
except Exception as exc:
    report["status"] = "FAIL"
    report["error"] = {"type": type(exc).__name__, "message": str(exc)}
    report["traceback"] = traceback.format_exc()
    raise
finally:
    report["finished_at"] = datetime.now(timezone.utc).isoformat()
    output = directory / "results.json"
    output.write_text(json.dumps(report, indent=2) + "\n", encoding="utf-8")
    print(json.dumps({"status": report["status"], "report": str(output)}))
The commissioning record reports that this exact file, whose SHA-256 appears above, exited with status 0 and produced PASS_6_CASES on CPython 3.12.14 with SQLite 3.53.1. Readers should treat their own results.json as the evidence for their environment; the reported commissioning result does not substitute for rerunning the fixture on another runtime.
Use a single execute call as the receipt control
single_execute establishes the ordinary one-row receipt path. The statement is parameterized and includes RETURNING id,request_key,payload. The cursor consumes the entire result with fetchall() before COMMIT, validates exactly one req-a/alpha receipt, and stores the mapping as provisional evidence.
After COMMIT, a new connection opens the same file in read-only URI mode and queries the table. The reopened row must validate to the same mapping before the receipt is placed in published_receipts. This is a control for one statement and one row; it does not imply that executemany() will update lastrowid, preserve result rows, or create a three-row mapping.
This distinction also explains the sqlite3 execute RETURNING fetchall pattern used throughout the two receipt-producing alternatives. Fetching identifies what the statement reported. Committing establishes the transaction outcome. Reopening independently checks what the database exposes afterward. None of those evidence items substitutes for the others.
Observe what plain executemany leaves in lastrowid
The two plain-batch cases execute the same SQL:
cur.executemany(
    "INSERT INTO jobs(request_key,payload) VALUES(?,?)",
    BATCH,
)
There is no RETURNING clause. That matters when interpreting cur.fetchall() == []: the empty fetch is expected because this statement does not produce result rows. It is not evidence from an executemany(... RETURNING ...) experiment.
The supplied observations separate database mutation from the caller's receipt contract:
Case | Rows after commit and reopen | lastrowid before | lastrowid after | Published receipts | Decision |
many_fresh_cursor | Three expected request rows | None | None | 0 | HOLD receipt contract |
many_reused_cursor | Seed plus three expected request rows | 97 | 97 | 0 | HOLD receipt contract |
Both inserts succeeded in their stated scope. Neither case is data loss, a rolled-back transaction, or an engine failure. The defect appears only when a caller requires SQLite batch insert IDs. A committed row count of three does not answer which generated ID belongs to each request, while the stale value 97 is affirmatively misleading if treated as a new-batch identifier.
rowcount and last_insert_rowid() remain diagnostics in the report, not mapping algorithms. rowcount can support the observation that statements modified rows, but it carries no request-to-ID association. The engine scalar can name the connection's latest insertion, but one scalar still cannot describe three associations.
Keep the RETURNING probe discrepancy outside the canonical proof
The Python sqlite3 cursor documentation says that executemany() discards resulting rows, including rows from DML statements containing RETURNING. At the broader interface level, PEP 249 says that using executemany() for an operation that produces result sets is undefined behavior and permits implementations to raise an exception. The Python-specific rule is therefore not a portable promise about every DB-API driver.
The commissioning packet separately reports an exploratory probe that diverged from the documented Python-specific expectation: one parameter set exposed a row, while a multi-item call raised InterfaceError after the first insertion. No cause, regression date, or corrected release has been established. The canonical fixture neither hides that observation nor depends on it. Its executemany() cases use plain INSERT, and its receipt cases use execute().
That is the safe review posture. An unexpected local result does not authorize rewriting the documentation or generalizing from one build. Record the exact Python and SQLite identities, preserve the probe separately, and HOLD that call combination until its behavior and transaction effects are understood.
Collect one keyed receipt per execute call
The first canonical receipt-producing alternative keeps the explicit transaction but replaces one executemany() call with three parameterized execute() calls:
receipts = []
for request in BATCH:
    one = cur.execute(INSERT, request).fetchall()
    require(len(one) == 1, "Missing single-row receipt")
    receipts.extend(one)
Each call uses INSERT ... RETURNING id,request_key,payload. Each result is consumed immediately, and each single-row call must return exactly one row. After the loop, validate(receipts, EXPECTED) proves that the combined collection contains one unique positive ID for every expected key and that every payload agrees.
The transaction has not committed yet. At this point the list is a provisional ledger. The fixture queries the same connection and validates the table against the same mapping, which proves precommit internal agreement but still does not permit publication. SQLite's RETURNING documentation distinguishes returned output from transaction completion: a returned row reports a directly modified row, while a surrounding transaction may still be pending. See the SQLite RETURNING reference.
Only after the explicit COMMIT does the fixture reopen the file through a separate read-only connection. The reopened mapping must equal the provisional mapping exactly. Then, and only then, the list becomes published_receipts.
This path is straightforward to reason about because every statement has one input key and one returned key. Its operational tradeoff is that a batch of three inputs executes three write statements. The experiment makes no throughput ranking and supplies no universal performance threshold. Teams should qualify latency, transaction duration, error handling, and resource use in their own workload rather than replacing a verified identity contract with an assumed optimization.
Use a multi-VALUES statement without positional coupling
The second receipt-producing alternative uses one fixed, parameterized statement for the three-row batch:
INSERT INTO jobs(request_key,payload)
VALUES (?,?),(?,?),(?,?)
RETURNING id,request_key,payload
The Python code flattens the already bounded BATCH values into one parameter tuple. It does not concatenate request values into SQL. This distinction preserves parameter binding while allowing one statement to return three keyed receipts.
The validator is identical to the loop path. That makes the comparison meaningful: both alternatives must satisfy the same independent manifest, the same uniqueness rules, the same explicit transaction boundary, and the same postcommit reopening. The SQL shape differs; the receipt contract does not.
This fixture deliberately fixes the statement at three rows. A production implementation that generates different placeholder counts or chunks a larger batch needs separate qualification. SQLite limits, driver binding behavior, memory pressure, statement size, and application latency are resource questions that this finite experiment does not answer. SQLite notes that RETURNING output is accumulated in memory before delivery, so very large outputs should not be extrapolated from this three-row result. See the SQLite RETURNING reference.
Make result ordering irrelevant to identity
SQLite explicitly documents arbitrary RETURNING row order. It may vary with schema, release, or execution, and cannot be constrained into a promised output order. The SQLite RETURNING row order is therefore not an identity channel. See the SQLite RETURNING ordering limitations.
The fixture therefore builds the SQLite multi-row insert receipt mapping from returned keys:
keyed = {key: record[0] for key, record in mapping.items()}It validates a reversed copy of the returned receipts and requires the same mapping. That reversal is a manufactured test mutation; it does not claim SQLite emitted reversed rows in the commissioning run.
A second negative control sorts returned rows by key, then incorrectly zips them against the original input order req-c, req-a, req-b. The resulting positional association must differ from the keyed one. This exposes the defect in code that writes:
request_to_id = dict(zip(request_keys, returned_ids))unless the ordering contract has been independently established - which SQLite does not establish here. A duplicate-receipt mutation is also rejected. The safe association is the SQLite RETURNING request key carried in each receipt, not its list position.
Invalidate provisional IDs when the batch rolls back
The rollback case demonstrates why a returned identifier cannot be published merely because it was exact when fetched. The input sequence is deliberately invalid:
insert req-c/gamma;
attempt req-c/changed;
insert req-a/alpha only if execution reaches it.
The first execute(... RETURNING ...) yields one exact provisional receipt. The second insert violates the table's unique request_key constraint and raises sqlite3.IntegrityError with SQLITE_CONSTRAINT_UNIQUE. In the supplied run, the explicit transaction remains open, the first row is visible on the writer connection, and the third request is never attempted.
The fixture verifies that the one provisional receipt matches the one pre-rollback row. It then issues explicit SQL ROLLBACK, reopens the file, and requires an empty table. published_receipts is also empty. This is the correct SQLite rollback provisional IDs outcome: diagnostics may remember the ID, but the caller must not receive it as a successful business result.
After rollback, last_insert_rowid() still equals the provisional integer. That is expected under SQLite's documented rule that a successful insertion counts for this scalar even when later rolled back. The scalar therefore cannot rescue the receipt or prove persistence. It records connection history, not the final batch outcome.
The duplicate-key input is only a controlled failure mechanism. It is not a recommendation to replace, merge, ignore, or upsert. Those choices belong to the distinct problem of SQLite conflict writes and child-row preservation, which this ordinary-insert receipt experiment excludes.
Keep evidence of partial progress without publishing it
Good recovery evidence preserves more than a final empty table. The case report retains:
the extended SQLite error name;
the exact provisional receipts collected before failure;
the rows visible before rollback;
the connection-level last-insert scalar after rollback;
the reopened rows;
the empty published list;
the explicit operational decision.
This record supports incident review without confusing attempted progress with accepted output. A failed batch can have useful diagnostic evidence and still have no publishable receipt.
The outer fixture applies the same discipline to unexpected exceptions. It begins with status HOLD, captures exception type, message, and traceback, writes the partial JSON report in finally, and re-raises so the process exits nonzero. An incomplete run must not be reported as a PASS simply because some database files or case entries exist.
The SQLite transaction documentation warns against assuming every error has the same rollback effect: some errors may undo a statement while leaving prior changes and the transaction active, while other circumstances may roll back more broadly. Applications should inspect the surviving state and choose an explicit recovery action. In this canonical constraint case, db.in_transaction is checked before the explicit rollback.
Reconcile the committed mapping against every request
A receipt validator should answer identity questions, not merely count questions. After commit, the fixture opens the original database file read-only and selects id, request_key, and payload, ordered only to make the evidence readable. It then applies the same key-based validator used before commit.
The required equality is exact:
the number of persisted rows equals the number of expected keys;
persisted keys equal the expected key set;
each persisted payload matches its independently declared payload;
every ID is a positive integer;
IDs and keys are individually unique;
the persisted request_key -> (ID, payload) mapping equals the provisional mapping.
A count of three cannot detect swapped identities or a changed payload. MAX(id) cannot show whether all expected keys exist. A contiguous-looking integer range cannot establish which request owns which value. A successful COMMIT cannot prove that the application assembled its receipt list correctly. These are separate predicates, so the evidence checks them separately.
The read-only reopening establishes that a new connection sees the same committed mapping in this file. In this laboratory, "published" means releasing the verified receipt list to the direct caller; it does not send a message, use an outbox, or establish distributed exactly-once delivery. It does not prove that those rows will retain their meaning through later maintenance, that storage survives a power-loss scenario, or that a separately copied artifact contains them. Readers dealing with the latter problem should verify committed rows in a SQLite backup; this experiment creates no backup and does not enable WAL.
The phrase SQLite returned IDs after commit should therefore mean more than "a list was fetched before COMMIT." It means that fetched, keyed receipts survived validation, the transaction committed, and an independent reopening reproduced the same finite mapping. Even then, the conclusion remains scoped to the original local file and the declared schema.
Choose a write path from the evidence
The write API should follow the caller contract rather than convenience alone.
Caller and evidence state | Recommended disposition |
Caller needs only committed writes, not IDs | Retain plain executemany() if its transaction/error contract is separately acceptable |
Caller needs one ID per request; bounded per-row execution is acceptable | Use execute(... RETURNING ...) per request, collect keyed receipts, commit, reopen, validate |
Caller needs one bounded statement and the row count is qualified | Use parameterized multi-VALUES execute(... RETURNING ...), map by returned key, then commit and reconcile |
Batch is already committed but receipts are missing | Query by independently unique request_key; verify payloads and cardinality before publishing |
Any key, payload, identifier, version, or transaction outcome is ambiguous | HOLD; do not invent a mapping or insert blindly |
An open batch has failed | Inspect transaction state, roll back explicitly in the qualified recovery path, discard provisional receipts |
A lookup by unique request_key can be a bounded recovery design for an already committed batch. It is not a seventh fixture case, and it needs its own treatment of missing keys, unexpected existing rows, payload disagreement, and transaction visibility. The important point is that lookup uses the independent identity contract. It does not reconstruct IDs from lastrowid, row count, or numeric ranges.
State ACCEPT, HOLD and rollback criteria separately
ACCEPT means every expected key has one unique positive ID, payloads agree, the explicit transaction committed, and a new read-only connection reproduced the same mapping. In this fixture, single_execute, loop_receipts, and multi_values_receipts satisfy their stated receipt contracts.
HOLD means receipts are absent, stale, duplicated, missing, associated only by position, tied to changed payloads, produced under an unrecorded environment, or left behind by an exception. The two plain executemany() cases HOLD only the ID-bearing caller contract; they do not retroactively turn successful writes into failed writes.
ROLLBACK AND DISCARD applies when the qualified path still has an open failed transaction. It does not undo an already committed batch. For committed-but-unmapped rows, the recovery action is investigation and reconciliation by request key, not a fictional rollback and not an unconditional retry.
These categories prevent a common incident-review error: mixing database state, receipt completeness, and recovery action into one "success/failure" flag. Each has its own evidence and its own owner.
Define recovery boundaries for existing callers
An existing caller that reads cursor.lastrowid after executemany() has a contract defect when it promises one ID per input. The repair is not to reinterpret the stale scalar. Preserve the caller-facing requirement and change the receipt-producing write path to one of the qualified, keyed alternatives - or explicitly remove IDs from the API contract.
Migration should start at the boundary where inputs are admitted. Require a stable, independently unique request_key and retain the expected payload or a comparable immutable request fingerprint. Pass that identity into the insert and return it through RETURNING. Validate the complete collection before publication.
For a historical batch that may already be committed, do not submit the same inputs again merely because the original function returned no usable receipts. First query the authoritative table by the known request keys. Classify each expected key as exactly matched, missing, payload-mismatched, or duplicated where the schema permits duplication. Under this fixture's unique constraint, one exact row per key can support bounded recovery; a missing or mismatched key remains unresolved.
This article excludes concurrent get-or-create. It does not address another writer inserting the same key between a lookup and a retry, PostgreSQL statement snapshots, CTE fallbacks, row locks, or retry-loop design. Those mechanisms need their own concurrency protocol. The safe conclusion here is smaller: for one SQLite writer and successful ordinary inserts, a stale scalar is not a receipt ledger, and blind reinsertion can make recovery worse.
Revalidate when the database or driver changes
Treat the fixture as a qualification test, not a timeless certification. Rerun it when any contract-relevant layer changes:
CPython or the sqlite3 module behavior;
the linked SQLite version or build identity;
transaction mode or connection wrapper;
table schema, generated columns, or key constraints;
SQL shape, placeholder generation, or chunking;
triggers, virtual tables, or WITHOUT ROWID;
conflict clauses, retries, or additional writers;
receipt validation and publication code.
Record the new interpreter, platform, SQLite version, source ID, fixture hash, timestamps, and complete JSON result. Compare case coverage as well as final status. A PASS from five cases is not equivalent to PASS_6_CASES, and a modified oracle is a new test.
Portability also stops at the documented interface boundary. PEP 249 leaves result-producing executemany() behavior undefined, while CPython's sqlite3 documentation gives its own discard rule. Another DB-API driver may behave differently without contradicting the generic specification. A driver change therefore requires direct qualification rather than copying this SQLite conclusion.
Connection admission can have separate state requirements. For example, applications using related tables may need to verify SQLite foreign-key enforcement. That is a distinct check; the present fixture has no foreign keys and changes no PRAGMA. Adding such features expands the test surface rather than silently inheriting this PASS.
Assign ownership of the receipt contract
The backend owner defines what the caller is promised: accepted input semantics, request-key stability, whether IDs are required, and when a receipt may be released. The database owner defines the schema constraint, generated-ID mechanism, transaction boundary, and recovery behavior. The reviewer supplies or approves the independent expected mapping and negative controls. The executor retains versioned evidence from the actual environment.
A concise evidence bundle contains the exact script, SHA-256, runtime identities, results.json, six database files, process exit status, and any separately labeled exploratory probes. That bundle makes Python batch insert receipt validation repeatable rather than dependent on a screenshot or remembered scalar. It should also state the operational decision for each path. This allows a later reviewer to distinguish documented behavior, the supplied commissioning observation, and an inference about application design.
PASS_6_CASES has a finite meaning: all six declared oracles held in one recorded environment. It does not certify security, performance, crash durability, every SQLite build, future versions, or an application with different schema behavior. The same restraint applies to EXPECTED_BEHAVIOR_CONFIRMED; it names the expected result of one case, not universal production readiness.
Ownership continues after insertion. A team that saves identifiers through schema changes or maintenance has a different obligation to preserve saved SQLite identities across VACUUM. This article ends at acquisition and publication of the committed request-to-ID mapping. It does not claim that a correct receipt remains meaningful through every later database lifecycle event.
Practice database validation with Refonte Learning
The resolved engineering decision is clear. Keep plain executemany() only for a writes-only contract. When the caller requires executemany generated identifiers, change the receipt-producing path: use qualified execute(... RETURNING ...) calls, associate every returned ID with its returned request key, validate the entire manifest, commit explicitly, reopen independently, and publish only the committed mapping. HOLD ambiguous evidence. Roll back an open failed batch and discard every provisional ID.
Engineers developing these review habits may find the Database Administrator Essentials program relevant. Its page lists a three-month duration and 12-14 hours per week, with topics including database design, SQL optimization, performance, security and access control, backup and recovery, cloud databases, and migration. It also states personalized mentorship and practical projects.
The page names MySQL Workbench, Oracle SQL Developer, and AWS RDS, but it does not confirm that Python sqlite3, this exact batch-ID laboratory, or these software versions are taught. It describes internship opportunity as potential rather than promising an individual placement, and lists a Training Certificate and Certificate of Internship upon successful completion. Those programme details should be evaluated on their own terms.
The transferable skill is narrower and more valuable than memorizing one API quirk: define the data contract, separate provisional from committed evidence, test negative controls, and refuse to publish an identity mapping that the evidence does not support.