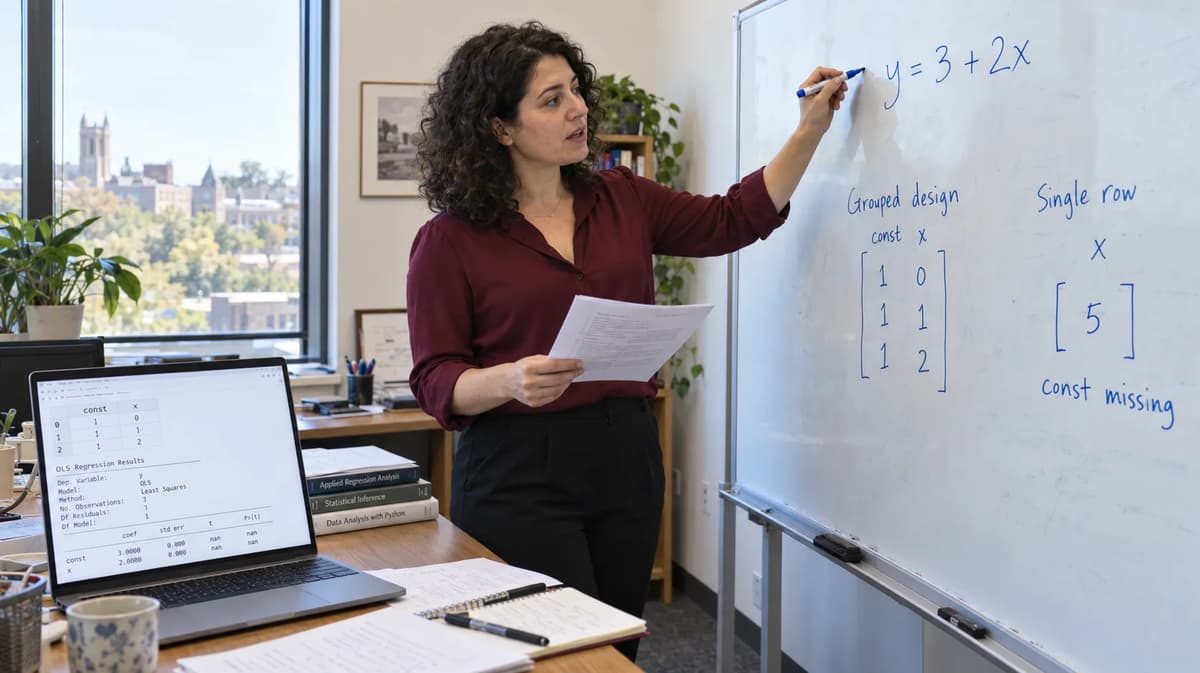
A useful regression interface can fail in a surprisingly local way: a batch of observations produces predictions, but the same observations prepared one at a time produce a matrix-alignment error. In the case examined here, nothing about the fitted coefficients has changed. The difference is introduced earlier, when statsmodels.add_constant is asked to infer whether the current prediction batch already contains a constant column.
That distinction matters because add_constant is a constructor utility, not a reader of the fitted model specification. Its documented default, has_constant='skip', avoids inserting another constant when one is detected. On the pandas path in statsmodels 0.15.0, the pinned implementation tests for a zero-range, nonzero column. Consequently, [5] and [5, 5] can be classified as already constant, while [0] is not. The result is not the rule “single rows lose their intercept”; the zero-valued singleton is an important counterexample.
The laboratory below keeps one raw float64 predictor x, the declared model design [const, x], row identities, and the fitted coefficient vector fixed. It compares a varying group with the same rows split into singleton calls, then replaces current-batch inference with a narrow raw-input constructor. This is an authored reproducibility fixture, not a customer incident. Its goal is equally narrow: decide whether to retain the declared design, reject an unqualified input, or stop for model-owner review. A shape error does not mean the fitted intercept disappeared, and a returned number does not by itself establish statistical validity.
State the fitted design before preparing a prediction
The starting point is the declared model, not whatever shape a convenience function happens to emit for the next request. This fixture has one authored raw feature, x, and one declared two-coordinate design:
Layer | Columns | Meaning |
Raw input | [x] | One observed predictor supplied by the caller |
Model design | [const, x] | Intercept coordinate followed by the predictor |
Parameters | [3, 2] | One coefficient for each declared design coordinate |
The authored relationship is y = 3 + 2x. Training values are x=[-1, 0, 1, 2], with literal targets y=[1, 3, 5, 7]. Training already calls the explicit design(train) constructor; this investigation does not test a default add_constant(train) training path. That boundary is important because the failure under examination occurs during prediction preparation, after a two-coordinate model has already been fitted.
For the non-formula array/DataFrame API, statsmodels documents that OLS does not automatically add an intercept; the user supplies the exogenous design. The documentation also describes hasconst as an indication that the right-hand side contains a user-supplied constant, not an instruction to manufacture a column.
So the prediction question is concrete: can each unchanged observation be turned back into [1, x] before multiplication by the already-fitted parameter vector? For example, x=1 must arrive as [1, 1] if the declared design is [const, x]. Supplying only [1] is not a request to “use the same model with one fewer column”; it is a different design width.
This article deliberately leaves broader regression assumptions and interpretation outside that interface question. Refonte Learning’s statistics guide discusses uncertainty, sampling, confounding, regression assumptions and model evaluation; here the issue is more mechanical: whether an already-declared coordinate reaches prediction at all.
Arithmetic consistency is therefore necessary evidence, not a scientific endorsement. If a maintainer cannot establish whether the fitted specification actually includes an intercept, adding one to make an exception disappear is not a repair. Recover the model specification first.
Follow the nonzero constant detection
The public statsmodels.tools.tools.add_constant interface documents three has_constant policies: skip, raise and add. skip is the default; add requests insertion despite detected constant data; raise converts detection into an exception. prepend=True controls whether the new ones column appears first, and for pandas inputs that inserted column is named const.
The exact statsmodels 0.15.0 tools.py source matters because pandas input takes a specific route. add_constant recognizes the pandas object and delegates to add_trend(..., trend="c", prepend=..., has_constant=...). Nothing in that call retrieves the fitted OLS object, its exog_names, or the parameter vector. The utility examines the object it has just been given.
The corresponding tagged tsatools.py implementation makes the detection rule more precise than the short public phrase “has a constant.” For a pandas column, its local constant check is effectively: range equals zero and at least one value is nonzero. If a detected column exists and the policy is skip, the new constant trend is removed from the construction. If the policy is add, that skip branch is not taken.
That is why “add_constant skips the intercept” is too loose unless the input values and version-specific path are also stated. The API prose is the public contract; the pinned implementation explains the observed nonzero qualifier in this finite-numeric DataFrame experiment.
A raw predictor can look constant in the current batch
Consider four prediction inputs:
Raw x batch | Within-batch range | Any nonzero? | Default result in this lab |
[0, 1] | 1 | Yes | [const, x] |
[5] | 0 | Yes | [x] |
[5, 5] | 0 | Yes | [x] |
[0] | 0 | No | [const, x] |
For [5], the sole predictor column has no variation because a one-element range is zero, and the value is nonzero. For [5, 5], the larger batch still has zero range and contains nonzero values. Both therefore satisfy the tested detection. [0] has zero range too, but it fails the nonzero part of the condition and receives a newly inserted const. This behavior follows the 0.15.0 pandas implementation just cited.
The critical semantic distinction is between constant in this argument and the model’s intended intercept coordinate. Raw x=5 remains the predictor x; its numerical constancy within one particular call does not transform it into the separately declared intercept column. The detector cannot know that local application meaning because it is not consulting the fitted design.
This article keeps that claim narrow: finite numeric DataFrames on the recorded stack. It does not generalize the pandas helper’s mixed-type protection to arbitrary object-valued inputs, nor does it use private helpers.
Pin the environment and define an independent oracle
The commissioning reference is scoped to Python 3.12.14 on Linux x86_64 with glibc 2.39, statsmodels 0.15.0, pandas 2.2.3, NumPy 2.3.5, SciPy 1.17.0 and Patsy 1.0.2. The statsmodels stable documentation currently identifies itself as version 0.15.0, but a “stable” URL is a moving documentation selector rather than an immutable source artifact; the tagged GitHub source URLs used above preserve the implementation inspected for this baseline.
Patsy is imported because it belongs to the recorded dependency environment, not because this exercise executes a formula workflow. The OLS experiment uses DataFrames and the array-style interface throughout. Formula construction is intentionally outside scope.
The wider ecosystem context is available in Refonte Learning’s overview of Python libraries for analytical work, but this reproduction deliberately pins versions rather than relying on an ecosystem-level description.
An isolated virtual environment is useful here because it makes the intended dependency set explicit. It is not advice to replace dependencies in an existing analytical environment without its own change control. The script itself verifies statsmodels, pandas and NumPy versions as hard preconditions and records SciPy and Patsy versions in the report; that is useful provenance, but it is not a complete transitive dependency lock.
The supplied reference run is the evidence baseline for this article. An independent rerun on that baseline was unavailable: the verification environment had Python 3.13.5 and statsmodels 0.14.6, lacked Python 3.12, and could not download the requested packages because external package resolution was unavailable. Results from that fallback environment would not establish new evidence for the requested 0.15.0 baseline.
Keep expected answers independent of the fitted result
The oracle is authored before prediction:
training x = [-1, 0, 1, 2];
training y = [1, 3, 5, 7];
expected coefficient vector [3, 2];
expected query predictions [3, 5, 7] for x=[0,1,2];
expected repeated-value predictions [13, 13] for x=[5,5].
Those expected predictions come from the literal affine specification 3 + 2x, not from calling the fitted model once and using that output as the expected result of another call. That separation prevents a self-comparison from masquerading as an independent known-answer test.
The fixture accepts absolute error up to 1e-12 for these small controlled calculations. That tolerance belongs to this authored numerical example; it is not a general business-precision policy.
The x=5 control is intentionally outside the training range [-1,2]. Its role is only to test design construction and arithmetic with fixed coefficients: [1,5] @ [3,2] = 13. A successful value of 13 does not validate extrapolation for a real scientific or business model.
The supplied reference run started at 2026-11-02T08:09:25.022989+00:00, finished at 2026-11-02T08:09:25.114144+00:00, exited 0 and reported PASS_11_CASES. Those timestamps are provenance, not a benchmark.
Run the complete design-construction laboratory
Save the following source as ml_constant_fixture.py. The bytes below match the supplied fixture: 177 lines, 739 whitespace-separated words, SHA-256 29d8198765867a5016936ff4d5426a40494748bed47a129dff2cd05e396325c2. The digest identifies the source bytes; it does not independently prove that any historical run occurred.
Use the requested interpreter and dependency versions for a comparable run:
python3.12 -m venv .venv-ols
.venv-ols/bin/python -m pip install numpy==2.3.5 pandas==2.2.3 scipy==1.17.0 patsy==1.0.2 statsmodels==0.15.0
.venv-ols/bin/python ml_constant_fixture.py > ml_constant_results.json
If the interpreter patch level or package versions differ, record the change rather than treating the result as the same baseline. If an import fails before the program writes a report, there is no successful fixture report to interpret. Preserve the trailing newline when checking the source digest.
"""Owned OLS design-construction controls; no scientific or serving approval."""
import hashlib, json, platform, sys
from datetime import datetime, timezone
from pathlib import Path
import numpy as np
import pandas as pd
import scipy, statsmodels, patsy
from statsmodels.regression.linear_model import OLS
from statsmodels.tools.tools import add_constant

RAW_NAMES, DESIGN_NAMES = ['x'], ['const', 'x']
CALLS = 0

def require(ok, message):
    if not ok:
        raise RuntimeError(message)

def frame(values, ids=None):
    return pd.DataFrame({'x': values}, index=ids, dtype='float64')

def close(actual, expected):
    a, e = np.asarray(actual), np.asarray(expected)
    require(a.shape == e.shape and np.isfinite(a).all()
            and np.all(np.abs(a - e) <= 1e-12), 'Authored affine oracle mismatch')

def design(raw):
    if not isinstance(raw, pd.DataFrame) or list(raw.columns) != RAW_NAMES:
        raise ValueError('Expected raw x only; no pre-added constant')
    if not raw.index.is_unique or len(raw) == 0 or raw['x'].dtype != np.dtype('float64'):
        raise ValueError('Unqualified row identities, size or dtype')
    values = raw.to_numpy()
    if not np.isfinite(values).all() or np.any(np.abs(values) > 10):
        raise ValueError('Unqualified numerical input')
    result = add_constant(raw, prepend=True, has_constant='add')
    require(list(result.columns) == DESIGN_NAMES and result.index.equals(raw.index),
            'Design labels changed')
    require(result.to_numpy().tolist() == [[1., float(x)] for x in raw['x']],
            'Design values changed')
    return result

def guarded_predict(fitted, raw):
    global CALLS
    prepared = design(raw)
    CALLS += 1
    return fitted.predict(prepared).tolist()

def observe_default(fitted, raw):
    prepared = add_constant(raw)
    report = {'columns': list(prepared.columns), 'shape': list(prepared.shape),
              'design': prepared.to_numpy().tolist()}
    try:
        report.update(status='RETURNED', predictions=fitted.predict(prepared).tolist())
    except ValueError as error:
        report.update(status='VALUE_ERROR', error=str(error))
    return report

def main(report):
    require(statsmodels.__version__ == '0.15.0' and pd.__version__ == '2.2.3'
            and np.__version__ == '2.3.5', 'Package baseline')
    train = frame([-1., 0., 1., 2.], ['T1', 'T2', 'T3', 'T4'])
    snapshot = train.copy(deep=True)
    target = pd.Series([1., 3., 5., 7.], index=train.index)
    fitted = OLS(target, design(train), missing='raise').fit()
    frozen_params = fitted.params.copy()
    cases = report['cases']

    def record(identity, observation, meaning):
        cases.append({'case': identity, 'observation': observation,
                      'meaning': meaning, 'status': 'PASS'})

    close(fitted.params.tolist(), [3., 2.])
    require(fitted.model.exog_names == DESIGN_NAMES, 'Fitted design names')
    record('A01', {'params': fitted.params.tolist(), 'expected_params': [3., 2.],
                  'names': fitted.model.exog_names}, 'Known affine training control')

    for identity, values, names, status, expected in [
        ('A02', [0., 1.], DESIGN_NAMES, 'RETURNED', [3., 5.]),
        ('A03', [5.], RAW_NAMES, 'VALUE_ERROR', None),
        ('A04', [5., 5.], RAW_NAMES, 'VALUE_ERROR', None),
        ('A05', [0.], DESIGN_NAMES, 'RETURNED', [3.]),
    ]:
        observed = observe_default(fitted, frame(values))
        require(observed['columns'] == names and observed['status'] == status,
                identity + ' default construction')
        if expected is not None:
            close(observed['predictions'], expected)
        record(identity, {'values': values, 'expected_columns': names,
                         'expected_status': status, **observed},
              'Default detection depends on the current values, not fitted design')

    queries = frame([0., 1., 2.], ['Q1', 'Q2', 'Q3'])
    grouped = observe_default(fitted, queries)
    singles = [observe_default(fitted, queries.iloc[[i]]) for i in range(3)]
    close(grouped['predictions'], [3., 5., 7.])
    require([r['status'] for r in singles] == ['RETURNED', 'VALUE_ERROR', 'VALUE_ERROR'],
            'Default partition control')
    record('A06', {'grouped': grouped, 'single_rows': singles},
           'The unchanged observations do not retain a usable default design when split')

    fixed_group = guarded_predict(fitted, queries)
    fixed_singles = [guarded_predict(fitted, queries.iloc[[i]])[0] for i in range(3)]
    fixed_repeated = guarded_predict(fitted, frame([5., 5.]))
    close(fixed_group, [3., 5., 7.])
    close(fixed_singles, [3., 5., 7.])
    close(fixed_repeated, [13., 13.])
    require(pd.concat([design(queries.iloc[[i]]) for i in range(3)]).equals(design(queries)),
            'Partitioned design equality')
    record('A07', {'grouped': fixed_group, 'single_rows': fixed_singles,
                  'repeated': fixed_repeated, 'helper_predictions': CALLS},
           'Explicit construction meets the authored partition contract')

    try:
        add_constant(frame([5.]), has_constant='raise')
    except ValueError:
        raised = True
    else:
        raised = False
    zero = add_constant(frame([0.]), has_constant='raise')
    require(raised and list(zero.columns) == DESIGN_NAMES, 'Raise versus zero control')
    record('A08', {'nonzero_raises': raised, 'zero_columns': list(zero.columns)},
           'Raise is a diagnostic policy, not a repair for an intended raw predictor')

    prepared = design(queries)
    duplicate = add_constant(prepared, has_constant='add')
    require(list(duplicate.columns) == ['const', 'const', 'x'], 'Blind add is not idempotent')
    before = CALLS
    try:
        guarded_predict(fitted, prepared)
    except ValueError:
        pass
    else:
        raise RuntimeError('Pre-added constant was admitted')
    require(CALLS == before, 'Prepared input reached prediction')
    record('A09', {'blind_add_columns': list(duplicate.columns), 'helper_call_delta': CALLS-before},
           'Only declared raw features may enter the explicit builder')

    flagged = OLS(target, train, hasconst=True, missing='raise')
    require(flagged.exog.shape == (4, 1) and flagged.exog_names == RAW_NAMES
            and flagged.k_constant == 1, 'hasconst does not insert a column')
    record('A10', {'shape': list(flagged.exog.shape), 'names': flagged.exog_names,
                  'k_constant': flagged.k_constant},
           'OLS hasconst is a declaration, not design construction; this model is not fitted')

    bad = {'extra_column': queries.assign(extra=1.), 'nan': frame([float('nan')]),
           'infinity': frame([float('inf')]), 'empty': frame([])}
    rejected, before = [], CALLS
    for label, raw in bad.items():
        try:
            guarded_predict(fitted, raw)
        except ValueError:
            rejected.append(label)
        else:
            raise RuntimeError('Missing admission rejection')
    require(rejected == ['extra_column', 'nan', 'infinity', 'empty'] and CALLS == before,
            'Admission case inventory')
    record('A11', {'rejected': rejected, 'helper_call_delta': CALLS-before},
           'Invalid authored inputs stop before helper prediction')
    require(train.equals(snapshot) and fitted.params.equals(frozen_params), 'Baseline changed')
    require(CALLS == 5 and [c['case'] for c in cases] == [f'A{i:02}' for i in range(1, 12)],
            'Evidence inventory')
    report.update(status='PASS_11_CASES', helper_prediction_calls=CALLS,
                  training_preserved=True, fitted_params_preserved=True)

if name == '__main__':
    report = {'status': 'FAIL', 'cases': [], 'started_utc': datetime.now(timezone.utc).isoformat(),
              'source_sha256': hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
              'environment': {'python': sys.version, 'platform': platform.platform(),
                              'statsmodels': statsmodels.__version__, 'pandas': pd.__version__,
                              'numpy': np.__version__, 'scipy': scipy.__version__,
                              'patsy': patsy.__version__}}
    try:
        main(report)
    except Exception as error:
        report['error'] = {'type': type(error).__name__, 'message': str(error)}
    report['finished_utc'] = datetime.now(timezone.utc).isoformat()
    print(json.dumps(report, indent=2, allow_nan=False))
    sys.exit(0 if report['status'] == 'PASS_11_CASES' else 1)
The condensed commissioning ledger is:
Case | Required reference observation |
A01 | Explicit training design [const,x]; coefficients ≈[3,2]. |
A02 | Default [0,1] creates [const,x], shape 2×2; predictions ≈[3,5]. |
A03 | Default [5] leaves [x], shape 1×1; prediction raises ValueError. |
A04 | Default [5,5] leaves [x], shape 2×1; prediction raises ValueError. |
A05 | Default [0] creates [const,x], shape 1×2; prediction 3. |
A06 | Grouped Q1–Q3 returns ≈[3,5,7]; singleton statuses RETURNED, VALUE_ERROR, VALUE_ERROR. |
A07 | Explicit grouped/singleton designs agree; predictions ≈[3,5,7], repeated ≈[13,13]; five helper calls. |
A08 | has_constant='raise' raises for [5]; [0] still receives [const,x]. |
A09 | Blind add gives [const,const,x]; guarded pre-prepared input is rejected; helper delta 0. |
A10 | hasconst=True leaves exog 4×1 with names [x], k_constant=1; object not fitted. |
A11 | Extra field, NaN, infinity and empty input rejected; helper delta 0. |
The supplied reference outcome is PASS_11_CASES, process exit 0, the stated source digest, helper_prediction_calls=5, and preserved snapshots of the original training DataFrame and fitted parameter Series. “Eleven passing cases” includes expected exceptions and rejections; it does not mean eleven predictions returned successfully.
Compare one varying batch with the same rows split
A06 is the central batch prediction invariance check. The three identified observations are Q1=0, Q2=1, Q3=2. Prepared together by default, x=[0,1,2] has nonzero range, so add_constant constructs a 3×2 design with columns [const,x]. The fitted two-parameter model can therefore evaluate all three rows and return approximately [3,5,7].
Now keep those same row values and identities but call the constructor separately on queries.iloc[[i]]. Q1 contains x=0, so its singleton receives [const,x] and predicts 3. Q2 contains only nonzero x=1; Q3 contains only nonzero x=2. Under the pinned pandas detection, each is treated as a nonzero constant column, so default construction returns a 1×1 [x] frame instead.
Prediction then encounters a dimensional mismatch because the supplied exogenous row has one coordinate while the fitted parameter vector has two. The 0.15.0 OLS implementation ultimately evaluates supplied exog and parameters with np.dot(exog, params). The commissioning fixture records these as ValueError outcomes; exact wording should be treated as stack-specific rather than a cross-version API promise.
This is different from Refonte Learning’s prior discussion of feature identity at prediction time, where width stayed constant while feature positions could be permuted. Here x never changes identity or order; the extra intercept coordinate is either present or absent.
Sorting rows, adding more training observations, or editing coefficients would not address the demonstrated constructor decision. The difference is created before the dot product.
Preserve row identity while comparing the two paths
The fixture does not invent new singleton observations. It selects each existing row with queries.iloc[[i]], preserving the row’s index. The explicit-constructor path later concatenates the individually prepared rows and checks equality with design(queries).
That equality matters because equal prediction values alone would be weaker evidence. The tested contract says Q1, Q2 and Q3 retain their identities and become exactly [1,0], [1,1] and [1,2], respectively, regardless of whether the three rows are prepared together or as this particular singleton partition.
The experiment therefore establishes partition consistency for one authored three-row case. It does not prove a universal property over every conceivable partitioning, dtype, number of features or preprocessing stack.
Use zero and repeated values as diagnostic controls
A03, A04 and A05 prevent two common misdiagnoses.
First, A04 shows that the behavior is not confined to statsmodels add_constant single row inputs. A repeated two-row batch, [5,5], still has zero range and nonzero values, so the same detection is triggered and the result stays [x]. That means “just buffer several requests before calling add_constant” is not an established solution: a larger constant-valued prediction batch can reproduce the same missing design coordinate. The 0.15.0 implementation makes this deterministic for the tested inputs.
Second, A05 prevents the opposite overstatement. A singleton [0] does not satisfy the nonzero qualifier, so it receives [const,x] and returns the authored value 3. The correct explanation is therefore conditional: nonzero constant-valued columns in the current DataFrame can trigger the default skip policy. “Every singleton loses the intercept” is false for this implementation.
These controls are especially useful during review because they separate a value-dependent branch from vague claims of instability. Nothing random has been demonstrated. The same documented policy and pinned implementation produce different design widths because the detection result differs across current arguments.
Nor does the repeated-value test simulate a queue, request scheduler or production batching system. It supplies two rows directly to the utility. Any operational buffering policy would require its own evidence.
Construct the declared design from raw features only
A07 replaces inference with an explicit local contract. design(raw) accepts one DataFrame whose columns are exactly ['x'], then inserts the intercept with add_constant(raw, prepend=True, has_constant='add'). Because this function has already established that its input is raw x rather than a prepared design, forcing insertion is appropriate at this boundary.
The helper also checks conditions that belong to this laboratory’s application contract: a nonempty DataFrame; exact raw name x; unique row identities; float64 dtype; finite values; magnitude no greater than 10; exact output names [const,x]; unchanged index; and literal output rows [1., x]. These are not general statsmodels requirements.
Using has_constant='add' here is consistent with the public option: the API states that add inserts a column even when the input is detected as already constant. The important safety property does not come from add alone. It comes from pairing that policy with a raw-only admission boundary.
For Q1–Q3, A07 obtains [3,5,7] when the rows are prepared together and the same [3,5,7] when the three rows are prepared separately. The fixture additionally concatenates the three separately prepared DataFrames and requires that result to equal the grouped prepared design exactly. The repeated [5,5] case becomes two rows [1,5], giving the authored arithmetic [13,13].
No coefficients are refitted. The original fitted parameter Series is compared with its snapshot at the end of the fixture and remains equal. The source implementation of OLS prediction is consistent with this interpretation: when exogenous data are supplied, linear prediction evaluates their dot product with the parameter vector.
Make the raw-input boundary explicit
There are two owners in this narrow interface.
The caller supplies raw x. The constructor owns the insertion of const. A caller must not sometimes send [x] and sometimes send [const,x] to this same entry point, because that would make has_constant='add' unsafe.
The boundary therefore rejects already-prepared frames rather than trying to infer whether they are “probably okay.” Unknown schemas do not get guessed into the declared design. They are rejected or sent for specification review.
That is the practical remedy for the statsmodels intercept prediction batch problem demonstrated here: stop asking each batch to rediscover a model coordinate whose existence is already part of the model specification.
Demonstrate why adding the constant twice is unsafe
A09 is the control against turning the previous recommendation into “always use has_constant='add' everywhere.”
Start with prepared = design(queries). Its columns are already [const,x]. Calling add_constant(prepared, has_constant='add') deliberately asks statsmodels to insert another ones column even though a constant is present. The resulting DataFrame has labels [const,const,x]. That follows directly from the public meaning of add and the pandas construction path, which concatenates the new trend frame with the existing object rather than enforcing label uniqueness.
The fixture observes that duplicate-column result but does not fit a model or call prediction with it. Instead, it sends the already-prepared frame to guarded_predict. The raw-only design() function sees that its columns are not exactly ['x'] and raises ValueError before CALLS is incremented.
A09 then requires the helper-call delta to remain zero. That detail separates two claims:
the invalid prepared input was blocked before the guarded prediction call;
the fixture has not proven that every conceivable malformed input is blocked.
The first claim is executable evidence. The second is a coverage limit.
This is why add_constant has_constant add is a constructor policy, not an idempotent “ensure constant” operation. Calling it after the model design is already prepared can create a duplicate intercept column. The safe pattern here is narrower: force insertion only after the interface has verified that it owns a raw one-column x frame.
Separate constructor policies from model declarations
Several similarly named controls govern different responsibilities. Treating them as interchangeable makes the debugging process much harder.
Control | What it controls here | What it does not do |
add_constant(..., has_constant='skip') | Leaves input unchanged when the current argument is detected as constant | Does not consult the fitted OLS design |
add_constant(..., has_constant='add') | Inserts a ones column despite detected constant data | Does not prevent duplicate constants if input is already prepared |
add_constant(..., has_constant='raise') | Raises when current input is detected as containing a constant | Does not manufacture the separately intended intercept for a legitimate nonzero raw singleton |
OLS(..., hasconst=True) | Declares constant treatment to the model object | Does not insert a missing const column |
The skip, add and raise behavior is documented by add_constant, while the exact pandas detection and concatenation behavior are visible in the 0.15.0 add_trend implementation.
A08 illustrates why raise is a diagnostic choice, not the repair. add_constant(frame([5.]), has_constant='raise') raises because x=5 is detected as a nonzero constant in that argument. Yet raw x=5 is legitimate under the authored model contract and still needs to become [1,5]. Converting the skip into an exception makes the ambiguity visible but does not construct the required design.
The contrast with fitted preprocessing output schemas is useful. That earlier Refonte workflow discusses transformation behavior learned at fit time. add_constant, by contrast, is being called afresh on the current DataFrame; the source path shown here carries no learned prediction-time state about the original OLS design.
hasconst=True does not insert the intercept
A10 constructs OLS(target, train, hasconst=True, missing='raise') using train, which contains only the single raw x column. The fixture requires exog.shape == (4,1), exog_names == ['x'] and k_constant == 1.
That is consistent with the OLS documentation: an intercept is not included by default for this route, and hasconst=True says the right-hand side should be treated as containing a user-supplied constant.
The A10 model object is never fitted. Therefore nothing in this experiment supports claims about its coefficients, residuals, fit statistics or predictions. Its sole purpose is to show that hasconst and add_constant(..., has_constant=...) solve different problems despite their similar names.
Avoid an inappropriate rank test on prediction batches
A one-row design [1,5] has shape 1×2 and cannot have full column rank two. That fact does not make it unusable for evaluating an already-known two-coefficient vector.
The distinction is between estimation and evaluation. During prediction, statsmodels’ OLS implementation takes the supplied exogenous design and parameter vector and returns their dot product. A 1×2 row multiplied by a length-two parameter vector is dimensionally valid, regardless of whether that one-row matrix could identify two unknown coefficients from scratch. OLS.predict describes prediction as returning linear predicted values from a supplied design, and the tagged implementation shows the np.dot(exog, params) calculation directly.
Estimation has a different concern. The statsmodels Pitfalls page warns that linear-model families use generalized inverses and that rank-deficient exogenous matrices can be accepted rather than automatically rejected, with parameters requiring scrutiny in such situations.
Those two facts should not be collapsed into a blanket rule such as “reject every rank-deficient prediction batch.” Such a rule would reject every valid singleton with more than one declared model coordinate, including the [const,x] row this workflow is trying to preserve.
Conversely, the ability to evaluate [1,5] @ [3,2] does not justify fitting duplicate intercept columns, ignoring multicollinearity during estimation, or assuming a returned prediction is scientifically appropriate. No rank-deficient fitting experiment is performed here.
Repair the constructor while preserving the baseline
A bounded recovery procedure follows directly from the evidence.
First, stop changing the affected prediction path while its design specification is uncertain. Establish from the model owner or fitting code whether the fixed model was trained with [const,x]. The documented OLS route will not silently recreate that intercept for you at prediction time.
Second, distinguish raw observations from model-ready design matrices. In this fixture, raw input means exactly one float64 column named x. Prepared input means exactly [const,x]. Do not allow the same interface to accept both forms.
Third, construct the design explicitly from qualified raw rows. Here that means prepend=True, has_constant='add' after raw-only admission has established that no pre-added intercept is present. Then check labels, identity and literal rows before prediction.
Fourth, reconcile unchanged known observations through both relevant groupings. Q1–Q3 must yield the same prepared rows and the literal predictions [3,5,7] whether handled together or separately. The [5,5] control must yield [13,13]. These values establish the local arithmetic contract, not external model quality.
Fifth, keep the fitted baseline fixed during the repair. The fixture checks that the original training DataFrame equals its snapshot and that the fitted parameter Series equals its frozen copy. That is narrower than proving that every internal model attribute, serialized artifact or external process state stayed unchanged.
The same discipline appears in Refonte Learning’s guidance on preserving source meaning during data cleaning: define the intended meaning of the input before transforming it rather than “fixing” values until a downstream operation succeeds. Here, source meaning is especially simple: x remains x; the constructor owns const.
If input origin or intercept specification cannot be recovered, hold the change for model-owner review. This procedure is proposed handoff practice; it is not an executed deployment, rollback or service-recovery test.
Reconcile the ledger into an acceptance decision
The ledger supports a compact acceptance rule.
Decision | Evidence required |
Accept the constructor for this fixture | Exact raw schema [x]; declared output [const,x]; literal [1,x] rows; row identities retained; grouped/singleton equality for Q1–Q3; authored arithmetic matches; all A01–A11 cases present; five guarded helper predictions |
Hold | Package/interpreter baseline mismatch not accounted for; unexpected exception; missing report; source digest mismatch; undeclared input schema; unknown intercept specification; disagreement with the independent oracle |
Model-owner review | It is unclear whether the fitted specification actually contains an intercept, or whether the caller is supplying raw versus already-prepared design data |
The five guarded predictions are exact: one grouped call, three singleton calls and one repeated-value call in A07. The default-path predictions in observe_default are not part of that counter. A09 records helper-call delta zero because a pre-prepared frame is rejected before prediction. A11 also records delta zero because its four challenged inputs fail admission first.
Expected failures are evidence, not blemishes to remove from the test report. A03 and A04 deliberately expect ValueError; A08 deliberately expects the raise policy to reject nonzero [5]; A09 and A11 deliberately expect application-level rejection. A green PASS_11_CASES means every case behaved as specified, not that every path returned a prediction.
Likewise, a returned number does not establish correctness beyond the bounded check. A05’s prediction of 3 confirms that [0] became [1,0] and multiplied consistently by the fixed coefficients. It says nothing by itself about model suitability, calibration, uncertainty, causal meaning or operational approval.
Keep untested guards outside the coverage claim
A11 explicitly challenges four invalid inputs: an extra column, NaN, infinity and an empty frame. A09 separately challenges an already-prepared [const,x] frame. These are the only rejection cases individually exercised in the supplied case ledger.
The constructor also contains branches for non-DataFrame input, duplicate indices, wrong or renamed columns, non-float64 dtype and values with absolute magnitude above 10. Those conditions exist in the source, but this fixture does not include individual named cases that challenge each of them.
That distinction is essential in numerical interface reviews. Code presence is not the same as executed coverage. The appropriate statement is that the constructor contains those guards while the authored case inventory explicitly demonstrates the A09 and A11 rejections listed above.
Nor should the fixture be broadened into a universal prediction design matrix validation framework. It covers one feature, one intercept-first design, one DataFrame dtype, one partition comparison and one statsmodels route.
Assign ownership and bound the next application
A practical ownership split keeps the design decision from becoming another implicit convention.
The model owner should own the declared model coordinates: whether an intercept exists, what the predictor means, and the order [const,x]. That information should not be reconstructed by inspecting whatever values happen to arrive in the next prediction batch.
The input-boundary maintainer should own the distinction between raw and prepared data. In this fixture, that means admitting only raw x, inserting const exactly once, preserving the index and rejecting unknown schemas rather than guessing.
The reviewer should own the evidence interpretation: source digest, environment versions, case inventory, expected errors, known-answer arithmetic and any documented deviations from the reference stack. These roles are recommended operational practice rather than statsmodels API requirements.
A later multi-feature adaptation needs its own qualification. So does an ndarray or Series variant, a formula-based model, a different dtype policy, another intercept position, a constant-predictor training fit or an online service implementation. None inherits PASS_11_CASES merely because it also calls add_constant.
The practical decision is therefore bounded and auditable. If the specification says [const,x] and the caller supplies qualified raw x, use a constructor that deterministically emits [const,x] instead of asking each batch to rediscover whether a constant “already exists.” If the input violates the declared raw boundary, reject it. If the intercept specification itself is unknown, stop for model-owner review.
That preserves numerical construction without pretending to answer the separate questions of domain meaning, extrapolation validity, scientific adequacy or operational authorization.
Continue with Python and statistical modelling foundations
This exercise is fundamentally about making a numerical interface explicit: know which columns a fixed model expects, know which component constructs them, and verify that regrouping unchanged observations does not silently change that declared design.
Refonte Learning’s Data Science & AI programme currently lists Python Data Science, Statistical Modelling, Model Optimization & Problem-Solving Techniques, EDA and Data Visualization, Machine Learning and Predictive Modelling among its advertised competencies. Its FAQ also names Python, Jupyter Notebook, Pandas, NumPy, Matplotlib, scikit-learn and TensorFlow among tools used in the course.
Those published topics provide a reasonable foundation for further practice with explicit analytical interfaces, but the programme page does not establish that statsmodels, OLS, add_constant, hasconst, the exact software versions here or this laboratory are curriculum components. Prospective learners should inspect the current programme details for the scope that matters to them.
The concrete skill practised here is narrower and immediately reusable: when grouping changes, inspect the design actually supplied to the fixed model. For this statsmodels 0.15.0 DataFrame path, the evidence shows why a varying batch can receive [const,x] while a nonzero singleton or repeated-value batch receives only [x], and why an explicit raw-input constructor can retain the declared intercept coordinate without refitting or altering coefficients.