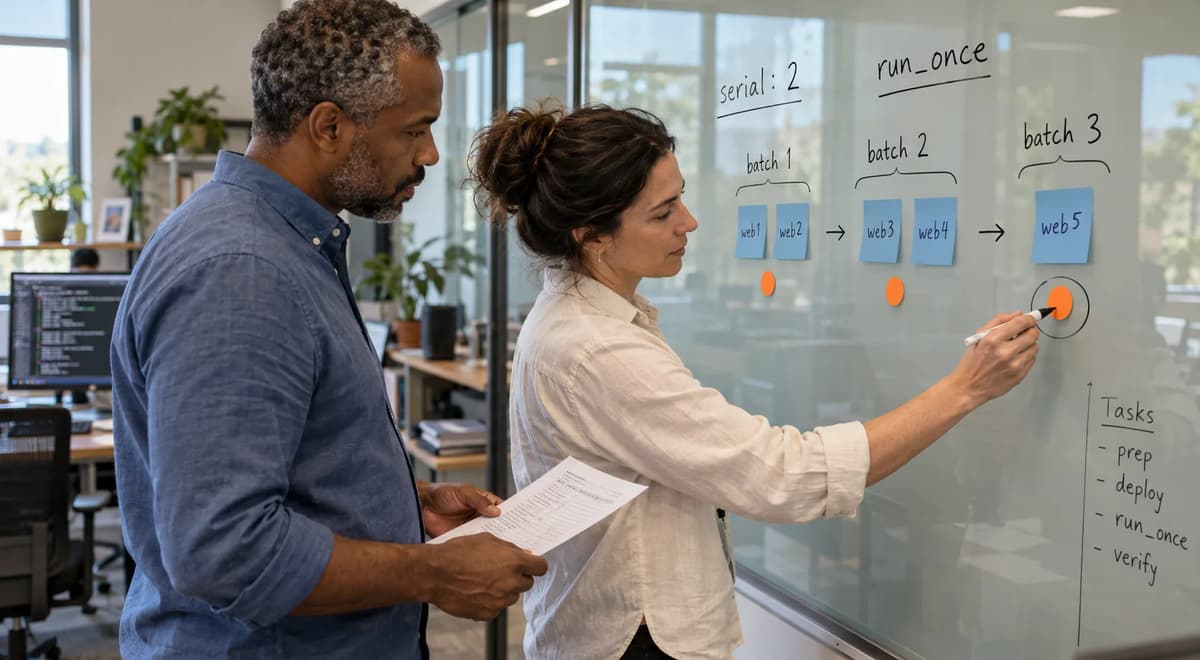
A five-host rollout contains a task that is intended to act like a singleton. With no serial setting, the supplied laboratory records one invocation. Add serial: 2, keep run_once: true, and the same synthetic action is recorded three times: once for the node01,node02 batch, once for node03,node04, and once for node05. Nothing “ignored” run_once. The scope changed.
That distinction is the diagnostic center of this playbook. The Ansible execution-strategy guide documents serial as a way to partition a play into batches and run_once as selecting one host in the current batch; used together, a run_once task runs once in each serial batch. The operational mistake is to read the English word once as a durable singleton guarantee across the whole rollout, across changed target selections, or across separate ansible-playbook launches.
The evidence here is deliberately narrower and stronger than a hypothetical deployment story. The supplied preparation, completed on 2026-10-26 under CPython 3.12.14 and ansible-core 2.19.3, used six logical inventory aliases on one local machine and wrote only synthetic event files inside an owned temporary directory. It ran ten cases and reported PASS_10_CASES. The analysis uses the supplied execution record, without a new fixture run, and Ansible documentation accessed at the same research cutoff.
The goal is an invocation ledger and a repair decision. The owner must declare whether the contract is once per batch, once per selected-play invocation, or an ordered prerequisite before fleet work. Host selection, execution location, concurrency, process return codes, and durable side-effect semantics are evaluated separately.
Define the scope of the word once
Before reviewing YAML, define the acceptance unit. “Once” can describe at least four different contracts: one task instance per host, one action per serial batch, one action during one selected playbook invocation, or a durable operation that must not be repeated across later launches. Those contracts are not interchangeable, and no spelling of run_once, delegate_to, or throttle: 1 turns one into another by implication. The Ansible Playbook Keywords reference says run_once bypasses the ordinary host loop by attempting the task on the first available host and then applying its results and facts to active hosts in the same batch. serial, separately, defines how the play target is batched.
For this diagnostic, the side-effect owner’s test policy is explicit: an ordinary “singleton” marker is expected either once per serial batch when that is the declared design, or once per selected-play invocation when the action represents a whole-rollout singleton. R2 therefore passes as a measurement of Ansible’s batch behavior but requires REPAIR if the application policy was one action for the whole five-host invocation. R6 passes the narrower current-play selection policy. R8 proves that this policy still produces one action on each separate launch, not a durable once-ever operation.
That separation matters because module idempotence and invocation cardinality answer different questions. A module can be idempotent when called repeatedly, while an arbitrary ansible.builtin.command can perform a non-idempotent external effect every time it is invoked. Conversely, a task can be invoked exactly once in a particular run and still perform the wrong operation. The broader automation foundations for system administrators are useful context for repeatable configuration work, but they do not supply a universal “safe to call twice” property for arbitrary commands.
A review should therefore carry five columns, mentally or literally: invocation count, logical target selection, execution destination, concurrency bound, and durable effect identity. In this fixture, event files prove the first two and help correlate the third; throttle tests the fourth; the fifth is intentionally out of scope. There is no database migration, distributed deduplication record, transaction token, or exactly-once delivery protocol. ACCEPT_TESTED_SCOPE means the local scheduling contract matched its declared expectation, not that a real-world singleton side effect is safe.
Never approve a “run once” task until its owner can complete the sentence, “Once per what?” Per-batch and per-invocation rules can be tested here; a never-repeat-across-launches rule requires durable operation identity outside this fixture.
Freeze the play, inventory, and selection
The supplied fixture removes infrastructure variability so the scheduling question has nowhere to hide. The inventory contains node01 through node05 in group fleet and one controller alias in group coordinator. All six aliases use ansible_connection: local and the active Python interpreter. The play also states connection: local, become: false, gather_facts: false, strategy: linear, and order: sorted. The ansible.builtin.local connection documentation says local execution occurs on the controller rather than a remote machine, so six inventory names here are six logical identities, not six physical computers.
The recorded preparation environment was CPython 3.12.14, ansible-core 2.19.3, Jinja2 3.1.6, PyYAML 6.0.3, Linux 6.18.55 x86_64, glibc 2.39. The test ansible.cfg sets forks = 5, disables retry files and host-key checking, and redirects Ansible local and remote temporary paths into the owned scratch directory. The fixture uses only ansible.builtin.command and ansible.builtin.assert for the tested actions and barrier. The ansible.builtin.command documentation supports argv as a list and expand_argument_vars: false; the fixture uses those controls to avoid shell parsing and disable argument-variable expansion.
This is intentionally narrower than Terraform and Ansible infrastructure foundations: there is no provisioning layer, cloud account, service state, SSH connection, credential, privileged operation, or production inventory here. The lab isolates play scheduling and writes only event records.
The documentation cited in this article is the current rolling Ansible documentation directly opened on the 2026-10-26 research cutoff. That access date is not treated as an ansible-core 2.19.3 publication date or a feature-introduction date. The executable-version evidence instead comes from the supplied preparation report and its ansible --version probe. If a later installation behaves differently, its own version output, generated playbook, stdout/stderr, return code, and event ledger must be retained rather than silently replacing the observation with the expected count.
A target list and a serial batch are different populations
The variables make the scope visible. The Ansible Special Variables reference defines ansible_play_hosts_all as all hosts targeted by the play, while ansible_play_batch is the active set constrained by serial; ansible_play_hosts is the active play population not limited by serial. inventory_hostname remains the original inventory name for the current host even when delegation is used, and ansible_limit reflects the current --limit option.
For R2, ansible_play_hosts_all remains node01 through node05 in every event, while ansible_play_batch changes from [node01,node02] to [node03,node04] to [node05]. That is the difference between “who belongs to this selected play?” and “who is active in this pass?” The fixture pins order: sorted, which Ansible documents as alphabetical host-name ordering. The same documentation warns that default inventory order should not be equated with textual order in an inventory source. Failed/unreachable hosts, dynamic inventory mutation, custom strategies, and alternative ordering are excluded, so no broader host-selection guarantee should be inferred.
Make every real invocation leave its own evidence
A changed recap is not an invocation oracle. Neither is a shared counter that can be overwritten, a final file that contains only the last writer, or a claim that “the task showed changed three times.” The supplied fixture instead gives each helper invocation its own immutable event file: uuid.uuid4().hex + ".json", created with mode "x" so the helper will not overwrite an existing path. Every successful helper call therefore contributes one independently countable record to that case’s event directory.
Each record contains origin, batch, targets, kind, invocation, pid, and monotonic_ns. origin is the templated inventory_hostname; batch is the current ansible_play_batch; targets is ansible_play_hosts_all; kind distinguishes singleton, preflight, and rollout; and invocation distinguishes separate playbook launches in R8. The process ID and monotonic timestamp provide local ordering evidence for the helper processes. They are not presented as a distributed clock or as proof of physical execution on different machines.
That evidence design is stronger than relying on the Ansible recap because it measures the acceptance object directly: an actual helper process reached the point at which it created a unique event. The command task also returns its normal command result, so the report retains process return codes and command stdout/stderr. Ansible documents standard command execution through argv without a shell and exposes command return data; the fixture deliberately does not import the command module’s separate check-mode behavior into this article.
The distinction is also why this article only links to checking which Ansible validation tasks actually ran as a neighboring evidence problem. That article asks what a dry run really validates. This fixture performs ordinary command execution and counts actual event creation across scheduling scopes.
Keep the invocation oracle independent of the task result
The harness derives expected origins, batches, target lists, kinds, and return codes in Python before it evaluates the observed files. The execute() function then runs the generated playbook, reads every *.json event, sorts events by the helper’s local monotonic_ns, and compares the observed values with independent expected lists. It does not decide the expected count from Ansible’s recap after the fact.
The retained report also includes the generated inventory object, Ansible configuration text, generated playbook structures, each subprocess argv, return code, stdout and stderr, every decoded event, the source digest, and the helper digest. The supplied preparation identifies source SHA-256 950684e2259a1abfd7018f05cfc1d8c980030f6b6efebbae7793f5ac0ffb4dd3 and helper SHA-256 e41cafb3661ca7476bdaf2e158a3bf54fd3cfd873bc7413a7894f4e653e1123a. The temporary workspace is removed at the end, but the report has already serialized the evidence needed to review what ran.
A missing event is not automatically proof that the intended action “ran zero times correctly.” The play might have failed before the helper or evidence might be incomplete. Incomplete evidence is HOLD or RERUN, not a convenient zero-count success.
Compare one batch with three serial batches
R1 establishes the baseline. The play targets all five sorted fleet aliases, has no serial, and marks the synthetic command run_once: true. The supplied preparation records one event, originating from node01, with batch equal to all five nodes and targets equal to the same five-node selection. Under this controlled healthy selection, there is one tested batch and one action.
R2 changes one scheduling control: serial: 2. The selected population is still five aliases, but Ansible partitions the play into three passes: two hosts, two hosts, then one host. Its execution guide states that with serial, Ansible completes the play on the specified number of hosts before moving to the next batch; the same guide explicitly states that run_once used with serial runs on one host in each serial batch. The preparation observes exactly that documented interaction: three events with origins node01, node03, and node05.
Abbreviating each event to deterministic fields supplied by the preparation, the R2 ledger is:
{"origin":"node01","batch":["node01","node02"],"targets":["node01","node02","node03","node04","node05"],"kind":"singleton","invocation":1}
{"origin":"node03","batch":["node03","node04"],"targets":["node01","node02","node03","node04","node05"],"kind":"singleton","invocation":1}
{"origin":"node05","batch":["node05"],"targets":["node01","node02","node03","node04","node05"],"kind":"singleton","invocation":1}
The actual helper records also contain pid and monotonic_ns; those run-specific values were retained in the preparation report but are not invented here. The important observation is that the full target list stays fixed while the active batch changes, and one origin is selected from each batch.
R3 makes the interaction impossible to miss by setting serial: 1. Five selected hosts become five one-host batches, so run_once produces five actual helper invocations: node01, node02, node03, node04, and node05. Smaller batches do not move the guarantee outward to the entire play; they create more batch boundaries at which the batch-scoped rule applies. The measured sequence is therefore R1 = 1, R2 = 3, R3 = 5.
The repair decision depends on the declared policy, not on whether Ansible matched documentation. If the intended contract is “one pre-batch action for each rolling slice,” R2’s three events are ACCEPT_TESTED_SCOPE. If the contract is “one action for this selected five-host invocation,” the exact same R2 result is REPAIR: the scheduling primitive is correctly executing the wrong application scope.
Send every batch to one controller and count again
R4 keeps the R2 batch shape and run_once: true, then adds delegate_to: controller. The result is still three events with origins node01, node03, and node05. That count is the critical evidence: choosing one delegated destination does not collapse three batch-local task instances into one whole-play invocation.
The Ansible delegation guide documents delegation as choosing another host on which to execute a task. It also warns that delegation does not inherently serialize parallel task instances or resolve concurrent writes on the delegated host. In this fixture every inventory alias already uses the local connection, so all actions are physically executed on the controller machine anyway; R4 is about logical scheduling and delegated inventory context, not a test involving multiple remote machines. The configured destination becomes the controller alias, while the source task instances still arise once per serial batch.
The R4 deterministic event projection therefore has the same batch/origin sequence as R2. That is not a contradiction. delegate_to answers “where should this task instance execute?” run_once plus serial answers “how many batch-scoped task instances are selected?” Conflating those questions produces a common location-only repair: the operator sends everything to one coordinator and assumes that one destination implies one call. R4 demonstrates why that assumption earns REPAIR when the requirement is one invocation for the play.
Execution location does not redefine the host loop
Under delegation, Ansible preserves inventory_hostname as the original task host; connection variables and most delegated execution context come from the delegated host. The special-variable documentation likewise says inventory_hostname is not affected by delegation. That is why the helper’s origin remains node01, node03, or node05 instead of becoming controller.
The fixture should not be overread as a machine-identity detector. The helper receives an origin string from templating; it does not independently query a remote kernel and certify which physical server executed it. The playbook structure and Ansible command output establish that R4 was delegated to the controller alias, while the event records establish the originating logical host and batch. Because the local connection is used everywhere, there is only one physical machine in scope.
The operational lesson is to keep two ledger columns: logical origin/task selection and execution destination. A singleton design can be wrong in either column. Delegating a per-batch task to the correct controller does not fix its cardinality, and selecting one logical origin does not by itself establish durable ownership of an external side effect.
Limit concurrency without confusing it with cardinality
R5 removes run_once. It is an ordinary per-host task, still delegated to controller, still under serial: 2, with throttle: 1. The supplied preparation records five events, one for every fleet alias. That result separates concurrency from cardinality: one worker at a time is not the same thing as one total execution.
The Ansible keyword reference defines throttle as a limit on concurrent task runs, independent of the forks and serial limits except that it cannot raise concurrency above them. The strategy guide likewise describes throttle as restricting workers for a task or block. R5 therefore has five host-task instances but permits only one of those task instances to execute at a time. The count remains five.
This is an appropriate control for a different requirement. A rate-limited API, serialized write path, or resource-sensitive command may need throttle: 1 even though every target still requires its own operation. It is not a deduplication mechanism and it does not declare an application singleton. No throughput, race-frequency, or performance benchmark is claimed by the fixture; the recorded duration is simply provenance for one laboratory run.
Keep the controls distinct. forks caps Ansible’s available workers globally. serial partitions the hosts that progress through the play together. throttle imposes a lower concurrency ceiling on a task, block, or play. run_once changes task selection so one host in the current batch attempts the action. Only the last of those directly reduces ordinary host-task cardinality, and under serial it reduces it to one per batch, not necessarily one per playbook invocation.
R5 is therefore a useful negative control for an Ansible throttle versus run_once review. If a proposed repair for a repeated singleton consists only of throttle: 1, mark it REPAIR: it addresses simultaneous execution, not total invocation count. If serialization is independently required, it may remain in the final design, but it should be justified as a concurrency control rather than credited with singleton semantics.
Select one host from the current play
R6 removes run_once and uses an ordinary task guarded by when: inventory_hostname == ansible_play_hosts_all[0]. The play still targets the five-node fleet, still uses serial: 2, and still runs in sorted order. The supplied preparation records exactly one event: origin node01, batch [node01,node02], targets node01 through node05.
This repair changes the selection rule. Instead of asking Ansible to choose one host from each active batch, the condition compares every host’s original inventory name with the first member of the full play target list. Ansible’s own strategy guide recommends this construct when a task must run only once regardless of serial, and its special-variable reference defines ansible_play_hosts_all as all hosts targeted by the play. Under the fixture’s fixed linear strategy, healthy host set, sorted ordering, and full selection, that rule yields one node01 action.
The important qualification is that this is an application selection rule, not an exactly-once primitive. Its guarantee is bounded by the selected play invocation and the assumptions that make [0] meaningful. The fixture does not test failed or unreachable selected hosts, dynamic inventory changes, custom strategies, or alternate ordering. It does not invent a fallback if the chosen host cannot execute the task. A production design that needs fallback leadership must define and test that policy separately rather than assuming Ansible will promote the “next” host in the desired way.
The current-play guard is therefore acceptable when the owner really means: “For this invocation, among the hosts selected into this play under the reviewed ordering and failure assumptions, choose the first selected host as the sole logical origin.” That is a narrower contract than “this cluster has a permanent leader” and much narrower than “this external operation can never repeat.” The acceptance label is ACCEPT_TESTED_SCOPE, not “exactly once.”
A new limit can choose a different singleton
R7 makes the selection dependency explicit. It runs the same guarded play with --limit node03:node04:node05. The observed event count remains one, but the origin changes to node03; its first active serial batch is [node03,node04], and targets contains only node03, node04, and node05.
That behavior follows from the rule itself. ansible_play_hosts_all[0] means the first member of the current play’s targeted population, not the first host in some permanent cluster-wide registry. The ansible_limit magic variable reflects the CLI limit, while ansible_play_hosts_all reflects the resulting play target set. A changed limit can therefore change the chosen singleton host even when the YAML is unchanged.
That is why a limit change should trigger REVIEW_TARGET_SET, not automatic acceptance. The inventory/selection owner must confirm that the restricted target population is intentional and that allowing node03 rather than node01 to own the invocation is valid. If the operation is actually bound to a designated coordinator, encode that ownership structurally instead of treating “first selected fleet host” as a surrogate leader.
The guard also does not, by itself, express the strongest form of prerequisite ordering. In this measured fixture, the guarded task is evaluated in the first batch before subsequent tasks in that batch under the linear strategy, so the observed one-count result is clear. But a reviewer should not generalize that count into a universal guarantee that a prerequisite precedes every other host’s work under arbitrary ordering, selection, failure, or strategy changes. When “preflight must complete successfully before any rolling work begins” is the contract, a separate controller play plus an explicit barrier is easier to review because it gives the prerequisite its own structural boundary.
Run the guarded play twice without resetting its evidence
R8 answers the question that a single successful launch cannot answer: does the current-play guard create a durable singleton across separate invocations? The harness runs the same R6-style playbook twice against the same case directory and deliberately keeps both event files. Both subprocesses return zero. The first launch writes one node01 event with invocation: 1; the second writes another node01 event with invocation: 2. The total is two.
That result is not a failure of the guard. The guard’s contract is scoped to host selection inside the current play invocation. On the second ansible-playbook launch, there is a new invocation and the condition is true again for the first selected host. Neither when: inventory_hostname == ansible_play_hosts_all[0] nor run_once stores a durable operation history outside the current execution. The documented Ansible controls describe task scheduling and host selection, not a cross-launch deduplication ledger.
This is the point at which an infrastructure reviewer must stop using scheduling vocabulary to solve side-effect semantics. A real operation that must not repeat across launches needs an application-owned identity and an authoritative record of whether that identity was committed. Depending on the system, that might involve a migration table, transaction key, compare-and-set state, external workflow record, or an idempotent API contract. Those are examples of the kind of ownership required; this article does not implement or validate any of them.
R8 also avoids a more dangerous inference: “The first run exited zero, therefore retrying is safe.” Exit status says what the automation process reported, not whether an external side effect is repeatable. A process can fail after an external system has accepted an operation, or succeed while an operator later loses the evidence required to prove what happened. Unknown side-effect history is therefore HOLD, not permission to replay an arbitrary command.
The fixture does not simulate transport ambiguity, controller crashes, partial network outcomes, or real migration recovery. Its two launches are ordinary completed local runs. That is sufficient for the bounded conclusion: a current-play first-host guard can produce one action per tested invocation, but it does not provide durable deduplication across invocations.
For release review, retain both dimensions in the ledger. R6 says invocation cardinality = 1 for one launch under the tested selection. R8 says launch cardinality = 2 launches, therefore two actions overall. If the side-effect owner requires one action across both launches, neither R6 nor R8 supplies the required mechanism; the operational state must be reconciled outside this scheduling fixture before any retry.
Put the prerequisite in a separate controller play
R9 changes the problem from “choose one fleet host” to “make a controller-owned prerequisite happen before fleet work.” The generated playbook contains two plays. The first targets only controller and executes one synthetic preflight command, registering its result as preflight_result. The second targets fleet, uses serial: 2, and begins with an ansible.builtin.assert barrier that requires hostvars['controller']['preflight_result'] to be defined and to contain rc == 0. Only after that assertion does the ordinary per-host rollout marker run.
This is a materially different contract from the R6 guard. The prerequisite has an explicit owner (controller) and a separate play boundary. The fleet play does not infer success from a chosen fleet host; it checks evidence from the controller play for this invocation. The ansible.builtin.assert documentation accepts explicit that expressions and fail_msg, which is exactly how the fixture turns “preflight evidence must exist and show success” into a visible gate. Its documentation does not grant a generic global host-loop bypass for assert; the fixture intentionally lets the barrier be evaluated for fleet hosts.
The supplied R9 result is six total event records, but they must not be mislabeled as six singleton executions. There is one preflight event from controller, followed by five rollout marker events, one for each fleet alias. The rollout markers are ordinary throttled scheduling probes; they simulate “work would proceed on this host” and do not deploy software or mutate a service. R9 returns code 0.
This structure is preferable when order is part of the requirement. A current-play guard can prove a one-count selection under its tested assumptions; the separate controller play makes the prerequisite a first-class phase and gives the later play an explicit condition to verify. That is easier for a release reviewer to reason about because “who owns preflight?” and “what proves it happened?” no longer depend on the first member of a rolling fleet selection.
The barrier is still not durable exactly-once delivery. preflight_result is a registered result from the current Ansible invocation. It is not a persistent cross-run ledger, not a cryptographic attestation of an external system, and not a recovery record. The fixture’s acceptance claim is only that, in R9, the controller preflight ran once before the synthetic fleet markers were allowed to run.
Make missing prerequisite evidence stop the later work
R10 uses the same two-play structure but adds --limit fleet. That limit excludes the controller play. The preflight does not run and fail; it is absent. When the first fleet batch reaches the assertion, hostvars['controller']['preflight_result'] is defined is false. The preparation records process return code 2 and zero event files for the case, because there is neither a preflight event nor any rollout marker.
The second play sets any_errors_fatal: true. The Ansible error-handling guide documents that with this option, an error causes it to finish the fatal task for the current batch and then stop the play across hosts, preventing subsequent tasks from running. That behavior supplies the demonstrated barrier: missing current-invocation prerequisite evidence blocks the rollout marker. It does not undo any effect that happened before the failure; error stopping and rollback are different responsibilities.
R10 is an expected negative control, not a broken harness. Its zero marker count is accepted only together with the failed assertion and expected return code 2. The fixture does not generalize that numeric return code to every Ansible failure category. It also does not test every possible preflight failure, stale fact-cache behavior, external side-effect status, or unreachable-host case. The measured negative case is specifically: controller excluded by --limit, result absent, assertion fails, rollout markers do not start.
Run the complete ten-case experiment
The source below is the complete supplied program. It generates its own JSON inventory and JSON-formatted playbooks, uses an owned TemporaryDirectory, records source and helper digests, captures every Ansible subprocess call, and removes only that owned temporary fixture when finished. The executed-source SHA-256 in the preparation is 950684e2259a1abfd7018f05cfc1d8c980030f6b6efebbae7793f5ac0ffb4dd3; the embedded helper SHA-256 is e41cafb3661ca7476bdaf2e158a3bf54fd3cfd873bc7413a7894f4e653e1123a.
The preparation ran from 2026-10-26T06:10:21.988009Z to 2026-10-26T06:10:34.940972Z and reported PASS_10_CASES. The elapsed time is provenance, not a benchmark. Its captured output also retained a warning that the default /root/.ansible directory could not be created; filesystem confinement is not under test.
The source uses ansible.builtin.command for event creation and ansible.builtin.assert for the prerequisite barrier. The command module’s documented argv form avoids shell tokenization problems, and expand_argument_vars: false tells the module not to expand argument variables. The plays explicitly state linear, order: sorted, gather_facts: false, and become: false; excluded areas include free strategy, async, retries, dynamic inventory changes, failed/unreachable-host injection, custom strategies, handlers, check mode, live recovery, performance benchmarking, and exactly-once delivery.
Save the file as cloud_ansible_run_once_lab.py if reproducing it. The source text shown here is byte-for-byte consistent with the supplied executed-source digest. Anyone who changes whitespace, code, play generation, or assertions has created a different source and must compute a new digest and run it before inheriting the old result.
"""Local alias hosts and owned temporary files only; no SSH, services, or migrations."""
import hashlib
import importlib.metadata as md
import json
import os
import platform
import subprocess
import sys
import tempfile
from datetime import datetime, timezone
from pathlib import Path

NODES = [f"node{i:02d}" for i in range(1, 6)]
HELPER = r'''import json, os, sys, time, uuid
from pathlib import Path
folder, origin, batch, targets, kind, invocation = sys.argv[1:]
record = {"origin": origin, "batch": json.loads(batch), "targets": json.loads(targets),
          "kind": kind, "invocation": int(invocation), "pid": os.getpid(),
          "monotonic_ns": time.monotonic_ns()}
destination = Path(folder) / (uuid.uuid4().hex + ".json")
with destination.open("x", encoding="utf-8") as stream:
    json.dump(record, stream, sort_keys=True)
print(json.dumps({"event_file": destination.name, "origin": origin, "kind": kind}))
'''


def require(ok, reason):
    if not ok:
        raise AssertionError(reason)


def sha(data):
    return hashlib.sha256(data).hexdigest()


def main():
    report = {"status": "RUNNING", "started_utc": datetime.now(timezone.utc).isoformat(),
              "python": platform.python_version(), "ansible_core": md.version("ansible-core"),
              "jinja2": md.version("jinja2"), "pyyaml": md.version("PyYAML"),
              "platform": platform.platform(),
              "source_sha256": sha(Path(__file__).read_bytes()), "cases": []}
    try:
        with tempfile.TemporaryDirectory(prefix="ansible-once-") as temporary:
            root = Path(temporary)
            helper = root / "record_event.py"
            helper.write_text(HELPER, encoding="utf-8")
            inventory = {
                "all": {"vars": {"ansible_connection": "local",
                                   "ansible_python_interpreter": sys.executable},
                        "children": {"fleet": {"hosts": {n: {} for n in NODES}},
                                     "coordinator": {"hosts": {"controller": {}}}}}}
            inventory_path = root / "inventory.json"
            inventory_path.write_text(json.dumps(inventory, indent=2), encoding="utf-8")
            local_tmp, remote_tmp = root / "local-tmp", root / "remote-tmp"
            local_tmp.mkdir()
            remote_tmp.mkdir()
            cfg = root / "ansible.cfg"
            cfg.write_text("[defaults]\nforks = 5\nretry_files_enabled = False\n"
                           "host_key_checking = False\n", encoding="utf-8")
            env = {k: v for k, v in os.environ.items() if not k.startswith("ANSIBLE_")}
            env.update({"ANSIBLE_CONFIG": str(cfg), "ANSIBLE_NOCOLOR": "1",
                        "ANSIBLE_LOCAL_TEMP": str(local_tmp),
                        "ANSIBLE_REMOTE_TMP": str(remote_tmp)})
            report["inventory"] = inventory
            report["config"] = cfg.read_text()
            report["helper_sha256"] = sha(helper.read_bytes())
            cli = [sys.executable, "-m", "ansible.cli.playbook"]
            version = subprocess.run(cli + ["--version"], cwd=root, env=env,
                                     capture_output=True, text=True, timeout=30)
            require(version.returncode == 0, "Ansible version probe failed")
            report["ansible_version_output"] = version.stdout

            def action(events, kind="singleton", once=False, delegated=False,
                       guard=False, throttled=False):
                result = {
                    "name": "Record actual " + kind + " invocation",
                    "ansible.builtin.command": {"argv": [sys.executable, str(helper),
                        str(events), "{{ inventory_hostname }}",
                        "{{ ansible_play_batch | to_json }}",
                        "{{ ansible_play_hosts_all | to_json }}", kind,
                        "{{ lab_invocation }}"], "expand_argument_vars": False}}
                if once:
                    result["run_once"] = True
                if delegated:
                    result["delegate_to"] = "controller"
                if guard:
                    result["when"] = "inventory_hostname == ansible_play_hosts_all[0]"
                if throttled:
                    result["throttle"] = 1
                return result

            def play(tasks, serial=None, hosts="fleet"):
                result = {"name": "Owned local execution-scope probe", "hosts": hosts,
                          "connection": "local", "become": False, "gather_facts": False,
                          "strategy": "linear", "order": "sorted", "tasks": tasks}
                if serial is not None:
                    result["serial"] = serial
                return result

            def execute(case, make_plays, expected_origins, , limit=None, repeat=1,
                        expected_rc=0, expected_batches=None, expected_targets=None,
                        expected_kinds=None):
                owned = root / case
                owned.mkdir()
                events = owned / "events"
                events.mkdir()
                plays = make_plays(events)
                script = owned / "playbook.json"
                script.write_text(json.dumps(plays, indent=2), encoding="utf-8")
                attempts = []
                for attempt in range(1, repeat + 1):
                    command = cli + ["-i", str(inventory_path), str(script),
                                     "--extra-vars", json.dumps({"lab_invocation": attempt})]
                    if limit:
                        command += ["--limit", limit]
                    completed = subprocess.run(command, cwd=root, env=env,
                                               capture_output=True, text=True, timeout=90)
                    attempts.append({"argv": command, "returncode": completed.returncode,
                                     "stdout": completed.stdout, "stderr": completed.stderr})
                    require(completed.returncode == expected_rc, case + " return code")
                observed = [json.loads(p.read_text()) for p in events.glob(".json")]
                observed.sort(key=lambda event: event["monotonic_ns"])
                record = {"case": case, "playbook": plays, "attempts": attempts,
                          "events": observed, "actual_invocations": len(observed)}
                report["cases"].append(record)
                require([e["origin"] for e in observed] == expected_origins, case + " origins")
                if expected_batches is not None:
                    require([e["batch"] for e in observed] == expected_batches, case + " batches")
                if expected_targets is not None:
                    require(all(e["targets"] == expected_targets for e in observed),
                            case + " targeted hosts")
                if expected_kinds is not None:
                    require([e["kind"] for e in observed] == expected_kinds, case + " kinds")
                return observed

            execute("R1", lambda e: [play([action(e, once=True)])], ["node01"],
                    expected_batches=[NODES], expected_targets=NODES)
            execute("R2", lambda e: [play([action(e, once=True)], 2)],
                    ["node01", "node03", "node05"],
                    expected_batches=[NODES[:2], NODES[2:4], NODES[4:]], expected_targets=NODES)
            execute("R3", lambda e: [play([action(e, once=True)], 1)], NODES,
                    expected_batches=[[n] for n in NODES], expected_targets=NODES)
            execute("R4", lambda e: [play([action(e, once=True, delegated=True)], 2)],
                    ["node01", "node03", "node05"],
                    expected_batches=[NODES[:2], NODES[2:4], NODES[4:]], expected_targets=NODES)
            execute("R5", lambda e: [play([action(e, delegated=True, throttled=True)], 2)],
                    NODES, expected_targets=NODES)
            execute("R6", lambda e: [play([action(e, guard=True)], 2)], ["node01"],
                    expected_batches=[NODES[:2]], expected_targets=NODES)
            execute("R7", lambda e: [play([action(e, guard=True)], 2)], ["node03"],
                    limit="node03:node04:node05", expected_batches=[NODES[2:4]],
                    expected_targets=NODES[2:])
            repeated = execute("R8", lambda e: [play([action(e, guard=True)], 2)],
                               ["node01", "node01"], repeat=2, expected_targets=NODES)
            require([e["invocation"] for e in repeated] == [1, 2], "R8 independent invocations")

            def separate_plays(events):
                preflight = action(events, kind="preflight")
                preflight["register"] = "preflight_result"
                barrier = {"name": "Require this invocation's controller preflight",
                           "ansible.builtin.assert": {"that": [
                               "hostvars['controller']['preflight_result'] is defined",
                               "hostvars['controller']['preflight_result']['rc'] == 0"],
                               "fail_msg": "No verified preflight for this invocation"}}
                rollout = action(events, kind="rollout", throttled=True)
                second = play([barrier, rollout], 2)
                second["any_errors_fatal"] = True
                return [play([preflight], hosts="controller"), second]

            execute("R9", separate_plays, ["controller"] + NODES,
                    expected_kinds=["preflight"] + ["rollout"] * 5)
            execute("R10", separate_plays, [], limit="fleet", expected_rc=2)
            require(len(report["cases"]) == 10, "case coverage")
        report["status"] = "PASS_10_CASES"
        report["temporary_fixture_removed"] = True
    except Exception as exc:
        report["status"] = "FAIL"
        report["error"] = {"type": type(exc).__name__, "message": str(exc)}
        raise
    finally:
        report["finished_utc"] = datetime.now(timezone.utc).isoformat()
        print(json.dumps(report, indent=2))


if name == "__main__":
    main()
The supplied reproduction commands are:
python3.12 -m venv .venv
.venv/bin/python -m pip install ansible-core==2.19.3 Jinja2==3.1.6 PyYAML==6.0.3
.venv/bin/python -m pip freeze > ansible-run-once-environment.txt
.venv/bin/python cloud_ansible_run_once_lab.py > ansible-run-once-results.json
Those commands pin the three named Python packages used as preparation inputs, while pip freeze retains the actually resolved dependency set. A later rerun must report its own runtime, dependency manifest, command output, process exit status, JSON status, and digests. A different environment that agrees with the expected counts is useful new evidence; it is not evidence that the original 2026-10-26 preparation somehow ran on that later environment. Conversely, an unexpected failure or partial report is RERUN after diagnosis, not permission to relabel missing events as successful zeros.
Reconcile counts, identities, and decisions
The ten-case ledger is the acceptance core. R1 through R9 returned code 0; R8 contains two separate code-0 subprocess results. R10 returned code 2 because its expected assertion failed. The measured counts and interpretations are:
Case | Declared configuration | Return code | Recorded actual invocations | Recorded interpretation |
R1 | run_once; no serial | 0 | 1 | node01; one five-host batch |
R2 | run_once; serial: 2 | 0 | 3 | node01, node03, node05; batches 2/2/1 |
R3 | run_once; serial: 1 | 0 | 5 | one invocation for each one-host batch |
R4 | R2 plus delegate_to: controller | 0 | 3 | same logical origins; one delegated destination does not remove batches |
R5 | ordinary delegated task; serial: 2; throttle: 1 | 0 | 5 | per-host task count remains five |
R6 | serial: 2; current-play first-host when guard | 0 | 1 | node01 under the fixed full selection |
R7 | R6; limit node03:node04:node05 | 0 | 1 | node03 under the restricted selection |
R8 | R6 in two launches; evidence retained | 0, 0 | 2 | node01 twice; invocation fields 1 and 2 |
R9 | controller preflight play; result barrier; serial fleet play | 0 | 6 total | one preflight, then five rollout markers |
R10 | R9 with --limit fleet excluding controller | 2 | 0 | preflight result absent; assertion blocks rollout markers |
The table has three different kinds of “success.” R1–R8 are positive scheduling controls whose event sequences matched the independently declared expectations. R9 is a positive prerequisite/barrier control: one preflight event exists and five later markers are allowed. R10 is a successful negative diagnostic control precisely because the playbook fails in the expected place and creates no rollout markers. PASS_10_CASES means those assertions matched; it does not approve a production deployment.
The identities matter as much as the counts. R4’s three events prove that a common delegated destination did not change the batch-origin sequence. R7’s single event proves that a target-set change can move the selected origin. R8 proves that a one-per-invocation selector repeats on a new launch. R9’s six records must be split by kind; calling all six “singleton executions” would erase the difference between the prerequisite and the simulated fleet work.
Evidence completeness is also part of the decision. A clean zero is meaningful only when the harness reaches a state that explains the zero. R10 has an expected failed assertion, code 2, captured output, and zero markers. An interrupted run that merely leaves no event files is not equivalent. Missing version data, incomplete stdout/stderr, an edited source without a new digest, or an unexplained partial report requires HOLD or RERUN depending on whether the uncertainty concerns operation history or just the laboratory environment.
The documented and measured layers should stay separate. Ansible documentation explains why run_once is batch-scoped with serial and why throttle limits concurrency rather than task count. The supplied preparation shows the exact counts for this local fixture. The application owner then decides which of those documented behaviors satisfies the release contract. A test can be technically correct and still expose a policy defect.
Repair the playbook without erasing its earlier effects
Repair starts by preserving evidence, not by editing YAML immediately. Keep the original playbook, effective inventory, --limit, host ordering, Ansible configuration, version output, subprocess traces, event ledger, and any known external side-effect history. The scheduling defect may be easy to reproduce locally; the external action that already happened may not be safe to repeat or reverse.
There are three bounded repair choices. Keep run_once with serial when the action is intentionally once per batch. Use the ansible_play_hosts_all[0] guard when the accepted contract is one logical origin in the current selected play invocation, with reviewed selection/order/failure assumptions. Use a separate controller preflight play plus explicit barrier when a controller-owned prerequisite must be established before rolling fleet work is allowed to begin. These are different ownership models, not stylistic equivalents.
A location-only change such as adding delegate_to: controller does not repair R2’s cardinality; R4 proves that. A concurrency-only change such as throttle: 1 does not repair it either; R5 proves that. For a whole-play singleton requirement, both are REPAIR unless another independent selector reduces the invocation count to the declared scope.
Do not confuse this scheduling repair with recovering state after an Ansible handler was skipped. Handler notification and activation recovery have a different failure boundary. Here the question is how many ordinary task invocations were selected and whether a prerequisite phase gated later work.
Most importantly, reverting the playbook cannot undo an external operation that already ran. If a task performed a real schema migration, released a token, modified a third-party system, or changed service state, restoring the old YAML changes future scheduling only. The side-effect owner must reconcile what actually happened before deciding whether another invocation is safe.
Requalification and recovery have different jobs
Requalification asks whether the repaired automation now satisfies the local scheduling contract. Rerun the synthetic fixture after changes to ansible-core, Python, strategy, ordering, inventory selection, task guards, delegation, or evidence code, and label that need RERUN. Preserve the new environment and digest instead of borrowing PASS_10_CASES from a different source.
Recovery asks what to do about a potentially real operation that may already have occurred. Unknown effect history is HOLD. It should stay on hold until the side-effect owner can reconcile authoritative state and define a safe next action. The laboratory’s cleanup only deletes its own temporary event workspace; it is not a model of rolling back a migration or deployment. That distinction prevents a clean test rerun from being mistaken for operational recovery.
Assign acceptance and operational ownership
A singleton rule needs named owners because each part of the evidence answers a different question. The playbook maintainer owns the scheduling expression and executable source. The inventory/selection owner owns target patterns, --limit, and ordering assumptions. The side-effect owner owns operation identity, repeatability, and reconciliation. The release reviewer owns the final evidence-backed acceptance decision. That separation matches the broader emphasis on automation, release management, infrastructure, and collaboration in DevOps release and collaboration responsibilities, without turning this repair into a career guide.
Use the following compact decision matrix:
Decision | Use it when | Required owner action |
ACCEPT_TESTED_SCOPE | The measured local behavior matches the explicitly declared per-batch or per-invocation contract under the recorded strategy, selection, order, and failure assumptions | Release reviewer records the exact accepted scope and evidence |
REPAIR | The task is batch-scoped when the requirement is whole-play, or a proposed change only moves execution location/limits concurrency without fixing cardinality | Playbook maintainer changes the scheduling structure and requalifies it |
REVIEW_TARGET_SET | --limit, inventory composition, or ordering changes the population from which the singleton is selected | Inventory/selection owner approves the new target set and resulting owner |
HOLD | Prerequisites are missing, evidence is incomplete in a way that affects safety, or real side-effect history is unknown | Side-effect owner reconciles authoritative state before replay |
RERUN | The laboratory environment, executable source, strategy, selection assumptions, or evidence collection changed, or the prior diagnostic report is incomplete | Maintainer runs the owned diagnostic again and retains new evidence |
The review record should retain strategy, selected host set and limit, batch rule, singleton selector, durable operation identity if one exists, and the evidence artifact. Changes to serial, order, inventory patterns, or --limit can alter the singleton contract even when the task body is unchanged.
For this supplied fixture, the owner-reviewed judgment is bounded. R2 is acceptable only for a once-per-batch contract; it is a repair candidate for a once-per-invocation contract. R6 is acceptable for the tested current-play first-host rule, subject to target-set review. R9 is the preferred structure when the requirement is an ordered controller prerequisite before fleet work. R10 proves the tested “missing current-invocation evidence blocks markers” case. None of those decisions certifies a real migration, service rollout, or cross-launch exactly-once effect.
Build the automation judgment behind the syntax
The syntax is the easy part. The engineering judgment is recognizing that scheduling controls operate on different axes. run_once selects within a batch; serial creates batches; delegation chooses execution context; throttle constrains concurrency; ansible_play_hosts_all[0] can select one member of the current play; and a separate controller play can create a clearer prerequisite boundary. None of those labels, by itself, defines durable singleton semantics across independent launches.
For the measured local contract, retain the final rule in operational language: accept per-batch execution only when per-batch is the declared requirement; otherwise repair the scope, review target-set changes, hold on unknown real effects, and rerun the diagnostic after relevant environment or source changes. That statement is more reviewable than “it has run_once, so it is safe.”
Refonte Learning’s DevOps Engineering program currently describes a three-month, 12–14-hours-per-week program covering Linux fundamentals and scripting, Git and GitHub, CI/CD, Docker and Kubernetes, Infrastructure as Code with Terraform, AWS/Azure/GCP, monitoring/logging, and a capstone; it also states a bachelor’s-or-higher study requirement and describes virtual internship opportunities. Those foundations are relevant to the scripting, release-review, and infrastructure reasoning used in a diagnostic like this. Engineers seeking specialist Ansible coverage should verify the current syllabus directly rather than assume this run_once/serial laboratory or a particular ansible-core version is included.