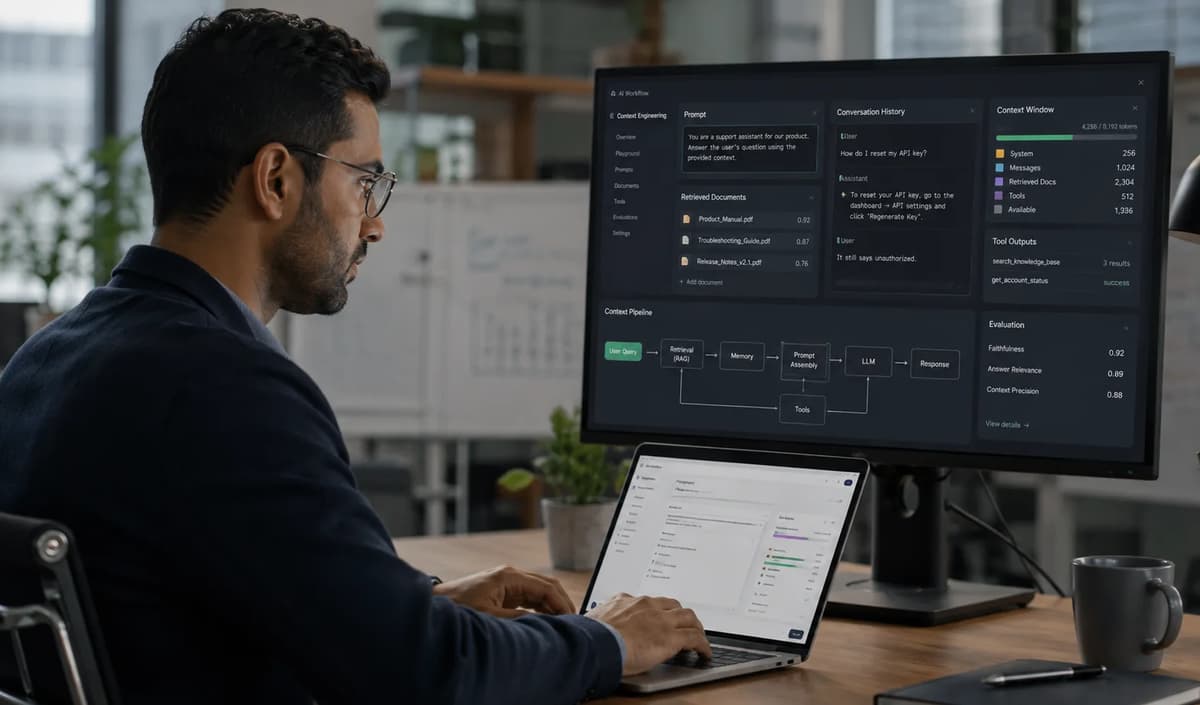
Context engineering in 2026 raises an uncomfortable career question: if you built your value around writing precise instructions for large language models, is the Prompt Engineer job title already becoming obsolete?
LangChain co-founder Harrison Chase has become one of the most visible advocates for the shift. A July 8, 2026 report from press.farm frames his position bluntly: the standalone Prompt Engineer title is giving way to context engineering, agent engineering, and a broader discipline of building the systems around models. Chase's own discussions are slightly more nuanced, but they leave little doubt that he sees context engineering and agent harnesses as central to serious AI engineering.
Anthropic supplied the strongest practical evidence on July 24, 2026. While adapting Claude Code for its Claude 5-generation models, Anthropic says it removed more than 80% of Claude Code's system prompt for models including Claude Opus 5 and Claude Fable 5, “with no measurable loss on our coding evaluations.” The company simultaneously moved toward progressive disclosure: instead of preloading every instruction and reference, give the model relevant context when the task actually requires it.
That result matters if you have spent years optimizing system prompts. It does not show that instructions stopped mattering; it shows that a bigger prompt is not automatically a better AI system, especially as frontier models become more capable and agents operate over longer horizons.
There is also an important historical correction to make before going further. Anthropic did not coin the phrase “context engineering” in September 2025: Shopify CEO Tobi Lütke was publicly advocating the term by June 19, 2025, Andrej Karpathy endorsed it days later, and Philipp Schmid published a detailed treatment on June 30. Anthropic's September 29 article instead gave the emerging discipline one of its most important formal definitions from a frontier AI lab.
So the useful question is not “prompt engineering or context engineering?” It is: which parts of prompt engineering remain foundational, which responsibilities have expanded, and how should you reposition your career before the job market settles on new titles?
This guide answers that from a practitioner's perspective: what context engineering actually means, what changed inside Claude Code, how context engineering vs prompt engineering differs in day-to-day work, what current job postings require, how much confidence you should place in context engineer salary 2026 estimates, what certifications now exist, and what to learn next if you already work with prompts.
Context Engineering and Why the AI Industry Broadened Beyond Prompt Engineering
For the first generation of LLM applications, the engineering bottleneck was often the instruction itself. You wrote a system prompt, experimented with few-shot examples, adjusted formatting, changed the order of constraints, evaluated the output, and iterated.
That work still exists. But an agent using Claude, LangChain, a retrieval system, external tools, persistent memory, and a long conversation does not receive just one prompt; before every model call, software effectively assembles a temporary information environment around the model.
That is the central distinction behind what is context engineering.
Aspect | Prompt Engineering | Context Engineering |
Core question | “What instruction should I write?” | “What should the model see, and in what order, for this step?” |
Primary scope | Instructions, examples, templates | The complete information environment supplied at inference |
Typical inputs | System prompt, user prompt, few-shot examples | Prompts, retrieved documents, messages, memory, tools, tool results, state |
Time horizon | Often one request or a bounded workflow | Repeated model calls across multi-turn and long-horizon agents |
Optimization target | Instruction following and output quality | Relevance, attention, reliability, token use, latency, continuity |
Historical marker | Central to the early LLM API era | Term gained major attention in mid-2025; Anthropic formalized its framing in September 2025 |
Best fit | Discrete generation and transformation tasks | Agents, RAG applications, tool use, persistent workflows |
Anthropic describes context engineering as the natural progression of prompt engineering. Its September 29, 2025 article defines it, in part, as “the set of strategies for curating and maintaining the optimal set of tokens,” then expands the concept beyond prompts to everything else entering the model during inference.
In practical terms, that “everything else” is where the career expansion happens. Your context might contain a system instruction, five retrieved policy documents, the last ten conversation turns, a customer's account status, a tool schema, a tool's returned JSON, a summary of an earlier task, a stored user preference, and a file the agent opened thirty seconds ago.
A Prompt Engineer can optimize the wording telling the model how to use those resources. A Context Engineer also decides which resources belong there at all, how much of each to include, when to retrieve them, how to compress them, and what to remove before irrelevant material starts competing for the model's attention.
LangChain expresses the concept even more operationally. Its current documentation defines context engineering as “providing the right information and tools in the right format so the LLM can accomplish a task” and calls that work “the number one job of AI Engineers.”
LangChain divides that context into model context, tool context, and lifecycle context. Model context covers instructions, messages, available tools, the chosen model, and response format; persistent sources include short-term state and longer-term stores; lifecycle engineering can add summarization, guardrails, and logging between calls.
That framing explains why a production agent can fail despite having an excellent system prompt. The instruction can be perfectly written while the retrieval layer fetches the wrong document, memory injects an outdated preference, fifty pages of tool output bury the relevant fact, or an important result from an earlier turn disappears during history truncation.
Anthropic makes a related argument around context rot. As context expands, retrieval and reasoning accuracy can degrade rather than improve indefinitely, so Anthropic recommends looking for a relatively small set of high-signal tokens instead of assuming that filling a giant context window is inherently beneficial.
This means context engineering is not simply “prompt engineering plus more tokens.” It is often the opposite: the discipline of deciding what not to send.
For readers who need the taxonomy of traditional techniques first, the full breakdown of prompt engineering types covers that narrower prompt-level landscape. The distinction here is that context engineering asks what happens around those techniques across the complete execution cycle.
The most useful mental model is therefore:
Prompt engineering optimizes an instruction. Context engineering optimizes the information environment in which that instruction is interpreted.
That is why the underlying prompt skill survives. When you select context correctly but tell the model ambiguously what to do with it, the system can still fail; when you write an outstanding prompt but supply irrelevant or stale context, it can fail for a completely different reason.
What Changed in Claude and Why the Prompt Engineer Title Is Under Pressure
Anthropic's July 2026 Claude Code result converts an abstract terminology debate into an engineering experiment.
According to Anthropic, Claude Code's earlier system prompt had accumulated instructions designed around older generations of models. As Claude became more capable, those instructions could become unnecessary constraints, duplicate behavior the model already understood, or create conflicts with skills and user-level directions.
For newer Claude 5-generation models, Anthropic removed over 80% of the Claude Code system prompt without a measurable drop in its coding evaluations. That does not prove that every company should delete 80% of every prompt; it proves that Anthropic could remove a very large amount of previously useful up-front instruction after the capability profile of its model changed.
The deeper lesson is the move from preloading to progressive disclosure. An agent does not necessarily need the full code-review playbook, every workflow rule, all reference material, and every available tool description before it knows what problem it is solving.
A better architecture can expose the right skill, file, tool, or reference once the agent reaches the point where that information has decision value. Anthropic's earlier September context-engineering article described the same principle through just-in-time retrieval and incremental discovery.
Earlier design instinct | Context-engineering design instinct |
Put detailed rules into one large system prompt | Keep core instructions concise and load specialist guidance when relevant |
Expose every tool immediately | Expose or discover tools according to the task |
Keep complete history in the active context | Summarize, compact, or retain only decision-relevant history |
Return full tool results | Store large outputs and surface the relevant portion |
Add instructions whenever a failure appears | Test whether the failure comes from instructions, retrieval, memory, tools, or context overload |
Assume more context is safer | Measure whether additional context improves or harms task success |
For a senior Prompt Engineer, this changes the debugging question. When an agent gives a wrong answer, you cannot immediately conclude “the prompt needs another rule.”
You inspect the trace. Did retrieval bring back the correct evidence? Did the evidence arrive before or after a conflicting message? Did the model have twenty irrelevant tools available? Did a large API response consume the useful context budget? Did compaction erase an important constraint? Did memory surface a fact that was true last month but not now?
Harrison Chase makes this trace-driven view especially important for long-horizon agents. In his conversation with Sequoia, he explains that with an agent running repeatedly, you cannot know from static code alone exactly what will be in the context at a later step, because every preceding step can retrieve or generate additional information; he therefore sees traces as a critical artifact for debugging agent behavior.
This is the strongest version of LangChain's career argument. A July 8, 2026 press.farm article summarizes Chase's position with the headline-level claim that the Prompt Engineer title is dead, replaced by broader work around context, agents, and harnesses.
I would treat “dead” as a useful provocation rather than a literal description of the skill. Chase's primary-source discussion with Sequoia says agents still need instructions and prompts while emphasizing that models, context, compaction, planning, memory, filesystems, and harnesses now work together as a system.
The analogy I use with teams is the old “webmaster” title. HTML did not stop mattering when web development split into frontend engineering, backend engineering, cloud infrastructure, DevOps, accessibility, analytics, and security; the job boundary expanded until a single title no longer described the production system.
Prompt engineering is moving in a similar direction. Clear instructions remain a production dependency, while “Prompt Engineer” may become too narrow a title for the person responsible for the whole agent.
That brings us to harness engineering in AI, another term showing up around Chase's work.
Layer | Main responsibility | Typical artifacts |
Prompt engineering | Tell the model what task to perform and how | System prompts, templates, examples, schemas |
Context engineering | Control what information reaches the model at each decision point | Retrieval, history, memory, tool outputs, compaction, context budgets |
Harness engineering | Design the execution environment and control machinery around the model | Agent loop, planning, filesystems, tools, sandboxes, subagents, traces, evals, guardrails |
Chase describes modern agent harnesses as more opinionated than generic frameworks: they can provide built-in planning tools, context compaction, filesystem access, and other mechanisms that enable a model to operate over longer horizons. His Sequoia discussion argues that recent agent progress comes from both better models and better harnesses, not either factor alone.
The distinction is useful. Context engineering decides what the model can see at a particular inference step; harness engineering shapes the broader environment through which the agent plans, calls tools, stores information, delegates tasks, resumes work, and gets evaluated.
There is another factual update worth making around Gartner. The idea that Gartner's position is available only through secondary reporting from early 2026 is no longer correct: Gartner has a directly accessible primary article dated October 6, 2025, titled Context Engineering Is the New Prompt Engineering.
That Gartner article explicitly recommends that AI leaders make context engineering a strategic priority and appoint a context-engineering lead or team, integrating the function with AI engineering and governance. Its public definition emphasizes designing relevant data, workflows, and environments rather than depending on manual prompts alone.
So Gartner's involvement does not need to be described as merely “reportedly” in August 2026. What still requires caution is a different inference: Gartner recommending a context-engineering function does not prove that companies have standardized “Context Engineer” into a mature, universally recognized job title.
Context Engineering vs Prompt Engineering in Skills and Daily Work
When you compare context engineering vs prompt engineering at production level, the cleanest difference is not “writing versus coding.” Both jobs can involve code, templates, experiments, APIs, evaluation, and model-specific behavior.
The difference is the unit of optimization.
A Prompt Engineer can ask: “How do I make this instruction produce a better answer?” A Context Engineer asks: “Across this entire agent session, which instructions, facts, memories, tools, and intermediate outputs should be available at each step, and how will I prove that my decisions make the system better?”
Factor | Prompt Engineering | Context Engineering |
Primary artifact | Prompt or reusable prompt template | Context-assembly and management strategy |
Optimization scope | One model call or tightly bounded flow | Full sequence of model calls |
Main failure | Model misreads or incompletely follows instructions | Model sees missing, irrelevant, stale, excessive, or badly formatted information |
Core testing | Compare prompt variants | Compare context policies and run-level outcomes |
Retrieval | May consume retrieved text | Designs what to retrieve, rank, compress, and expose |
Memory | Usually peripheral | Determines what persists and what returns to active context |
Tool use | Describes how a model should use tools | Controls tool availability and how returned data enters context |
History | Often appended automatically | Actively trims, summarizes, stores, or reconstructs history |
Cost concern | Prompt-token and output-token use | Context budget across retrieval, memory, tools, caching, and repeated turns |
Best evidence of competence | Versioned prompts with evaluations | Production-style traces, retrieval tests, memory strategy, context ablations, eval results |
Consider a customer-support agent. A traditional prompt-engineering task might be to produce a system instruction that tells Claude to answer politely, cite policy, avoid making unsupported promises, and escalate refunds above a threshold.
A context-engineering task starts earlier. Which customer records may the agent retrieve? Which policy version should rank first? How do you prevent policies for another market from entering context? Does the agent need the entire conversation or a structured summary? Should the refund tool become available immediately or only after identity verification? What happens to a ten-thousand-token tool response? Which facts become persistent memory?
Those questions are increasingly visible in real job descriptions. Onit's current AI Engineer posting asks the engineer to own context engineering end-to-end, including dynamic assembly from retrieval, state, and tool outputs; context budgeting; compression and summarization; grounding; RAG; evaluation; observability; prompt versioning; and agent memory/state.
Infinite pl's AI Engineer role similarly combines RAG, vector search, prompt/context engineering, system-prompt design, tool calling, agent loops, memory, retrieval, tracing, and evaluation. The title is “AI Engineer,” not “Context Engineer,” which is precisely the labor-market pattern to pay attention to.
Aera Technology goes even further. Its current AI/ML Engineer description expects familiarity with context engineering, tool and skill design, subagent patterns, agent memory, evaluation, LLM-as-judge techniques, structured outputs, prompt caching, RAG, LangGraph-like orchestration, and observability.
That is what context engineering skills look like when they stop being a vocabulary exercise.
Priority | Prompt Engineering Foundation | Additional Context Engineering Skill |
Must | Clear, unambiguous instructions | Context-window and token-budget reasoning |
Must | Few-shot example selection | Retrieval and RAG design |
Must | Prompt testing and evaluation | Multi-turn state and memory management |
Must | Structured-output instructions | Retrieval-quality and grounding evaluation |
Should | Reusable templates and variables | Tool-result filtering, formatting, and summarization |
Should | Understanding model-specific behavior | Context compression and compaction |
Should | Prompt-version management | Prompt/context caching and latency trade-offs |
Good | Cross-model portability | Progressive disclosure and dynamic tool exposure |
Good | Error analysis | Trace analysis across long-running agent sessions |
Every item in the left column remains useful. You cannot reliably engineer context if you do not understand how a model interprets instructions, examples, schemas, ambiguity, ordering, and conflicting constraints.
The right column changes your perspective from document author to information-flow engineer.
RAG is the most obvious skill delta, but RAG is not synonymous with context engineering. Retrieval-augmented generation determines which external knowledge to retrieve; context engineering decides how retrieval interacts with instructions, active conversation state, persistent memory, tool results, token limits, and the rest of the model's environment. LangChain's model makes that broader scope explicit.
A production RAG pipeline therefore needs more than an embedding model and vector database. You need chunking, retrieval filters, ranking or reranking, permissions, source freshness, deduplication, a strategy for contradictory documents, and an evaluation set that tells you whether the evidence reaching the LLM is actually the evidence it needs.
Memory management creates a different problem. “Remember everything” sounds useful until old facts, obsolete user preferences, speculative model conclusions, and duplicated conversation details start competing with current instructions.
Anthropic's long-horizon guidance includes compaction and structured note-taking for exactly this reason. In Claude Code, Anthropic describes summarizing message history while preserving decisions and unresolved implementation details and dropping less useful material.
Tool-result management is just as important. If an API returns five thousand rows but the model needs three fields, passing the complete response spends tokens and attention without necessarily improving the decision; a context engineer may transform, filter, summarize, store, or make the large output selectively retrievable.
For agent-heavy applications, prompt engineering for multi-agent systems remains useful background. Context engineering extends that concern into questions such as what one agent should pass to another, whether a subagent gets full history or a task-specific packet, and what information survives a handoff.
Likewise, prompt engineering skills, tools, and career path provides the prompt-level foundation. The career upgrade is to add retrieval, state, memory, tool architecture, trace analysis, and system-level evaluation rather than discard that foundation.
A strong Context Engineer's daily workflow can therefore look less like “write a perfect prompt” and more like this:
· inspect failed traces and identify the point at which the wrong context entered the model;
· test retrieval strategies against a fixed evaluation set;
· decide which message history to retain, summarize, or externalize;
· reduce noisy system instructions or duplicate examples;
· design tool schemas and transform oversized tool outputs;
· measure task success, groundedness, token consumption, latency, and regression rates before and after a context change.
Anthropic's Claude Code experiment captures the discipline neatly: delete, defer, and retrieve can be engineering improvements, not compromises.
Context Engineer Pay, Job Demand, and Credentials
Searches for 2026 Context Engineer salaries currently produce more apparent precision than the labor market can justify.
There are jobs explicitly using “Context Engineer,” “GenAI Context Engineer,” “Context & Memory Engineer,” and similar wording, but the title is still less standardized than AI Engineer, Machine Learning Engineer, or Software Engineer. ZipRecruiter's current results, for example, mix GenAI context work with broader roles and highly specialized titles, which makes a single aggregate average difficult to interpret as the salary of an LLM context-engineering specialist.
That distinction matters before you put a six-figure range into a career article.
Source | Role/category | Current figure | How to interpret it |
Prompt Engineer | 2025 guide spans roughly $95K to $270K by projected level | Refonte's own salary-guide modeling, not a dedicated current context-engineer benchmark | |
AI Engineer | About $145K median total pay; roughly $116K–$183K total-pay range | Useful broad AI-engineering baseline, not context-specialist pay | |
“Context Engineer” search/category | About $101,752 average; most around $84K–$116.5K | Directional only because title/category coverage is heterogeneous | |
Dedicated LLM Context Engineer | Emerging title | No robust cross-employer benchmark located | Use individual postings and adjacent AI-engineer data rather than pretend precision |
Refonte Learning's full prompt engineering salary guide published its own 2025 estimates reaching from approximately $95,000 at the lower end of its projected Prompt Engineer bands to $270,000 at the senior end. Those figures provide historical context for the prompt engineer salary 2026 conversation, but they should not be repackaged as a verified market-wide 2026 benchmark.
Glassdoor's U.S. AI Engineer page currently reports approximately $145,000 median total pay, with a reported total-pay band of about $116,000 to $183,000. Recent salary submissions on the page run through August 2026, making this more useful as a current generalist baseline.
ZipRecruiter's Context Engineer category reports an average of about $101,752 as of August 12, 2026 and says most workers represented in its data fall around $84,000–$116,500. But the same search surfaces jobs ranging from enterprise retrieval engineering to clinical context work and context-enablement roles, so I would not read that number as “the market rate for an LLM Context Engineer.”
The frequently repeated $140,000–$230,000 Context Engineer range and claims that context specialists automatically receive a 30–50% premium over generalist AI engineers deserve particular caution. I did not find a named, methodologically transparent salary survey in the researched primary/current sources that supports treating those exact figures as established market statistics.
They may be plausible for individual senior U.S. AI roles, but “plausible” and “verified benchmark” are different standards. An SEO article should not erase that distinction.
Current postings provide a cleaner demand signal than aggregated salary estimates.
Current role | Evidence of the shift |
End-to-end context assembly, retrieval, state, tool outputs, budgeting, compression, grounding, RAG, evals | |
RAG, vector search, prompt/context engineering, system prompts, tool calling, memory, evaluation | |
Context engineering, agent memory, subagents, prompt caching, evals, RAG, observability | |
Prompt/context engineering, RAG, agent harnesses, memory, structured outputs, evaluation | |
LTS: Senior Applied AI Engineer | Prompt engineering plus memory strategies, context management, RAG, retrieval, benchmarking |
These are current postings accessible in August 2026.
The pattern is more important than any one company: context engineering is showing up inside AI Engineer, Applied AI Engineer, AI/ML Engineer, and agent-engineering roles rather than consistently creating a separate hiring silo.
Kobie's posting is particularly revealing. It asks for production experience in “prompt/context engineering” alongside tool calling, structured outputs, RAG, observability, evaluation, agent harnesses, and memory; it is hiring an AI Engineer, not replacing the entire discipline with a Context Engineer title.
That makes the career conclusion different from the headline “Prompt Engineer is dead.” The specialist title may be narrowing while the capability is expanding into higher-scope engineering roles.
There is also an important correction on certifications. It is no longer accurate to say that no formal context-engineering certification exists.
Databricks now offers the Databricks Certified Context Engineer Associate credential. Its exam covers designing and governing information supplied to agents at inference time, including system prompts, retrieval, memory architecture, MCP-connected tools, context-window constraints, compaction, trimming, governance, long-horizon workflows, and empirical evaluation.
The certification is proctored, currently has 45 scored questions, a 90-minute limit, a $200 registration fee, and a two-year validity period; Databricks recommends hands-on experience even though it lists no formal prerequisite.
That credential is a legitimate market signal. It is still not a substitute for evidence that you can make an agent work.
For hiring, I would rank a well-documented portfolio project above an unsupported LinkedIn title change. Show a baseline agent, the context failure you found, the change you made, and a quantitative or rubric-based before-and-after evaluation.
A credible portfolio artifact should answer four questions:
What information was available to the model before your intervention?
What retrieval, memory, compaction, or tool-output policy did you change?
Which evaluation set or production metric measured the result?
What happened to quality, groundedness, latency, and token usage after the change?
That is a stronger Context Engineer signal than a collection of clever one-off prompts because it demonstrates the system-level judgment that current job descriptions actually request.
How to Reposition a Prompt Engineer Career
For anyone asking whether prompt engineering is obsolete in 2026 because their current title says Prompt Engineer, my advice is simple: reposition; do not panic.
You already own a substantial piece of the new stack.
You understand instruction hierarchy. You know that “be accurate” is weaker than an explicit output contract. You have seen few-shot examples steer behavior. You understand why ambiguous constraints create unpredictable results and why evaluation matters more than judging one impressive demo.
Those skills remain relevant because every dynamic context packet still needs instructions that explain how the model should interpret evidence, invoke tools, resolve conflicts, format responses, and behave when information is missing. Anthropic itself characterizes context engineering as a progression from prompt engineering rather than the erasure of it.
What changes is your learning sequence.
Repositioning priority | What to build | Evidence you should be able to show |
Foundation | Keep prompt design and evaluation disciplined | Versioned prompt tests and regression cases |
Retrieval | Learn chunking, search, reranking, metadata filters, grounding | RAG agent evaluated on a controlled knowledge set |
State | Learn short-term conversation-state design | Agent that preserves constraints across turns |
Memory | Separate working context from durable memory | Explicit storage/retrieval policy and memory tests |
Tool context | Transform and selectively surface tool outputs | Lower token use without lower task success |
Progressive disclosure | Load skills/references only when needed | Ablation comparing preload vs just-in-time context |
Evaluation | Measure the entire agent rather than single outputs | Trace-based test suite with quality/cost/latency results |
Harness awareness | Learn agent loops, planning, compaction, observability | A production-style agent project with traces and failure analysis |
Start with RAG pipeline fundamentals because retrieval forces you to think beyond the prompt. Build a small knowledge base, create a test set with known answers, compare retrieval strategies, and measure not only whether the final response sounds right but whether the correct evidence reached the model.
Then add multi-turn state and memory. Give your agent a task that lasts long enough to accumulate decisions; test what happens when you pass the entire transcript, when you summarize it, and when you externalize durable facts into a separate store.
Next, add tool use. Have the agent call an API that can return a large response, then compare raw injection with a filtered representation that preserves only fields relevant to the next decision.
Finally, run an ablation. Remove context deliberately and observe the result.
This is where prompt engineers often discover the new discipline. You may find that deleting four thousand tokens of generic instructions changes nothing, while removing one retrieved fact causes task accuracy to collapse; that observation tells you more about the system than another hour of wordsmithing.
Anthropic's July experiment is essentially a large-scale version of that mindset. The company changed the context architecture and measured whether the system actually got worse rather than assuming previously accumulated instructions had to remain forever.
A useful portfolio project could be an internal-policy research agent. Give it a corpus containing current policies, superseded policies, regional variants, and irrelevant documents, then require it to answer multi-step employee questions with evidence.
Your first version might simply retrieve the top chunks and append them to a long system prompt. Your second could add metadata filters and reranking; your third could compact conversation history; your fourth could put large tool outputs into external storage and retrieve them only when necessary.
Track the same evaluation questions on every version: Did it retrieve the current policy? Did it cite supporting evidence? Did it preserve constraints from prior turns? Did it incorrectly use an obsolete policy? How many input tokens did it consume? Did the final answer improve when you removed information?
That project lets you say, honestly, “I designed and evaluated context for a long-running LLM application,” rather than merely changing your LinkedIn headline.
For foundational career sequencing, the existing guide on how to become a prompt engineer remains relevant. The additional step is to treat prompt engineering as the first layer rather than the destination.
Two reactions to the shift are especially unhelpful.
The first mistake is rebranding without retraining. If your only experience consists of prompt templates and chatbot instructions, calling yourself a Context Engineer does not create retrieval, memory, state-management, tool-design, or evaluation competence.
Current hiring language is too concrete for that. Onit wants dynamic context assembly and compression; Aera asks for memory, caching, evaluation, and RAG; Infinite pl asks for prompt/context patterns, retrieval flows, agent loops, and evaluation assets.
The second mistake is dismissing context engineering as a buzzword. The terminology is fashionable, but the underlying engineering problem is observable: what information reaches an LLM changes its behavior, while excessive or badly chosen information can consume attention, cost, and latency.
Anthropic's >80% Claude Code system-prompt reduction is especially difficult to dismiss as mere marketing because the company attached the change to its own coding evaluations.
The right response sits between those extremes. Keep the prompt-engineering foundation, add system-level information management, and let your portfolio prove the new capability before your title does.
Self-Study and Structured Training Compared Honestly
You can learn context engineering through self-study. There is no technical rule that says you need a course before building RAG, memory, tool-use, or evaluation systems.
In fact, context engineering rewards experimentation because its central question is empirical: does this context policy make the agent perform better?
The difficulty is coverage. A learner who follows isolated tutorials can become good at writing prompts while never learning evaluation discipline, or build a vector-search demo without learning how to measure retrieval quality, memory contamination, or long-horizon regressions.
Factor | Self-study | Structured Prompt Engineering Program |
Basic prompting | Accessible through model docs and experimentation | Guided as part of a defined sequence |
Prompt design | Learner chooses sources and exercises | Dedicated Prompt Design & Structure module |
Advanced techniques | Often assembled across documentation and tutorials | Dedicated Advanced Prompt Techniques module |
Evaluation | Easy to postpone or perform informally | Dedicated AI Model Evaluation module |
Ethics | Depends on learner's plan | Dedicated Ethics in AI and Prompting module |
Optimization | Self-designed experimentation | Prompt Tuning & Optimization module |
Portfolio | Scope and rigor depend on learner | Capstone project plus program certificates |
Context engineering itself | Must deliberately add RAG, memory, context management, agent traces | Not explicitly named in the published Refonte curriculum |
Best use | Strong for independent builders who can define their own evals | Strong for building structured prompt-design and evaluation foundations |
The Refonte Learning curriculum currently lists eight prompt-engineering competencies plus a capstone, including prompt design, advanced techniques, tuning, evaluation, ethics, automation, and real-world use cases. The published program page does not list context engineering, RAG, or memory management as named modules.
That distinction should remain explicit.
A structured prompt program can help you build the foundation underneath context engineering, particularly instruction design and evaluation. You then need to extend that foundation into retrieval, context assembly, persistent memory, tool-result management, and long-horizon agent evaluation through additional projects or study.
I would also avoid universal claims such as “self-study makes you job-ready in three to six months.” Job readiness depends on your existing Python, software-engineering, NLP, API, data, and evaluation experience, and current AI Engineer postings often ask for production engineering skills well beyond prompting.
The meaningful comparison is therefore not fast versus slow. It is self-directed breadth versus structured foundation.
If you already know Python and have built production APIs, you may learn RAG and context management by constructing agents directly. If you are still guessing whether a prompt change improved performance because you do not have a repeatable evaluation method, strengthening prompt design and evaluation first is rational.
That sequencing matters because context engineering multiplies the number of variables you must test. Instead of comparing Prompt A with Prompt B, you might compare prompt versions, retrieval policies, chunk sizes, history summaries, memory retrieval, tool schemas, model choice, and context budgets simultaneously.
Without disciplined evaluation, context engineering becomes architecture by intuition.
The Refonte Learning Prompt Engineering Program
The Refonte Learning Prompt Engineering Program should be understood as a foundation program for prompt design, optimization, and evaluation, not as a context-engineering certification.
Its current public curriculum is specific about what it teaches, and maintaining that boundary makes the program easier to evaluate honestly.
Program detail | Published information |
Duration | Three months |
Weekly commitment | Twelve to fourteen hours per week |
Format | Online training structured around a training-and-internship model |
Curriculum | Eight named prompt-engineering modules plus capstone |
Mentor | Dr. Ashley Moore, Senior Prompt Engineer at Refonte Learning |
Mentor experience | More than twelve years of NLP and AI industry experience |
Career outcomes named by program | Prompt Engineer, AI Consultant, NLP Specialist |
Prerequisite | Pursuing or completed bachelor's degree in computer science, linguistics, or a related field |
One-time fee | $300 |
Installment option | $204 + $98 |
Certificates | Training Certificate and Certificate of Internship |
Additional recognition | Top performers may receive a Letter of Recommendation and Certificate of Appreciation |
These details are published on Refonte Learning's current program page.
The eight curriculum modules are:
Introduction to AI & NLP
Prompt Design & Structure
Advanced Prompt Techniques
Prompt Tuning & Optimization
AI Model Evaluation
Ethics in AI and Prompting
Automation of Prompts
Real-World Use Cases for Prompt Engineering
The program also lists a Capstone Project in Prompt Engineering among its featured learning components.
That curriculum aligns with the portion of the context-engineering stack that this article has argued remains indispensable. Before deciding whether an agent received the right context, you need to know how to express an instruction clearly, test model behavior, compare variants, recognize failure modes, and evaluate whether an intervention actually helped.
The tools named across the program material include OpenAI GPT models, Google BERT, Anthropic Claude, LangChain, Prompt Layer/PromptLayer, and AI-evaluation frameworks. Its FAQ also references Python, OpenAI APIs, and LangChain in the technical workflow.
The program is led by Dr. Ashley Moore, whom Refonte identifies as a Senior Prompt Engineer with more than twelve years of NLP and AI industry experience. Her published profile focuses on prompt design, evaluation, automation, and AI-model optimization.
Students who successfully complete the program receive a Training Certificate and Certificate of Internship. Refonte says outstanding performers may additionally receive a Letter of Recommendation and Certificate of Appreciation.
The published format is three months with a commitment of twelve to fourteen hours each week. Admission information says applicants should be pursuing or have completed a bachelor's degree in computer science, linguistics, or a related field.
The one-time enrollment price displayed at research time is $300. The page also offers installments of $204 and $98, which total $302; elsewhere on the same page, Refonte displays the program against a $387 list price and a 30% promotional label.
For career positioning, the program names Prompt Engineer, AI Consultant, and NLP Specialist as intended outcomes. The page also advertises “$100K+” starting compensation and “10K+” annual jobs for Prompt Engineering; those figures should be read as Refonte's own published career-market claims, not as independent salary or vacancy statistics verified in this article.
Most importantly for this article, the published curriculum does not currently name context engineering, RAG, or memory management. It would therefore be inaccurate to market the program as if it directly teaches the complete Context Engineer skill set shown in current AI Engineer postings.
The defensible value proposition is narrower and stronger: the course builds prompt design, optimization, evaluation, and model-interaction fundamentals that you need before you can manage a larger context architecture systematically.
That foundation also helps explain why “prompt engineering is obsolete” is the wrong educational conclusion. The title may broaden; the ability to instruct and evaluate language models remains embedded inside context engineering, agent engineering, and harness engineering.
For learners who want that structured foundation, review the Refonte Learning Prompt Engineering Program and compare its published curriculum with the additional RAG, memory, and agent-context skills identified in this guide.
Frequently Asked Questions and the Bottom Line
The questions below address what readers most often ask about context engineering, the future of prompt engineering, and emerging salary data.
Question area | Practical answer |
Is prompt engineering obsolete? | The standalone title is under pressure; the skill remains foundational |
What changed? | Engineers now optimize the entire inference context, not only instructions |
Is “Context Engineer” a real title? | Yes, but it is not yet standardized across the market |
Are salaries settled? | No; adjacent AI Engineer data is more robust than specialist-title data |
What should Prompt Engineers learn? | RAG, state, memory, tools, context budgeting, traces, and evaluation |
Does Refonte teach context engineering directly? | Not according to its currently published curriculum |
Is prompt engineering obsolete because of context engineering?
No. Anthropic explicitly presents context engineering as a progression from prompt engineering: prompts remain part of the context, while the engineer also manages retrieved information, tools, history, memory, and other inputs supplied during inference.
The narrower Prompt Engineer job title may become less common as employers package prompt work into AI Engineer, Applied AI Engineer, and agent-engineering jobs. Current postings from Onit, Infinite pl, Aera Technology, and Kobie already combine prompt engineering with context engineering, RAG, memory, tools, evaluation, and production software engineering.
What is context engineering?
Context engineering is the practice of deciding what information and capabilities an LLM receives at inference time, how those inputs are formatted, when they appear, and what should be excluded or compressed. Anthropic's September 29, 2025 formulation focuses on curating the optimal tokens available to the model, including information that sits outside the prompt itself.
In a real agent, that can cover system instructions, conversation history, retrieved documents, tool definitions and results, short-term state, long-term memory, summaries, and external data. LangChain's documentation treats controlling this information as a core reliability problem for AI engineers.
Did LangChain really say the Prompt Engineer title is dead?
A July 8, 2026 press.farm article explicitly frames LangChain co-founder Harrison Chase's view that way.
Primary material from Chase is more useful for understanding the substance: in his Sequoia discussion, he argues that context engineering describes much of the work LangChain has been doing and explains why long-horizon agent performance depends on context, memory, compaction, prompts, tools, and better harnesses. The safest interpretation is that the standalone title is being superseded by a larger systems discipline, not that effective instructions have become unnecessary.
How much does a Context Engineer make?
There is not yet a clean, standardized salary benchmark for an LLM-specialist Context Engineer. Glassdoor currently reports roughly $145,000 median total pay for the broader U.S. AI Engineer category, while ZipRecruiter's “Context Engineer” category reports about $101,752 average annual pay but covers a heterogeneous collection of jobs.
For that reason, exact claims such as $140,000–$230,000 for all mid-to-senior Context Engineers, or a universal 30–50% context-engineering premium, should be treated as directional secondary estimates unless accompanied by a transparent dataset. Individual senior AI and agent roles can certainly pay within or above that range, but that is not the same as a standardized context engineer salary 2026 statistic.
What skills do I need to become a Context Engineer?
Start with prompt-writing and evaluation fundamentals, then add RAG and retrieval design, ranking, context-window budgeting, multi-turn state, persistent memory, tool-result transformation, compaction, progressive disclosure, prompt/context caching, agent traces, and empirical evaluation.
You should be able to explain not merely how you changed context, but whether the change improved the agent. Current job descriptions increasingly expect engineers to prove this through regression tests, golden datasets, observability, groundedness measures, latency/cost monitoring, and production traces.
Does the Refonte Learning Prompt Engineering Program teach context engineering?
Not explicitly, according to the currently published curriculum. The program lists prompt design and structure, advanced prompting, tuning and optimization, AI model evaluation, ethics, automation, real-world prompt-engineering use cases, AI/NLP foundations, and a capstone; it does not name context engineering, RAG, or memory management as curriculum modules.
Its relevant value is foundational: context engineering still depends on understanding how to instruct language models and how to evaluate whether a change improved behavior. Learners pursuing Context Engineer or broader AI Engineer roles should add dedicated RAG, memory, context-management, and agent-system projects beyond the published program curriculum.
The evidence supports four career conclusions:
Context engineering is a real engineering shift, but Anthropic did not originate the phrase in September 2025. The term was already circulating publicly in June 2025; Anthropic gave it an influential formal treatment on September 29, then supplied unusually concrete evidence on July 24, 2026 when it reported removing more than 80% of Claude Code's system prompt for advanced Claude models without measurable coding-evaluation loss.
The Prompt Engineer title can shrink without prompt engineering becoming obsolete. Harrison Chase and LangChain are pushing the industry toward context and harness engineering, while current employers increasingly combine prompts, RAG, memory, tools, context management, evaluation, and observability inside broader AI Engineer roles.
Context Engineer salary data remains less mature than the headlines imply. Current general AI Engineer compensation data is usable as a baseline, and explicit Context Engineer jobs now exist, but title taxonomy remains noisy enough that precise specialist ranges and percentage premiums should not be presented as settled statistics.
The rational response for a working Prompt Engineer is expansion, not reinvention. Keep instruction design and evaluation, then add RAG, retrieval quality, conversation state, memory, tool-output handling, context compression, progressive disclosure, agent traces, and production evaluation. This is the same wider systems perspective covered in the broader AI engineering roadmap and career guide.
If your immediate gap is the prompt-design and evaluation foundation that context engineering builds on, the Refonte Learning Prompt Engineering Program provides a structured starting point; the next career step is to layer dedicated retrieval, memory, and agent-context engineering practice on top of it.