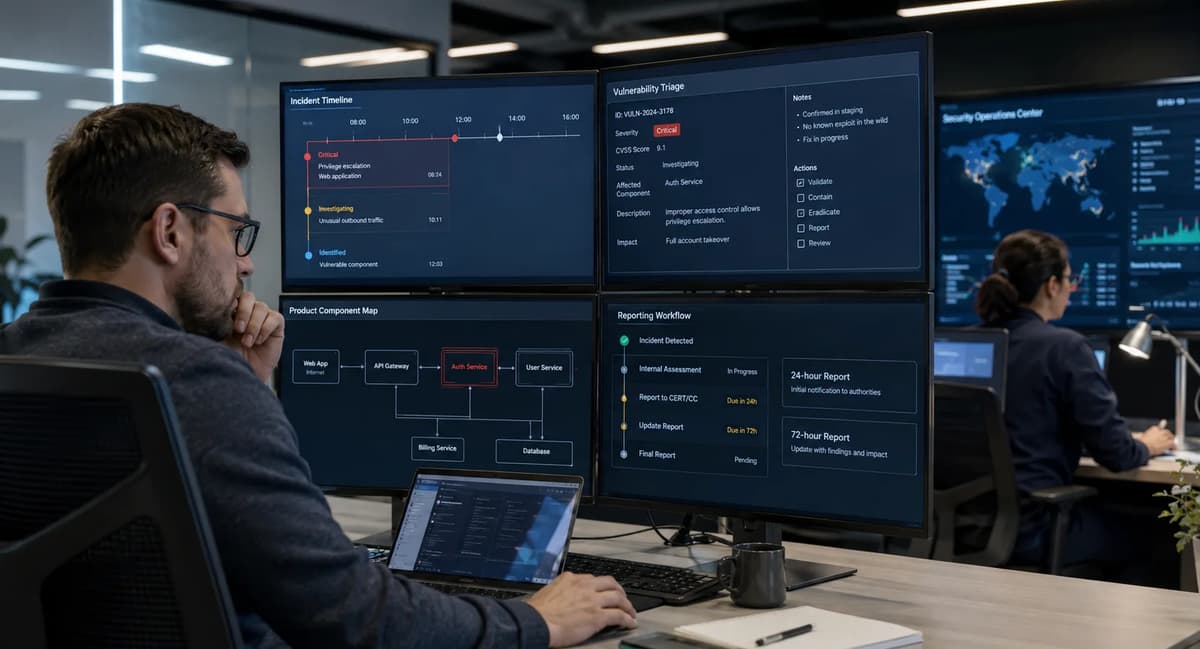
On a Friday afternoon at 16:40, a customer unexpectedly contacts your PSIRT: they have evidence that an older product version is being actively exploited. Engineering isn’t sure which component is vulnerable, and Legal debates whether the 24-hour clock has really started – “maybe we should wait for more confirmation?” In reality, under Article 14 of the Cyber Resilience Act (CRA) the clock starts the moment the manufacturer becomes aware of active exploitation or a severe incident. From September 11, 2026 onward, any time a manufacturer knows of a relevant exploit or incident, it must trigger the timed reporting process. This guide shows how to operate under uncertainty: gather facts, declare “early warning” with whatever is known, and iterate. By the end of this playbook you will have a concrete runbook and exercises to ensure your team meets the CRA’s 24-hour and 72-hour notification requirements. (The 14-day and 1-month final-report obligations will follow.) September 11, 2026 is not a far-off date – it’s when this clock starts running on your current product portfolio.
1. September 11 Turns Product Security Into a Timed Reporting System
As of 11 September 2026, manufacturers of any “products with digital elements” on the EU market must report actively exploited vulnerabilities and severe incidents in a stepwise timeline. That means a 24-hour “early warning,” a 72-hour detailed notification, and a final report (14 days after a patch for vulnerabilities, one month after initial notification for incidents). There is no single deadline – each trigger has its own clock.
Trigger | Vulnerability Path | Incident Path |
Awareness (t=0) | Manufacturer becomes aware of exploit | Manufacturer becomes aware of severe incident |
Early Warning (24 hours, max) | Preliminary alert (Product ID, states, etc.) | Preliminary alert (indicate malicious cause, product states) |
Full Notification (72 hours, max) | Initial assessment (severity, scope, mitigations pending) | Initial assessment (nature, scope, actions taken/planned) |
Final Report | 14 days after fix available (detailed vuln report) | 1 month after 72h notification (full incident report) |
Each step must be met “without undue delay, and in any case within” the time limit. For example, if an exploit is confirmed on Monday at 10:00, the 24-hour warning is due by Tuesday 10:00, and the 72-hour notification by Thursday 10:00. The final report deadline then depends: for a vulnerability it’s 14 days after the patch is out; for an incident it’s one month after the first notification. Notably, these clocks start on “awareness” of the issue – not when a CVE is published, not when counsel signs off, and not when a patch ships. Press release timelines and risk scores (CVSS, EPSS, etc.) are irrelevant to the clock. What matters is credible knowledge.
Deadline table: The obligations break out as above. In practice, put these in your runbook’s timeline table and track each clock. (Use UTC or a fixed time zone to avoid confusion.) For example:
Deadline | Time Limit | Trigger | Responsibility |
24h “Early Warning” | ≤24h after awareness | Any evidence of exploitation or incident | PSIRT Lead |
72h “Notification” | ≤72h after awareness | Initial assessment with factual details | PSIRT Lead |
Final Vulnerability Report | ≤14 days after fix available | Final remediation (patch or workaround) | Engineering/PSIRT |
Final Incident Report | ≤1 month after initial notification | Incident root-cause and mitigation summary | PSIRT Lead |
Design this timeline carefully: each phase overlaps (the 72h report can go out before a fix). Keep the two tracks separate in your runbook (the CRA-regulated final deadlines differ for vulnerabilities vs. incidents).
2. Decide Whether the Product and Organization Are in Scope
Who must report? Under the CRA, the manufacturer (or its authorized rep) of any in-scope product must report the issue. The scope definitions come from the CRA (Reg. 2024/2847) and Commission guidance. A “manufacturer” is anyone developing or marketing the product under its name. An importer has obligations only if the manufacturer is outside the EU – it may need to act as the reporting point via the platform. A distributor has no own reporting duty, unless it modifies the product. An open-source software steward (Article 24) only reports security incidents affecting their OSS project (and not all actively exploited bugs). If your role or product is unclear, err on the side of inclusion and consult legal or the regulator. Use an internal scope worksheet or checklist:
Entity scope: Are we the manufacturer (or EU rep) of this product with digital elements? (If yes, we are obligated. If we are only a distributor, we generally do not report.) If the manufacturer is outside the EU, the importer or authorized representative takes the lead on the SRP submission. If in doubt about who “owns” the product for CRA, escalate to legal.
Product scope: Is it a product with digital elements? The CRA covers hardware or software products (including components) that have some data connection functionality. In practice, anything with embedded software that can connect to networks is in scope. (It does not cover purely analog or industrial equipment without any digital interface, nor excluded categories like vehicles or medical devices by other rules.) Per transitional Article 69(3), these reporting duties apply to all such products already on the EU market by Dec 11, 2027 – i.e. legacy products in use are not exempt.
Third-party components: If the vulnerability lies in a third-party library or open-source component inside your product, you still must report it for your product. The CRA emphasizes the product as a whole, not just first-party code. Guidance is still evolving here, but treat every software component in your release as within your scope if it can be exploited in your product. (Different deployments might affect exploitability, but the reporting duty is per affected product.)
Use an escalation rule: if your team cannot agree whether the product or entity is in scope within an hour, automatically consider it in scope and start the clock. Having a legal or compliance person on call to mediate such disputes is key, but the time to resolve should be minimal. Document the decision in your log with rationale.
Internal Tips: Maintain a clear company-wide registry of who is considered the “manufacturer” for each product SKU, including any authorized representative. Track which of your products are deemed to have digital elements and whether they’ve been declared in any CRA compliance documents (like Article 13 vulnerability commitments). This mapping should be part of your initial readiness (see Section 14).
3. Define the Awareness Event That Starts the Clock
The CRA requires that the clock starts when the manufacturer becomes aware of the issue. Do not wait for formal validation, CVE publishing, or legal sign-off. “Awareness” means the first time someone in your organization has credible information that an exploit or severe incident is occurring. For example, a confidential bug report showing an exploit payload, or internal monitoring logs of unauthorized code execution, would count. The Commission’s draft guidance says this is “first knowledge that meets a reasonable threshold of plausibility” – in other words, if a trusted engineer says “this looks like an exploit,” that can start the clock.
To manage this, define internal fields in your incident-tracking system, e.g.:
awareness_at: The UTC timestamp when a credible signal arrived (e.g. customer email, IDS alert, or third-party report).
awareness_basis: A short description of the initial signal (e.g. “honeypot telemetry indicating code execution”, “CISA KEV listing for CVE-2026-1234”, “customer site reported crypto-mining activity”).
clock_owner: The role or person responsible for the reporting case (e.g. “PSIRT Manager”). This person has authority to start the CRA clock.
clock_status: Enum states like Not Started, In Progress, Paused, Closed.
decision_log: A timestamped audit trail recording decisions (who declared awareness, classification decisions, who approved notifications, etc.).
Importantly, legal approval is not the awareness event. The moment the evidence crosses your threshold of reliability, record the awareness. The legal team should advise, but cannot retrospectively pause the clock or backdate decisions. In practice, your PSIRT or security operations team should have the delegated authority to “file the notice” immediately when needed. If there is internal debate or uncertainty (for example, “the evidence is not rock-solid”), escalate quickly to a senior security decision-maker. They should decide: either send a preliminary 24h notice saying “investigation ongoing” (preferable), or quickly determine the facts.
The first output after recognizing the issue is an internal early-warning notice (not the official SRP entry yet) – often just an email or ticket update marked with the 24-hour deadline. It should say: “At awareness_at (source: awareness_basis), we have a credible indication of [exploitation/incident] in Product X.” That kick-starts your 24h clock.
4. Separate Actively Exploited Vulnerabilities from Severe Incidents
The CRA’s reporting regime has two distinct tracks: one for actively exploited vulnerabilities and one for severe incidents. These are different thresholds:
Actively Exploited Vulnerability: A software flaw in a product where “there is reliable evidence that a malicious actor has exploited it”. In other words, exploitation has actually happened. This definition is factual, not based on severity score. Evidence can be logs showing an attack, forensic analysis of compromised devices, credible threat-intel indicating the exploit was used, or inclusion in lists like CISA’s Known Exploited Vulnerabilities (KEV). A published proof-of-concept alone does not count; you need proof it occurred in the wild.
Severe Incident: An event that “negatively affects or is capable of negatively affecting the ability of a product with digital elements to protect availability, authenticity, integrity or confidentiality of sensitive or important data or functions”. Put simply, a successful attack or failure that causes major security impact (e.g. device crash, data exfiltration, execution of malware) qualifies as severe. Not every vulnerability exploitation is a “security incident” under this definition (for example, an exploit that requires user interaction and causes minor info leak might be below this bar).
Use a signal-to-threshold matrix in triage to decide which path you’re on. For example:
Signal / Source | Exploited Vulnerability? | Severe Incident? |
Customer report of exploit code | Yes – treat as active exploitation (start vuln clock) | Possibly – if data or functional compromise occurred |
Internal IDS/telemetry logs show malware | Likely – evidence of exploitation | Yes – if it impacted product’s data or availability |
CISA KEV or EUVD “exploited” flag | Yes – by definition | Depends – is the exploit disrupting product ops? |
Public exploit kit or PoC published | Not automatically (no evidence of use) | Not necessarily (until used or incident occurs) |
High CVSS & EPSS scores alone | No (indicates risk, not known exploit) | No – requires an actual incident |
Unexpected reboot or crash | Possibly (could be vulnerability being exploited) | Yes, if system integrity or availability is broken |
Detected unauthorized access | Possibly (vulnerability used to gain access) | Yes (confidentiality/integrity breach) |
In short: look for “proof of exploitation” signals (attacker IPs, malware telemetry, log evidence) to call it actively exploited. If instead you have signs of a broader security breach (e.g. data loss, persistent malware), call it a severe incident. (Often a severe incident is the result of exploitation, but the reporting requirements treat them as separate categories with separate report contents.)
Evidence quality: Any signal should be accompanied by source and confidence. Treat a researcher’s claim as provisional until you verify, but do not delay reporting. If you only have a credible tip (e.g. one customer crashed after an update) but no proof, include that under an “Initial assessment” heading and mark it as such. Remember the CRA does not demand absolute proof – it demands that if there is reliable evidence. Document your reasoning: “We are treating this as an actively exploited vulnerability because we have logs showing exploit code execution (see annex)” or “as a severe incident because multiple devices lost integrity.”
This separation also leads to different final-report deadlines (see Section 7). Always annotate in your case whether you have classified the event as a vulnerability or an incident (or both, if needed). Update that classification as more facts come in.
5. Build the 24-Hour Early-Warning Workflow
The 24-hour report is a preliminary alert, not a polished incident report. Its purpose is to alert regulators (via CSIRTs) that “something serious is happening” before details are ready. Your internal runbook should enforce a minimum viable payload for this early warning. Key fields to include at 24h (as required by the SRP template) are:
Notification Type: Are you reporting a Vulnerability or an Incident?
Notification Level: Mark this as “24h” (the platform uses this to route).
Reporting Time: Timestamp you are reporting (t+X hours).
Reporter: Who is filing this report (name/email/role).
Manufacturer Name: Your company name (always mandatory).
Product Identifier: The exact product name/ID and version range affected.
Product Type/Category: If your product is classified as “Important” or “Critical” per Annex III/IV, note that.
Affected Member States: List EU countries where the product is sold/used. If unknown, include all where sales occur.
Title/Brief Description: A concise title (“Preliminary report: [Product] exploited / security incident”).
Malicious Act Suspected?: (For incidents) a checkbox or note if you believe it’s due to malicious action.
General Info: A short statement of what is known (“Customer reported crypto-mining on device X; we have logs of code execution matching CVE-2025-5678”).
Mitigation Status: Indicate if any fix/patch is already deployed (likely “No – under development”).
Any data that is still uncertain should be noted as such (e.g. “Product version unconfirmed – investigating”). Do not leave mandatory fields blank; mark “unknown” or “to be determined.” It is better to submit partial info than to miss the deadline. For example, if you only know the product ID and that a customer was hit in Germany, list that rather than delaying. You can update and correct details in the 72h report.
Clock budget: Allocate time slices for the first 24 hours. A typical breakdown might be:
Task | Time Allotted | Owner |
Triage signal and decide “CRA? ” | 1–2 hours | PSIRT on-call |
Internal kickoff meeting (decide path) | 1 hour | PSIRT Lead + SMEs |
Draft 24h notification payload | 2–3 hours | PSIRT Analyst |
Legal/classification review | 2 hours (in parallel) | Legal (on-demand) |
Finalize fields and approval | 1 hour | PSIRT Manager & Legal |
Submit/Transmit alert internally and note deadline | 1 hour | PSIRT Manager |
Follow-up (documentation, notify execs) | 1 hour | PSIRT/Comms |
Escalation path if uncertain: If critical facts are unclear, escalate immediately up. Your “Senior Analyst” or PSIRT leader should have the authority to push the notice. For example, you might not know the exact CVE or exploit vector yet; an early warning can say “possible SQLi vulnerability under active exploitation” and reserve details. Ensure someone (Engineering or vendor team) is assigned to chase any missing info in parallel.
Fail-Safe: If the team cannot meet the 24-hour window due to confusion or absence (e.g. it’s the weekend), enforce an escalation path: the case stays open, and a backup person (e.g. manager on-call) must file the notice on behalf of the team. The clock doesn’t stop for weekends. Log each hand-off in decision_log.
6. Build the 72-Hour Notification Workflow
The 72-hour report (often called the “detailed notification”) requires a fuller picture. By 72h you should have at least initial confirmation or ruling out of the exploit, an assessment of scope, and what you’re doing about it. Key items to update/include (per ENISA’s SRP fields) are:
General Nature of Vulnerability/Incident: Flesh out what type of flaw or attack this is (e.g. “remote buffer overflow in JSON parser” or “malicious firmware update vector”).
Nature of Exploit: How was it exploited? For vulnerabilities this might be “malicious payload injected via open port”, or for incidents “unauthorized code execution via USB port.”
Corrective Measures Taken: What fixes or mitigations have been applied so far (e.g. “hotfix patch deployed to 100 test devices; disable affected feature”).
User Remediation Instructions: What steps (if any) should customers take immediately (e.g. “set firewall restrictions, disable network interface until patch”).
Date of Patch Availability: If a patch is ready, give the date (this starts the 14-day clock). If not ready, you may have to estimate (label as “planned availability: 2026-09-18”).
Detailed Description: A fuller write-up of the vulnerability/incident, its potential impact, and exploitation evidence (fill in i21/i22 for incidents or v22-v24 for vulnerabilities).
Explicitly mark which information is confirmed vs preliminary. For example, your 24h notice might have speculated “vulnerability X” with low confidence; in the 72h notice, you should update it as confirmed or withdrawn. ENISA’s template lets you copy forward fields (flagged “C” in the table). If new details emerge, do not erase the old record without note – instead append an entry. For instance, your decision_log might say: “–30h: believed worm using CVE-2023-9999. +5h: discovered CVE was incorrect, actual exploit is CVE-2024-8888. Updated payload accordingly.” This preserves auditability.
Also, double-check product mapping by 72h: use your SBOM and sales data to estimate how many devices could be affected, and in which geographies. Add this to the “scope” field. If you have partial info (e.g. only know an ISP saw it in one country), say so. Do not silently overwrite or delete any field – always note the change.
Once the 72h payload is assembled, review it carefully but do not delay. The SRP expects “without undue delay” after 72 hours as well. Have a checklist to ensure all mandatory sections (like those above) are filled. If something is missing, either append it via an update or clearly state “information pending”.
Labeling: Use tags like [CONFIRMED], [PRELIMINARY], [TBD] in your internal records to differentiate facts. For example: “Vendor analysis [PRELIMINARY]: root cause appears to be code injection via WebSocket interface.” Then update in final report as [CONFIRMED] or [CORRECTED] as you verify it.
7. Plan the Two Different Final-Report Timelines
After early and detailed notifications, you must submit a final report when the situation is resolved. The type of final report and its deadline differ:
Report Type | Trigger Event | Deadline | Owner | Key Contents |
Vulnerability Final | Corrective measure (patch/workaround) available | 14 days after patch is deployed | Engineering/PSIRT | Full technical description of the vulnerability, severity (CVSS/CWE), exploit evidence, identity of actor (if known), details of the fix or patch, verification of deployment, remaining risks, and actions for users. |
Incident Final | Initial notification submitted | 1 month after first notification (count from 72h submission) | PSIRT/Incident Team | Comprehensive description of the incident (timeline, system logs), confirmed root cause (e.g. exploited vulnerability, misconfiguration), impact assessment (data loss, downtime), steps taken and completed (mitigation, remediation), ongoing monitoring plans, and an analysis of lessons learned. |
Triggers: note that for vulnerabilities, the 14-day clock starts when a fix is available (not from the initial awareness). For example, if an exploit is patched on Sep 20, the final vulnerability report is due by Oct 4. For incidents, the one-month countdown begins from the moment you sent the 72-hour notification (not from discovery). Assign clear owners: typically an engineering team builds the patch (with PSIRT oversight) and produces the vulnerability report, while the PSIRT lead coordinates the incident report with input from all stakeholders.
Use a table like above in your runbook to keep track of these deadlines. Ensure that your team knows what constitutes “fix available”: it could be a publicly published patch or a secret hotfix you plan to distribute. If a patch is rolled out in phases, use the date of the first availability to affected users.
Closure: The final report should close the loop. Verify that the reported fix was actually applied (patch notes, update servers) and include proof (screenshots, hashes). Confirm if customers need additional actions. Conclude with a statement of compliance: e.g. “All relevant installations have been patched and no further exploitation has been observed; case closed.”
8. Create the Product-to-Component Ownership Graph
A key to timely reporting is knowing which products contain which components. Build a structured mapping of your entire portfolio to the underlying components and versions. This often requires combining multiple data sources:
SBOMs (Software Bills of Materials): Maintain an SBOM (CycloneDX, SPDX, etc.) for each product version. SBOMs list the exact software components and versions inside the product. In CRA terms, an SBOM is not a reporting artifact by itself, but it tells you which product is affected when a particular CVE is discovered. (For guidance on SBOM tooling, see our review of CRA SBOM compliance platforms and ENISA’s SBOM Adoption State of Play report.)
Release Manifests/Build Records: Your CI/CD system should tag what goes into each product build. Keep a database or spreadsheet that ties each release SKU to its component list and any open issues.
Support and Versioning Records: Track which versions are still supported or in use. End-of-life products may have different reporting handling, but they are not excluded from CRA reports once they are on-market.
Market Distribution Data: Know where each product version is sold or deployed (which EU member states, industries, etc.). Sales, deployments, and telemetry feeds (e.g. from phone-home features) can reveal which customer bases are exposed.
Customer Exposure: If possible, have a field in your CRM or vulnerability tracker noting estimated number of affected units or customers per product version. Even a rough estimate (“~5,000 devices, mostly in EU”) helps gauge severity.
Data model: A simplified table might look like:
Product SKU | Version(s) | Components (SBOM) | In-Scope Region(s) | Known Customers/Installations |
SmartSensor v1.x | v1.0–1.4 | libc-2.31, OpenSSL-1.1.1 etc. | DE, FR, IT | 1200 units (Key Telecom 2022) |
SmartSensor v2.x | v2.0–2.1 | libc-2.33, OpenSSL-3.0 etc. | All EU | 3000 units (TelCo 2023) |
ControlHub v3.5 | v3.5 only | Qt5.12, libcrypto-2.32 | BE, NL | 500 units (Utilities) |
When an alert mentions a component (say “OpenSSL-1.1.1” with a CVE), you can query this graph to find all products and versions containing it. Crucially, do not rely on SBOMs alone for CRA readiness – they tell you what could be affected, but not whether it is exploited. Use them to map products to known CVEs once a signal arrives.
Version/Market Overlap: Track old vs new versions. In many cases, “older product in use” means just a legacy version of your catalog still in the field (as in our intro scenario). Include legacy (even if unsupported) in the graph. Also note non-software components if they have firmware.
Inventory Hygiene: As part of continuous compliance, maintain and audit this product/component graph. This is similar to best practices in DevSecOps governance but applied to the product catalog under CRA rules. Make sure the people who own SBOMs (often DevOps or engineering) and those who own incident response (PSIRT) collaborate to keep it current.
9. Design the Internal Data Model and SRP Handoff
Internally, your incident case object (in your ticketing or CMDB system) must store all relevant fields and map cleanly to the ENISA Single Reporting Platform (SRP). Define an internal model like:
Manufacturer: company name, EU legal identifier
Product Name/ID: internal SKU and version range
Event Type: Vuln vs Incident
Evidence Summary: free text of exploitation data (logs, PoC, etc.)
Mitigation Status: patch ETA, workarounds in place
Customer Impact: summary of affected users/units
CSIRT Assigned: which national CSIRT is the coordinator (determined by main establishment).
Regulatory Deadlines: computed fields for the 24h and 72h cutoff times and final due dates.
Then map these to the SRP fields (per ENISA’s template). For example:
Internal Field | ENISA SRP Field | Notes |
event_type | Notification type (Vulnerability/Incident) | Filled at creation |
notification_stage | Notification level (24h/72h/Final) | Updated for each submission |
awareness_at | Reporting time - 24h | Copied to SRP field, timestamp format |
reporter | Reporter | Must match registered Assigned Rep |
manufacturer_name | Name of manufacturer | 24h must include, 72h/Final carry forward |
product_name, version_range | Product | 24h must include |
product_type/category | Product Type/Category | Optional if known |
affected_states | Member States where product available | 24h at least "EU" or known markets |
title | Title | Brief summary for humans |
vulnerability_id | CVE ID/EUVD ID | If known by 72h |
description | Full description fields (v22/v23/v24 or i21/i23) | Filled in final report |
exploit_evidence | Active exploitation evidence (if any) | Mapped to “exploit nature” fields |
mitigations | Corrective measures | 72h: planned, final: details |
severity/impact | Severity, Impact | If assessed |
Before submitting to the SRP, prepare a “submission checklist”:
Verify All required fields (marked X in Q16 table) are complete or have placeholders.
Mark Sensitivity: choose appropriate TLP. The SRP supports TLP:Amber (or stricter) to delay broad sharing. But don’t over-classify internally – only sensitive personal data or secret plans should be marked private.
Confirm Dual Control: One person populates the SRP form, another reviews it before submission. Have both log in with their EU Login accounts as ARs.
After submission, take a screenshot or PDF receipt of the confirmation page and store it in the case record (the SRP will not email receipts). Note the SRP “incident ID” if given.
Plan a retry policy: If submission fails (network error, time-out), have a backup connectivity (VPN/mobile) and try again. The clock keeps ticking, so don’t wait longer than an hour to re-submit if it fails. Document attempts.
Since ENISA is not providing an API yet, this step is manual. Consider using a secured browser profile and avoid cut-and-paste errors: copy data from your internal model carefully. Record in your system that the notification was filed, when, and by whom.
Finally, link this SRP handoff checklist to your internal runbook. The goal is that after 72h analysis, one person can submit the report quickly using the prepared data, and another can verify it, so that in a stress scenario (even at 3am) the process is second-nature.
10. Establish Decision Rights Across PSIRT, Engineering, Legal, and Communications
Clear roles and responsibilities prevent gridlock. Draft a RACI (Responsible, Accountable, Consulted, Informed) table for the key decisions. For example:
Decision / Action | PSIRT / Security Team | Engineering | Legal/Compliance | Communications |
Classify event (Vuln vs Incident) | A/R (Lead) | C | C | I |
Determine when “awareness” occurred | R (Analyst) | C | C | I |
Start the 24h clock and file 24h alert | A/R (Lead) | - | C | I |
Fill and review 72h notification | R (Analyst) | C | A/R | I |
Sensitivity/TLP marking | R (Lead) | C | A/R | I |
Content of final vulnerability report | C | A/R | C | I |
Content of final incident report | R (Lead) | C | C | I |
Decide customer notification needed | C (PSIRT) | C | A/R | R (Comms) |
Official public disclosure of issue | C | C | A/R | A/R (with Execs) |
PSIRT / Security Team: Generally accountable for monitoring, triage, reporting content, and liaising with CSIRTs and ENISA. They coordinate the process (A/R for classification, initial filings, incident report).
Engineering: Responsible for developing fixes and technical details. They own the final vulnerability report content (severity, fix description).
Legal/Compliance: Consulted for interpretation of scope, endorsement of messaging (though they should not delay immediate reporting). They set policy for disclosure and customer notification (e.g. privacy laws). They should be looped in but not as blockers.
Communications: Responsible for external notifications to customers or media. They must work from PSIRT/Legal input for accuracy and tone.
Decision rights: Explicitly empower one person as the CRA Reporting Owner (often the PSIRT Manager) to make go/no-go calls within each deadline. For example, they alone should decide “we have enough to send the 24h alert” or to mark information as sensitive. Engineering should decide the fix date; legal decides classification or whether to request SRP’s delayed dissemination (under the delegated act). If any disagreement (e.g. “Should we consider this a severe incident or just a vulnerability?”), the RACI table indicates escalation – typically PSIRT Lead accountable, so they can escalate to the CISO or executive if needed.
Finally, align this RACI with your existing organizational roles. For instance, if your CISO is ultimately responsible for CRA compliance, mark them “Accountable” at a high level (informed but empowered) and delegate the day-to-day in the table above. This avoids scenario where “nobody could start the clock because Legal was not present.”
For a broader view on assigning these roles and integrating them with existing development workflows, see DevSecOps compliance and governance practices. To clarify how CRA tasks fit across teams, see Cybersecurity versus DevSecOps use cases.
11. Protect Sensitive Evidence and Coordinate Disclosure
The information you handle may include exploit code, customer data, or other sensitive details. Minimize access to this evidence: only personnel directly involved in triage and remediation should see full logs or PII. In your case management system, mark the case as confidential or restricted. For example, use role-based access so engineers fixing the bug don’t see unrelated incident logs, and vice versa.
Maintain the integrity of evidence. If possible, capture hashes or write-once copies of key artifacts (system images, network packet captures). Keep an audit trail of who accessed them. In the SRP itself, there is a “sensitivity of information” field; use it honestly (TLP:Amber if customer identities are present, for instance). Remember: the receiving CSIRT can (in very rare cases) delay sharing further if the report is marked sensitive, but keep internal responders working with full data as needed.
Be careful with legal privilege: if legal is involved in internal analysis, that discussion may be privileged, but you still must extract the non-privileged facts needed for reporting. Do not refuse to give needed facts to the CSIRT on the basis of privilege – just ensure you only omit attorney-advice commentary, not the raw evidence of exploitation.
Coordinate with any outside parties carefully. If you are working with a vulnerability researcher or CERT, set expectations up front about confidentiality and communication. If the issue will become public, plan the public disclosure path in tandem (see Section 11 of the CRA text for requirements on user notification). But do not let the idea of a press release slow down your SRP submission. The SRP info goes to regulators; customer communications can follow your normal incident process timeline (“notify customers without undue delay, when appropriate” – Art. 14(8)).
In summary: apply “least privilege” on evidence, classify with caution, and share with regulators promptly. Do not over-restrict the team’s access to the information they need; a common pitfall is locking the evidence too tight and then being unable to analyze it. Balance security with practicality: relevant staff should have decrypted data if needed, under audit.
12. Connect Detection, Triage, Remediation, and Customer Action
Integrate your vulnerability management and incident response pipelines. The CRA clock often starts with a detection from your own tools. For example, suppose your vulnerability scanner (e.g. using Trivy) flags a known CVE in a recent build. That alone doesn’t trigger CRA reporting – you need evidence of exploitation. However, it should immediately create a PSIRT ticket because if that CVE shows up in KEV or is reported exploited, you’ll need to know where it is in production. Similarly, customer security reports or threat intelligence should auto-populate your tracking system and trigger alerts.
Below is a worked scenario timeline example (simplified) illustrating how an actively exploited vulnerability case might flow:
Time (UTC) | Action / Event |
2026-09-11 16:40 (Fri) | Triage: A client reports their 1.2 version device has been compromised. PSIRT opens a case; awareness_at=2026-09-11 16:40. Initial email says “Customer X saw malware attempting buffer overflow on Port 2222.” Risk unclear but plausibly exploit of CVE-2026-1234 in libXYZ. |
2026-09-11 18:00 | Preliminary Analysis: Engineers confirm unusual traffic to Port 2222; security logs show repeated attempts. No patch yet. PSIRT decides to treat as an actively exploited vulnerability. 24h clock started. |
2026-09-11 20:00 | 24h Notification Prepared: PSIRT drafts early warning: product “SecureController 1.2”, unknown attack vector (not enough time), affected MS: DE, FR. Owner “MFG-INC”. Mitigations: “Customers advised to disable network access immediately.” Internal reviewers sign off. Case fields: notification_level=24h. |
2026-09-12 16:30 (Sat) | Internal 24h Deadline: Early warning emailed to CSIRT coordinator and ENISA. (Official SRP submission to occur Monday due to SRP offline on weekend). Update clock_status=24h_notified. |
2026-09-13 10:00 (Sun) | Investigation: Engineers find root cause: a command injection in the web interface (CVE-2026-1234) that has a known exploit. 70% of deployed devices still have v1.2 (mostly DE and FR). No fix yet, but a patch is in dev. |
2026-09-14 16:00 (Mon) | 72h Notification Due: PSIRT finalizes detailed report. Now fields are filled: Title=”Active exploitation of CVE-2026-1234 in SecureController”. Mitigations: “Patch scheduled by 2026-09-18; customers disabling port 2222.” Root cause confirmed, scope estimated. Submit via SRP at 16:00. (Set notification_level=72h.) |
2026-09-18 | Remediation: A patch is released to all customers. (This is the “corrective measure available” date.) |
2026-09-24 | Final Vulnerability Report Due: 6 days after patch (well within 14-day window). Report includes patch verification, CVSS=9.8, note that attackers believed to be a known cybercriminal group. Affirm all affected devices patched. |
This timeline shows how detection (customer report), triage (classify exploited vulnerability), and mitigation (patch) interact with reporting deadlines. Note the clock ran continuously through the weekend. In practice, hold regular “checkpoint” meetings so that, e.g., on Saturday morning an off-duty lead is consulted to ensure nothing critical is missed.
Incorporate tools like Trivy into the pipeline to flag CVEs as soon as code is written or containers are built. When Trivy or a similar scanner detects a high-risk vulnerability, use a workflow that notifies the PSIRT automatically. Although a scanner finding alone does not start the CRA clock, it helps the team monitor the right signals. In this scenario, Trivy could have identified CVE-2026-1234 in the SBOM for SecureController 1.2, prompting manual verification.
13. Run Tabletop Exercises Against the 24-Hour Clock
Drills make readiness measurable. Schedule at least one 24-hour exercise simulating an actively exploited vulnerability, and one simulating a severe incident. For example:
Exercise A (Vulnerability): “A newly discovered bug in our smart sensor firmware is rumored to be exploited. A simulated security researcher emails evidence to PSIRT.” Inject to roles: engineer has partial logs, head of sales reports customer complaints. The objective is to complete the 24h and 72h notifications and product mapping.
Exercise B (Incident): “A coordinated DDoS hits multiple devices of our industrial control system product. The network team notices data integrity issues.” Objective: identify as severe incident, practice the incident path and final report.
Use a compressed 24h timeline format (the “exercise clock”) to keep it short (e.g. simulate 24h in 2 hours real time). Include at least two scenario injects (initial alert, then new information during the drill). Provide an observer checklist with criteria such as:
Did the team log an awareness_at by the first inject?
Was an early warning created and sent before the exercise clock hit 24h?
Did the participants identify and include required fields in the mock SRP report?
Was the product-component mapping consulted?
Were classification disagreements escalated properly?
Define pass/fail criteria. For example, a pass might require: “A plausible 24h notice was submitted on time and the team did not second-guess waiting for perfect proof before starting the clock.” A fail might be if the team misses the deadline or cannot articulate who is responsible. Let observers note things like how long it took to identify roles and deadlines, and whether legal or communications was consulted correctly.
After each drill, score readiness on key metrics (clock met or not, report completeness, evidence handled correctly). Document lessons: for example, you might discover your SBOM mapping is incomplete (say, the exercise component wasn’t in the SBOM) and add that to a gap list.
14. Measure Readiness and Execute the Final 30-Day Plan
With structures in place, compile a CRA Readiness Scorecard and 30-day action plan. Include metrics and a gap register. Examples:
Readiness Item | Status | Owner | Target Date |
Identify CRA reporting owner and backup | Completed | Security Ops | – |
Update PSIRT runbook with CRA timeline | In progress | PSIRT Lead | 2026-08-30 |
Build product-component inventory (SBOMs) | Gap – 70% done | DevOps | 2026-09-07 |
Map products to markets and CSIRTs | Gap | Compliance | 2026-09-10 |
Onboard SRP test account (via EU Login) | Not started | PSIRT Manager | 2026-09-05 |
Complete one 24h tabletop exercise | Gap | PSIRT Lead | 2026-09-03 |
Train staff on new compliance requirements | Gap | HR / Learning | 2026-09-15 |
Each row should have a clear owner and due date. After your first drill (Section 13), fill the “Gap” items based on what failed. For example, if you realized during the exercise that nobody knew who the EU CSIRT contact was, add “Identify national CSIRT coordinator” as a task. Maintain this as a living log.
Set exit criteria: you should be able to check “Yes” to statements like “PSIRT has met the 24h drill criteria at least once” and “All critical product-market mappings are documented.” Also track elapsed time on mock deadlines during drills (e.g. “average triage-to-notification time: 6h”).
For the final 30 days leading up to September 11, make weekly milestones: by Sept 4 have all SBOMs ready; by Sept 7 have SRP registration complete; by Sept 10 have at least two practice runs; by Sept 11 know exactly who is on call. Assign owners to each milestone and prepare to review daily in leadership meetings.
Readiness Scorecard: If helpful, assign points or a traffic-light status (Green/Amber/Red) to each major area: clock awareness, mapping, reporting workflows, evidence handling, and exercises. Aim for all “Green” before go-live.
Use this runbook as your guide – it won’t be fully baked on Day 1, but these metrics and targets ensure you continuously improve.
Conclusion: The first steps for a product-security lead are to (1) assign a CRA reporting owner in your team and ensure they can act immediately, (2) inventory all products with digital elements (including legacy versions) and map their components and markets, and (3) run a table-top drill against the 24-hour clock to uncover any workflow gaps. Remember: the CRA clock runs on “when we knew”, not “when it was proven”. Ambiguity is inevitable; build in a bias to action and a log of decisions.
This is complex work, combining technical detection, compliance, and communication. Consider strengthening your team’s skills through structured training. For example, the Refonte Learning Cybersecurity & DevSecOps Program (a 3-month part-time course with certificates) covers incident response, secure CI/CD, DevSecOps practices, and risk mitigation. It can equip practitioners with the tools and mindset needed to implement runbooks like this under pressure.