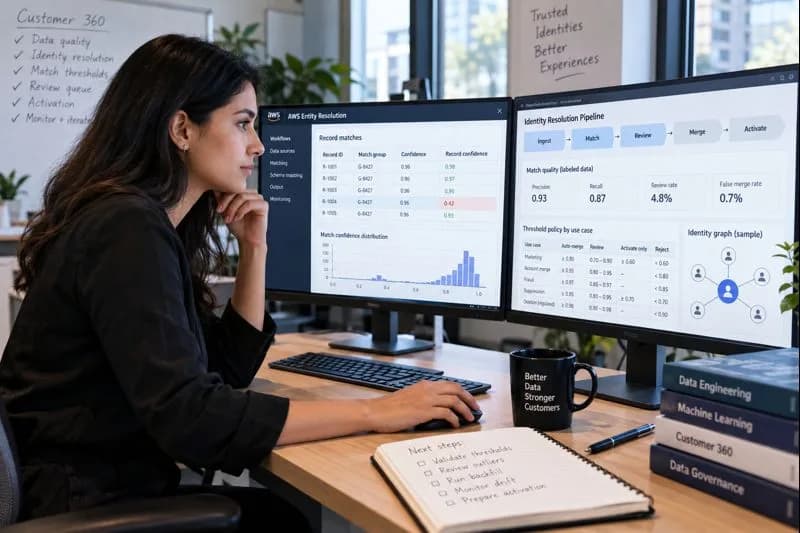
AWS added record-level confidence scores for machine-learning matching on September 9, 2026. The AWS launch announcement matters because incremental matching can now expose evidence about each record, not only a score for the matched set. That is useful, but it does not turn a model output into a verified identity. A high score still reflects statistical similarity under a particular workflow, schema, source mix, and time period. It does not establish legal identity, account ownership, household membership, consent, fraud, or the proper scope of a deletion request.
The operational risk appears when one score is reused for several decisions. A threshold that is tolerable for low-risk personalization may be unacceptable for account consolidation. A score that helps prioritize a fraud review must not become an adverse decision by itself. A linkage that is useful for discovering records related to a privacy request is not enough evidence to delete those records automatically. The business consequence, not the numerical neatness of the score, determines the control.
This guide replaces the single global threshold with a governed policy matrix. It shows how to label representative truth data, measure precision and recall by cohort, distinguish group confidence from record confidence, define auto-merge and review bands, preserve lineage, control incremental updates, and reverse a bad merge after identity state has propagated. The acceptance standard is not that a workflow ran successfully. It is that every production decision can be explained, measured, authorized, contained, and reversed without losing the original source identities.
1. Define the Identity Decision and Its Business Consequence
Start by naming the decision, not the model. “Resolve customers” is too broad to govern. The same pair of records can support several actions with different consequences: show a preferred product category, combine two loyalty profiles, route a suspicious transaction for review, suppress marketing, or locate records for a regulated deletion request. Each action needs its own threshold, approver, evidence requirement, retention rule, and rollback path.
A match score is evidence about similarity. Business certainty is a policy conclusion that may require additional proof. For example, exact agreement on an email address can be powerful matching evidence, but shared inboxes, recycled addresses, aliases, data-entry errors, and compromised accounts make it insufficient for some decisions. Likewise, a shared postal address may support household personalization while directly contradicting a person-level merge.
Write a decision contract before tuning. At minimum, record the entity type, action, affected systems, expected benefit, false-merge harm, false-split harm, permissible attributes, review authority, maximum propagation delay, and reversal objective. The contract should also state what the score cannot authorize. A fraud score may create a case; it cannot freeze an account. A deletion linkage may produce candidate records; it cannot establish that every record belongs to the requester.
Low consequence: temporary personalization, with no profile consolidation and a short time to live.
Moderate consequence: analytics aggregation or service context that remains traceable to source records.
High consequence: account merge, identity-based suppression, fraud controls, or any action that changes an authoritative system.
Regulated consequence: access, correction, deletion, retention, or legal hold, where identity verification and evidence rules remain separate from match confidence.
This framing prevents a common governance failure: optimizing a model metric while ignoring the state change it triggers. The right threshold is the one that keeps expected harm within an approved limit for a specific action, not the one that produces the cleanest dashboard.
2. Understand Group Confidence and Record Confidence
The current AWS ML workflow documentation distinguishes ConfidenceLevel, the confidence for the matching group, from RecordConfidenceLevel, the confidence for an individual record in an incremental ML workflow. The AWS Entity Resolution glossary provides the product vocabulary, while the broader service overview explains the rule-based, ML-based, and provider matching methods. Treat these fields as different evidence objects. Never copy the group score into a record-level policy column or assume that every member deserves the set score.
There is also a first-party documentation timing issue to manage. The September 9, 2026 launch announcement and the current ML workflow output table describe incremental ML record confidence. By contrast, older summary wording in the service overview and glossary has continued to describe automatic processing as rule-based only, and the documentation history last listed an Entity Resolution update dated April 27, 2026 when checked for this guide. For production contracts, the launch announcement, the current workflow output table, and observed output should govern. Treat the older summary wording as documentation lag, not as a reason to invent behavior.
2.1 Read the Matched-Set Score Correctly
A group-level score answers a set-level question: how confidently does the workflow regard the records as a matching group? It is not a guarantee that every pairwise relationship is equally strong. Cluster construction can be supported by a strong core, while one member contributes less evidence or enters through a shared attribute. A group score can therefore conceal the exact record that deserves review.
Use ConfidenceLevel for set-level monitoring, such as comparing cluster quality distributions or identifying unusually large high-scoring groups. Do not use it as the sole predicate for merging each member. A production decision should evaluate the record-level score, contradictory attributes, cluster topology, source trust, and business policy together. If the workflow output lacks record-level confidence because it is not an incremental ML result, the policy must fail closed or follow a separately validated path.
2.2 Identify Weak Records Inside a Strong Cluster
Consider this hypothetical customer 360 cluster. The numbers are illustrative; they are not a published AWS calibration and must not be copied as default thresholds. The group receives ConfidenceLevel = 0.970, but the members do not carry equal evidence.
Record | Evidence and score | Governed decision |
A: CRM | Verified email and phone agree with B and C. RecordConfidenceLevel = 0.998. | Core member. Eligible for the policy band appropriate to the business action. |
B: Commerce | Email agrees with A; phone and delivery address agree with C. Score 0.996. | Core member. Preserve the commerce customer ID even if a resolved ID is assigned. |
C: Service | Phone agrees with A and B; recent authenticated service event. Score 0.993. | Core member. Service history may be associated only under an approved merge policy. |
D: Loyalty | Name, normalized phone, and postal code agree. Score 0.986. | Possible core member, but account merge may still require review if loyalty value is material. |
E: Lead file | Common surname and household address only; different first name, no email, no phone. Score 0.610. | Weak outlier. Keep separate or route to review. Do not inherit the group score. |
If a policy auto-merges all five rows because the group score exceeds 0.95, it converts a set-level signal into a false person-level claim. The correct action is to preserve the strong core, isolate E, and ask whether the target entity is a person or a household. That decision remains reversible because every source ID, score, and membership edge is retained.
3. Build a Labeled Truth Set Before Choosing Thresholds
Threshold design starts with labels, not score histograms. Build a golden dataset containing verified matches, verified non-matches, ambiguous cases, shared-household cases, recycled identifiers, sparse records, conflicting attributes, duplicate source IDs, and records added after an existing cluster was formed. Labels should come from evidence that is independent of the model score, such as authenticated account ownership, steward investigation, contractual customer records, or another approved source of truth.
Sample the production population rather than only easy historical examples. Stratify by source, country, script, language, customer age, missing fields, household density, business segment, and record freshness. Oversample rare but expensive errors, including twins, family members sharing contact details, business accounts with several users, and privacy requests spanning old systems. Keep a blinded holdout set that is not used to select thresholds.
The labeling guide must define person, account, organization, device, and household separately. It should permit “uncertain” rather than forcing reviewers to guess. Measure inter-reviewer agreement, adjudicate disagreements, and retain the evidence used for each label. A model can only be evaluated against the meaning encoded by those labels; weak labels produce false precision.
Input quality gates belong in the same test harness. AWS Glue Data Quality rules can support measurable checks for completeness, uniqueness, validity, and change over time, but the particular rules and limits remain yours. Validate unique IDs, source identifiers, schema mappings, null handling, field normalization, and the frequency of contradictory attributes before scoring. A threshold cannot compensate for a broken identifier contract.
4. Measure Precision, Recall, Coverage, and Review Load
Report more than an overall accuracy number. Precision measures how often accepted matches are correct; recall measures how many true matches the policy finds. A false merge appears in the precision denominator. A false split appears in the recall denominator. Coverage shows how much of the eligible population receives an automated or reviewed decision, and review volume shows whether the operating model can actually sustain the chosen bands.
Metric | Decision question | Required reporting |
Precision | Of the records merged or activated, how many links are correct? | By policy band, source pair, country, entity type, and missing-field pattern. |
Recall | Of the true links, how many did the policy recover? | Include false splits caused by conservative thresholds and unresolved review cases. |
Coverage | What share of eligible records receives a usable decision? | Separate auto-merge, activate-only, review, reject, and no-score outcomes. |
Review volume | Can stewards resolve the queue before its business deadline? | Cases per day, age distribution, handling time, escalation rate, and backlog. |
Expected loss | Does the policy reduce total business harm? | False merges multiplied by their cost, plus false splits, review work, delay, and recovery cost. |
Use confidence intervals, not only point estimates. A policy that shows 100 percent precision on 40 examples is not equivalent to one tested on 40,000 representative decisions. For high-impact automation, require a lower confidence bound that remains above the approved precision floor. Document exclusions, unresolved labels, and sample weights so the metric cannot be improved by quietly removing difficult cohorts.
4.1 Segment Metrics by Source, Cohort, and Missing Fields
A single cutoff rarely has a single meaning. A score of 0.97 may have excellent precision for authenticated commerce records matched to CRM data and poor precision for purchased lead files with missing phone numbers. Report the score distribution and outcome metrics for each material cohort. At minimum, segment by source pair, country, language or script, record age, number of populated identity fields, household density, and whether any high-trust identifier agrees or conflicts.
Track the population entering each band. A stable global precision can hide a deteriorating source because its volume is small. Conversely, a source-mix shift can move the overall score distribution even when the model’s within-cohort behavior is unchanged. The monitoring record should therefore include both outcome quality and the denominator: how many records, which sources, and which evidence patterns produced the result.
4.2 Price False Merges and False Splits Differently
False merges and false splits are not symmetrical. A false split may show a returning customer as new or prevent useful service context from appearing. A false merge can expose another person’s history, combine balances, misdirect a fraud action, suppress the wrong person, or propagate an incorrect deletion. For many authoritative workflows, one false merge costs more than hundreds of false splits.
Translate those consequences into a policy loss model. The simplest form is: expected loss equals false merges multiplied by false-merge cost, plus false splits multiplied by false-split cost, plus review volume multiplied by handling cost, plus delay and recovery cost. Use ranges when a precise monetary value is unavailable. Privacy, legal, and safety impacts should remain explicit even when they cannot be reduced honestly to currency.
This is why the threshold that maximizes F1 is often the wrong production threshold. F1 weights precision and recall in a particular mathematical way; it does not know that an account merge may be difficult to reverse or that missing an opt-out can create regulatory exposure. The policy owner chooses the loss boundary, and model metrics show whether a candidate threshold stays inside it.
5. Design Auto-Merge, Review, Activation, and Reject Bands
Do not create one “matched” flag. Create explicit decision bands with different allowed actions. Auto-merge changes authoritative identity state. Activate-only permits a bounded downstream use without consolidating source records. Review holds the case for a steward. Reject keeps the records separate for that policy. A record can be activate-only for personalization and simultaneously ineligible for account merge.
The following bands are illustrative starting points for policy design, not vendor defaults or guaranteed calibrations. Replace every number with results from your labeled population. A contradiction, such as different verified dates of birth or two concurrently authenticated owners, should override a high score and route the case away from automation.
Business use | Illustrative policy bands | Required control |
Low-risk personalization | Activate-only at >= 0.90; sample or review 0.75-0.899; do not use below 0.75. | No authoritative merge. Short time to live, no sensitive inference, easy suppression, and sampled outcome review. |
Account merge | Auto-merge only at >= 0.995 with corroboration and no contradiction; review 0.970-0.994; keep separate below. | Very high cohort precision, original IDs retained, split tested, balances and entitlements reconciled. |
Fraud | Use higher scores to prioritize evidence collection; lower scores may still route for review. | No adverse action from match score alone. Investigator sees source evidence and contradictory attributes. |
Suppression | Propagate only through verified identifiers or an exceptionally precise approved band; review ambiguous households. | Define person, account, email, phone, and household scope. Log why each destination was suppressed. |
Regulated deletion | No score-only deletion. Use confidence to discover candidate records, then verify scope and authority. | Approved identity verification, legal basis, system inventory, deletion evidence, exceptions, and replay-safe audit trail. |
Bands should be monotonic in permitted consequence. A lower threshold may enable a reversible offer, while a higher threshold may permit a provisional resolved view. That does not mean any score automatically authorizes a regulated or adverse action. Some policies have no auto-action band at all. Fraud and deletion often use the score as a queueing signal, with independent verification remaining mandatory.
Specify tie breakers and abstention rules. If the top two candidate clusters are close, if a record conflicts on a high-trust field, if the source is outside the validated population, or if the review queue is over capacity, the system should abstain. Silent fallback to the group score is not an acceptable recovery behavior.
Acceptance gate: For an account-merge pilot, require the lower 95 percent confidence bound on precision to meet the approved floor in every high-impact cohort, zero known critical false merges in the blinded holdout and failure-injection suite, 100 percent source-ID lineage, and a demonstrated split-and-replay recovery within the defined objective. The exact floor and recovery time belong to the organization’s risk policy. |
6. Preserve Schema, Model, Policy, and Lineage Evidence
A reversible merge needs more than the winning resolved ID. Preserve every original source ID, input source, raw and normalized identity fields permitted by policy, MatchID, ConfidenceLevel, RecordConfidenceLevel when present, workflow configuration, schema-mapping version, run timestamp, decision-policy version, reviewer decision, and downstream propagation event. If AWS does not expose a model version identifier, do not invent one. Record the observable workflow configuration, service change date, run identifier, and policy version instead.
Schema stability is an operational contract. The record-level field is documented for incremental ML output, so consumers must define whether it is required, nullable, or absent for other processing modes. A newly missing field, changed scale, renamed source column, or altered null convention should quarantine the batch rather than coerce values silently. The AWS troubleshooting guidance also makes unique IDs and schema mappings central to successful workflows; validate them before records reach the decision engine.
Store lineage as append-only decision evidence. A current “golden profile” is not enough because it shows only the latest state. You need the membership event that added a record, the score and rule that authorized it, the prior cluster, every downstream target, and any manual override. These records support privacy accountability aligned with the NIST Privacy Framework and make identity changes auditable across cloud-native data pipelines.
Input evidence: source, unique ID, ingestion time, mapped fields, normalization version, and quality result.
Match evidence: workflow, run, matched set, group score, record score, conflicting attributes, and candidate alternatives.
Decision evidence: policy version, band, allowed action, approver or steward, reason code, and expiration time.
Propagation evidence: destination, original and resolved IDs, event ID, write result, reconciliation status, and compensating action.
Minimize access to this evidence because identity linkage can itself be sensitive. Stewards need enough detail to decide correctly, but not unrestricted access to every customer attribute. Apply least privilege, retention limits, purpose restrictions, and monitored export controls to review tools and audit stores.
7. Govern Incremental Matching and Existing Clusters
AWS announced incremental ML matching on May 4, 2026, and the incremental ML launch notice describes processing new records rather than rerunning the entire dataset. Incremental operation reduces latency and cost, but it creates a harder governance question: how should a new record change an identity that already exists and has already been activated? The new score must be evaluated against the current cluster, its prior decisions, and the consequences already propagated.
Treat each incremental result as a proposed membership event, not a replacement snapshot. Validate that the source event is new or changed, apply idempotency keys, retain the previous cluster version, and compare the new record with the validated policy. If a record would connect two existing clusters, expand a cluster beyond an approved size, or introduce a contradiction, hold it for review even when the numerical score is high.
Operational patterns from real-time data integration are relevant here: late arrivals, duplicate delivery, out-of-order updates, replay, and partial downstream failure all affect identity state. A watermark or successful job status does not prove that every destination received the same decision. Reconcile the match output, decision log, customer master, activation platforms, and suppression systems by event ID and source ID.
Backfills require a separate authorization. Historical records can have different missingness, formats, and source quality from recent events, so current thresholds may not retain their precision. Run backfills in shadow mode, compare cluster deltas, cap propagation, and preserve a pre-backfill crosswalk. Reprocessing the workflow creates a new resolution result; it does not undo email, service, fraud, billing, or privacy state already written elsewhere.
8. Handle Households, Shared Identifiers, and Identity Drift
Entity resolution fails when teams leave the entity type implicit. A household, person, account, organization, and device can share attributes without being interchangeable. Family members share addresses and sometimes phones. Employees share a corporate switchboard and office address. Parents and children may share an inbox. Businesses may reuse a billing contact across several legal entities. These are legitimate relationships, not noise to be merged away.
Define separate identifiers and policies for person-level and household-level views. A household cluster can support aggregate personalization or service routing, while person records remain distinct. If a downstream system can store only one resolved ID, do not force a household relationship into a person field. Use an explicit relationship table or withhold that use case until the destination can represent the distinction.
Identity evidence also drifts. Phone numbers are recycled, email aliases change, people move, names change, and shared identifiers become personal or vice versa. Apply freshness and validity rules to evidence, and make the decision policy time-aware. A five-year-old matching phone number should not necessarily outweigh a recent authenticated contradiction.
8.1 Detect Outliers and Ambiguous Cluster Membership
Record confidence makes weak membership visible, but score alone is not enough. Monitor the gap between the weakest member and the cluster core, the number of contradictory high-trust attributes, cluster size, source diversity, repeated identifiers, and the distance between the best and second-best candidate. Flag bridge records that connect otherwise separate clusters through a common address, phone, or domain.
Transitive linking documentation for advanced rule-based matching is a useful warning even though it is a different matching mode: a bridging record can create an unexpectedly broad group. In ML governance, test the same failure shape. The control objective is not to reproduce rule-based transitivity, but to prove that weak shared evidence cannot silently convert two known people into one production identity.
A practical outlier rule can combine record-level score, contradiction severity, and cluster context. For example, route any member below the merge band, any member with a verified attribute conflict, or any membership that increases cluster size beyond the validated range. The policy should explain which condition triggered the hold so a steward can investigate efficiently.
8.2 Escalate High-Impact Cases to Human Review
Human review is a controlled decision service, not a dumping ground for uncertain records. The queue should show source provenance, normalized and original values, score, group context, contradictions, previous decisions, affected downstream systems, and the permitted actions. Hide unrelated sensitive fields. Require a reason code and prevent a reviewer from approving an action outside the case’s policy.
Prioritize by consequence and deadline, not simply by score. A borderline regulated request may need faster handling than a slightly weaker marketing record. Measure review agreement, overturn rate, handling time, rework, queue age, and later confirmed errors by reviewer and cohort. Sample auto-merge decisions as well, because a queue containing only borderline cases cannot reveal systematic mistakes in the automatic band.
Escalate cases with conflicting authoritative evidence, suspected identity theft, legal hold, vulnerable-person concerns, or cross-jurisdiction uncertainty to the appropriate privacy, risk, or legal owner. The steward decides match policy; they should not be asked to interpret law or make an adverse fraud decision outside their mandate.
Failure injection: In a nonproduction truth set, add a bridge record that shares a household address and common surname with Person A, but has a different verified first name, date of birth, email, and phone. Submit it incrementally while Person A and Person B already have separate clusters. The expected result is review or rejection with no downstream merge. If a high group score causes automatic consolidation, stop the rollout, quarantine the batch, restore the prior crosswalk, split the clusters, and replay only approved identity events. |
9. Propagate Resolved Identity Without Losing Original IDs
A resolved ID should be an additional key, not a destructive replacement for source identifiers. Keep the CRM customer ID, commerce account ID, service ID, loyalty ID, and event ID in downstream records. Consumers need to trace a metric or action back to the exact source record and to detach that record later without rewriting history blindly.
Design propagation as versioned events: add member, remove member, replace resolved ID, suppress scope, and reverse decision. Include an idempotency key and the policy version. Destinations acknowledge the event and report the state they reached. This event contract follows the same discipline as robust database integration strategies: controlled schema changes, transactional boundaries where available, retries that do not duplicate effects, and reconciliation after partial failure.
Do not let downstream systems infer merge semantics from a changed customer ID. Send the action, scope, effective time, old and new identifiers, and the evidence reference explicitly. For analytics, preserve a slowly changing crosswalk so historical reports can reproduce the identity view used at the time. For operational systems, document which attributes are mastered, copied, or left untouched.
A propagation success response proves only that a write was accepted. It does not prove that a campaign audience, service screen, fraud graph, or deletion inventory now reflects the correct person. Reconciliation must compare expected and observed outcomes at the business-object level.
10. Validate Marketing, Service, Fraud, and Privacy Outcomes
Model evaluation asks whether labeled records were linked correctly. Downstream validation asks whether the business system behaved correctly after that link. Both are required. A high-precision match policy can still fail because an activation tool cached an old profile, a service platform chose the wrong mastered attribute, a fraud graph treated household edges as person identity, or a privacy workflow failed to reach an archived database.
For marketing, compare audience membership, contact frequency, opt-out inheritance, and personalization outcomes against a control group. For service, verify that agents see the correct history without exposing another person’s case. For fraud, follow the evidence-first pattern illustrated by AWS guidance on entity-resolution-supported fraud detection, but keep human investigation and independent controls between a match and any adverse action. For privacy, reconcile candidate discovery, identity verification, legal scope, system execution, and proof of completion separately.
Assign validation to the teams that understand the destination. The distinction between BI and analytics responsibilities matters: analytics teams can measure cohort quality and business outcomes, while operational owners must confirm that customer-facing state, permissions, and transactions remain correct. Neither a dashboard nor a successful pipeline run substitutes for source-system reconciliation.
Marketing check: no increase in complaints, duplicate contacts, or opt-out violations beyond the approved limit.
Service check: sampled cases show the correct person, history, entitlements, and visibility boundaries.
Fraud check: match confidence changes case priority only as authorized; no automatic sanction is introduced.
Privacy check: candidate records are verified before action, exceptions are recorded, and completion is reconciled across every in-scope system.
11. Monitor Score Drift and Data-Quality Regression
Monitor the system at four layers: input quality, score behavior, decision behavior, and business outcome. Input metrics include unique-ID violations, null rates, normalization failures, source delay, schema changes, and contradictory fields. Score metrics include distribution shifts, band share, no-score rates, weak-member rate, and the gap between core and outlier records. Decision metrics include auto-merge volume, review rate, overrides, queue age, and cluster-size changes. Outcome metrics include confirmed false merges, false splits, complaints, suppression errors, fraud escalations, and recovery work.
Always slice these metrics by cohort. A global score distribution can stay stable while one country’s address parser fails or a new source stops supplying phone numbers. Compare current performance with the labeled baseline and with a recent stable window. Investigate both sudden changes and gradual movement. A growing review queue may be the first evidence that source quality or population mix has shifted.
Define stop conditions before launch. Examples include any confirmed cross-person merge affecting regulated deletion, fraud, balances, or access; a precision confidence bound below the approved floor; lineage missing for any authoritative merge; an unapproved schema change; or a review backlog above sustainable capacity for two consecutive operating periods. A stop condition pauses new propagation. It does not delete evidence or force a hurried threshold change.
Recovery begins with containment: disable the affected policy action, preserve the incoming results, and quarantine unpropagated cases. Diagnose whether the cause is data, mapping, model behavior, threshold policy, steward error, or downstream handling. Revalidate on a corrected holdout, then resume through the same rollout rings rather than switching everything back on at once.
12. Reprocess, Split, and Roll Back Incorrect Merges
Reprocessing and rollback solve different problems. Reprocessing runs the matching workflow again with corrected data or configuration. It can produce a better cluster, but it cannot recall a campaign, uncombine a service history, reverse an account entitlement, remove a fraud edge, or restore a record already deleted downstream. Rollback is a coordinated business-state operation across every destination touched by the earlier decision.
AWS provides a workflow for deleting records from Entity Resolution, which is relevant to data management. Do not confuse deletion from a matching workflow with splitting a resolved identity or reversing propagated state. A safe split needs the prior membership graph, original IDs, mastered attributes, downstream event log, and a destination-by-destination repair plan. Where a destination cannot split data cleanly, document manual remediation and residual risk before approving auto-merge.
Preserve the following evidence for every split and replay: the erroneous membership event, the label or investigation that disproved it, the policy and score that authorized it, the last known correct cluster, all affected destinations, the compensating event for each destination, and reconciliation showing the restored result. The same principle that makes persistent identity state and lineage useful in other stateful systems applies here: the current snapshot is not enough to explain or reverse a sequence of changes.
1. Freeze new propagation for the affected policy, cohort, workflow run, or cluster range.
2. Snapshot the current source records, cluster versions, decision logs, and downstream states.
3. Create the corrected clusters without overwriting the erroneous version, then approve the split.
4. Emit compensating events in dependency order, starting with systems that master identifiers or permissions.
5. Replay only approved post-split events using idempotency keys, then reconcile every destination.
6. Document customer, privacy, risk, or financial remediation and update the labeled truth set.
Set a recovery objective and test it. For example, a pilot may require a five-record false merge to be identified, split, replayed, and reconciled within four hours with no loss of original IDs. The exact objective depends on business harm. If the team cannot meet it in a controlled exercise, the auto-merge band is not production-ready.
13. Roll Out Threshold Policies by Risk Tier
Roll out capability in rings, not by flipping a global threshold. Begin with shadow scoring, where results are labeled and measured but cannot change downstream state. Next, permit bounded activate-only use for a low-risk cohort. Then test a small account-merge population with strong evidence, low volume, and a staffed review and recovery window. High-impact and regulated actions remain candidate-discovery or review workflows until their independent controls are proven.
Ring | Allowed action | Promotion evidence |
0: Shadow | Score, label, and compare only. No activation or merge. | Representative truth set, cohort metrics, schema contract, and failure tests pass. |
1: Activate-only | Reversible low-risk use with expiration and control group. | Outcome reconciliation, complaint and suppression checks, and queue capacity remain within limits. |
2: Limited merge | Small, high-evidence cohort with on-call stewards and split tooling. | Precision gate, complete lineage, successful recovery drill, and downstream owner sign-off. |
3: Scaled policy | Approved use cases only, with cohort limits and automated monitoring. | Several stable windows, sampled auto-decisions, drift controls, and tested rollback remain effective. |
Promotion is per policy and cohort. Success in personalization does not authorize account merge, and success in one country does not validate another. Maintain a control group and a kill switch for each propagated action. During rollback, restore the prior policy version and crosswalk, but continue collecting shadow scores so the investigation retains evidence.
Do not lower thresholds simply to clear a review backlog. Reduce eligible volume, add capacity, improve data quality, or redesign the policy. Converting operational overload into automated false merges hides the queue while increasing the cost of recovery.
14. Establish Acceptance Gates and Stewardship Ownership
Production ownership must be explicit. The business policy owner defines the consequence and risk appetite. Data-quality owners maintain source contracts and labels. The matching owner runs evaluation and drift analysis. Privacy, legal, fraud, or risk teams approve controls within their mandate. Data stewards decide ambiguous memberships. Platform teams own propagation, observability, and rollback. Downstream owners reconcile the state they consume. Clear database and data-engineering ownership boundaries prevent a model team from approving its own high-impact business action.
Owner | Decision right | Required evidence |
Business policy owner | Approves purpose, consequence, bands, and expected-loss limit. | Use-case contract, benefit, harm analysis, and downstream scope. |
Data quality and matching | Approves schema, labels, cohort evaluation, and monitoring. | Truth-set provenance, precision, recall, coverage, review volume, and drift results. |
Privacy, legal, risk, or fraud | Approves high-impact controls within the relevant mandate. | Purpose limitation, identity verification, adverse-action boundary, audit, and retention. |
Data steward | Accepts, rejects, splits, or escalates cases allowed by policy. | Source evidence, contradictions, reason code, and reviewer accountability. |
Platform and downstream owners | Authorize propagation, rollback, and reconciliation. | Lineage completeness, idempotency, recovery drill, and destination sign-off. |
A production gate should be binary and evidence-based. Do not approve because the score “looks high” or the API call succeeded. Approve only when the labeled holdout meets precision and recall requirements by cohort, false-merge and false-split costs are inside the policy limit, coverage is useful, the review queue fits staffing capacity, every authoritative decision has lineage, downstream reconciliation passes, and the split-and-replay drill meets its recovery objective.
The standing stop rule should be equally clear: any critical false merge, untraceable authoritative decision, schema-contract breach, or failed recovery drill pauses the affected action. The recovery path is to contain, diagnose, correct, revalidate, and re-enter through shadow mode. The rollback path is to restore the prior identity crosswalk and policy, emit compensating events, replay approved changes, and reconcile business state. These are separate controls, and both must exist before automation expands.
For teams developing the transferable analytical foundations behind this work, the Refonte Learning Data Analytics Program is a three-month program requiring approximately 12 to 14 hours per week. Its published coverage includes Python, exploratory analysis, visualization, SQL, machine learning, deep learning, optimization, and analytical decision-making. Those skills support evaluation and governance, but the program page does not claim a dedicated AWS Entity Resolution or customer 360 module.
Record-level confidence is valuable because it reveals variation that a group score can hide. The production standard, however, remains larger than the score: a verified decision purpose, representative labels, consequence-specific thresholds, protected review, durable source lineage, downstream reconciliation, and a rehearsed split. Use the score as evidence. Keep identity authority with the governed process that can explain, test, authorize, observe, reverse, and audit what the organization does next.