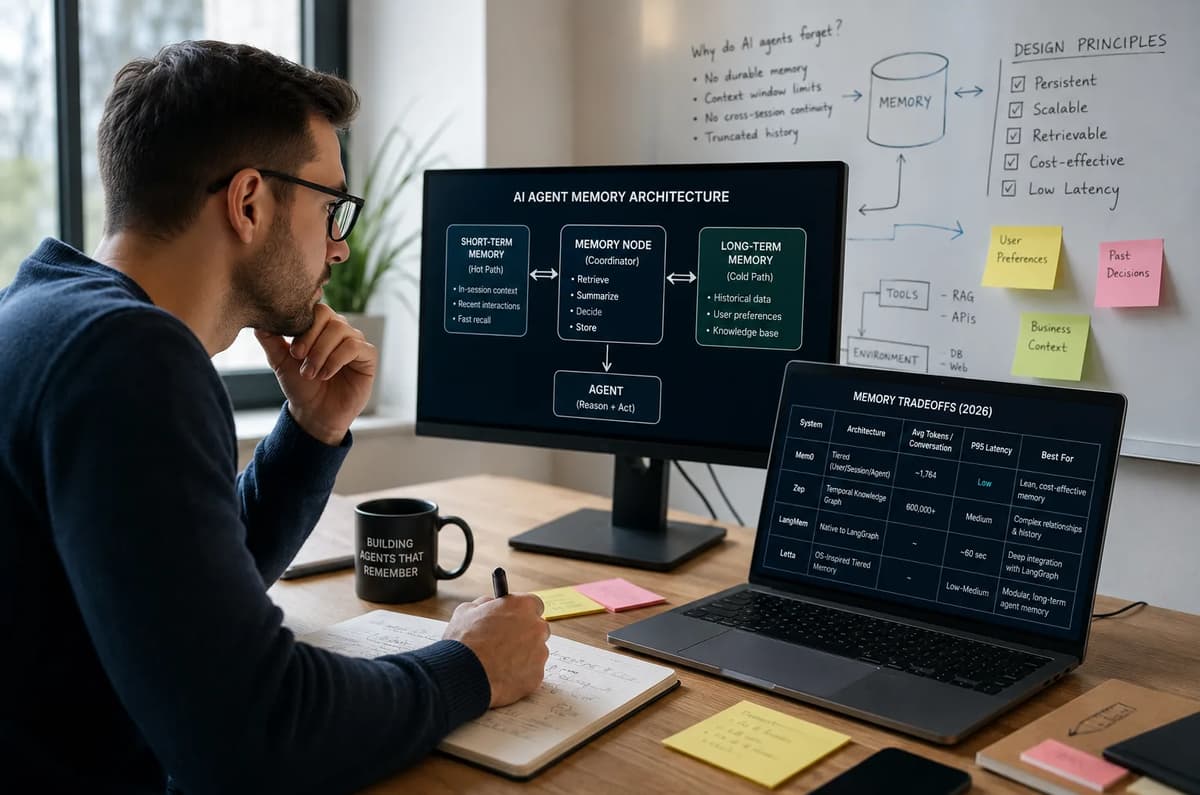
I have seen the same failure pattern more than once: an AI agent performs flawlessly in a controlled demo, remembers every constraint inside a 20-minute session, calls the right tools, and looks ready for production. Then a user returns two days later and the agent asks a question they already answered, ignores a correction they made last week, or acts on a preference that stopped being true three months ago.
The model did not suddenly become less intelligent. The system had never been given durable memory.
That distinction matters in 2026. Robert J. Szczerba, writing in Forbes on July 7, 2026, revisited Gartner's warning that more than 40% of agentic AI projects could be cancelled by 2027. The Gartner causes highlighted by Forbes were escalating costs, unclear business value, weak governance, inadequate data access, ownership problems, and insufficient operational discipline, not simply inadequate model intelligence.
Memory is not a cause Gartner explicitly identified, and it would be inaccurate to pretend otherwise. My engineering argument is narrower: poor agentic AI memory architecture is one of the concrete technical mechanisms through which the pilot-to-production gap appears, particularly when an agent must maintain continuity across sessions, users, changing facts, and long-running workflows.
This article examines the AI agent memory systems 2026 engineering teams are actually discussing: Mem0, Zep, LangMem, and Letta. We will compare their architectures, token profiles, agent memory latency, and operational tradeoffs, then turn those findings into an architecture you can build and skills you can develop through the Refonte Learning Agentic AI Engineer Program, whose current curriculum explicitly includes memory and state management.
The Agentic AI Failure Rate Nobody Wants to Talk About
The headline number is uncomfortable, but it needs precision.
Forbes reported Gartner's forecast that more than 40% of agentic AI projects could be cancelled by the end of 2027. Szczerba emphasized that the forecast was never primarily an indictment of model capability: the problems Gartner associated with cancellation included cost, unclear business value, and insufficient risk controls.
A separate data point comes from Deloitte's Tech Trends 2026. Deloitte reports that 30% of surveyed organizations were exploring agentic options and 38% were piloting them, while 14% had solutions ready to deploy and 11% were actively using agentic systems in production.
Those numbers are sometimes compressed into an "11–14% production success rate." That shorthand is useful for describing the scaling gap, but it is not technically exact: 14% means ready to deploy, while 11% means actively in production. They are different maturity stages, not two measurements of one standardized success metric.
Reported signal | What it actually means | How I would use it |
More than 40% cancelled by 2027 | Gartner forecast, revisited by Forbes in July 2026 | Evidence of a broad commercialization problem |
14% ready to deploy | Deloitte maturity finding | Evidence that few projects leave experimentation cleanly |
11% actively in production | Deloitte maturity finding | Stronger evidence of the pilot-to-production gap |
Up to 54% stall after 3–9 months | Figure circulating in 2026 secondary writeups | Directional field signal, not a standardized benchmark |
There is also a widely circulated 54% figure describing projects that stall roughly three to nine months after encouraging pilots. For example, ReadSignal's 2026 analysis describes a 54% stall rate during that period, while other 2026 secondary summaries repeat similar claims. I could not establish a primary survey instrument behind that number with the same confidence as Deloitte's 11% and 14% figures, so I would treat it as a practitioner signal rather than canonical industry data.
That source discipline matters. The agentic AI project failure rate is high enough without blending different surveys until they appear more definitive than they are.
Why Pilots Stall Between 3 and 9 Months
A demo tests an agent's intelligence over minutes. Production tests its state over months.
During a pilot, everyone is usually looking at today's prompt, today's customer account, today's tool responses, and one clean conversation. The context window can disguise an absent memory architecture because almost everything the agent needs still fits inside the active prompt.
Production eventually introduces the conditions demos avoid:
users return after hours, days, or weeks;
preferences and business facts change;
several conversations belong to the same identity;
one agent hands work to another;
context gets summarized or truncated;
memory stores accumulate contradictory entries;
retrieval latency begins affecting user-facing response time;
privacy and deletion requirements become real operational constraints.
This is why six months of usage teaches you more about agent memory than six hundred carefully scripted demos.
A 2026 Fountain City engineering guide by Sebastian Chedal makes essentially the same observation from production deployments: systems degrade when the context window is treated as storage, with stale facts, retrieval noise, and growing histories becoming increasingly damaging as the agent ages.
That is where the question changes from "Can the model reason?" to "Can the system preserve the right state, forget the wrong state, and retrieve the right piece of history quickly enough to matter?"
It's Not the Model: It's the Memory
When an agent forgets that a customer prefers email over phone, teams often reach first for the model layer: larger model, bigger context window, better system prompt, more sophisticated reasoning.
That can improve reasoning. It does not create persistence.
A foundation model receives whatever context your application assembles for the current inference call. Without an external persistence mechanism, a fact that existed yesterday is not automatically available today; the 2025 Mem0 research paper frames this as a central limitation of long-running LLM applications and argues that larger windows delay rather than eliminate the problem.
Symptom | Tempting diagnosis | More useful memory diagnosis |
Agent repeats an onboarding question | "The prompt is weak" | Prior answer was never persisted or retrieved |
Agent follows an old preference | "Model hallucination" | Memory lacks update/invalidation semantics |
Agent forgets a decision from last week | "Need a larger context window" | Decision exists outside current session state |
Response takes 12 seconds | "Model is slow" | Memory search/reranking dominates latency |
Agent gives contradictory answers | "Reasoning failure" | Conflicting memories reached context together |
This is also why memory deserves treatment separately from the broader 2026 agentic AI engineering toolkit. Tool calling, orchestration, APIs, models, and agent frameworks matter, but none of them automatically answers the persistence question.
The latest memory research increasingly treats memory as an architecture in its own right. A March 2026 survey by Pengfei Du formalizes agent memory as a write–manage–read loop and highlights write filtering, contradiction handling, latency budgets, privacy, consolidation, retrieval, and forgetting as distinct engineering problems.
That is the mental shift I recommend: do not ask whether your agent "has memory." Ask what it writes, who owns that memory, how facts change, what gets retrieved, how retrieval is evaluated, when data expires, and what the operation costs.
What "Memory" Actually Means in an Agent Architecture
The word memory has become dangerously overloaded.
A developer says "we have memory" because LangGraph preserves a thread. Another means they store conversation embeddings in Pinecone. Another has a customer profile table. A Letta user may mean agent-editable memory blocks, while a Zep implementation may mean a temporally aware entity graph.
These are different capabilities.
A useful production taxonomy is:
Memory layer | Scope | Example | Primary engineering concern |
Working/context memory | One inference or active context | Current prompt, scratchpad, recent turns | Token budget and relevance |
Session/thread memory | One ongoing task or conversation | LangGraph checkpointed state | Persistence and recovery |
Long-term user memory | Across conversations | Preferences, past decisions | Identity, retrieval, updates |
Episodic memory | Historical experiences | "Refund workflow failed last Friday" | Temporal retrieval |
Semantic memory | Durable facts | User role, product configuration | Accuracy and contradiction handling |
Procedural memory | Learned behavior | Preferred workflow or routing rule | Safe behavioral updates |
Relational/temporal memory | Facts plus changing relationships | Account owner changed from A to B | Time validity and provenance |
LangChain's current LangMem documentation explicitly supports extracting information from interactions, maintaining long-term memory, hot-path memory operations, background memory management, and native integration with LangGraph's long-term storage layer.
The distinction is architectural rather than semantic. Your storage choice, retrieval strategy, identity model, latency budget, and update rules should differ depending on which row you are trying to implement.
Context Window vs. Session Memory vs. Long-Term Memory
I use three questions when reviewing an agent design.
Will this information survive the next model call? Will it survive the next process restart? Will it survive the next user session?
If you cannot answer all three independently, your memory architecture is probably underspecified.
Context window: information temporarily available to the LLM during inference.
Session memory: state that preserves continuity within a thread or workflow, potentially across process boundaries.
Long-term memory: information deliberately retained and retrievable across sessions, such as preferences, prior outcomes, stable facts, corrections, and learned procedures.
This is why a massive context window is not equivalent to long-term memory for LLM agents. Even when history technically fits, sending everything forces the model to process irrelevant history repeatedly, raises token and latency costs, and does not solve contradiction, deletion, identity, provenance, or expiration.
The Mem0 LoCoMo evaluation illustrates the cost difference. Its full-context baseline processed about 26,031 tokens and recorded roughly 17.1 seconds p95 total latency in that experimental setup, whereas selective memory approaches used far smaller retrieved contexts.
Memory is also separate from interoperability. Refonte's article on MCP vs A2A vs OpenAPI for AI agents addresses how systems expose capabilities and communicate; memory answers what persistent state an agent carries through those interactions.
Protocols connect an agent to the world. Memory connects an agent to its own past.
Mem0: The Tiered User/Session/Agent Model
Mem0's basic design is attractive because it starts by compressing experience into memory instead of treating raw history as memory.
The 2025 Mem0 paper describes an incremental extraction-and-update pipeline. New interactions produce candidate memories, semantically similar existing memories are retrieved, and an LLM chooses among ADD, UPDATE, DELETE, or NOOP operations to reconcile the new information with what is already stored.
Avinash Tyagi's August 11, 2026 Levelop comparison describes Mem0 as organizing memory across user, session, and agent scopes, backed by vector, graph, and key-value representations. A separate July 27, 2026 comparison by Datapace's Maxime Dalessandro describes the current product in four scope layers: conversation, session, user, and organization, which is a useful reminder that product terminology and versions evolve.
Mem0 property | Practical implication |
Extraction-first | Raw transcripts do not have to become permanent memory |
ADD/UPDATE/DELETE/NOOP reconciliation | Better support for changing facts than append-only vector storage |
Scope-aware storage | Easier separation of session, user, and shared memory |
Optional graph representation | Adds relational structure when flat facts are insufficient |
LLM-mediated memory decisions | Flexible, but extraction/update quality becomes another failure surface |
Now for the famous token number.
Levelop repeats the headline that Mem0 averages around 1,764 memory tokens in the cited LoCoMo comparison. The original Mem0 paper confirms 1,764 in Table 2, but defines that deployment metric as tokens retrieved to serve as context for answering a query.
Later in the same paper, the authors report roughly 7,000 tokens per conversation to materialize the full Mem0 long-term store.
Those are not contradictory once you see that they measure different things. One is the retrieved context budget; the other is the materialized memory footprint.
This distinction is exactly why 2026 Mem0 vs Zep vs LangMem comparisons should not be reduced to a single token number.
Zep: Temporal Knowledge Graphs and Their Token Cost
Zep starts from a different problem: facts do not merely exist; facts change.
Its 2025 research paper introduces Zep as a memory layer built around Graphiti, a temporally aware knowledge graph designed to synthesize conversational and structured business data while preserving historical relationships. The paper reports 94.8% on the Deep Memory Retrieval benchmark versus 93.4% for MemGPT and improvements on LongMemEval, although those numbers come from Zep's own authors and should be read accordingly.
Datapace's July 2026 comparison captures the design nicely: entities become nodes, relationships become facts or edges, and invalidated facts can retain the period during which they were true instead of simply disappearing.
Zep strength | Why it matters |
Temporal knowledge graph | Handles changing facts explicitly |
Entity relationships | Better fit for relational memory than isolated preference facts |
Fact invalidation | Old truth can be preserved without remaining current truth |
Provenance/time structure | Supports "what was true when?" questions |
Rich graph processing | Potentially more operationally expensive than simpler fact memory |
The controversial part is cost.
The Mem0 team's benchmark reports 3,911 retrieved memory tokens for Zep in Table 2, but separately says Zep's materialized graph exceeded 600,000 tokens per conversation in its test. Levelop repeats the 600,000-plus comparison while clearly tying it back to the Mem0 team's evaluation rather than an independent standardized benchmark.
Do not convert that into "Zep always uses 600,000 tokens." That would be bad engineering analysis.
Zep publicly disputed Mem0's benchmark configuration. Daniel Chalef and Preston Rasmussen's Zep response, updated June 3, 2026, argues that Mem0 tested Zep incorrectly and reports a corrected LoCoMo result of 75.14% ± 0.17; the article is itself vendor-authored, so it should be treated as a counterclaim rather than neutral arbitration.
This disagreement is valuable. It tells us that the numbers are field reports from different configurations, not immutable product characteristics.
Zep makes most sense when temporal relationships are part of the domain itself: changing ownership, evolving customer state, historical dependencies, previous contractual status, or facts where "when was this true?" matters as much as "what is true?"
LangMem: Native LangGraph Memory and Its Latency Tradeoff
LangMem approaches memory from inside the LangGraph ecosystem rather than as a completely separate memory platform.
The official LangMem documentation describes functional primitives that can work with different storage systems, agent-controlled memory operations in the hot path, a background memory manager for extracting and updating knowledge, and native integration with LangGraph's long-term memory store.
That makes the architectural decision straightforward for many LangGraph teams.
LangMem characteristic | Engineering implication |
Native LangGraph integration | Low conceptual friction for existing LangGraph applications |
Storage-agnostic primitives | Developer retains infrastructure choice |
Semantic memory | Stores facts and durable knowledge |
Episodic memory | Can retain experience/history |
Procedural memory | Supports behavior and prompt refinement |
Hot-path + background workflows | Memory work can be split by latency sensitivity |
Datapace therefore characterizes LangMem less as an independent memory service and more as building blocks for teams already owning the surrounding LangGraph architecture.
Then there is the number that gets everyone's attention: nearly 60 seconds p95 search latency.
In the Mem0 team's LoCoMo benchmark, LangMem recorded 17.99 seconds p50 search latency, 59.82 seconds p95 search latency, and 60.40 seconds p95 total latency. Levelop's August 2026 comparison highlights the same result and warns that such tail latency would be problematic for interactive chat.
That does not mean "LangMem takes 60 seconds" as a universal product truth. It means one published competitor-run benchmark, under one implementation and dataset, produced that result.
This is a recurring lesson in agent memory latency: benchmark the actual pipeline you intend to ship. Backend choice, embedding model, index size, filters, network topology, concurrency, reranking, memory-manager design, and hot-path versus background execution can all change the latency profile.
For a batch research agent, a slower memory operation may be acceptable. For voice, support chat, coding copilots, or interactive workflow agents, it may make the architecture unusable without moving expensive work off the critical path.
Letta: An OS-Inspired Approach to Tiered Memory
Letta AI agent memory comes from the MemGPT research lineage and asks a more unusual question: what if the agent itself participates in managing its context?
MemGPT introduced an operating-system-inspired memory hierarchy in which limited LLM context behaves like scarce main memory while information can move between immediate and external storage. Letta's own technical writing describes core memory maintained in context alongside external conversational, archival, and file-backed memory.
Datapace describes modern Letta as agent-managed context: editable memory blocks remain in the active context, while archival storage holds information that does not need continuous visibility.
Letta concept | OS analogy | Agent consequence |
Core memory blocks | RAM | High-priority state remains immediately accessible |
Archival memory | Disk | Larger history retrieved when required |
Editable memory | Memory management | Agent can change what remains salient |
Shared blocks | Shared memory | Multiple agents can reference common state |
External/file memory | Filesystem | Large artifacts need not consume core context |
This architecture can be powerful for persistent digital coworkers, assistants with evolving identities, or long-running autonomous agents that need to curate their own state.
The tradeoff is control.
With an extraction-oriented platform, your application largely determines what gets written and retrieved. In an agent-managed architecture, you are deliberately allowing the agent more influence over which state remains visible, what gets archived, and how its memory evolves.
That creates a new engineering question: is the agent competent enough to manage the memory that its future behavior depends on?
There is no directly comparable 2026 Letta token or p95 latency number from the same Mem0 table used for Mem0, Zep, and LangMem. Treating Letta as though it had one would manufacture comparability that the source data does not provide.
That absence is itself useful: architecture should win your evaluation because it matches your workload, not because somebody managed to fit every system into a four-column benchmark.
Head-to-Head: Token Cost, Latency, and Architecture Compared
This is the comparison practitioners usually want, but the caveat comes first:
There is no single standardized 2026 benchmark that establishes universal token cost and latency for Mem0, Zep, LangMem, and Letta.
The figures below combine the Mem0 research benchmark with 2026 technical writeups from Levelop and Datapace, alongside vendor documentation and Zep's published rebuttal. Their experimental setups and metrics differ, and vendor-authored benchmark claims conflict.
System | Architecture and best fit | Reported cost and latency signals |
Mem0 | Architecture: Extract/update long-term facts; optional graph Best fit: Personalization and efficient cross-session memory | Token signal: 1,764 retrieved memory tokens in Mem0 Table 2; the same paper says approximately 7k for the materialized store Latency signal: 0.20s p95 search; 1.44s p95 total in the Mem0 benchmark |
Zep | Architecture: Temporal knowledge graph Best fit: Evolving relational and temporal facts | Token signal: 3,911 retrieved tokens in Mem0 Table 2; Mem0 authors report more than 600k for the materialized graph in their setup Latency signal: 0.778s p95 search in the Mem0 test; Zep disputes the competitor configuration |
LangMem | Architecture: LangGraph-native memory primitives Best fit: LangGraph-native semantic, episodic, and procedural memory | Token signal: 127 retrieved memory tokens in Mem0 Table 2 Latency signal: 59.82s p95 search in the Mem0 benchmark |
Letta | Architecture: Agent-managed hierarchical memory Best fit: Persistent agents that actively curate context | Token signal: No apples-to-apples token figure in that benchmark Latency signal: No apples-to-apples latency figure in that benchmark |
Mem0's Table 2 explicitly defines "memory tokens" as retrieved material serving as context, which is why comparing its 1,764 figure directly against a total materialized-store figure would be misleading.
Zep is the clearest example of benchmark disagreement. The Mem0 paper reported one latency/quality profile, while Zep's Chalef and Rasmussen argue that a corrected implementation materially changes the result.
So my practical Mem0 vs Zep vs LangMem decision tree is simpler:
Start with Mem0 when user/session memory, extraction, and a lean retrieval path dominate.
Start with Zep when changing relationships and point-in-time truth are first-class requirements.
Start with LangMem when LangGraph is already your orchestration substrate and you want framework-native memory primitives.
Start with Letta when the agent itself should curate an evolving working memory and identity.
Then benchmark against your workload rather than defending that initial choice.
When Latency Matters More Than Recall Depth
The most accurate memory system is not automatically the best production system.
A customer asking, "Where is my shipment?" will not celebrate sophisticated temporal recall if the memory stage adds 12 seconds before the model starts speaking. A research agent running unattended for 30 minutes may happily spend several seconds recovering richer history.
Set a memory latency budget according to the interaction:
Workload | Memory priority |
Voice agent | Extremely low tail latency |
Interactive customer support | Low p95, high relevance |
Coding copilot | Low-to-moderate latency, strong task continuity |
Autonomous research | Recall depth can outweigh latency |
Offline workflow agent | Background consolidation is often preferable |
Compliance investigation | Provenance and temporal accuracy may dominate speed |
This is where architecture turns into product engineering.
Optimize p95, not just averages. The slowest five percent of retrievals are the ones users describe as "the agent keeps hanging."
The Dual-Layer Pattern: Hot Path, Cold Path, and the Memory Node
One of the most useful agentic AI memory architecture patterns appearing repeatedly in 2026 engineering writeups is a two-layer split.
Sebastian Chedal's Fountain City guide describes Tier 1 as context-window "RAM" containing recent turns, the current scratchpad, and a small set of retrieved memories, while Tier 2 is a persistent SQL, vector, or specialized memory layer. DigitalApplied's 2026 technical guide uses similar terminology, a hot path, a cold path, and a dedicated memory node that decides what should persist.
This is a practitioner pattern, not an official standard.
Component | Responsibility | Latency profile |
Hot-path context | Current task, recent messages, critical preferences | Must be fast |
Fast memory retrieval | Fetch small number of immediately relevant memories | Usually synchronous |
Cold persistent store | Durable episodes, facts, relationships | Can be slower |
Memory node | Extract, classify, reconcile, and schedule writes | Often partly asynchronous |
Consolidation process | Merge duplicates, summarize episodes, expire stale state | Background/offline |
A production turn can therefore look like this:
Load thread/session state.
Identify the current user, agent, and task namespaces.
Search long-term memory for a small relevant set.
Assemble recent context plus retrieved memory.
Generate the action or response.
Pass the interaction to a memory node.
Decide whether each candidate should be added, updated, invalidated, ignored, or expired.
Perform expensive summarization, graph updates, or consolidation away from the user-facing critical path where possible.
This gives you a clean separation between recall and memory formation.
That separation matters because writing memory can be more expensive than reading it. Extraction, contradiction checks, embedding generation, entity resolution, graph mutation, reranking, and summarization do not all belong between the user's request and the agent's answer.
The dual-layer design also lets you degrade gracefully. If cold-path retrieval is unavailable, the agent may still operate on session state with reduced continuity instead of blocking the entire interaction.
In production systems, graceful memory degradation is often preferable to treating the memory service as a single synchronous dependency that can take the whole agent down.
Designing Memory Into an Agent From Day One, Not Bolting It On
The hardest memory migrations I have seen started with the sentence: "For now, let's just save the conversation."
Six months later, "the conversation" has become millions of messages with no clear scope, expiration rules, identity boundaries, supersession semantics, or evaluation dataset.
Fountain City's recommendation is the right one: define the memory taxonomy before the storage layer. Its June 2026 guide explicitly warns that teams often embed everything first and discover much later that retrieval is polluted because nobody decided what deserved to become memory.
At minimum, I want a durable memory object to carry fields like these:
Field | Why it exists |
scope | User, session, organization, agent, workflow |
type | Semantic, episodic, procedural, relational |
content | The memory itself |
source | Conversation, tool result, database, human update |
created_at | When it entered memory |
valid_from / valid_to | When the fact is true |
confidence | Reliability signal |
supersedes | Which older fact it replaces |
provenance | Evidence for auditing/debugging |
retention_policy | When it should expire or be deleted |
The temporal fields become especially important when "remembering" conflicts with "remembering correctly." Zep's architecture focuses strongly on that problem by maintaining historical relationships and validity instead of flattening each entity to one timeless fact.
Memory also needs a write policy.
"Store everything" is not a policy. You need explicit rules for what is durable, what is session-only, what requires confirmation, what may be inferred, what cannot be persisted for privacy reasons, and what must be removed when the authoritative source changes.
Common Mistakes That Compound Into Memory Failures
Most memory bugs do not start spectacularly. They compound quietly.
Using transcripts as the database. Raw history is evidence; it is not automatically a usable memory representation.
Mixing RAG and user memory indiscriminately. Product documentation and a user's personal preference have different authority, lifecycles, and namespaces. Fountain City explicitly recommends separating those retrieval domains.
Append-only facts. "Customer lives in Berlin" and "Customer moved to Madrid" should not become equally valid vector hits forever.
Ignoring identity boundaries. A memory system without rigorous user/tenant scoping eventually becomes a data-isolation problem.
Making all memory work synchronous. Expensive consolidation and graph construction can destroy interactive latency.
Treating extraction as truth. LLM-produced memory should preserve provenance because extraction itself can be wrong.
Never testing forgetting. Correct deletion, invalidation, and expiration are just as important as recall.
Measuring output quality without measuring retrieval. A bad answer may be caused by a good model receiving the wrong memory.
The 2026 survey literature now reflects the same shift. Du's taxonomy treats write, management, and read policies as separate components, with open problems including consolidation, causally grounded retrieval, trustworthy reflection, learned forgetting, and privacy governance.
A robust memory architecture therefore needs both remembering and forgetting.
Without forgetting, your memory store becomes an archaeological site. Everything is preserved; nothing is reliably current.
How Memory Failures Show Up in Production (and How to Debug Them)
The fastest way to debug agent memory is to stop looking first at the final answer.
Inspect the memory pipeline.
When a user says, "I told you this already," I want a trace showing what existed before the turn, which memories were searched, which candidates were returned, which were inserted into context, what the model saw, and what the write path did afterward.
Production symptom | Likely failure layer | First thing to inspect |
Agent forgets known preference | Write or retrieval | Was the preference persisted and returned? |
Old fact overrides new fact | Update/temporal layer | Was old memory invalidated? |
Correct memory exists but ignored | Ranking/context assembly | Did it enter the final prompt? |
Wrong user's information appears | Namespace/identity | Tenant and user filters |
Agent becomes slower over months | Retrieval/index growth | p50/p95 search and candidate count |
Memory store explodes | Extraction policy | Write rate, duplicates, summarization |
Agent confidently cites false history | Extraction/provenance | Original evidence and transformation logs |
Your observability events should include memory IDs, namespace, retrieval score, source timestamp, ranking position, token contribution, search duration, write operation, and any memory IDs superseded during the turn.
I also recommend four memory-specific production metrics:
Recall rate: did the required memory appear?
Precision: how much retrieved material was actually relevant?
Freshness correctness: did current truth outrank superseded truth?
Memory latency: how much of end-to-end response time came from retrieval and memory management?
Fountain City's production guide recommends tracking retrieval hit rate, token usage, latency, and memory growth from the beginning. That monitoring should be paired with conversation-level test cases where the expected memory state is known.
This is where memory engineering meets evaluation engineering. Refonte's guide to LLM evaluation pipelines for AI engineers is the complementary discipline: your general evaluation pipeline should be extended with tests that isolate memory formation, memory retrieval, stale-memory rejection, and cross-session continuity.
Recent research is also moving in this direction. The 2026 MemGym work argues that realistic agent evaluation needs to separate memory performance from reasoning, tool use, and other capabilities so engineers can determine which subsystem actually failed.
That distinction is critical.
Otherwise, teams see a bad final answer, blame "the LLM," switch models, and leave the actual memory defect untouched.
Memory and the Agentic AI Failure Rate: Connecting the Dots
We should not make a causal claim that the evidence does not support.
Gartner did not say "40% of projects will be cancelled because their memory systems are bad." Forbes' July 2026 treatment instead emphasizes governance, data access, ownership, ROI, cost, and deployment discipline.
Deloitte likewise points to a major gap between experimentation and production deployment rather than identifying memory as a single dominant cause.
The engineering connection is that memory sits underneath several of those production problems.
Enterprise scaling problem | Memory-layer manifestation |
Escalating cost | Excess context injection, expensive extraction, graph construction |
Poor data access | Memory cannot reconstruct state the agent never receives |
Governance | Persistent agent memory becomes governed enterprise data |
Reliability | Wrong/stale memory changes future actions |
Integration complexity | Identity and state must survive system boundaries |
Weak observability | Teams cannot explain why a memory was retrieved |
Unclear ROI | Slow or unreliable continuity destroys expected automation gains |
In other words, memory does not replace the organizational explanation. It gives engineers a specific architectural subsystem where several of the production problems become measurable.
This also explains why a demo can pass while the eventual system fails.
A demo can survive without long-term memory because the relevant facts have not had time to become old, contradictory, distributed across sessions, or expensive to retrieve. Production eventually forces all four conditions.
What Would Have to Change to Move the 11-14% Success Rate
First, remember that Deloitte's 11% and 14% are not one standardized "success-rate range." Eleven percent were actively using agentic systems in production, while 14% had solutions ready for deployment.
To improve those numbers, memory engineering would need to mature alongside the rest of production architecture:
Durable state should be part of the initial design, not a post-pilot feature.
Temporal semantics should become normal, so outdated facts can be superseded without deleting history.
Memory SLOs should exist, including retrieval p95, precision, recall, freshness, and availability.
Memory governance should match data governance, including tenant isolation, retention, provenance, correction, and deletion.
Teams should evaluate cross-session tasks, not just one-shot reasoning benchmarks.
Memory write paths should be observable, so engineers can explain why a fact exists.
Cost should be measured per useful remembered fact, not merely by total context-window capacity.
The ICLR-era research direction supports this broader evaluation shift: long-horizon memory benchmarks increasingly test incremental multi-turn interactions rather than isolated recall questions.
That is the standard production engineering needs.
The question is no longer "Can the model answer this?" It is "Can this system answer correctly after the relationship has lasted six months and the truth has changed five times?"
Skills Agentic AI Engineers Need for Memory Architecture in 2026
This is why agentic AI engineer skills 2026 are moving well beyond prompt design.
A production agent engineer needs to understand the interface between LLM behavior, databases, retrieval, distributed state, temporal data, observability, latency, evaluation, and governance.
Skill | What competence looks like |
Memory taxonomy | Distinguishing working, session, semantic, episodic, procedural, and relational memory |
Persistence architecture | Knowing when to use checkpoints, SQL, vector stores, graphs, or memory services |
Retrieval engineering | Embeddings, filtering, ranking, reranking, top-k and relevance |
Temporal modeling | Supersession, validity intervals, provenance and historical truth |
Context engineering | Choosing what actually enters the model window |
Latency engineering | Measuring p50/p95 and separating read/write paths |
Evaluation | Testing recall, precision, freshness and cross-session consistency |
Observability | Tracing memory from ingestion through retrieval |
Privacy/governance | Scoping, retention, deletion and tenant isolation |
Framework implementation | Building these patterns inside LangGraph, LangChain or equivalent stacks |
This is also the difference between being able to assemble an agent demo and being able to own an agent platform.
For engineers planning that career transition, Refonte's guide on how to become an agentic AI engineer in 2026 covers the broader role. Memory architecture should sit alongside tool use, orchestration, APIs, evaluation, deployment, and safety rather than being treated as a small RAG feature.
The 2026 research landscape supports that framing. Du's memory survey treats latency budgets, contradiction handling, privacy, consolidation, and retrieval as first-class engineering concerns, while Mem0, Zep, LangMem, and Letta represent materially different answers to those concerns.
The strongest engineers will not memorize which library won somebody else's benchmark.
They will be able to say: This workload requires user-level semantic memory, session recovery, 500-millisecond retrieval p95, explicit supersession semantics, audit provenance, and asynchronous consolidation; therefore this architecture fits, and here is the evaluation proving it.
That is an engineering skill.
Building This Expertise: The Refonte Learning Agentic AI Engineer Program
Refonte Learning's live Agentic AI Engineer program page already places memory in the correct broader context: the public curriculum explicitly includes "Memory & State Management for AI Agents" alongside agent architecture, tool calling, multi-agent orchestration, RAG, API integration, evaluation and observability, production deployment, and AI safety.
The public page does not currently name Mem0, Zep, LangMem, or Letta specifically. This article should therefore be read as a practical, tool-level extension of that memory-management competency, not as a claim that all four products are explicitly taught in the syllabus.
Program detail | Verified live-page information |
Format | 3 months |
Weekly commitment | 12–14 hours/week |
Early curriculum | Introduction to Agentic AI; Tool Use & Function Calling; Building Your First Agent with LangChain and LangGraph |
Memory curriculum | Memory & State Management for AI Agents |
Additional skills | RAG, API integration, evaluation/observability, deployment, safety |
Tools | LangChain, LangGraph, AutoGen, Claude API, OpenAI APIs, Pinecone, Chroma |
Mentor | Dr. John Anderson |
Mentor experience | 17 years in AI engineering; expertise includes agentic architecture and multi-agent orchestration |
One-time fee | USD 300 |
Installments | USD 204 + USD 98 |
Admission requirement | Public page currently states working toward a bachelor's or higher-level degree |
Python | Basic Python and LLM familiarity described as helpful |
Career outcomes listed | Agentic AI Engineer, AI Systems Engineer, LLM Engineer, AI Developer, Prompt & Agent Architect |
These details come from the program page as it appeared on August 17, 2026. It lists the program as three months at 12–14 hours per week, names the relevant career outcomes, explicitly includes memory and state management among the competencies, and describes Dr. John Anderson as having a 17-year AI career with experience in agentic architecture and production AI systems.
The current page lists a USD 300 one-time enrollment cost, with installment amounts of USD 204 and USD 98. It also displays USD 387 alongside the discounted USD 300 listing.
Refonte additionally advertises "$130K+ Starting" for the Agentic AI Engineer career path on the program page. That is Refonte Learning's own marketing claim and should not be interpreted here as an independently verified salary benchmark.
The reason this curriculum matters is that memory architecture forces you to connect skills that are often taught separately:
LangGraph state is not the same thing as long-term user memory.
RAG is not automatically agent memory.
A vector database does not by itself solve temporal truth.
A large context window does not provide durable continuity.
High benchmark recall is not sufficient if p95 retrieval destroys the product experience.
Persistent memory is not production-ready until it can be inspected, corrected, invalidated, governed, and evaluated.
The AI agent memory systems 2026 landscape makes those distinctions impossible to ignore.
Mem0 demonstrates the value of extracting and reconciling salient memories instead of replaying history. Zep makes temporal truth and evolving relationships architectural primitives. LangMem shows what memory looks like when integrated deeply into LangGraph's programming model. Letta pushes the idea further by giving a persistent agent responsibility for managing portions of its own context.
None is universally "best." The benchmarks themselves tell us not to think that way: Mem0's paper reports one set of token and latency advantages, Zep publicly disputes aspects of the competitor-run evaluation, LangMem's alarming near-60-second p95 comes from one particular benchmark configuration, and Letta does not even have an apples-to-apples result in that comparison.
The production question is therefore not which memory framework wins?
It is:
What must this agent remember, for whom, for how long, with what temporal semantics, at what latency, under what governance rules, and how will we prove that it still remembers correctly six months from now?
That is the memory problem behind the 2026 agent scaling gap. It is also exactly the kind of architecture problem an aspiring production engineer should learn to solve through the Refonte Learning Agentic AI Engineer Program, where memory management sits alongside the other skills required to move an agent from a convincing demo to a system that can actually survive production.