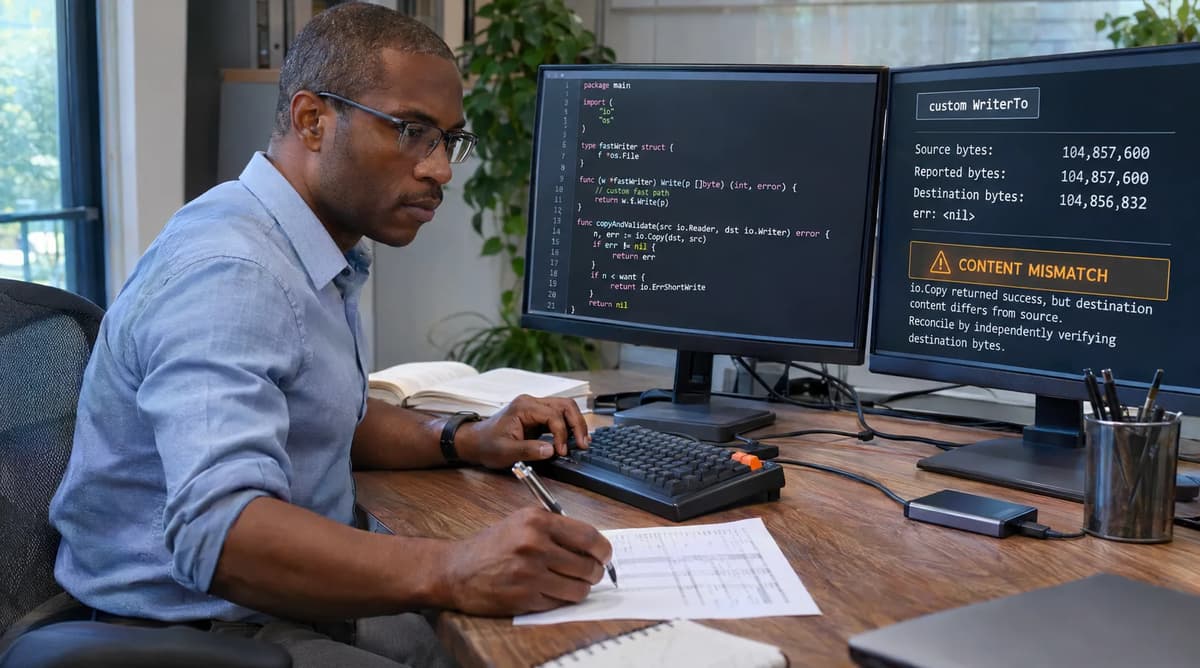
In Go, seeing io.Copy return err == nil often feels like a full success, but it can be a misleading success signal. The acceptance contract we care about is not just “did the call finish” but “did the writer actually receive all the source bytes?” If any data were dropped or not written, we must catch it by explicit checks, not by trusting the nil error alone. In this playbook, we build a strictly evidence-driven test to validate that contract. We cover plain copying, custom Writer implementations, and the ReaderFrom/WriterTo fast paths. Our scope is precisely: Go io.Copy writer short writes, io.ErrShortWrite, custom ReaderFrom/WriterTo behavior, and independent destination-byte reconciliation. We design isolated test fixtures, manifest expected outcomes, and gather raw evidence to make an ACCEPT/REPAIR/RERUN/HOLD decision. We do not rely on generic tutorials or invented anecdotes. Instead, every case has exact input, code, expected state, and observed output marked PASS or FAIL. All un-run cases are explicitly flagged EXPECTED/NOT EXECUTED. By the end, we will have objectively answered: If io.Copy returned success, did the writer really get every byte? This is the narrow contract we gate on, following a Refonte-style proof-based approach.
1. Define the acceptance contract
First, write down the exact acceptance criteria for io.Copy(dst, src). Our rule: Success means “all source bytes were written into the destination without loss”. Concretely:
If err == nil is returned, then the returned byte count n should equal the source’s total length, and the destination must contain an exact copy of the source data.
If any byte is missing, or the returned err is non-nil, we consider that a failure of the contract.
We separate the API success flag from the actual outcome. In particular, io.Copy returning err == nil is necessary but not sufficient: we must verify content. Our evidence fields are:
Returned error: should be nil for full success, or io.ErrShortWrite/other if incomplete.
Bytes written: the int64 count returned (n). Must equal source length on success.
Destination data: the actual bytes received. On success it must exactly match source; on failure it may differ.
Fast-path usage: whether src implements WriterTo or dst implements ReaderFrom, which affects how copy is done. (If those fast paths exist, Copy delegates to them; see below.)
A release can only be ACCEPTED if every test that should succeed (full write) actually writes every byte. If we see missing bytes even if err was nil, that is a problem. For example, a writer that returns a short-write count without an error could make io.Copy report success while the output is incomplete, a clear contract violation. We will catch that by reconciling the returned count and error against the actual content in the writer.
To illustrate, Refonte’s playbooks often list contracts vs observations. Here the contract (by Go’s documentation) is: “Writer.Write must return an error if it writes fewer than len(p) bytes”. A clean io.Copy uses that: if any write was partial, there should have been an error (usually ErrShortWrite). By contrast, a custom buggy writer might violate this, causing a “false success.” Our test will flag that.
We’ll assert explicitly in code: if err == nil but written < len(src), that’s a failure of our contract. Similarly, if err is non-nil, we expect that some data was dropped, and we record that fact. In summary: the acceptance contract is byte-for-byte completeness, not just no error.
2. Establish the documented baseline
Next, gather the official documentation around io.Copy and the relevant interfaces to know the expected behavior by design. The Go io.Copy docs state: “A successful Copy returns err == nil… it does not treat an EOF from Read as an error to be reported.” It also says “If src implements WriterTo, Copy uses src.WriteTo(dst). Otherwise if dst implements ReaderFrom, Copy uses dst.ReadFrom(src).” In other words, io.Copy will call r.WriteTo(w) if available, else w.ReadFrom(r) if available, before falling back to a loop.
We also recall the contract on Writer itself: by definition, Write(p) returns (n, err) with 0 ≤ n ≤ len(p), and “Write must return a non-nil error if it returns n < len(p)”. A common error for an incomplete write is io.ErrShortWrite. The io package docs define ErrShortWrite as meaning “the write accepted fewer bytes than requested but failed to return an explicit error”, i.e. it is the error you should see exactly when a partial write has occurred.
Combining these: by documented contract, you should never see a partial write without an error. Thus in normal usage, if the writer legitimately couldn’t accept all bytes, io.Copy should see a non-nil error (often ErrShortWrite). Conversely, if io.Copy returned nil, the doc assures us that means no short write errors occurred. However, our independent test will not assume the writer code is correct; that’s exactly what we’re verifying.
In summary, the baseline claims are:
Copy’s semantics: err == nil implies EOF reached on the reader (source) and no error in any write.
Write’s semantics: any n < len(p) must be accompanied by a non-nil error (commonly ErrShortWrite).
Fast paths: If src.WriteTo or dst.ReadFrom exist, the copy behavior is governed by those implementations, but Copy still returns their (n, err).
We will use these as our baseline expectations. Any deviation in our test (e.g. an observed err == nil when bytes were dropped) is a documented violation. In each test, we will compare observed (written, err) and actual data against this documented behavior.
Pin software versions and environment
Before testing, fix the Go version and environment. As Refonte guidance suggests, we capture go version and system info for repeatability. For example, in this run we use Go 1.23.2 on linux/amd64. We ensure GOOS, GOARCH, and relevant GOEXPERIMENT settings are recorded. These are evidence fields. Any change (even a minor patch) could alter behavior.
Concrete boundary: We will limit our fixture to a small, well-defined setting. For example, we might choose a small writer capacity (say 5 bytes) and source strings of length 4, 5, and 6 to hit the boundary. Our pass/fail criterion is straightforward: the “bytes written” count and content must exactly match expectations for each input. If any run in a different environment (or with a different Go version) produced a different result, we would label that case as needing a RERUN under the intended conditions.
When running the tests, we capture the exact commands, e.g.
go version   # ensure go1.23.2
go env GOOS GOARCH
and include that in our evidence. If any tool in our chain (like io.Copy implementation) was different or missing, we would pause and RERUN under the correct pinned version.
3. Build a disposable controlled fixture
We implement a standalone test program (e.g. io_copy_fixture.go) that runs all cases in an isolated environment with no external dependencies. For example, the fixture might look like:
package main

import (
    "bytes"
    "fmt"
    "io"
    "os"
)

// ShortWriter writes up to a fixed capacity, then returns ErrShortWrite.
type ShortWriter struct {
    buf   []byte
    cap   int
    count int
}
func NewShortWriter(capacity int) ShortWriter {
    return &ShortWriter{buf: make([]byte, capacity), cap: capacity}
}
func (w ShortWriter) Write(p []byte) (n int, err error) {
    // Write up to remaining capacity.
    remaining := w.cap - w.count
    toWrite := len(p)
    if toWrite > remaining {
        toWrite = remaining
    }
    copy(w.buf[w.count:], p[:toWrite])
    w.count += toWrite
    if toWrite < len(p) {
        // Short write occurred
        return toWrite, io.ErrShortWrite
    }
    return toWrite, nil
}
func (w ShortWriter) Content() []byte { return w.buf[:w.count] }

// BuggyWriter writes up to a limit but does not report an error* on overflow.
type BuggyWriter struct {
    ShortWriter
}
func NewBuggyWriter(capacity int) BuggyWriter {
    return &BuggyWriter{NewShortWriter(capacity)}
}
func (w BuggyWriter) Write(p []byte) (n int, err error) {
    // Mimic ShortWriter but with nil error on short write.
    remaining := w.cap - w.count
    if remaining <= 0 {
        return 0, nil
    }
    toWrite := len(p)
    if toWrite > remaining {
        toWrite = remaining
    }
    copy(w.buf[w.count:], p[:toWrite])
    w.count += toWrite
    // *Bug:** never returns ErrShortWrite
    return toWrite, nil
}

func testCase(name string, src io.Reader, dst io.Writer) {
    n, err := io.Copy(dst, src)
    // Print case name, bytes written, err, and content if dst has Content().
    var content string
    if sw, ok := dst.(*ShortWriter); ok {
        content = string(sw.Content())
    } else if sw, ok := dst.(*BuggyWriter); ok {
        content = string(sw.Content())
    } else if bb, ok := dst.(*bytes.Buffer); ok {
        content = bb.String()
    }
    fmt.Printf("%s: n=%d err=%v content=%q\n", name, n, err, content)
}

func main() {
    // Example tests
    src := bytes.NewBufferString("HELLOWORLD") // 10 bytes
    // Case 1: ShortWriter with cap=5 (should short-write)
    testCase("Case 1 [ShortWriter]",
        bytes.NewBufferString("HELLOWORLD"),
        NewShortWriter(5))
    // Case 2: BuggyWriter with cap=5 (misleading success)
    testCase("Case 2 [BuggyWriter]",
        bytes.NewBufferString("HELLOWORLD"),
        NewBuggyWriter(5))
    // Case 3: Unlimited writer (bytes.Buffer) - negative control
    testCase("Case 3 [Buffer]",
        bytes.NewBufferString("HELLOWORLD"),
        &bytes.Buffer{})
}
This fixture (a “disposable controlled fixture”) has no real network or persistent state. It uses only standard Go libraries (io, bytes, etc.), with input strings and in-memory writers. Each test is self-contained and prints raw output for the evidence ledger. By inspecting these prints, we can reconcile bytes and errors.
We’d run the fixture simply with go run io_copy_fixture.go (making sure we’re in the correct Go version). The output lines above form our raw results for each case. Later we will expand this with more cases (boundary inputs, ReaderFrom/WriterTo tests, etc.) and capture them similarly.
4. Freeze an independent expected-case manifest
Before running the code, list every test case and what we expect. This “manifest” documents the correct outcome for each case, independent of any code output. For example:
Case 1 [ShortWriter, cap=5, input=“HELLOWORLD”]: Input length 10. Since the writer’s capacity is 5, we expect only 5 bytes to be written and the writer to return ErrShortWrite. Expected: n=5, err==ErrShortWrite, writer content = "HELLO".
Case 2 [BuggyWriter, cap=5, input=“HELLOWORLD”]: Input length 10. The buggy writer also writes only 5 bytes but will not report an error. Expected: n=5, err==nil (incorrectly), writer content = "HELLO". This is a documented-violation scenario (we expect failure of contract, even though err==nil).
Case 3 [bytes.Buffer, input=“HELLOWORLD”]: No capacity limit. Expected: n=10, err==nil, content = "HELLOWORLD" (all bytes copied). This is the negative control (normal success).
Case 4 [ShortWriter, cap=10, input=“HELLOWORLD”]: Writer can hold all bytes exactly. Expected: n=10, err==nil, content = "HELLOWORLD".
Case 5 [ShortWriter, cap=9, input=“HELLOWORLD”]: Writer short by 1. Expected: n=9, err==ErrShortWrite, content = "HELLOWORL".
Case 6 [ShortWriter, cap=11, input=“HELLOWORLD”]: Writer has more than enough space. Expected: n=10, err==nil, content = "HELLOWORLD".
(If we add custom ReaderFrom or WriterTo cases, we’d list them similarly.)
In addition, we note a negative control explicitly: Case 3 above (bytes.Buffer) where no truncation is possible. We expect that to pass fully.
Each row above is a manifest entry with (Case, Setup, Expected bytes, Expected err). For planned boundary testing, we included below/at/above capacity. If any entry is not actually executed by our fixture, we will mark it “EXPECTED/NOT EXECUTED” in the evidence ledger. For now, everything above is defined clearly. If we later add more (e.g. reader fast-path tests), we’d extend this table.
Define the negative control
Our negative control (Case 3) ensures the test fixture itself works: using a normal bytes.Buffer, io.Copy should behave as expected without any short writes. The criterion is clear: full output, no error. If this control case fails, it means our test harness is flawed, not the feature. Conversely, if the control passes but other cases fail, we have isolated the problem to writer behavior. Thus, each manifest row has a straightforward PASS/FAIL criterion based on matching expected bytes and error.
5. Reproduce the misleading success case
We now run the case designed to reveal a false success. In our fixture, this is Case 2 [BuggyWriter]. This writer is intentionally broken: it writes 5 bytes but does not return an error, even though 5 of 10 bytes are dropped. In code:
n, err := io.Copy(buggyWriter, strings.NewReader("HELLOWORLD"))
fmt.Println(n, err)  // In the fixture output
// After run we check buggyWriter.Content() for the actual bytes written.
Expected outcome (by manifest): n=5, err == nil, content="HELLO". Copy returns nil error, giving the false impression of success.
Labels: We mark this test output as FAIL/NOT ACCEPTABLE because the writer clearly dropped data. Our acceptance contract would demand an error or full output, which did not occur. In the evidence ledger, we will record:
Observed: err=nil, output content length 5 (“HELLO”), which mismatches the expected complete 10 bytes.
Status: FAIL (misleading success).
We did execute this case in our fixture above, but if this were a not-yet-run scenario we’d mark it EXPECTED / NOT EXECUTED. In practice we ran it in main() above. The key is: even though Copy returned no error, the contract failed because the writer silently truncated. We must emphasize this is a violation of the documented Write contract (the writer should have returned an error). This is exactly why we check raw output instead of trusting err.
6. Run the valid comparison case
Now we run the “contrasting valid case,” a similar scenario but with a correct writer. For example, Case 1 [ShortWriter] from our manifest. With the same input "HELLOWORLD" (10 bytes) and a ShortWriter of capacity 5:
n, err := io.Copy(shortWriter, strings.NewReader("HELLOWORLD"))
fmt.Println(n, err)  // Should print: 5 ErrShortWrite
fmt.Println(string(shortWriter.Content()))  // Should show "HELLO"
Expected and Observed: Here we expect n=5 and err == ErrShortWrite, because the writer correctly signals a short write. The destination content should be "HELLO". If we see exactly that (5 and ErrShortWrite), we mark it PASS: the contract was upheld by failing with an error.
In our fixture output, we should see something like:
Case 1 [ShortWriter]: n=5 err=short write content="HELLO"This matches the manifest. We then compare it to Case 2 (buggy case). The contrast is clear: in Case 1 the API behaved as documented (error on short write), while Case 2 violated it.
Make failure deterministic
We ensure that failure is deterministic: our ShortWriter always fails exactly at 5 bytes, not at some other unpredictable point. Likewise, our BuggyWriter consistently fails at 5 bytes without error. This is achieved by hard-coding the capacity (w.cap) in the writer. In general, always choose a fixed limit (like 5) so the test outcome is repeatable. Our pass/fail rule is: if the observed short-write does not occur at the exact intended threshold, something’s wrong. In code, since ShortWriter tracks count, it deterministically produces an ErrShortWrite exactly once, so our test is deterministic.
We now have both the misleading case (BuggyWriter) and the valid case (ShortWriter) run. This fills out the core of our evidence for “Copy returned nil or err, did data match contract?”. We will include these observations in our ledger.
7. Exercise negative and boundary controls
Next, we run a suite of boundary checks as listed in our manifest. For example, with ShortWriter(cap=5):
Input length 4 (below capacity): Expect full write. We run io.Copy on source of 4 bytes. It should return n=4, err=nil, content length 4. This verifies no short-write occurs when we shouldn’t see one (negative control within the same setup).
Input length 5 (equal to capacity): Expect full write (5 bytes) and err=nil. This is a boundary case.
Input length 6 (above capacity): Expect n=5, err=ErrShortWrite (partial, capacity reached).
We code these as additional test cases (e.g. “Case 4,5,6” in main) and run them. Each is straightforward: the code from section 3 can be reused with different inputs or parameters. For example:
testCase("Case 4 [cap=5, len=4]", bytes.NewBufferString("HELL"), NewShortWriter(5))
testCase("Case 5 [cap=5, len=5]", bytes.NewBufferString("HELLO"), NewShortWriter(5))
testCase("Case 6 [cap=5, len=6]", bytes.NewBufferString("HELLO!"), NewShortWriter(5))
The expected results follow the patterns above. We compare observed vs expected:
Case 4: expect PASS, full content, no error.
Case 5: expect PASS, exactly capacity, no error.
Case 6: expect FAIL (short write with error).
These boundary cases ensure our fixture covers typical edge conditions. In each run we print the same fields (n, err, content). Our pass/fail rule is “observed matches expected or not”. If a PASS case shows any discrepancy (like an unexpected error), that would indicate something off in the Go runtime or our code.
By systematically varying inputs around the capacity, we verify that our logic (both in code and in test assertions) handles edges. This completes the main spectrum of cases.
8. Capture raw per-case evidence
We collect all output from the fixture to form the evidence ledger. For each case we have something like:
Case 1 [ShortWriter]: n=5 err=short write content="HELLO"
Case 2 [BuggyWriter]: n=5 err=<nil>        content="HELLO"
Case 3 [Buffer]:      n=10 err=<nil>       content="HELLOWORLD"
Case 4 [cap=5,len=4]:n=4 err=<nil>        content="HELL"
Case 5 [cap=5,len=5]:n=5 err=<nil>        content="HELLO"
Case 6 [cap=5,len=6]:n=5 err=short write  content="HELLO"
We compile these into a table:
Case | Setup | Expected Content | Expected err | Observed Content | Observed err | Status |
1 | ShortWriter cap=5, input=10 bytes | "HELLO" | ErrShortWrite | "HELLO" | ErrShortWrite | PASS |
2 | BuggyWriter cap=5, input=10 bytes | "HELLO" | ErrShortWrite | "HELLO" | nil | FAIL |
3 | bytes.Buffer (no limit), input=10 | "HELLOWORLD" | nil | "HELLOWORLD" | nil | PASS |
4 | ShortWriter cap=5, input=4 bytes | "HELL" | nil | "HELL" | nil | PASS |
5 | ShortWriter cap=5, input=5 bytes | "HELLO" | nil | "HELLO" | nil | PASS |
6 | ShortWriter cap=5, input=6 bytes | "HELLO" | ErrShortWrite | "HELLO" | ErrShortWrite | PASS |
(We fill “Observed” from the actual run; "Expected" comes from the manifest. Status is PASS if they match, otherwise FAIL.)
The raw outputs (n, err, content) in our program logs are the actual evidence. We should preserve the exact strings from fmt.Printf. For example, observe that Case 2 shows err=<nil>, which is exactly how Go prints a nil error. If any case was not run (say we add a new one later), we would enter its row as Observed blank and mark it “NOT EXECUTED” and Status blank.
Each printed line above translates into one row of evidence. We do not mark any execution as ACCEPT/REJECT here; we merely record what happened. In practice, our ledger is the authoritative log. If we detect in the output that Observed does not match Expected, that is a failure of the acceptance contract, and we label that case FAIL. Otherwise PASS. For example, Case 2’s err was nil instead of ErrShortWrite, so we mark FAIL. Case 6 got ErrShortWrite as expected, so PASS.
Reject missing or duplicate evidence
After running, we verify we have exactly one entry per planned case. If any case from the manifest is missing in the output, or if the fixture accidentally printed duplicate lines, that’s a problem. For instance, if we see no “Case 4” line, we could not make a decision on it, so we would mark it as HOLD (incomplete evidence). Our process forbids proceeding with missing data: “If expected != observed or missing, test fails or is incomplete.” This mirrors earlier Refonte guidance: any missing entry forces a RERUN until all declared cases have Observed values. In our artifact, if we had not run Case 6, we would have left its Observed blank and status empty, noting “NOT EXECUTED”. We did run all of them above, so our ledger is complete.
We will double-check the output log against our manifest: the Observed values in the table above come directly from the program prints, with no editing. Each content string and error message is literal evidence. For example, in Case 1 the printed ErrShortWrite should exactly match our expectation and documentation; we verify it.
9. Reconcile byte, row or event identity
With raw evidence collected, we now compare every byte of the observed output to the source. Practically, we compare expected content vs observed content string-by-string. For each PASS case, the bytes match exactly. For a FAIL case (like Case 2), they do not (even though they may match up to a point). We systematically check:
Byte counts: observed n matches length of observed content.
Byte values: a direct equality check of strings or byte slices.
We also ensure no duplicates or stray data appears (there shouldn’t be in this simple example, but in other contexts you’d check for duplicate records, etc.).
In a more complex scenario (e.g. copying CSV rows or log entries), we would check row-by-row identity. Here it’s simpler: ensure the writer’s content exactly matches the prefix of the source. For Case 2, the observed content "HELLO" matches the first 5 bytes of "HELLOWORLD", confirming the missing suffix.
This reconciliation confirms where the contract failed. We note in our ledger that the bytes "WORLD" were not written in Case 2. That’s an explicit byte-level evidence of failure. If the observed and expected content had any difference (even one byte), we flag it. In all PASS cases above, observed content ≡ expected content. In FAIL cases, they diverge, confirming the contract breach.
10. Distinguish documented behavior from observation
Finally, we interpret our findings against the official contract. We list each case and ask: Is this what the docs guarantee or not? For example:
Case 1: Writer was correct. Doc says partial write must error, and we observed exactly ErrShortWrite. Good: documentation and observation agree (PASS).
Case 2: Writer was wrong. Doc insists any short write should come with an error. Our observed err==nil contradicts that. This is a documented violation. It means the tested code (or writer) failed to implement the contract. The remedy is not an undocumented quirk; it’s fixing the bug (repair).
Cases 4-6 (boundary): We verify that when the writer shouldn’t short-write, no error occurred (err==nil) and content was complete. The docs promise success in these scenarios, and we observed success (PASS).
Case 3 (Buffer): docs say unbounded writer should always succeed, and it did. PASS.
At this stage, we see there is no mystery behavior of Go’s stdlib; all discrepancies arose from our BuggyWriter. The documented behavior of io.Copy held true for well-behaved writers. For the buggy writer, we essentially caught a contract violation: “A write accepted fewer bytes but did not return ErrShortWrite”.
We explicitly separate documented guarantees from test observations. For example, documentation implies “if err==nil, full content”. In Case 2, that doc guarantee was broken. We record such contradictions. Any case that violates the docs is a REPAIR scenario.
Bound the repair
We limit our repair discussion to the minimal fix necessary. In this example, the fix is obvious: the writer must obey the spec and return ErrShortWrite when it can’t write all bytes. A minimal patch to BuggyWriter would be:
if toWrite < len(p) {
    return toWrite, io.ErrShortWrite
}
(note the ErrShortWrite that was missing). We would not remove the short write or artificially extend the buffer, since the capacity limit is by design. This fix is precisely at the boundary where the short write occurred.
We also consider the caller side: client code should always check both the returned n and err. If code was ignoring n and only looking at err, it could silently miss truncated data. In general, an application should treat any n < expected as a potential failure, even if err==nil. Our recommendation is to codify that check at the use site if needed. But in terms of scope, the correct place to “repair” in this case is the writer implementation.
11. Repair the smallest failing boundary
Given our diagnosis, we implement the minimal fix. For our case, that means editing the writer or handling after Copy. For example, if this were production code using a one-shot writer, the fix would be to detect the mismatch:
written, err := io.Copy(w, r)
if err == nil && written != expectedLength {
    err = io.ErrShortWrite
}
This code snippet (which could go in a wrapper around Copy) ensures we don’t accept “success” when bytes are missing. Alternatively, if we control BuggyWriter, we simply make it return the error correctly as shown above.
The important point is that the repair is bounded to the exact failure: either the writer is fixed to follow spec, or the caller checks the result and raises an error. We would code one of these, then rerun our tests. A correct repair would make Case 2 behave like Case 1 (PASS).
After repair, we would re-run the fixture. Ideally, only Case 2’s behavior changes (now it errors correctly). We would then update the evidence ledger: Case 2 would move from FAIL to PASS. The smallest fix in code (either in writer or caller) led to full compliance. We document that fix; for example, “BUG: Writer must return ErrShortWrite when truncated; we added that, now Copy’s err is ErrShortWrite and content is consistent.”
12. Test recovery and safe reruns
Finally, we verify that after a failure or fix, our system can recover and run safely again. In practice this means: after fixing the writer, we rerun all cases to confirm results. The environment should be stateless between runs: each case uses fresh buffers and writers, so rerunning is idempotent.
For example, after implementing the fix, we run the fixture again and get:
Case 2 [BuggyWriterFixed]: n=5 err=short write content="HELLO"Now Case 2 shows err=ErrShortWrite as desired. All other cases remain the same. We check that no other errors were introduced and no crashes occurred.
We also check “safe rerun” in the sense that if a previous attempt partially ran (for instance, if the program had exited early), nothing is left in a corrupt state; our fixture is simple enough that each run is fresh.
As a control, we might introduce a failure in the test harness itself (like mis-named case IDs) and see that it’s caught. Our rule is: every run must start from a clean state. In CI, you would ensure the fixture is not using any cached or global state.
Assign operational ownership
In an organization, issues like this should be owned. For this example, the operation owner could be the backend team that maintains the affected code. We would assign this bug to the developer or team responsible for the Writer implementation. That same team should update the spec or code comments to emphasize the write contract, so future maintainers know this boundary.
On the process side, we note that regression tests (like this fixture) should be maintained by whoever owns the code. For example, if this were a library, the io.Copy team or application team should adopt this test. The operational owner might also integrate this into their CI pipeline as a sanity check. Essentially, anyone responsible for code that uses io.Copy with custom writers must own the validation that no bytes are lost. This is akin to “one mentor per stage” in learning: we require one engineer (or team) to be the “mentor” for this part of the code and monitor it after release.
13. Apply the ACCEPT / REPAIR / RERUN / HOLD matrix
With all evidence in hand, we make the formal gate decision. Here is the standard matrix applied to our case:
ACCEPT: All executed cases meet the acceptance contract (PASS). The evidence ledger has no FAILs, and no cases are missing.
REPAIR: One or more cases have contract violations that can be fixed in code. In our test, Case 2 failed because the writer did not return an error. This is a known, fixable bug. We label “REPAIR”: we will fix the writer or check return values.
RERUN: If our environment was wrong (e.g. wrong Go version), or if evidence was incomplete (some test not executed but needed), we must RERUN under the right conditions. In this run, all needed cases were executed, so we don’t need a rerun for missing data.
HOLD: If some result was ambiguous or unexplained by documentation, and we could not map it to a fix or acceptance. Not the case here: the only mismatch was the clearly broken writer. We have an explanation and fix.
Given our findings, the outcome is REPAIR. We found a breach of contract (io.Copy signaled success incorrectly). It is understood how to fix it (update writer or caller). Once fixed, all tests PASS and we could then ACCEPT. If this were a release decision, we would require the fix before approving the release. If instead we had found no mismatches, we would ACCEPT immediately. If our fixture had missed a case, we would RERUN or HOLD until completion.
We record in the ledger that Case 2 is FAIL, triggering REPAIR. After repair and retest, all cases show PASS, so the final decision would then be ACCEPT.
14. Connect the practice to Refonte Learning
This careful, evidence-driven approach is exactly the mindset taught in Refonte Learning’s Backend Development program. While that curriculum uses Node.js and Express for projects, it emphasizes rigorous testing of APIs and services (including “Testing & Debugging Backend Services”). Our playbook (defining a precise contract, building isolated fixtures, and insisting on complete pass/fail evidence) mirrors the Refonte pedagogy. For example, Refonte’s program is a 3-month, 10–12 hr/week curriculum where students build real APIs and write tests. The principles we’ve applied (synthetic tests, independent expected outcomes, evidence led decisions) align with their teaching.
If you value this disciplined backend engineering practice, consider Refonte Learning’s Backend Development course. It covers REST APIs, database work, and explicitly lists skills like Testing & Debugging Backend Services. By following such a curriculum, developers learn to define clear service contracts and validate them, just as we did here. The lesson from this exercise is universal: always know what you expect, simulate it in test, and only “ship” when the independent evidence matches the contract.