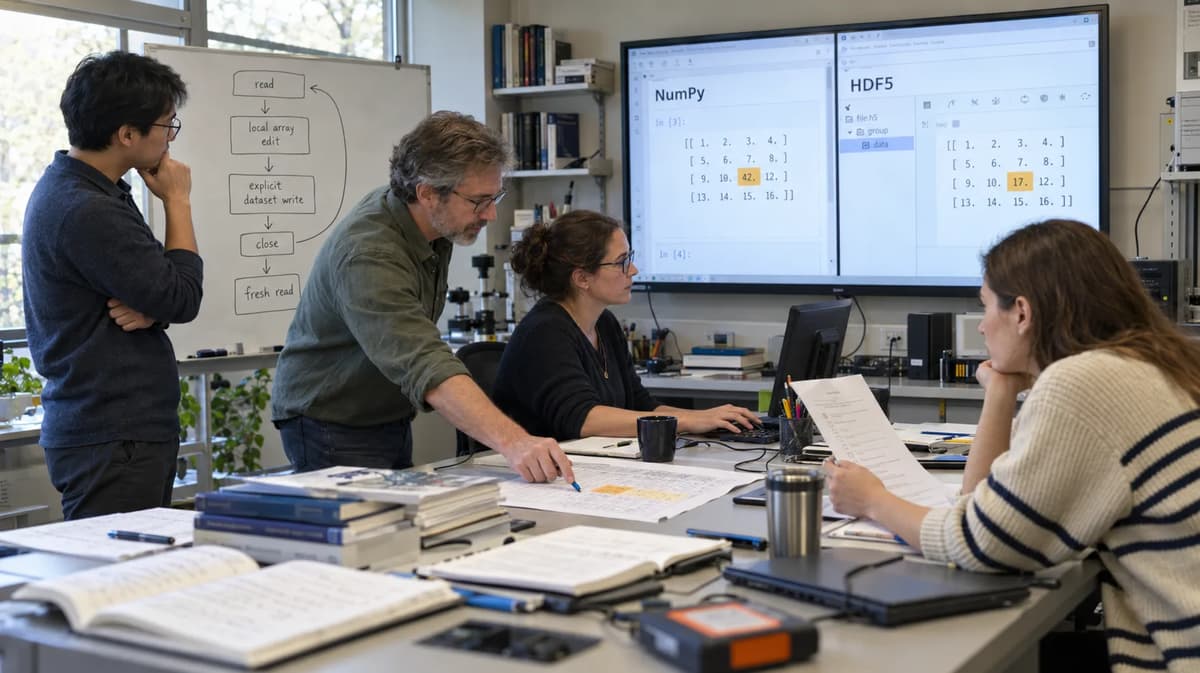
A row variable says 99. The HDF5 dataset, reopened from disk, still says 2. That contradiction is not evidence of a delayed flush, a mysterious cache, or an HDF5 write that vanished. In the common h5py failure examined here, the intended write was never submitted to the dataset at all.
The distinction is easy to miss because an h5py Dataset intentionally presents a NumPy-like indexing interface. But it is not a persistent NumPy array view. h5py documents that indexing a dataset loads data into memory, and specifically warns that an expression such as dset[0][1] = 3.0 modifies only the loaded array. To submit the write, the selection must reach the dataset assignment operation, for example dset[0, 1] = 3.0.
This playbook qualifies that boundary with one deliberately small fixture: Linux, CPython 3.13.5, h5py 3.15.1 linked to HDF5 1.14.6, NumPy 2.3.5, one owned temporary file per case, the ordinary local file driver, one writer, and a fixed 2×3 int32 dataset. Those runtime labels and the nine-case observations come from the preparation evidence supplied for October 23, 2026; they are not presented as a new execution performed for this article.
The operator’s decision is exact. Cell [0,1] must become 99; every other value, the shape, and the dtype must survive unchanged. Anything less is not an accepted write.
Define the exact cell update that must survive reopening
Start with the result contract, not the assignment syntax.
The baseline dataset is:
[[1, 2, 3],
 [4, 5, 6]]
The only approved result is:
[[1, 99, 3],
 [4,  5, 6]]
That means the acceptance oracle covers six cells, not merely the fact that one cell changed. It also covers shape (2, 3) and dtype int32. A process that changes exactly one value can still be wrong if it changes [1,0] rather than [0,1].
This is a small but important qualification habit. “A write happened” and “the intended state was produced” are separate questions. A successful API call, a nonzero difference count, or a plausible row variable does not establish coordinate-level correctness.
The same principle appears in other storage-validation work. HDF5 reads in a SAR workflow operate in a much broader scientific-data context; the narrower concern here is whether one specified mutation actually crossed the h5py file-backed dataset boundary. The h5py Dataset documentation for 3.15.1 describes datasets as homogeneous, rectangular collections exposed through a NumPy-like proxy rather than as ordinary in-memory ndarrays.
Write the oracle down before diagnosing the code:
BASE = np.array([[1, 2, 3], [4, 5, 6]], dtype=np.int32)
APPROVED = np.array([[1, 99, 3], [4, 5, 6]], dtype=np.int32)
The decision rule is correspondingly strict:
ACCEPT_WRITEBACK only when a fresh reader sees APPROVED, with the exact original shape and dtype.
That rule deliberately rejects an apparently healthy program whose local variable contains 99 while the reopened file does not. It also rejects a genuine HDF5 write made to the wrong coordinate. Storage qualification should test the externally observable state that matters, not the nearest convenient internal state.
Freeze the HDF5 file, dtype and writer ownership
Before debugging indexing, remove unrelated degrees of freedom.
Each case in this lab owns a newly created temporary directory and one file named owned.h5. The file first receives dataset /values from the fixed baseline array. It is then closed and reopened in r+ mode for the candidate operation. There is one writer. After that writer closes, a separate r handle performs the acceptance read.
That ownership model matters because this article is not attempting to diagnose concurrent-writer behavior, SWMR, MPI, object storage, crash recovery, or lost updates. Those require different evidence.
The h5py Quick Start Guide describes an HDF5 Dataset as a file-backed object with shape and dtype that supports array-style reading and writing; it is not itself the NumPy array returned by a read. The stable page consulted on October 23, 2026 displays h5py 3.16.0, so it is reference documentation rather than the measured 3.15.1 runtime in this fixture.
Likewise, h5py’s stable File Objects documentation currently identifies the default driver choice as the platform-appropriate standard HDF5 driver when driver=None; it also distinguishes r from r+, documents explicit closing, and defines flush() as a request for HDF5 to flush its buffers.
No alternate driver is introduced here. That is intentional. A driver change is a qualification change.
Keep shape and dtype fixed
The dataset is exactly two rows by three columns and contains int32 integers. Resizing, floating-point conversion, compression behavior, and chunk-layout optimization are excluded.
That prevents an indexing investigation from becoming a casting or storage-layout investigation. If a later implementation changes from int32 to another dtype, from contiguous to a different layout, or to another HDF5 driver, do not silently reuse this result as qualification evidence. The decision is RERUN.
The accepted readback therefore requires all three conditions simultaneously:
observed.shape == (2, 3)
observed.dtype == np.dtype(np.int32)
np.array_equal(observed, APPROVED)
The point is not that these parameters are universally correct. They are correct for this controlled case, which makes deviations observable rather than negotiable.
Create the independent baseline and readback harness
The strongest part of this fixture is not the assignment line. It is the observation boundary around that line.
Every case creates a clean baseline file, performs one candidate behavior, reads the dataset again through the still-open writer for diagnostic comparison, closes that writer, and only then opens an independent read-only handle. The reopened array is compared against the complete expected result.
The preparation recipe is:
python -m pip install "numpy==2.3.5" "h5py==3.15.1"
python hdf5_lab.py > hdf5-evidence.json
The installation command is the reproduction recipe, not a verified record of the command used during the preparation run. The preparation evidence records the installed package versions observed by the fixture.
The complete fixture is:
import hashlib
import json
import platform
import tempfile
from pathlib import Path

import h5py
import numpy as np

if not debug:
    raise RuntimeError('Run without -O; diagnostic assertions are required.')

BASE = np.array([[1, 2, 3], [4, 5, 6]], dtype=np.int32)
APPROVED = np.array([[1, 99, 3], [4, 5, 6]], dtype=np.int32)


def run(case, mode):
    with tempfile.TemporaryDirectory(prefix='hdf5-write-lab-') as tmp:
        path = Path(tmp) / 'owned.h5'
        with h5py.File(path, 'w') as f:
            f.create_dataset('values', data=BASE)
        local = None
        with h5py.File(path, 'r+') as f:
            ds = f['values']
            if mode == 'chained':
                ds[0][1] = 99
            elif mode == 'row_flush':
                local = ds[0]
                local[1] = 99
                f.flush()
            elif mode in ('combined', 'combined_flush'):
                ds[0, 1] = 99
                if mode == 'combined_flush':
                    f.flush()
            elif mode == 'writeback':
                local = ds[0]
                local[1] = 99
                ds[0] = local
            elif mode == 'iteration':
                for index, row in enumerate(ds):
                    if index == 0:
                        row[1] = 99
                        local = row
            elif mode == 'full_copy':
                local = ds[...]
                local[0, 1] = 99
            elif mode == 'wrong_coordinate':
                ds[1, 0] = 99
            elif mode != 'baseline':
                raise ValueError(mode)
            same_handle = ds[...].tolist()
        # A new read-only handle is opened only after the writer closes.
        with h5py.File(path, 'r') as observer:
            observed = observer['values'][...]
        expected = BASE.copy()
        if mode in ('combined', 'combined_flush', 'writeback'):
            expected = APPROVED.copy()
        elif mode == 'wrong_coordinate':
            expected[1, 0] = 99
        assert observed.dtype == BASE.dtype and observed.shape == BASE.shape
        assert np.array_equal(observed, expected), (case, observed)
        assert same_handle == observed.tolist()
        accepted = np.array_equal(observed, APPROVED)
        assert accepted == (mode in ('combined', 'combined_flush', 'writeback'))
        return {'case': case, 'mode': mode,
                'local_array': None if local is None else local.tolist(),
                'same_handle': same_handle, 'reopened': observed.tolist(),
                'approved_cell_contract': bool(accepted)}


if name == '__main__':
    modes = ['baseline', 'chained', 'row_flush', 'combined', 'writeback',
             'iteration', 'full_copy', 'wrong_coordinate', 'combined_flush']
    cases = [run(f'H{i}', mode) for i, mode in enumerate(modes, 1)]
    print(json.dumps({'python': platform.python_version(), 'numpy': np.__version__,
                      'h5py': h5py.__version__, 'hdf5': h5py.version.hdf5_version,
                      'source_sha256': hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
                      'cases': cases, 'status': 'PASS_9_CASES'}, indent=2))
The supplied preparation fixture is identified by SHA-256 9c17044697e98c43d341a0185bf73ad7bc25660b6965f650c1396d558c8c82f5. That digest identifies source bytes; it does not prove the source was executed correctly, authenticate an execution record, or prove the resulting HDF5 values.
The preparation evidence reports runtime labels CPython 3.13.5, NumPy 2.3.5, h5py 3.15.1 and HDF5 1.14.6, plus JSON status PASS_9_CASES. The preparation record does not include a separate shell exit status.
Do not reuse the writer as the final observer
A same-handle read is useful, but it is not the final acceptance boundary.
h5py’s file-closing documentation explains that leaving a with h5py.File(...) block closes the file and invalidates objects obtained from it; opening a new file in r mode creates a read-only access path. The fixture deliberately exploits that lifecycle: the writer is gone before the observer starts.
That sequence answers a precise question: after normal writer closure, what does a new reader see?
It does not establish crash durability after sudden power loss, filesystem fsync behavior, multi-process isolation, or SWMR visibility. Those questions are outside this test.
Reproduce the chained-indexing non-write
The failing expression is deceptively concise:
ds[0][1] = 99The essential operation boundary is between the two bracket pairs.
h5py’s version-specific documentation states explicitly that indexing a dataset once loads a NumPy array into memory. It gives the same multiple-indexing pattern and says that assigning through the second index has no effect on the dataset. Its documented equivalent is:
new_array = dset[0]
new_array[1] = 3.0
As the h5py multiple-indexing example shows, the local array changes; a new dataset read does not.
Conceptually, the failing expression proceeds like this:
row = ds.__getitem__(0)  # HDF5 read -> in-memory result
row.__setitem__(1, 99)   # NumPy mutation
It does not proceed like this:
ds.__setitem__((0, 1), 99)That method distinction is the diagnostic core.
The h5py 3.15.1 implementation makes the boundary visible as well. Dataset.__getitem__ is the dataset read path; for its ordinary fallback path it creates a NumPy output array, calls the low-level dataset read into that memory, and returns the array. Dataset.__setitem__, by contrast, builds a dataset selection and eventually calls the low-level HDF5 write operation. The public documentation, rather than these internal implementation details, should remain the application-level contract, but the source explains why the two forms take fundamentally different paths.
In supplied case H2, chained indexing leaves the same-handle dataset and the reopened dataset at:
[[1, 2, 3],
 [4, 5, 6]]
That is not an HDF5 write that later disappeared. No intended dataset assignment was submitted.
The repair is therefore structural: make the dataset itself the target of assignment.
Show why flushing a changed row does not submit it
The next trap begins with clearer code:
local = ds[0]
local[1] = 99
f.flush()
Now inspection of local gives exactly what the engineer wanted:
[1, 99, 3]That can make flush() feel like the missing final step. It is not.
The File Objects documentation defines File.flush() as a request for the HDF5 library to flush its buffers to disk. Meanwhile, h5py’s Dataset documentation says that ds[0] has already loaded array data into memory and that modifying that array does not write it back.
Taken together, the operational inference is straightforward: HDF5 cannot flush a dataset mutation it was never asked to perform. Changing an independent Python/NumPy object does not populate an HDF5 write buffer with the intended new cell.
Supplied H3 demonstrates precisely that separation:
local array:       [1, 99, 3]
same-handle data:  [[1, 2, 3], [4, 5, 6]]
reopened data:     [[1, 2, 3], [4, 5, 6]]
For a parallel lesson about validating the consumer-visible object rather than relying on a nearby success signal, see reconciling raster copy completeness. The storage mechanism there is different; the useful common principle is to qualify the state the downstream reader actually consumes.
A RAM change is not an HDF5 buffer change
NumPy’s Copies and Views documentation distinguishes an ndarray copy from a view and explains that views can share the same NumPy data buffer while copies do not. That distinction remains useful after an HDF5 read, but it should not be extended beyond the ndarray boundary.
Suppose a loaded row is further sliced:
row = ds[0]
view = row[0:2]
view[1] = 99
Because basic NumPy slicing normally produces a view, row and view can share RAM; changing view can therefore change row.
But neither object is a persistent view onto the h5py Dataset. Their shared memory relationship is between NumPy objects created after the HDF5 read.
This is a useful mental model:
HDF5 dataset
|
| Dataset.__getitem__ / HDF5 read
v
loaded NumPy array <----> NumPy views of that array
Mutations can propagate horizontally among NumPy objects that share memory. Persistence requires an explicit path back upward through a dataset write.
No amount of File.flush() repairs a missing arrow.
Write the target with one combined index
For a one-cell update, the narrowest correct operation is also the clearest:
ds[0, 1] = 99h5py explicitly recommends combining indices into a single indexing operation when writing.
This expression reaches Dataset.__setitem__ with the coordinate selection as a tuple. The h5py 3.15.1 source describes Dataset.__setitem__ as the path that writes to the HDF5 dataset; after preparing the selection and source data, it invokes the low-level dataset write.
For the present fixture, that gives the desired modification boundary: one logical cell.
The supplied H4 observation is:
same-handle:
[[1, 99, 3],
 [4,  5, 6]]

reopened:
[[1, 99, 3],
 [4,  5, 6]]
It therefore satisfies the full oracle:
observed.dtype == np.int32
observed.shape == (2, 3)
np.array_equal(observed, APPROVED)
This is ACCEPT_WRITEBACK.
Note the wording. Acceptance is based on readback, not merely on recognizing the syntax as correct. Correct-looking syntax is a reason to expect a write; the fresh read-only handle is the evidence that this particular case produced the approved stored state.
For a targeted update, this form is preferable to reading and rewriting an entire row because the code expresses the same logical boundary as the requirement. The intended state transition is “replace coordinate [0,1],” and the write selection says exactly that.
Use explicit row writeback when a row edit is intended
Sometimes application logic genuinely operates on a row as a unit. In that case, detached-array editing can still be valid, but only if the row is deliberately assigned back to the dataset:
local = ds[0]
local[1] = 99
ds[0] = local
The first line is a read. The second line is an in-memory NumPy mutation. The third line is the persistence operation.
This makes the write boundary reviewable. The unsafe version:
local = ds[0]
local[1] = 99
has no dataset assignment. The repaired version does.
Supplied H5 shows:
local:
[1, 99, 3]

same-handle:
[[1, 99, 3],
 [4,  5, 6]]

reopened:
[[1, 99, 3],
 [4,  5, 6]]
It therefore receives ACCEPT_WRITEBACK under the admitted single-writer fixture.
This pattern can be useful when several cells in one row are transformed together and the row is naturally the unit of computation. It should not, however, be described as equivalent to a coordinate-level merge under arbitrary writer topologies.
Writeback has a wider modification boundary
ds[0, 1] = 99 replaces one selected cell.
ds[0] = local replaces the selected row with whatever values are currently present in local.
In this fixture that distinction causes no problem because there is one writer and the row was read immediately before modification. The baseline row is [1,2,3]; after the local change it is [1,99,3]; writing it back produces exactly the oracle.
Under concurrent modification, a read-modify-write of an entire row could overwrite an intervening update made by another actor. That scenario is explicitly outside this laboratory. No concurrency guarantee should be inferred from H5.
This is why the disposition is RERUN rather than automatic approval if writer ownership changes. A row-writeback pattern qualified under one-writer assumptions has not been qualified as multi-writer update control.
Inspect iteration and full-array copy traps
Iteration creates the same category of hazard in less obvious syntax.
h5py documents that iteration walks the first axis and specifically warns that modifications to the yielded data are not recorded in the file. The 3.15.1 implementation is unusually explicit: Dataset.__iter__ yields self[i] and its docstring warns that modifications to those yielded values are not written back.
So this is not persistent iteration:
for index, row in enumerate(ds):
    if index == 0:
        row[1] = 99
The changed row is useful local data, but it is not a live dataset row.
Supplied H6 confirms that row becomes [1,99,3] while the same-handle and reopened dataset remain at the baseline.
The full-array form has the same persistence boundary:
local = ds[...]
local[0, 1] = 99
ds[...] is a dataset read. The result is an in-memory ndarray. Editing that result changes the ndarray, not /values. Supplied H7 records the local array as:
[[1, 99, 3],
 [4,  5, 6]]
while reopened storage remains:
[[1, 2, 3],
 [4, 5, 6]]
Both cases are REPAIR.
It can be tempting to analogize this to a pandas chained-assignment migration, but the explanation should stop at the broad engineering lesson that intermediate objects require careful ownership reasoning. h5py’s behavior here is its own file-backed Dataset contract, not a pandas Copy-on-Write rule.
The distinction also avoids an imprecise phrase such as “all slicing makes a copy.” NumPy itself has both copies and views. Basic slicing of an ndarray ordinarily returns a view, while advanced indexing returns a copy. The important boundary here is earlier: h5py has already performed a dataset read and returned in-memory data. NumPy view-sharing inside that returned object does not reconnect it to HDF5 persistence.
Reject a real write to the wrong coordinate
A robust test suite needs a negative control in which persistence works but correctness fails.
H8 does exactly that:
ds[1, 0] = 99This is valid combined indexing. It reaches the actual dataset assignment path. The write therefore persists.
But it produces:
[[1, 2, 3],
 [99, 5, 6]]
instead of:
[[1, 99, 3],
 [4,  5, 6]]
That case must be classified REJECT_WRONG_TARGET.
Why keep this control? Because a weaker oracle can accidentally certify it.
Consider a validation rule such as:
np.count_nonzero(observed != BASE) == 1
H8 passes. One cell changed.
A rule checking only for the presence of 99 also passes. A rule checking shape and dtype passes. A rule proving that an HDF5 write occurred passes.
Every one of those statements can be true while the update is still wrong.
The approved oracle instead asks whether all six values equal the declared target array. This gives the negative control real diagnostic power: it shows that the harness can distinguish missing persistence from incorrect persistence.
That distinction matters during repair. An H2-style problem requires inserting the missing Dataset write boundary. An H8-style problem already has a functioning write boundary; what needs repair is coordinate selection or intent mapping.
Those are different defects and should not receive the same disposition.
Close the writer and reconcile all nine cases
The supplied preparation evidence gives a compact ledger of the relevant states:
Case | Operation | Local edited value | Same-handle dataset | Fresh read-only readback | Approved oracle |
H1 | Baseline | None | [[1,2,3], | [[1,2,3], | No; control |
H2 | ds[0][1] = 99 | Intermediate not retained | [[1,2,3], | [[1,2,3], | No |
H3 | Edit retained row, then flush() | [1,99,3] | [[1,2,3], | [[1,2,3], | No |
H4 | ds[0,1] = 99 | None | [[1,99,3], | [[1,99,3], | Yes |
H5 | Edit row, then ds[0] = local | [1,99,3] | [[1,99,3], | [[1,99,3], | Yes |
H6 | Edit yielded iteration row | [1,99,3] | [[1,2,3], | [[1,2,3], | No |
H7 | Edit ds[...] result | [[1,99,3], | [[1,2,3], | [[1,2,3], | No |
H8 | ds[1,0] = 99 | None | [[1,2,3], | [[1,2,3], | No |
H9 | ds[0,1] = 99, then flush() | None | [[1,99,3], | [[1,99,3], | Yes |
Every case also asserts the baseline shape and dtype after reopening.
H9 is particularly useful when people suspect that H4 worked only because close implicitly handled something special. H9 performs the same real dataset assignment and explicitly calls flush(). It still produces the approved result. That does not make flush the cause of correctness; H4 already demonstrated correctness without the explicit call.
The comparison isolates the important variable:
H3: mutate ndarray -> flush       -> baseline remains
H9: Dataset assignment -> flush   -> approved value remains
The difference is whether a dataset write was submitted.
h5py’s file API says flush() requests that HDF5 flush its buffers; its closing documentation says leaving the context manager closes the file. The qualification sequence uses both concepts correctly: a real dataset assignment may be followed by an explicit flush where the application needs that operation, but final acceptance still occurs after writer close through a fresh reader.
Count equality does not prove cell identity
H8 is the reason to keep the oracle coordinate-specific.
Both H4 and H8 have one cell different from baseline. Both retain (2,3) shape. Both retain int32. Both contain one 99. Both represent real writes.
Only H4 changes the specified cell.
This is why storage readback should reconcile identities, not just totals. Counts are useful diagnostic summaries; they are not substitutes for an exact expected state when the expected state is small and fully known.
For this fixture, np.array_equal(observed, APPROVED) is inexpensive and unambiguous. There is no reason to weaken the contract.
Choose accept, repair, rerun or hold
Once the fresh-reader observation exists, the disposition should be mechanical rather than rhetorical.
Condition | Decision | Required interpretation |
Fresh reader sees exactly [[1,99,3], | ACCEPT_WRITEBACK | The candidate satisfies this fixture’s stored-state oracle |
Intended edit exists only in a row, iteration result or full loaded ndarray | REPAIR | Add an explicit Dataset assignment with the correct selection |
A real Dataset write persisted to a coordinate other than [0,1] | REJECT_WRONG_TARGET | Persistence works; target selection is wrong |
Driver, dtype, layout or relevant Python/h5py/HDF5/NumPy library conditions change | RERUN | Existing evidence does not qualify the altered environment |
File ownership, writer lifetime or intended cell identity is unknown | HOLD | Do not infer intent or replay an ambiguous change |
Under that matrix, H4, H5 and H9 meet ACCEPT_WRITEBACK. H2, H3, H6 and H7 are REPAIR patterns. H8 is REJECT_WRONG_TARGET. H1 is the baseline control and should not be mislabeled as an accepted update.
The JSON status PASS_9_CASES deserves careful interpretation. It means the diagnostic fixture observed all nine cases in the expected categories supplied by the preparation evidence. A passing negative control does not authorize the unsafe behavior it demonstrates. H2 “passes” the diagnostic because the harness successfully confirms that chained indexing fails to persist the intended update.
For broader operational context, data-pipeline quality checks are useful framing, but this acceptance rule is intentionally narrower: it tests one file-backed write boundary against a complete cell oracle.
The decision matrix also prevents an attractive but unsafe troubleshooting shortcut: adding flush() everywhere. H3 already demonstrates why that cannot repair detached-array mutation. Repair the missing assignment boundary first.
Recover files affected by a missing writeback
Finding ds[0][1] = 99 in source code does not by itself tell you what values historical files should contain.
That matters during remediation.
Suppose an earlier job loaded a row, calculated an intended replacement, changed the row in RAM and then exited without assigning it to the Dataset. The file contains the old value. If the intended replacement can be reconstructed from an authoritative source (an immutable input, a retained transformation record, a validated transaction log, or another trusted artifact), then the file can be repaired deliberately.
A safe recovery flow is to preserve the original file, establish the exact intended coordinate and value from independent evidence, open a repair copy under controlled ownership, perform the narrowest appropriate Dataset assignment, close the writer, and validate the entire required result through a fresh read-only handle.
For this fixture, a known repair would be:
with h5py.File(path, "r+") as f:
    f["values"][0, 1] = 99

with h5py.File(path, "r") as f:
    observed = f["values"][...]

assert observed.dtype == np.dtype(np.int32)
assert observed.shape == (2, 3)
assert np.array_equal(observed, APPROVED)
The important phrase is known repair.
A stale file containing 2 at [0,1] does not prove that 99 was historically intended. The source code might have been executed with different inputs, a different row, or no update requirement at all. A missing writeback explains a mechanism; it does not reconstruct business or scientific intent.
Reconstruct intent before replaying edits
When the intended cell identity or replacement value is uncertain, the correct decision is HOLD.
Do not scan historical files for a suspicious value and replace it speculatively. Do not infer that every dataset touched by an unsafe coding pattern needs the same mutation. Do not manufacture expected values from what the repaired program would produce today unless that is an explicitly qualified reconstruction method.
Preserve the affected artifact and the evidence around it. Separate three questions:
Was the historical code capable of losing an intended update because it only mutated an in-memory array?
Was an update actually intended for this particular file?
What exact coordinate and value should that file contain?
Only the first can be answered from identifying a chained-indexing or detached-array pattern. The other two require intent evidence.
That boundary keeps repair from turning a known persistence bug into an unverified data rewrite.
Release the write boundary with ownership and regression checks
Once repaired, make this behavior difficult to regress.
The most valuable regression test is not simply:
assert row[1] == 99That checks the place where the bug can hide.
Instead, preserve a miniature file-backed test that constructs known input, performs the candidate update, closes the writer, opens a new reader and checks the complete expected array, shape and dtype. Keep the wrong-coordinate case as a negative control so the suite proves it can reject a real but incorrect write.
Record enough execution context to make changes visible: Python version, NumPy version, h5py version, linked HDF5 version, driver policy, fixture source revision, expected array and per-case results. If you create a new evidence run, capture its actual source digest and process result rather than copying the October 23, 2026 preparation labels into a new record.
The supplied digest is particularly useful for source identification:
9c17044697e98c43d341a0185bf73ad7bc25660b6965f650c1396d558c8c82f5But treat it according to its real evidentiary scope. A hash can identify the fixture bytes used to compute it; by itself it does not prove that Python executed those bytes, that the reported runtime loaded the claimed libraries, or that a file contains the approved cells.
Use Git for versioning the write and readback fixture to keep code changes reviewable, but do not substitute Git history for file qualification. Source provenance and stored-state readback answer different questions.
The release gate should also encode the environment boundary. A change to the file driver, dtype, layout or relevant library stack triggers RERUN. Unknown ownership or writer lifetime triggers HOLD. That is not because these changes necessarily break the update; it is because this fixture has not established their behavior.
The same restraint applies to concurrency and durability. This article qualifies a normal close followed by a fresh read-only reopen under a single-writer local-file regime. It does not qualify SWMR, MPI, concurrent writes, crash consistency, fsync, remote object storage, or lost-update prevention.
That is the principal storage lesson: make the acceptance boundary as explicit as the write boundary. “The Python assignment completed” is weaker than “the Dataset read changed.” “The Dataset read changed” is still weaker than “after the writer closed, an independent reader observed exactly the approved state.”
Practice storage reasoning through data engineering
The h5py failure is small enough to fit on one line:
ds[0][1] = 99But the engineering lesson is larger. Array-like syntax can cross several ownership domains: an HDF5 dataset, a newly loaded NumPy array, a NumPy view of that array, HDF5’s internal write path, and finally a later independent reader. Reliable storage work depends on knowing which object owns the mutation at each step.
For this case, the rule is concrete. Dataset.__getitem__ reads data into memory; editing the resulting ndarray is local. A combined assignment such as ds[0, 1] = 99 reaches the Dataset write path. Explicit row writeback can also be correct under the admitted single-writer policy. flush() cannot reconstruct a Dataset assignment that never happened. And acceptance comes only after the writer closes and a fresh reader reconciles every required cell, shape and dtype. h5py’s documented multiple-indexing and iteration behavior directly supports those boundaries.
For engineers building the broader skills around ingestion, transformation, storage and protection, Refonte Learning’s Data Engineering Program currently lists a three-month curriculum at 12–14 hours per week covering data pipelining, streaming and batch ingestion, transformation, storage provisioning, data protection, Hadoop, and an educational path that includes Spark, alongside practical projects, educational mentorship and a virtual internship opportunity. The program page states that completion awards include a Training Certificate and Certificate of Internship and that admission requires working toward a bachelor’s or higher-level degree. It does not establish h5py, HDF5, or this exact readback laboratory as named curriculum content.