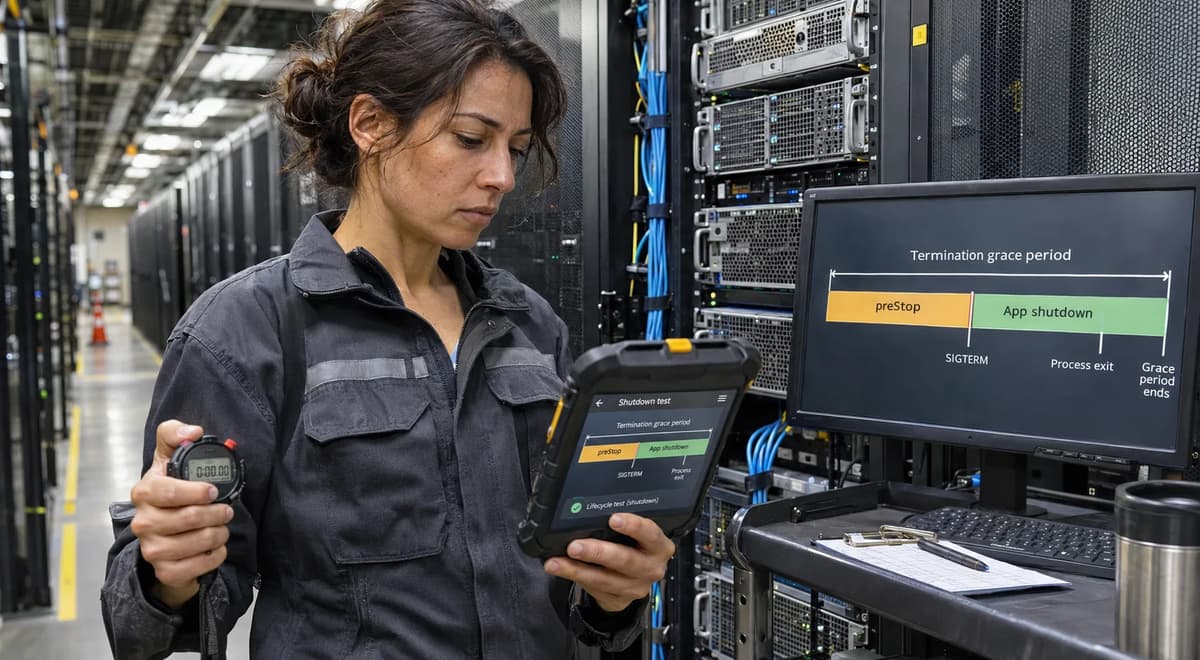
A Kubernetes Pod can look as though it has been given a generous shutdown window while the application itself receives only the remainder of that window. The reason is narrow but operationally important: the Pod termination grace-period countdown begins before a preStop handler executes, and the handler normally must finish before the container runtime is asked to deliver the stop signal to the container. Kubernetes therefore treats hook execution and application shutdown as consumers of the same termination interval rather than as two sequential budgets.
That distinction is easy to lose in logs. A hook can start successfully, sleep for several seconds, complete successfully, and still leave too little time for the application’s SIGTERM handler. Conversely, a terminating Service endpoint can become unsuitable for ordinary traffic while the Pod’s own Ready condition remains true and the process is still alive. If the remaining time expires, the kubelet can move from graceful termination to forcible shutdown and the container runtime sends SIGKILL to processes still running.
The acceptance question is therefore not “did preStop run?” It is whether the evidence establishes four separate boundaries: when deletion became effective, how long the hook occupied the grace period, when SIGTERM reached the application, and whether the application exited before forcible termination. This playbook builds that evidence on an owned, disposable local cluster with synthetic state only. The fixture is a proposed experiment; its expected outcomes must be verified against a captured run.
Define the acceptance contract and capture the baseline
Treat the experiment as a lifecycle acceptance test rather than as a generic Kubernetes tutorial. The contract under review is the relationship among a Pod deletion request, terminationGracePeriodSeconds, a container preStop handler, the later stop signal, EndpointSlice state and final container termination.
The primary contract comes from three current Kubernetes statements. First, the lifecycle-hook documentation says the grace-period countdown starts before preStop and that the hook must complete before the stop signal can normally be sent. It explicitly describes the termination interval as covering both hook execution and normal container shutdown. Second, the Pod lifecycle documentation places preStop before the runtime stop request in the termination flow and says that, when the grace period expires with a process still running, forcible shutdown follows. Third, the Pod API reference repeats that preStop management blocks until the hook completes or the termination grace period is reached.
Define acceptance before creating the Pod:
Evidence boundary | ACCEPT condition | Failure interpretation |
Deletion start | .metadata.deletionTimestamp is retained | Without it, elapsed shutdown time has no authoritative API anchor |
Hook interval | HOOK_START and, when expected, HOOK_END are independently observable | A delete return code alone does not establish hook duration |
Stop delivery | application records SIGTERM_RECEIVED after HOOK_END in the normal case | Signal before completed hook contradicts the expected lifecycle for this fixture |
Endpoint transition | EndpointSlice reaches terminating=true, with ready=false for the terminating endpoint | Pod readiness alone is insufficient evidence of Service eligibility |
Graceful completion | container terminates without signal 9 and records application shutdown completion | Hook + application path fit inside the tested budget |
Forced case | long-budget case succeeds, short-budget control records signal 9 or equivalent runtime evidence | Without a contrasting forced case, the test does not establish the boundary |
Identity | Pod UID, image ID, node, runtime and Kubernetes versions are captured | Results cannot be assigned to a reproducible execution environment otherwise |
Do not substitute command success for those states. kubectl delete accepting the request establishes that deletion was requested; it does not by itself prove when the hook finished, when SIGTERM was delivered, or whether SIGKILL was required. Kubernetes finalization also means an object can have a deletion timestamp while remaining visible until its finalizers are cleared.
This evidence discipline is intentionally different from the Refonte Learning article One Exception Can Stop a Java Periodic Task. That page separates a periodic task’s terminal state from executor liveness; it does not test Kubernetes Pod termination or preStop. The reusable lesson is only the separation of states: one green signal must not be promoted into proof of a different boundary.
Before intervention, capture the host and toolchain rather than writing “tested on Kubernetes” without qualification:
set -eu

mkdir -p evidence
date -u +"%Y-%m-%dT%H:%M:%SZ" > evidence/run-start.txt

uname -a > evidence/host-uname.txt
docker version > evidence/docker-version.txt 2>&1
kind version > evidence/kind-version.txt
kubectl version -o yaml > evidence/kubectl-version.yaml
As of November 6, 2026, Kubernetes lists the actively maintained minor branches as 1.37, 1.36 and 1.35; its release page identifies 1.37.1 as the latest published 1.37 patch. Do not turn that publication-time fact into an execution claim. The evidence packet must record what the test actually used.
For a deterministic local control-plane base, kind v0.33.0 publishes this Kubernetes v1.37.0 node image and explicitly recommends using its digest rather than relying only on the tag:
KIND_NODE='kindest/node:v1.37.0@sha256:a1ed56cfb0e7b93589bdf97c8cd566405a265939e3620fc4f5de89adff580ae5'

kind create cluster \
  --name prestop-budget \
  --image "$KIND_NODE"
Immediately capture what was actually created:
kubectl cluster-info > evidence/cluster-info.txt
kubectl get nodes -o wide > evidence/nodes-wide.txt
kubectl get nodes -o json > evidence/nodes.json

kubectl get node prestop-budget-control-plane \
  -o jsonpath='{.status.nodeInfo.kubeletVersion}{"\n"}{.status.nodeInfo.containerRuntimeVersion}{"\n"}{.status.nodeInfo.osImage}{"\n"}{.status.nodeInfo.kernelVersion}{"\n"}' \
  > evidence/node-runtime.txt
That file is more important for later comparison than a prose statement copied from kind release notes. Runtime version pinning is an observed property of the run, not an assumption.
Build a controlled disposable fixture and pin its ownership
The fixture needs one application container, one Service and no production dependencies. The application records SIGTERM, deliberately delays its own exit, and exposes an HTTP endpoint that the preStop handler can use to emit markers through the application’s normal log stream. That arrangement avoids pretending that lifecycle-hook stdout is the evidence source.
Resolve the workload image to an immutable digest at execution time:
docker pull python:3.13-alpine

APP_IMAGE="$(
  docker image inspect python:3.13-alpine \
    --format '{{index .RepoDigests 0}}'
)"

printf '%s\n' "$APP_IMAGE" | tee evidence/app-image-digest.txt
The moving tag is used only for discovery. The rendered Pod manifest should contain the resolved digest from APP_IMAGE. That means a rerun can retain the exact image reference actually selected rather than silently consuming a later tag.
Create app.py:
import http.server
import os
import signal
import sys
import threading
import time
from datetime import datetime, timezone
from urllib.parse import urlparse, parse_qs

TERM_SECONDS = float(os.environ["TERM_SECONDS"])

def now():
    return datetime.now(timezone.utc).isoformat()

def emit(event):
    print(f"{now()} {event}", flush=True)

class Handler(http.server.BaseHTTPRequestHandler):
    def do_GET(self):
        parsed = urlparse(self.path)

        if parsed.path == "/ready":
            self.send_response(200)
            self.end_headers()
            self.wfile.write(b"ready\n")
            return

        if parsed.path == "/mark":
            event = parse_qs(parsed.query).get("event", ["UNKNOWN"])[0]
            emit(event)
            self.send_response(204)
            self.end_headers()
            return

        self.send_response(404)
        self.end_headers()

    def log_message(self, fmt, *args):
        return

server = http.server.ThreadingHTTPServer(("0.0.0.0", 8080), Handler)

def on_term(signum, frame):
    emit("SIGTERM_RECEIVED")
    time.sleep(TERM_SECONDS)
    emit("APP_SHUTDOWN_COMPLETE")
    sys.exit(0)

signal.signal(signal.SIGTERM, on_term)

emit("APP_STARTED")
server.serve_forever()
The important fixture property is not Python itself. It is the independently visible event sequence. The main process logs SIGTERM_RECEIVED; the hook asks that process to log HOOK_START and HOOK_END; Kubernetes API observations record deletion and endpoint state; container status records how execution actually terminated.
Create a small renderer called render-case.sh:
#!/bin/sh
set -eu

: "${APP_IMAGE:?set APP_IMAGE}"
: "${CASE:?set CASE}"
: "${GRACE:?set GRACE}"
: "${HOOK_SECONDS:?set HOOK_SECONDS}"
: "${TERM_SECONDS:?set TERM_SECONDS}"

cat <<EOF
apiVersion: v1
kind: ConfigMap
metadata:
  name: prestop-app
  namespace: prestop-lab
data:
  app.py: |
$(sed 's/^/    /' app.py)
---
apiVersion: v1
kind: Pod
metadata:
  name: prestop-budget
  namespace: prestop-lab
  labels:
    app: prestop-budget
    case: "${CASE}"
  finalizers:
    - evidence.refonte.dev/retain
spec:
  terminationGracePeriodSeconds: ${GRACE}
  containers:
    - name: app
      image: "${APP_IMAGE}"
      imagePullPolicy: IfNotPresent
      env:
        - name: TERM_SECONDS
          value: "${TERM_SECONDS}"
        - name: HOOK_SECONDS
          value: "${HOOK_SECONDS}"
      command: ["python", "/fixture/app.py"]
      ports:
        - containerPort: 8080
      readinessProbe:
        httpGet:
          path: /ready
          port: 8080
        periodSeconds: 1
        failureThreshold: 1
      lifecycle:
        preStop:
          exec:
            command:
              - /bin/sh
              - -c
              - |
                python -c "import urllib.request; urllib.request.urlopen('http://127.0.0.1:8080/mark?event=HOOK_START').read()"
                sleep "\$HOOK_SECONDS"
                python -c "import urllib.request; urllib.request.urlopen('http://127.0.0.1:8080/mark?event=HOOK_END').read()"
      volumeMounts:
        - name: fixture
          mountPath: /fixture
          readOnly: true
  volumes:
    - name: fixture
      configMap:
        name: prestop-app
---
apiVersion: v1
kind: Service
metadata:
  name: prestop-budget
  namespace: prestop-lab
spec:
  selector:
    app: prestop-budget
  ports:
    - port: 80
      targetPort: 8080
EOF
The evidence-only finalizer is deliberate. Kubernetes documents that a finalizer causes the API object to receive a deletion timestamp and remain present until the finalizer is removed. That makes post-termination container state inspectable instead of racing API-object deletion. It is not a production recommendation. Ownership is explicit: this disposable fixture adds the finalizer, this procedure inspects the state, and this procedure removes it.
Prepare the namespace:
kubectl create namespace prestop-lab
chmod +x render-case.sh
The fixture owns no secret, credential, persistent volume, external endpoint or customer payload. Destroying the namespace and kind cluster should be sufficient cleanup after finalizer reconciliation.
Record the documented behavior before predicting results
Write the expected lifecycle down before running a case. Otherwise the test can degenerate into reading whatever happened and retrofitting a story around it.
For a Pod whose terminationGracePeriodSeconds is nonzero, current Kubernetes lifecycle documentation describes the sequence as: deletion marks the Pod as terminating; the kubelet invokes preStop; if the hook completes, the kubelet asks the container runtime to deliver the stop signal; and when the allowed graceful shutdown interval expires with processes still alive, forcible termination follows. The same documentation notes a small, one-off two-second extension when a preStop handler is still running as the grace period expires.
That two-second extension matters when interpreting measurements. Do not redefine the advertised Pod grace period as “grace plus two seconds.” The Kubernetes documentation presents the extension as a special kubelet request for an over-running preStop, not as an application budget that a design should deliberately consume. A release gate should therefore size the configured grace period for the declared hook plus application cleanup requirement, rather than depending on emergency extension behavior.
A useful model is:
Tdelete
  |
  +---- preStop ------------------+
  |                               |
  |                           SIGTERM
  |                               |
  +--------- configured grace ----+--------> forced termination boundary
For a normal case, the engineering inequality is approximately:
hook runtime + required application shutdown time < configured grace period
That is an operational design inequality, not a claim that wall-clock scheduling is exact to the second. Kubelet observation latency, API propagation, container-runtime scheduling and log transport can all affect measurements. The acceptance test therefore reasons about ordering and sufficient margin, not nanosecond equality.
The Pod API reference is worth keeping beside the experiment because it prevents an easy conceptual mistake: terminationGracePeriodSeconds is the Pod’s graceful termination duration, while lifecycle management for preStop blocks until the handler finishes or that period is reached. Reading only the PodSpec field description can produce a misleading mental model that the application receives the full period after SIGTERM.
The Service-facing state has its own boundary. EndpointSlice documents three relevant conditions: serving, terminating and ready. For Pod-backed endpoints, serving maps to Pod readiness; terminating is set when the Pod receives a deletion timestamp; and EndpointSlice ready is effectively serving && !terminating, apart from the documented publishNotReadyAddresses exception. Consequently, an application may still report healthy while the endpoint is marked terminating=true and ready=false.
That distinction is one reason the experiment must capture both Pod and EndpointSlice state. “Readiness changed” is too vague. Which readiness representation changed, and why?
The false-positive hypothesis is now precise: a successful preStop completion can be mistaken for successful graceful shutdown even when the hook has consumed enough of the common grace period that the application is later killed.
Refonte Learning’s Python Subprocess Exit Is Not Pipe EOF addresses an analogous evidence mistake in a different domain: child-process exit and pipe EOF are separate states. It provides no Kubernetes evidence and is not proof of this article’s claim. Here the corresponding separation is hook completion versus application completion.
Run contrasting cases and compare the competing timelines
Use at least three cases. The first establishes a comfortable positive control. The second is the critical counterexample: the hook itself completes, SIGTERM arrives, but the remaining budget is too small for the application’s declared shutdown. The third deliberately allows the hook itself to overrun the configured budget.
For every case, render a fresh Pod rather than mutating a terminating object:
export APP_IMAGECase A: sufficient shared budget
export CASE=fit
export GRACE=15
export HOOK_SECONDS=3
export TERM_SECONDS=4

./render-case.sh > evidence/fit-manifest.yaml
kubectl apply -f evidence/fit-manifest.yaml
kubectl wait -n prestop-lab \
  --for=condition=Ready pod/prestop-budget \
  --timeout=60s
The predicted ordering is:
deletionTimestamp
HOOK_START
~3 s
HOOK_END
SIGTERM_RECEIVED
~4 s
APP_SHUTDOWN_COMPLETE
container exits without SIGKILL
The total declared work is seven seconds against a fifteen-second configured grace period. The acceptance target is not exactly seven seconds from deletion; it is the correct order, sufficient margin and no forced termination.
Case B: hook completes but consumes the application’s room
export CASE=consumed
export GRACE=12
export HOOK_SECONDS=9
export TERM_SECONDS=6

./render-case.sh > evidence/consumed-manifest.yaml
The predicted sequence is different:
deletionTimestamp
HOOK_START
~9 s
HOOK_END
SIGTERM_RECEIVED
application begins 6 s shutdown
configured grace expires before that shutdown can finish
SIGKILL / forced termination
This is the central case. Its misleading green signal is HOOK_END. If the test stops there, the lifecycle appears healthy. The acceptance ledger must continue through container termination.
Case C: hook itself overruns the configured interval
export CASE=hook-overrun
export GRACE=10
export HOOK_SECONDS=20
export TERM_SECONDS=1

./render-case.sh > evidence/hook-overrun-manifest.yaml
Here HOOK_START should be observable, but HOOK_END should not be assumed. Kubernetes documents that a still-running hook at grace expiry can receive a one-off small extension, after which forcible shutdown can occur if termination has not completed. Because the application stop handler is downstream of normal hook completion, this case tests a different failure boundary from Case B.
Run one case at a time. Before deletion, start the log capture:
CASE_DIR="evidence/$CASE"
mkdir -p "$CASE_DIR"

kubectl get pod -n prestop-lab prestop-budget -o json \
  > "$CASE_DIR/pod-before.json"

kubectl get endpointslice -n prestop-lab \
  -l kubernetes.io/service-name=prestop-budget \
  -o json > "$CASE_DIR/endpoints-before.json"

kubectl logs -n prestop-lab pod/prestop-budget \
  -c app -f --timestamps \
  > "$CASE_DIR/app.log" 2>&1 &
LOG_PID=$!
Record the Pod UID, node, image and resolved runtime image identifier:
kubectl get pod -n prestop-lab prestop-budget \
  -o jsonpath='{.metadata.uid}{"\n"}{.spec.nodeName}{"\n"}{.spec.containers[0].image}{"\n"}{.status.containerStatuses[0].imageID}{"\n"}' \
  > "$CASE_DIR/identity.txt"
Start independent API polling. This deliberately samples state from outside the container:
(
  while true; do
    ts="$(date -u +'%Y-%m-%dT%H:%M:%SZ')"

    if ! obj="$(kubectl get pod -n prestop-lab prestop-budget -o json 2>/dev/null)"; then
      break
    fi

    printf '%s\t' "$ts"
    printf '%s\n' "$obj" |
      jq -c '{
        uid:.metadata.uid,
        deletionTimestamp:.metadata.deletionTimestamp,
        grace:.metadata.deletionGracePeriodSeconds,
        phase:.status.phase,
        ready:(
          [.status.conditions[]? |
           select(.type=="Ready") |
           .status][0] // null
        ),
        state:.status.containerStatuses[0].state
      }'
    sleep 1
  done
) > "$CASE_DIR/pod-poll.ndjson" &
POD_POLL_PID=$!
Capture EndpointSlice conditions independently:
(
  while true; do
    ts="$(date -u +'%Y-%m-%dT%H:%M:%SZ')"
    printf '%s\t' "$ts"

    kubectl get endpointslice -n prestop-lab \
      -l kubernetes.io/service-name=prestop-budget \
      -o json 2>/dev/null |
      jq -c '[
        .items[].endpoints[]? |
        {
          uid:.targetRef.uid,
          ready:.conditions.ready,
          serving:.conditions.serving,
          terminating:.conditions.terminating
        }
      ]'

    sleep 1
  done
) > "$CASE_DIR/endpoints-poll.ndjson" &
EPS_POLL_PID=$!
Then request ordinary graceful deletion, not force deletion:
date -u +"%Y-%m-%dT%H:%M:%SZ" \
  > "$CASE_DIR/delete-request-client-time.txt"

kubectl delete pod -n prestop-lab prestop-budget \
  --wait=false \
  > "$CASE_DIR/delete-response.txt" 2>&1
Kubernetes warns that force deletion does not wait for confirmation that node-side processes have stopped, so --force --grace-period=0 would destroy the lifecycle boundary this experiment is intended to measure.
Wait until the retained Pod object shows a terminated container, using a bounded diagnostic loop:
for i in $(seq 1 45); do
  state="$(
    kubectl get pod -n prestop-lab prestop-budget \
      -o jsonpath='{.status.containerStatuses[0].state.terminated.finishedAt}' \
      2>/dev/null || true
  )"

  [ -n "$state" ] && break
  sleep 1
done
Now preserve the final state before removing the evidence finalizer:
kubectl get pod -n prestop-lab prestop-budget -o json \
  > "$CASE_DIR/pod-after.json"

jq '.status.containerStatuses[0].state.terminated' \
  "$CASE_DIR/pod-after.json" \
  > "$CASE_DIR/termination.json"

kubectl get endpointslice -n prestop-lab \
  -l kubernetes.io/service-name=prestop-budget \
  -o json > "$CASE_DIR/endpoints-after.json"
The Kubernetes Pod API exposes exitCode, reason, finishedAt and signal in ContainerStateTerminated; the signal field is therefore stronger forced-kill evidence than inferring everything from a log gap. In the forced case, a reported signal: 9 directly identifies termination by signal 9 in the Kubernetes container state. Preserve the raw JSON rather than converting the whole decision into “exit 137,” because exit-code conventions can obscure the source.
This experiment also needs a true negative control: remove preStop while leaving the application’s SIGTERM delay and grace period unchanged. For example, with GRACE=12 and TERM_SECONDS=6, deleting the lifecycle.preStop stanza should give the application substantially more of the configured interval. The comparison is causal: same application behavior and same Pod grace period, but no nine-second hook consumption.
Refonte Learning’s Python Path Containment: Prefix Checks Can Admit Escapes likewise uses contrasting controls to locate an exact boundary, but its path-resolution experiment is unrelated to Pod shutdown and should not be cited as evidence for Kubernetes behavior.
Do not compare only Case A and Case C. Case B is the most useful acceptance case because it disproves the false inference that “hook finished” means “shutdown fit inside the budget.”
Measure identity, lifecycle state and completed effects independently
The fixture produces several evidence streams because no single stream can answer every lifecycle question.
The application log establishes process-visible events:
APP_STARTED
HOOK_START
HOOK_END
SIGTERM_RECEIVED
APP_SHUTDOWN_COMPLETE
Those labels have different evidentiary weight. HOOK_START means the lifecycle exec handler reached the running application and asked it to record the marker. HOOK_END means the sleep interval completed and the hook’s second marker call reached the application. SIGTERM_RECEIVED is evidence from the application process that it observed SIGTERM. APP_SHUTDOWN_COMPLETE means the application reached the end of its deliberate cleanup delay.
The absence of a marker is weaker evidence. Missing APP_SHUTDOWN_COMPLETE is compatible with forced kill, logging failure or a broken capture process. Therefore classify forced shutdown primarily from Kubernetes container termination state and only use the missing application marker as corroboration.
The API stream answers a different question. .metadata.deletionTimestamp identifies that deletion has entered the Kubernetes object lifecycle. Finalizers keep a marked object visible until cleared; they do not make the object “not deleted yet” in the ordinary operational sense of accepting new lifecycle work. Kubernetes describes deletion with finalizers as a two-stage process in which the timestamp is set before ultimate storage removal.
The EndpointSlice stream separates process health from routability. When the Pod deletion timestamp appears, Kubernetes documents that the endpoint can be marked terminating; for a terminating endpoint, ordinary EndpointSlice ready becomes false even when serving remains true because the Pod itself is still Ready. A captured state such as:
{
  "ready": false,
  "serving": true,
  "terminating": true
}
would therefore not mean that the application readiness probe failed. It would mean the endpoint is terminating while the backing Pod remains ready according to the readiness source represented by serving.
This is exactly why “readiness transitions” must be named. The Pod Ready condition, EndpointSlice serving, EndpointSlice terminating, and EndpointSlice ready are related but not interchangeable.
After each case, compare timestamps and states using the following ledger schema. The values below are fields to populate, not an execution transcript:
Field | Case A | Case B | Case C | No-hook control |
Pod UID | capture | capture | capture | capture |
configured grace | 15 s | 12 s | 10 s | 12 s |
hook request | 3 s | 9 s | 20 s | none |
app TERM delay | 4 s | 6 s | 1 s | 6 s |
deletionTimestamp | measure | measure | measure | measure |
HOOK_START | measure | measure | measure | N/A |
HOOK_END | expect yes | expect yes | do not assume | N/A |
SIGTERM_RECEIVED | expect after hook | expect after hook | uncertain if hook never finishes | expect early |
APP_SHUTDOWN_COMPLETE | expect yes | expect absent if forced | do not assume | expect yes |
endpoint terminating | expect true | expect true | expect true | expect true |
endpoint ready during termination | expect false | expect false | expect false | expect false |
terminating.signal | expect 0/none | predicted 9 | predicted forced termination | expect 0/none |
verdict | pending evidence | pending evidence | pending evidence | pending evidence |
The predicted outcomes are grounded in the documented lifecycle, but they remain predictions until the fixture is executed and the raw files are retained. Do not replace “predicted 9” with “signal 9 observed” without an actual termination.json.
Preserve independent observation even when the application appears conclusive. If the same process both creates and validates every event, one bug can manufacture a self-consistent story. Kubernetes API state and EndpointSlice state provide separate observers outside the container.
The same principle appears in Refonte Learning’s Python tarfile Errors: Validate Staged Extraction: an API refusal does not retroactively establish that no earlier effect occurred. That article is not Kubernetes evidence, but its evidence discipline is applicable here: a lifecycle-stage result must not be treated as proof about later completed effects.
Build an auditable ledger, repair the violated boundary and make the release decision
Once the raw evidence exists, reduce it into a case-by-case ledger without discarding the originals. A practical directory should resemble:
evidence/
├── host-uname.txt
├── docker-version.txt
├── kind-version.txt
├── kubectl-version.yaml
├── cluster-info.txt
├── nodes.json
├── node-runtime.txt
├── app-image-digest.txt
├── fit/
│   ├── app.log
│   ├── identity.txt
│   ├── pod-before.json
│   ├── pod-poll.ndjson
│   ├── endpoints-poll.ndjson
│   ├── delete-response.txt
│   ├── pod-after.json
│   └── termination.json
├── consumed/
└── hook-overrun/
For each case, calculate four intervals where the evidence permits it:
hook duration:
    HOOK_END - HOOK_START

time from deletion to SIGTERM:
    SIGTERM_RECEIVED - deletionTimestamp

application time available after SIGTERM:
    container finishedAt - SIGTERM_RECEIVED

total lifecycle interval:
    container finishedAt - deletionTimestamp
Do not force arithmetic on clocks that are not comparable. Application timestamps come from the container’s node clock; Kubernetes object timestamps come from control-plane components; the external poller uses the host clock. On a local kind cluster they may be closely aligned, but that is still an assumption that should be checked rather than silently asserted. Ordering within one evidence source is stronger than subsecond subtraction across unsynchronized clocks.
The most persuasive Case B evidence packet would contain all of the following: a deletion timestamp; HOOK_START; a later HOOK_END; SIGTERM_RECEIVED after the hook; no application shutdown completion; and a terminated container state indicating signal 9. That combination identifies the precise failure boundary: preStop itself did not fail, but its runtime consumed enough of the common termination interval that the application did not complete before forcible shutdown.
Repair should address that boundary rather than simply making the test green. Several repairs are possible, but they are not equivalent.
First, shorten or remove work from preStop. Kubernetes explicitly advises keeping hook handlers lightweight, while acknowledging that longer operations may sometimes be useful. If the hook merely sleeps in the hope that traffic drains, measure whether that delay is actually required and whether a dedicated drain mechanism can express the requirement more directly.
Second, increase terminationGracePeriodSeconds when the workload genuinely needs both a hook interval and application cleanup interval. Kubernetes’ Pod lifecycle documentation explicitly says to increase the grace period when the preStop hook needs longer than the default interval allows. The engineering value should include measured worst-case cleanup plus deliberate margin, not merely the median observed in one laptop run.
Third, make the application begin draining independently when appropriate rather than assuming that preStop is the only traffic-removal mechanism. EndpointSlice termination state already represents an important Service-facing transition; consumers that implement connection draining can reason about terminating and serving. Whether an ingress, service mesh or external load balancer honors those conditions is implementation-specific and must be tested separately rather than inferred from Kubernetes API state.
After the repair, rerun the same failing case. Do not silently increase both the hook duration and the grace period, change the application image and alter the observer at once. A release gate needs one changed boundary and stable controls.
For example, if Case B failed with:
grace = 12
hook  = 9
TERM cleanup = 6
a repair experiment could retain hook and application timings but increase grace:
grace = 20
hook  = 9
TERM cleanup = 6
The repaired case should then preserve HOOK_END < SIGTERM_RECEIVED < APP_SHUTDOWN_COMPLETE and complete without a forced-termination signal. The no-hook control should also be rerun to detect unrelated regression.
Reconciliation follows every case because the evidence finalizer intentionally blocks final object removal. First confirm that pod-after.json and termination.json exist. Then remove only the finalizer owned by this fixture:
kubectl patch pod -n prestop-lab prestop-budget \
  --type=json \
  -p='[
    {"op":"remove","path":"/metadata/finalizers"}
  ]'
Kubernetes cautions against casually removing finalizers because they normally represent cleanup obligations. Here removal is justified only because evidence.refonte.dev/retain was created by this test for the sole purpose of retaining the Pod object until its terminal state was captured.
Confirm disappearance before the next case:
kubectl wait -n prestop-lab \
  --for=delete pod/prestop-budget \
  --timeout=30s
Then reapply the next rendered manifest.
The final release matrix should force one of four explicit outcomes:
Decision | Evidence rule | Required action |
ACCEPT | documented ordering reproduced; repaired/target case exits without forced kill; identity and controls retained | approve the tested configuration within its stated version/platform scope |
REPAIR | failure boundary is understood and attributable to insufficient shared shutdown budget or avoidable hook work | change the boundary, then rerun the original failing case |
HOLD | evidence is incomplete, clocks/identity are ambiguous, hook ordering contradicts expectations, or required state cannot be captured | do not generalize or approve; investigate the fixture/runtime |
RECONCILE | experiment left retained objects, partial state or deliberate finalizers requiring cleanup before further testing | complete cleanup and prove the next run starts from a clean state |
ACCEPT is intentionally scoped. It does not mean every Kubernetes version, CRI implementation, operating system, load balancer or workload has been proven. It means the tested Kubernetes/runtime/image combination produced evidence consistent with the declared contract for the tested cases.
REPAIR is appropriate when the cause is reproducible and the remedy is architectural or configurational. HOLD is the correct choice when evidence cannot discriminate between competing explanations. RECONCILE exists because cleanup is itself state: a partially retained test Pod must not be treated as a fresh baseline.
Refonte Learning’s CloudFront Cache Isolation: Audit Personalized Responses uses a different platform and security boundary, but it similarly separates a passing local signal from the actual consumer-visible isolation state. The relevant practice here is not CloudFront configuration; it is release acceptance based on the state that matters rather than the command that happened to return success.
Document limits, operational ownership and apply the discipline with Refonte Learning DevOps Engineer
This fixture establishes a deliberately narrow claim. It tests ordinary Pod deletion on a local Linux kind cluster, an exec-based preStop hook, an application that handles SIGTERM, one Service and EndpointSlice observation. It does not establish eviction behavior under every controller, node failure, kubelet restart, network partition, Windows container semantics, sidecar shutdown ordering, service-mesh draining or cloud load-balancer timing.
Those limits matter because Kubernetes itself documents additional branches. A force-deleted Pod has different API semantics, and the API server does not wait for confirmation that its processes have stopped. Native sidecar containers also have special termination ordering, whereas ordinary containers do not receive stop signals in a guaranteed inter-container order. Neither behavior belongs in this fixture unless it becomes the explicit next research question.
Do not treat the EndpointSlice transition as an end-to-end network guarantee. Kubernetes documents that terminating endpoints are normally ignored by Service proxies, but it also describes cases where an endpoint that is both serving and terminating may be routed to if all available endpoints are terminating. A production traffic-draining acceptance test would therefore need the actual proxy, ingress, mesh or external load-balancer path as another evidence layer.
Similarly, do not claim wall-clock precision that the protocol does not provide. Kubernetes guarantees lifecycle relationships at the API and kubelet level; it does not turn a shell sleep 9 plus a six-second application delay into a real-time deadline proof with zero scheduling overhead. The point of the contrasting cases is to make the budget boundary large enough to observe robustly.
Operational ownership should be recorded beside the ledger:
Artifact | Owner |
Fixture manifest and application code | test author |
kind and Kubernetes version capture | platform engineer |
workload image digest | release/test owner |
application shutdown requirement | application owner |
approved termination grace value | workload + platform owners |
evidence ledger | person performing acceptance run |
finalizer removal and namespace cleanup | fixture owner |
ACCEPT / REPAIR / HOLD / RECONCILE decision | named release authority |
At the end of all cases, reconcile the entire disposable environment:
kubectl delete namespace prestop-lab --wait=true
kind delete cluster --name prestop-budget

date -u +"%Y-%m-%dT%H:%M:%SZ" \
  > evidence/run-end.txt
Retain the manifests, raw JSON, logs and version capture together. The evidence packet should allow a reviewer to distinguish an official Kubernetes statement from a predicted fixture outcome and an actually observed result without rerunning the test.
Refonte Learning’s Kubernetes PDB playbook discusses node-drain acceptance and records Pod termination as one element of a broader maintenance sequence. Its StatefulSet article tests PVC identity and retention across scale changes. This experiment isolates preStop’s consumption of the Pod termination grace period.
The practical conclusion is therefore narrow: a Kubernetes preStop hook and the application’s graceful SIGTERM handling consume the same Pod termination grace window; a successful hook is not sufficient evidence that the application received enough shutdown time. Kubernetes’ current lifecycle documentation and API reference state that the countdown begins before the hook, the normal stop signal follows the hook, and forcible termination can occur when the grace period expires with processes still running. Release acceptance should prove that relationship with deletion timestamps, hook markers, application signal evidence, EndpointSlice state and terminal container status.
For engineers who want to practice the wider discipline behind that process, Refonte Learning’s DevOps Engineer program currently lists Linux and scripting, CI/CD, Docker and Kubernetes, Terraform, cloud platforms, monitoring and logging, and a capstone among its stated competencies; the page also describes a three-month program with a stated 12–14 hours per week. The page does not specifically list this preStop shutdown-budget experiment. The broader evidence practice is to pin the environment, construct the negative control, preserve independent observations, reconcile partial state, and make the release decision from the boundary you actually measured.