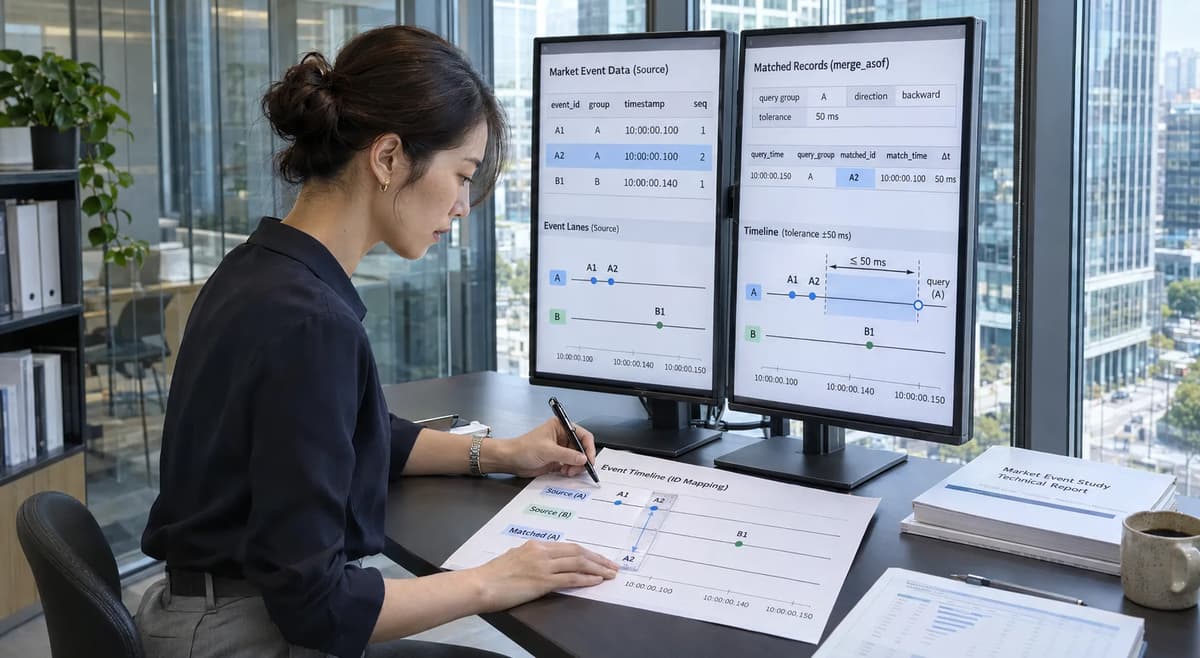
A non-null merge_asof result is weak evidence. It proves that pandas found a row satisfying the mechanics of the call; it does not prove that the row represents the business event you intended. The distinction becomes operationally important when timestamps are duplicated, groups overlap in time, tolerance boundaries sit close to adjacent events, or a migration changes ordering assumptions.
For pandas 2.2.3, the documented contract is precise about the search dimension: direction="backward" selects the last eligible right-hand row at or before the left key, direction="forward" selects the first eligible row at or after it, and direction="nearest" selects the row whose key is closest in absolute distance. by constrains matching to equal group keys, tolerance limits admissible distance, and both sides must be ordered by the as-of key. Those are library semantics, not an event-identity policy. The documentation does not promise a business interpretation for two distinct events carrying the same timestamp.
This playbook treats that gap as a release-acceptance problem. I executed a disposable local fixture before writing the observed-result sections. The run used CPython 3.13.5, pandas 2.2.3 and NumPy 2.3.5 on Linux; it exited with status 0 and emitted zero warnings. The fixture deliberately contains duplicate timestamps, a competing group, tolerance boundaries, an exact-match exclusion case, and an unsorted-input rejection case. The resulting decision is not simply “pandas works.” It is narrower: ACCEPT the explicitly grouped directional cases under the pinned contract; REPAIR any workflow that omits grouping; RERUN after any relevant version, fixture, ordering or policy change; HOLD any release whose correctness depends on an undocumented duplicate tie-break for nearest.
Define the Operational Contract, Fixture and Release Gate
Define the Operational Contract and Release Gate. The unit of correctness is the event identity, not merely the matched timestamp. In this fixture, a right-hand event is identified by the tuple (entity, event_ts, event_seq, event_id). Two rows may legitimately share entity and event_ts; therefore timestamp equality alone cannot establish identity.
The version-pinned pandas merge_asof documentation says the operation performs a distance-based left-style match, requires ordering by the match key, supports grouping with by, permits a compatible tolerance, and lets the caller control exact matches and search direction. In pandas 2.2.3 specifically, backward means the last eligible right row at or before the key, forward means the first at or after it, and nearest means minimum absolute key distance.
That wording produces a useful but incomplete event contract. Backward and forward tell us how equal keys relate to “last” and “first” in the ordered right frame. Nearest specifies distance but does not separately document which physical row wins when multiple right rows have the same nearest timestamp. That distinction matters enough that this playbook treats nearest-with-duplicate-identity as a release boundary rather than silently promoting an observation to an API guarantee.
The acceptance gate is therefore:
Evidence condition | Release interpretation |
Right input is ordered by the as-of key and duplicate order is pinned by an explicit event-sequence policy | Necessary precondition |
by matches the declared entity boundary | Necessary when event identity is group-scoped |
Observed event ID equals the independently authored expected event ID | Required for acceptance |
Match distance is inside the declared tolerance | Required for matched cases |
Expected unmatched cases remain unmatched | Required negative boundary evidence |
Negative control fails identity in the predicted way | Demonstrates that the test can detect the target defect |
Warnings, versions, command status and hashes are retained | Required reproducibility evidence |
A case depends only on undocumented duplicate selection under nearest | HOLD, even if the current version happens to return the locally preferred event |
This is deliberately different from Refonte’s pandas resample bin membership article. That page asks which interval owns a boundary event under closed, label and origin rules; it builds an integer interval oracle and reconciles event-to-bin membership. The present problem is not time-bucket assignment. It is one-to-one event identity after a distance join.
The executed fixture used this independently authored manifest. The manifest was written as data before pandas results were reconciled; no expected event ID is calculated by calling merge_asof.
{
  "contract_revision": "merge-asof-event-identity-v1",
  "identity_key": ["entity", "event_ts", "event_seq", "event_id"],
  "duplicate_policy": {
    "backward": "latest eligible timestamp; highest sequence at equal timestamp",
    "forward": "earliest eligible timestamp; lowest sequence at equal timestamp",
    "nearest": "closest timestamp; duplicate-row tie is treated as version-observed"
  },
  "cases": [
    ["C01", "backward", true, 100, true,  "10:00:00.100", "A", "A2"],
    ["C02", "forward",  true, 100, true,  "10:00:00.100", "A", "A1"],
    ["C03", "nearest",  true, 100, true,  "10:00:00.100", "A", "A2"],
    ["C04", "backward", false,100, true,  "10:00:00.150", "A", "A2"],
    ["C05", "backward", true, 50,  true,  "10:00:00.150", "A", "A2"],
    ["C06", "backward", true, 49,  true,  "10:00:00.150", "A", null],
    ["C07", "forward",  true, 50,  true,  "10:00:00.150", "A", "A3"],
    ["C08", "backward", true, 100, false, "10:00:00.100", "A", "A0"],
    ["C09", "backward", true, 100, true,  "10:00:00.100", "A", null]
  ]
}
The full manifest used for execution is retained as manifest.json. Its SHA-256 at execution was 137ccad9d551a2620c51eea830e786124bbf1a9f44c9e57b1edb8e6aa1c28395.
Capture the Baseline and Versioned Environment. At the time of the fixture review, the general pandas documentation resolved to pandas 3.1.1, whereas the fixture ran pandas 2.2.3. The newer page used slightly updated wording about ascending order and grouping-column sorting, so this playbook uses the 2.2.3 documentation whenever it describes the executed contract rather than assuming newer documentation is identical to the installed release.
The recorded environment was:
CPython 3.13.5
pandas 2.2.3
NumPy 2.3.5
Linux 6.18.57-x86_64, glibc 2.41
command exit status: 0
warnings captured: 0
stderr: empty
The environment evidence was recorded in environment.json; command status is in command_status.txt, and the captured warning stream is warnings.log.
The release rule is simple: if the exact runtime differs, the result is not inherited. It becomes a RERUN candidate. That is particularly important where acceptance depends on ordering among duplicate keys or on a case not explicitly guaranteed by the version-pinned API.
Construct the Controlled Fixture and Independent Oracle
Construct a Disposable Controlled Fixture. The right-hand event table contains only five synthetic events. It has no external service dependency and no production credentials. The data are intentionally small enough that an engineer can inspect every candidate by eye.
event_id | entity | event_ts | event_seq | purpose |
A0 | A | 10:00:00.000 | 0 | prior event |
A1 | A | 10:00:00.100 | 1 | first duplicate |
A2 | A | 10:00:00.100 | 2 | second duplicate |
B1 | B | 10:00:00.140 | 1 | nearer competing group |
A3 | A | 10:00:00.200 | 3 | next event |
The source snapshot used by the run is right_events.csv, SHA-256 2146770f87e2642ec929d02b8d747dca134377fdf6cf1ee1324e9b759f454ec8.
Pin Inputs and Isolate Side Effects. Before matching, the fixture canonicalizes duplicate order explicitly:
right = raw.sort_values(
    ["event_ts", "event_seq", "event_id"],
    ignore_index=True,
)
assert right["event_ts"].is_monotonic_increasing
assert right["event_id"].is_unique
The reason for pinning order is not cosmetic. The pandas sort_values documentation distinguishes stable and unstable algorithms and notes that the kind parameter applies directly to single-column DataFrame sorting. If duplicate-key identity matters, relying on incidental incoming order is an avoidable source of migration risk; the fixture therefore gives duplicate rows an explicit sequence key instead.
A concrete boundary is query A @ 10:00:00.150. For grouped backward matching, A2 is 50 ms behind and A3 is 50 ms ahead. A backward call may only consider A2 among those two; a forward call may only consider A3. With a 50 ms tolerance both are admissible in their respective directions. With backward tolerance reduced to 49 ms, A2 must no longer be accepted by the local case manifest. The measurable assertions are therefore “C05 returns A2” and “C06 returns no event.”
This problem is separate from the pandas GroupBy dropna reconciliation page. That article audits whether nullable grouping keys cause source rows to disappear from an aggregate. Here, every synthetic row remains present; by="entity" is a matching boundary that prevents a nearer event from another entity from becoming the selected identity.
Define an Independent Evidence Oracle. An independent oracle must not simply invoke pandas a second time with slightly different syntax. The oracle for these cases is a literal case manifest plus human-auditable predicates:
For backward: restrict to the declared entity, keep right timestamps <= query_ts, reject distances greater than tolerance, and choose the latest eligible timestamp. At the duplicate A timestamp, the local business rule orders event sequence and therefore expects A2.
For forward: restrict to the entity, keep timestamps >= query_ts, enforce tolerance, and choose the earliest eligible timestamp. At the duplicate A timestamp, the local sequence rule expects A1.
For allow_exact_matches=False, equality is inadmissible. Therefore query A at 10:00:00.100 cannot choose A1 or A2; backward falls to A0, exactly 100 ms earlier.
For the negative control, intentionally remove by. Query A at 10:00:00.150 then sees B1 at 10:00:00.140, only 10 ms behind, while the latest A event is at 10:00:00.100, 50 ms behind. A non-null result is therefore possible while event identity is wrong.
For the unsorted case, the expected observation is an exception rather than an event. The 2.2.3 API states that both input frames must be sorted by the match key.
The complete executable harness is fixture.py, SHA-256 93bc0ed2bdd81df2aa1f1ab51b0f86d47d61e29d8e90b974d70c77a52e8643fc. Its core path is reproduced below:
from future import annotations
import json
import warnings
from pathlib import Path

import pandas as pd
from pandas.testing import assert_frame_equal

ROOT = Path(__file__).resolve().parent
manifest = json.loads((ROOT / "manifest.json").read_text())

def t(value):
    return pd.Timestamp(value)

raw = pd.DataFrame(
    [
        ("A0", "A", t("2026-01-01 10:00:00.000"), 0),
        ("A1", "A", t("2026-01-01 10:00:00.100"), 1),
        ("A2", "A", t("2026-01-01 10:00:00.100"), 2),
        ("B1", "B", t("2026-01-01 10:00:00.140"), 1),
        ("A3", "A", t("2026-01-01 10:00:00.200"), 3),
    ],
    columns=["event_id", "entity", "event_ts", "event_seq"],
)

right = raw.sort_values(
    ["event_ts", "event_seq", "event_id"],
    ignore_index=True,
)

assert right["event_ts"].is_monotonic_increasing
assert right["event_id"].is_unique
assert right.loc[
    right.duplicated(["entity", "event_ts"], keep=False),
    "event_id",
].tolist() == ["A1", "A2"]

def execute(case):
    left = pd.DataFrame(
        {
            "case_id": [case["case_id"]],
            "entity": [case["entity"]],
            "query_ts": [pd.Timestamp(case["query_ts"])],
        }
    )

    candidate_right = right.copy(deep=True)

    if case["case_id"] == "C09":
        candidate_right = candidate_right.iloc[
            [4, 0, 1, 2, 3]
        ].reset_index(drop=True)

    kwargs = {
        "left": left,
        "right": candidate_right,
        "left_on": "query_ts",
        "right_on": "event_ts",
        "direction": case["direction"],
        "tolerance": pd.Timedelta(
            milliseconds=case["tolerance_ms"]
        ),
        "allow_exact_matches": case["allow_exact_matches"],
    }

    if case["by"]:
        kwargs["by"] = "entity"

    observed = None
    exc_type = None
    exc_message = None

    try:
        out = pd.merge_asof(**kwargs)
        if pd.notna(out.loc[0, "event_id"]):
            observed = str(out.loc[0, "event_id"])
    except Exception as exc:
        exc_type = type(exc).__name__
        exc_message = str(exc)

    if case["expect_exception"]:
        raw_match = exc_type == case["expect_exception"]
    else:
        raw_match = (
            exc_type is None
            and observed == case["expected_event_id"]
        )

    if case["control"] == "negative_expected_mismatch":
        harness_pass = (
            exc_type is None
            and observed != case["expected_event_id"]
        )
    else:
        harness_pass = raw_match

    return {
        "case_id": case["case_id"],
        "expected_event_id": case["expected_event_id"],
        "observed_event_id": observed,
        "exception_type": exc_type,
        "exception_message": exc_message,
        "raw_identity_match": raw_match,
        "harness_pass": harness_pass,
    }

with warnings.catch_warnings(record=True) as records:
    warnings.simplefilter("always")
    ledger = pd.DataFrame(
        execute(case) for case in manifest["cases"]
    )

expected_directional = pd.DataFrame(
    {
        "case_id": ["C01", "C02"],
        "expected_event_id": ["A2", "A1"],
    }
)

observed_directional = ledger.loc[
    ledger["case_id"].isin(["C01", "C02"]),
    ["case_id", "observed_event_id"],
].rename(
    columns={"observed_event_id": "expected_event_id"}
).reset_index(drop=True)

assert_frame_equal(
    observed_directional,
    expected_directional,
    check_dtype=False,
)

assert ledger["harness_pass"].all()
assert len(records) == 0
The equality assertion uses the version-pinned pandas.testing.assert_frame_equal, which pandas documents as a DataFrame comparison helper intended primarily for tests and capable of checking structural and dtype differences with configurable strictness.
Reproduce Misleading Success and Run the Contrasting Correctness Cases
Reproduce the Misleading Success Case. Case C04 is the important negative control because it succeeds syntactically and fails semantically.
The query is:
entity = A
query timestamp = 10:00:00.150
direction = backward
tolerance = 100 ms
by = omitted intentionally
The independent contract expects A2. Within entity A, the latest eligible event is A2 at 10:00:00.100, 50 ms before the query. But without grouping, B1 at 10:00:00.140 becomes eligible and is only 10 ms behind.
The executed observation was:
C04 expected event: A2
C04 observed event: B1
raw_identity_match: False
negative-control harness_pass: True
That is exactly the failure pattern this playbook is designed to catch. A row matched. The timestamp distance looked even better than the intended A event. The result was nevertheless the wrong event because group identity was lost.
The version-pinned API explicitly provides by to match equivalent group keys before searching the on key. Omitting it therefore changes the search domain rather than merely affecting presentation.
Record the Negative Control Before Repair. Preserve the C04 output before changing code. A negative control is valuable only if the pre-repair state remains reviewable. The ledger row records both the expected identity and the observed B1 identity; the retained CSV is evidence_ledger.csv.
A specific measurable assertion is stronger than “the unsafe branch should fail.” In this fixture the assertion is:
neg = ledger_df.loc[ledger_df["case_id"] == "C04"].iloc[0]
assert neg["observed_event_id"] == "B1"
assert neg["observed_event_id"] != neg["expected_event_id"]
If a future fixture change makes this negative control start returning A2 accidentally, the test should be redesigned rather than celebrated. A control that can no longer expose the defect no longer proves detection sensitivity.
Run a Contrasting Correctness Case. C01 and C02 isolate duplicate identity while keeping the entity boundary intact. Both query A exactly at 10:00:00.100, where A1 and A2 share the same timestamp.
The observed results were:
Case | Direction | Grouped | Expected | Observed | Status |
C01 | backward | yes | A2 | A2 | PASS |
C02 | forward | yes | A1 | A1 | PASS |
These observations line up with the documented “last eligible” wording for backward and “first eligible” wording for forward, given the fixture’s explicit ordering of A1 before A2.
That still does not mean every arbitrary duplicate dataset is safe. The event-sequence order has to be part of the local contract. If equal-time rows arrive in a different order and you sort only on timestamp using an order-preserving algorithm, the physical first/last duplicate can change with source order. If event identity matters, canonicalize duplicates with an authoritative sequence or reject the ambiguity instead of pretending timestamp is unique.
This is where the problem differs from Refonte’s scikit-learn column order and feature identity validation. That page asks whether values reach the feature coordinates learned by a fitted model even when shape remains valid. The common operational lesson is identity-over-plausibility, but the failure mechanism here is temporal candidate selection, not model feature positioning.
Explore Failure and Boundary Conditions. C05 through C09 put pressure on the contract rather than repeating the happy path.
C05 used backward direction, grouping, query 10:00:00.150 and tolerance exactly 50 ms. A2 was observed. C06 changed only tolerance to 49 ms, and no event was observed. Those two cases provide direct runtime evidence that the boundary used by this pandas 2.2.3 fixture admits the 50 ms candidate and rejects the same candidate at 49 ms. The API documents tolerance as selecting as-of matches “within this range”; the precise local boundary observation is therefore recorded as executed evidence rather than inflated into a cross-version claim.
C07 used forward direction at the same query time and 50 ms tolerance. It selected A3 at 10:00:00.200, as the directional predicate requires. C08 used backward direction at the duplicate timestamp but set allow_exact_matches=False; the exact A1/A2 rows were excluded and A0 was selected 100 ms earlier. The API explicitly documents that False changes the comparison from inclusive to strict.
C09 deliberately scrambled the right-hand as-of key. The observed exception was:
ValueError: right keys must be sortedThat is consistent with the documented ordering precondition.
Check Missing and Duplicate Evidence. Duplicate evidence is not itself a defect. In the executed input, only A1 and A2 share (entity, event_ts), and the fixture asserts their sequence values are [1, 2]. The defect would be an undefined or unstable rule for choosing between them when the release claims event identity.
The missing-match control is C06. Its measurable assertion is not “output is falsy”; it is “event_id is missing while the left query row survives.” merge_asof is structurally similar to a left join: unmatched left rows remain and right-side values are missing. That distinction matters when reconciling query coverage.
Capture Per-Case Evidence and Reconcile Expected Identity
Capture Complete Per-Case Evidence. A usable audit ledger has to record enough context to explain why a row was accepted or rejected without rerunning immediately. The executed ledger stores case ID, control type, direction, grouping state, tolerance, exact-match policy, expected identity, observed identity, observed sequence and timestamp, expected exception, actual exception, raw identity comparison and harness interpretation.
The complete observations were:
Case | Expected | Observed | Evidence interpretation |
C01 | A2 | A2 | backward duplicate, grouped, PASS |
C02 | A1 | A1 | forward duplicate, grouped, PASS |
C03 | A2 | A2 | nearest duplicate, OBSERVED PASS but not sufficient for portable acceptance |
C04 | A2 | B1 | deliberate missing-group negative control, expected mismatch demonstrated |
C05 | A2 | A2 | 50 ms backward boundary admitted |
C06 | no match | no match | 49 ms backward boundary rejected |
C07 | A3 | A3 | 50 ms forward boundary admitted |
C08 | A0 | A0 | exact duplicates excluded |
C09 | ValueError | ValueError | unsorted right input rejected |
All nine declared controls behaved according to the manifest. That means the harness passed; it does not mean all nine represent acceptable application configurations. C04 is intentionally unsafe. C03 deserves a HOLD classification if a release contract depends on exactly which duplicate row nearest returns.
The key artifact hashes from execution were:
fixture.py
93bc0ed2bdd81df2aa1f1ab51b0f86d47d61e29d8e90b974d70c77a52e8643fc

manifest.json
137ccad9d551a2620c51eea830e786124bbf1a9f44c9e57b1edb8e6aa1c28395

right_events.csv
2146770f87e2642ec929d02b8d747dca134377fdf6cf1ee1324e9b759f454ec8

evidence_ledger.csv
ecd6233129fad50bfa0d9db01be42cc6ec091a9706fff1d6e7dc107136a27734

environment.json
0f4463cb2560069ca3b32da140aacd0307d242625d8ebd6550c9d96d4b574195

warnings.log
e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855
The empty-file SHA-256 for the warning log is expected because no warnings were captured. The full checksum inventory, including stdout, stderr, command status and result JSON, is retained in sha256sums.txt.
Reconcile Expected and Observed Identities. Reconciliation should use ordinary equality logic, not another as-of match. For multi-row ledgers, a normal relational merge is useful because it makes missing expected or observed cases visible and can validate cardinality.
The version-pinned DataFrame.merge documentation describes both indicator=True, which identifies left-only/right-only/both provenance, and validate=, which can enforce uniqueness expectations such as one-to-one joins.
A reconciliation pattern is:
reconciled = expected_cases.merge(
    observed_cases,
    on="case_id",
    how="outer",
    indicator=True,
    validate="one_to_one",
    suffixes=("_expected", "_observed"),
)

reconciled["identity_equal"] = (
    reconciled["event_id_expected"]
    .fillna("<NO_MATCH>")
    .eq(
        reconciled["event_id_observed"]
        .fillna("<NO_MATCH>")
    )
)

assert reconciled["_merge"].eq("both").all()
The important comparison is identity, not just timestamp distance. Two distinct events may share one timestamp, and one nearer timestamp may belong to another group.
That provenance emphasis is related to, but does not duplicate, Refonte’s pandas reindex fill values and missing-value provenance. The reindex article distinguishes observed zeros from inserted zeros under a structural-zero policy. Here the provenance dimension is which source event became the matched identity.
Retain Failure Artifacts Before Rerun. When C04 fails identity, do not overwrite its ledger row after adding by="entity". Preserve the unsafe output, the source snapshot and the manifest, then run the corrected path into a new evidence file or revision.
A specific release assertion can be:
assert bad["expected_event_id"] == "A2"
assert bad["observed_event_id"] == "B1"

assert repaired["expected_event_id"] == "A2"
assert repaired["observed_event_id"] == "A2"
Both are evidence. The first proves the defect was reproducible; the second proves the proposed repair addressed the targeted case.
Separate Documented Behavior From Observation and Repair Safely
Separate Documented Behavior From Observation. Release notes and acceptance records should distinguish four categories.
“Documented” means the version-pinned primary source states the behavior: backward uses the last right key at or before the left key; forward uses the first at or after; nearest uses minimum absolute key distance; by constrains group equality; tolerance limits distance; exact-match behavior can be disabled; inputs must be ordered.
“Manifest expectation” means the fixture’s independent policy declares a specific event identity. That is application evidence, not a pandas promise.
“Observed” means the executable run produced a value under the captured environment. C03 observed A2 for nearest at a duplicated exact timestamp. That is a valid local observation.
“Inference” means a reviewer draws a maintenance conclusion. The relevant inference here is that a release should not depend on C03’s exact duplicate-row selection unless the application first removes ambiguity itself. This follows because the API specifies nearest timestamp distance but does not separately specify a duplicate-row tie policy.
The distinction prevents a common migration error: a current behavior gets copied into a test, the test passes for years, and the behavior gradually acquires the status of “contract” even though no primary source promised it.
The same discipline appears in Refonte’s SciPy curve_fit covariance scaling validation, where the page separates documented absolute_sigma semantics from a bounded numerical experiment. The subject is unrelated to merge_asof; the shared lesson is the separation of API contract, observed runtime evidence and scientific or business interpretation.
Repair the Workflow Without Masking Errors. For the C04 class of defect, the repair is not “take the closest result and relabel it.” The repair changes candidate eligibility by enforcing the missing group dimension:
safe = pd.merge_asof(
    left,
    right,
    left_on="query_ts",
    right_on="event_ts",
    by="entity",
    direction="backward",
    tolerance=pd.Timedelta("100ms"),
)
That addresses cross-entity leakage, but duplicate identity still needs an explicit precondition. If event sequence is authoritative, canonicalize right-hand ordering before the as-of operation. If duplicate events cannot be ordered by a trustworthy rule, reject or quarantine the ambiguous candidate set instead of allowing timestamp alone to invent identity.
For nearest matching, an even safer design is to separate candidate discovery from identity resolution when exact duplicate identity matters. Use merge_asof only where its documented timestamp contract is sufficient, or pre-collapse/validate duplicate timestamps according to a business rule before joining. Do not encode the current observed A2 result as though pandas had documented “highest sequence wins for nearest duplicates.”
Explain the Scope of the Fix. The repair fixes candidate-domain leakage and deterministic duplicate ordering for the tested schema. It does not prove upstream timestamps are correct, that event sequence represents business precedence, or that every future entity has the same semantics.
A measurable boundary is C04: after grouping is restored, its observed identity must move from B1 to A2 without changing the raw event table. Another is C03: even though it observed A2, the release status remains HOLD if the consuming application requires a pandas-guaranteed duplicate tie policy that the API does not state.
This is why using DataFrame.merge(..., validate=...) for ordinary reconciliation does not substitute for validating merge_asof. merge can enforce cardinality on its own equality keys, but merge_asof solves a different nearest-key problem and exposes a different set of identity risks.
Test Recovery, Rollback, Rerun Safety and Apply the Decision Matrix
Test Recovery, Rollback and Rerun Safety. A repair is releasable only if an engineer can return to an unmodified source snapshot and reproduce both the defect and the corrected result.
The recovery sequence is:
Retain the original event fixture, expected manifest, unsafe ledger, runtime versions, warnings, stdout/stderr and hashes.
Apply the repair to code or configuration, not to the failed output.
Rerun from the retained source snapshot.
Compare the new ledger with the independent manifest.
If pandas, Python, NumPy, ordering logic, tolerance, direction, grouping fields, duplicate policy or fixture input changes, mark the previous evidence stale and rerun the entire case set.
If source provenance is missing or hashes cannot be reconciled, HOLD rather than reconstructing identity from the already-joined output.
That is also rollback safety. The rollback target is not “whatever table existed before repair”; it is a known source-and-contract state with reproducible artifacts. A failed as-of output can contain a perfectly plausible wrong event, so it is not a safe reconstruction source.
The executed run recorded execution.stderr as empty and exit status 0; those results were recorded in execution.stderr and command_status.txt. The evidence does not establish behavior on another pandas release.
Apply the Acceptance and Ownership Matrix.
Decision | Trigger | Evidence required | Owner/recovery implication |
ACCEPT | Documented semantics and local identity contract agree; grouped directional cases reconcile exactly; required negative controls behave as designed | Version capture, input/manifest hashes, case ledger, zero unexplained exceptions | Release owner accepts only the tested contract and artifacts |
REPAIR | A recoverable configuration defect produces a wrong identity, such as omitted by | Preserved failing case plus corrected rerun from unchanged source | Workflow owner changes matching configuration and reruns |
RERUN | Runtime version, candidate ordering, tolerance, direction, grouping key, duplicate policy, source fixture or manifest changes | Fresh environment capture and regenerated ledger/hashes | Migration/release owner invalidates prior execution evidence |
HOLD | Event identity is ambiguous, source provenance is missing, or acceptance relies on an undocumented duplicate tie-break | Explicit unresolved condition in ledger/release note | Data owner or interface owner must define policy before release |
Record ACCEPT, REPAIR, RERUN or HOLD. The final decision for this executed fixture is deliberately split by case, because collapsing the whole exercise to one green/red status would hide the important distinction.
C01 and C02 are ACCEPT for the pinned fixture and contract. Their event identities agree with the independently authored manifest and with documented backward/forward first/last semantics applied to a deterministically ordered right frame.
C04 is REPAIR as an application configuration. The omission of by produced B1 instead of A2 while returning a syntactically valid match. The evidence is decisive because the negative control was designed before the repair and behaved exactly as predicted.
C05 through C09 are ACCEPT as regression evidence for this pinned runtime: the 50 ms boundary admitted A2, 49 ms rejected it, forward selected A3, exact-match exclusion selected A0, and unsorted input raised ValueError. They should be RERUN after a relevant runtime or contract change.
C03 is HOLD for any release claim that requires pandas to guarantee which duplicate event wins under nearest. The actual run returned A2, and the manifest expected A2, but the 2.2.3 API describes nearest-key distance rather than a separate duplicate-row tie guarantee. A local observation is not enough authority to convert that implementation behavior into a portable event-identity contract.
The measurable release assertion is therefore not all_declared_controls_passed == True by itself. The stronger condition is: every case required by the release must map to ACCEPT under documented semantics or an application-owned deterministic policy; no required case may remain HOLD.
Release Conclusions and Related Skills
The operational conclusion is narrow. merge_asof can correctly satisfy its timestamp search contract and still select the wrong application event if the candidate domain is wrong. Grouping is therefore not an optional descriptive field when identity is group-scoped. Tolerance is not a quality score; it is an eligibility boundary. Duplicate timestamps are not harmless if event identity extends beyond time. And a passing nearest-match test is not a sufficient release gate when the exact duplicate tie-break you depend on is not part of the documented API.
The safest acceptance record contains three independent layers: a version-pinned documented contract, an independently authored expected-case manifest, and an executed evidence ledger. Where those agree, accept narrowly. Where a known parameter defect explains the mismatch, repair from retained source and rerun. Where environment or contract state changes, rerun rather than inheriting evidence. Where identity remains ambiguous or depends on undocumented behavior, hold.
Build Related Skills With Refonte Learning. Refonte Learning’s Data Engineering program page describes a three-month program with a stated dedication of 12–14 hours per week, requires applicants to be engaged in bachelor’s or postgraduate study, mentions a virtual internship opportunity, and lists curriculum areas including data warehousing and ETL, big-data technologies and data-pipeline design. It also states that successful completion can result in a Training Certificate and a Certificate of Internship. The page does not establish specialized instruction in this merge_asof validation protocol.
For engineers who want structured practice around the broader data-engineering context in which this kind of validation sits, the program offers a related learning path. The release standard remains the same regardless of training source: define identity before the join, preserve the evidence that can falsify your assumption, and accept only the behavior the contract and the executed ledger actually support.