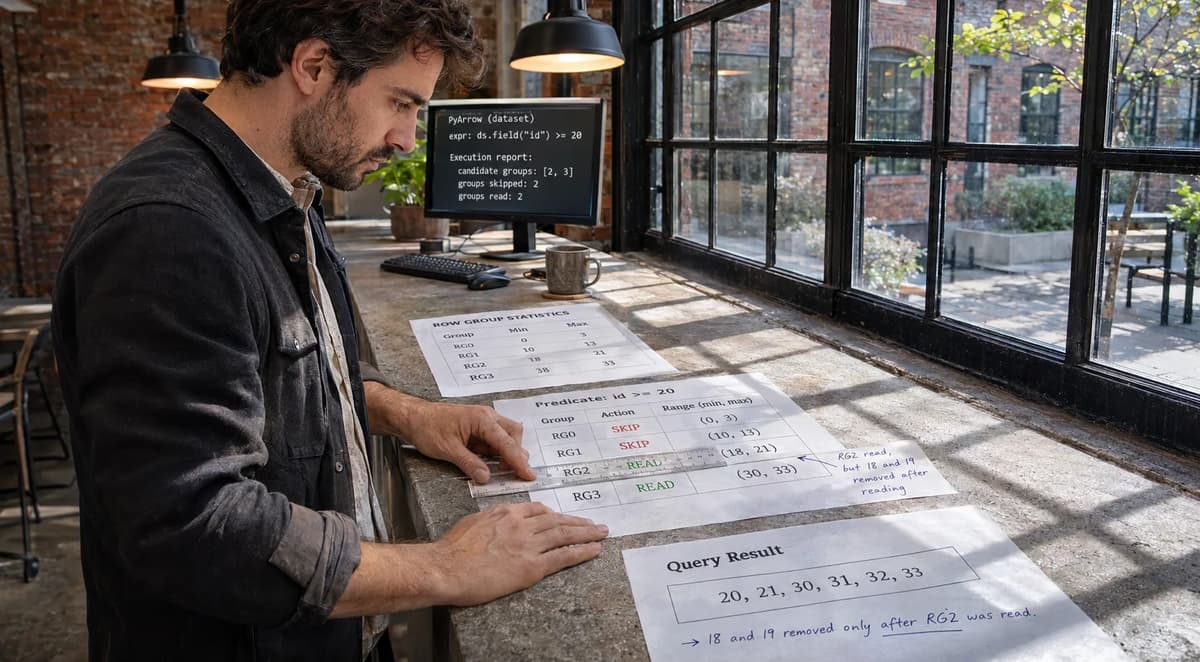
A filtered Parquet read that returns fewer rows is not evidence that any row group was skipped. That result is compatible with two materially different execution paths: the reader can reject a whole row group from its Parquet metadata before reading its data, or it can read a row group and remove nonmatching rows afterward. PyArrow documents both sides of that distinction. Its Parquet guide states that read filters can skip entire row groups from their min/max statistics; its Dataset scanner documentation also states that, when predicate pushdown cannot exploit partition or internal metadata, rows can instead be filtered from loaded record batches.
The release question is therefore not:
“Did the filtered result contain fewer rows?”It is:
“For every row group that the predicate made impossible from metadata alone, can we prove that PyArrow classified that row group as excludable from its statistics, independently of the final row count?”
That wording deliberately separates the apparent success signal from the state under test.
This playbook treats PyArrow row-group statistics pruning as an acceptance problem. The fixture is synthetic and disposable. The runtime is pinned. Expected row-group eligibility is calculated independently of the scan result. Metadata, filter output, and row-group selection evidence are retained separately. A negative control is mandatory. Any result that cannot distinguish Parquet statistics pruning from post-read filtering is a HOLD, not an ACCEPT.
The current documented baseline used here is PyArrow 26.0.1, released November 3, 2026. Apache Arrow lists 26.0.1 as the current release, and its official Python wheels bundle the Arrow and Parquet C++ libraries. PyArrow 26.0.1 supports Python 3.11 through 3.14.
This article does not report the synthetic cases as executed observations. The cases and outputs below are marked EXPECTED / NOT EXECUTED. Consequently, the operational decision for the fixture itself is HOLD pending execution, even though the documented API behavior is sufficient to specify the expected manifest.
Acceptance contract
The acceptance contract is concrete:
Assertion | Required evidence | Reject when |
Runtime identity is exact | python, pyarrow.__version__, pyarrow.cpp_version, platform capture | Version differs or is missing |
Fixture contains known row groups | ParquetFile.num_row_groups, per-group row counts | Layout differs from manifest |
Statistics exist where pruning is claimed | column metadata plus statistics.has_min_max | Required min/max absent |
Expected eligibility is independent | JSON manifest calculated from known synthetic ranges, not scan output | Expected set derived from actual filtered result |
Candidate pruning is inspectable | ParquetFileFragment.split_by_row_group(filter=...) row-group IDs | Only final row count is available |
Post-read filtering remains distinguishable | all row groups read explicitly, then Arrow compute filter applied | Comparison path also prunes |
Negative control survives | overlapping-statistics group remains a candidate although some rows fail predicate | Test would classify it as skipped |
Release evidence is complete | raw metadata, manifest, candidate set, result rows, hashes, version capture | Any mandatory artifact missing |
A related Refonte Learning article on Kubernetes shutdown-budget validation asks a methodologically similar question: whether a visible successful event proves the lifecycle state that actually matters. Its domain is unrelated to Parquet, so it is useful only as an adjacent operational-validation pattern, not as evidence for Arrow behavior. The article describes evidence-based lifecycle acceptance around preStop and termination state.
Pin the documented and versioned baseline
The file-format premise is stable and predates this 2026 release. A Parquet file is divided into row groups; file metadata records the locations of the corresponding column chunks. Parquet deliberately separates file metadata from data so readers can navigate the file using metadata before consuming column data.
For this experiment, the relevant metadata is the statistics attached to a column chunk in each row group. PyArrow exposes these through ParquetFile.metadata, row-group metadata, column-chunk metadata, and Statistics. The statistics interface exposes has_min_max, min, max, null count and related properties.
PyArrow’s current Parquet documentation is explicit about the behavior being tested: supplying filters pushes predicates into the reader and can skip entire row groups based on min/max values stored in row-group metadata. The same documentation describes row-group skipping from column statistics as automatic when filters are applied.
The Dataset API gives us a particularly useful validation surface. ParquetFileFragment.split_by_row_group(filter=...) returns row-group fragments and documents that row groups whose metadata contradicts the filter are excluded using Parquet row-group statistics. That is stronger diagnostic evidence than a reduced result count because it exposes the candidate row-group set directly.
At the same time, do not overstate what the Dataset scanner promises. Its filter contract says the scan returns matching rows; when possible it pushes predicates down to partition information or internal metadata such as Parquet statistics, and otherwise it filters loaded record batches before yielding them. A correct final row set therefore does not imply a particular pruning path.
Use the following reproducibility boundary:
CPython: 3.13.5
pyarrow: 26.0.1
Arrow C++: capture from pyarrow.cpp_version; expected to correspond
           to the bundled 26.0.1 wheel, but record the observed string
Package source: official PyPI wheel
Parquet format version written by fixture: explicitly set to "2.6"
Compression: NONE
Dictionary encoding: disabled for target column
Statistics: enabled
Threads: disabled for scan paths where deterministic diagnostic ordering matters
Filesystem: local disposable directory
The decision to use PyArrow 26.0.1 is not a claim that pruning first appeared there. It is a versioned behavior boundary for the acceptance run. Arrow’s install documentation states that its PyPI wheels bundle the Arrow and Parquet C++ libraries; the 26.0.1 release is a patch release whose published changes include security and unrelated bug fixes, not a declaration that row-group statistics filtering is new.
Runtime command and rejection boundary
Create an isolated virtual environment and refuse silent drift:
python3.13 -m venv .venv
. .venv/bin/activate

python -m pip install --upgrade pip
python -m pip install 'pyarrow==26.0.1'

python - <<'PY'
import json
import platform
import sys
import pyarrow as pa

actual = {
    "python": platform.python_version(),
    "python_executable": sys.executable,
    "pyarrow": pa.__version__,
    "arrow_cpp": pa.cpp_version,
    "platform": platform.platform(),
}

print(json.dumps(actual, indent=2, sort_keys=True))

assert actual["python"] == "3.13.5", actual
assert actual["pyarrow"] == "26.0.1", actual
PY
Boundary case: the operator runs the fixture under 26.0.0, 25.0.1, a source build, or an unrecorded C++ library combination.
Expected result: the guard fails or the run is assigned a new manifest identity.
Rejection criterion: evidence from a different runtime is mixed into the 26.0.1 acceptance ledger and presented as if it were the same case.
The official installation documentation confirms that PyArrow 26.0.1 supports Python 3.13, so this pin is within the documented compatibility envelope.
Build the reproducible fixture and independent expected-case manifest
The fixture needs row groups whose statistics make three situations obvious:
a group that the predicate definitely cannot match;
a group that can match and contains only qualifying rows;
a group whose min/max overlap the predicate even though only some rows qualify.
That third group is the negative control. Statistics pruning is conservative. If min/max cannot disprove the predicate for the entire row group, the group must remain a candidate even if row-level filtering later discards most of its rows.
Use four row groups of four rows each:
Row group | id values | Min | Max | Predicate id >= 20 | Manifest status |
RG0 | 0, 1, 2, 3 | 0 | 3 | impossible | exclude |
RG1 | 10, 11, 12, 13 | 10 | 13 | impossible | exclude |
RG2 | 18, 19, 20, 21 | 18 | 21 | possible | retain |
RG3 | 30, 31, 32, 33 | 30 | 33 | certain for all non-null rows | retain |
The expected candidate set is therefore {RG2, RG3}. The final matching row IDs are {20, 21, 30, 31, 32, 33}.
Those are different assertions. RG2 is expected to be read-eligible from statistics even though two of its rows should later fail id >= 20. If your harness expects RG2 to be pruned, it is testing an impossible standard rather than Parquet statistics pruning.
Create the fixture with explicit row groups:
# build_fixture.py
from pathlib import Path
import json
import pyarrow as pa
import pyarrow.parquet as pq

ROOT = Path("parquet-pruning-lab")
ROOT.mkdir(exist_ok=False)
PATH = ROOT / "fixture.parquet"

groups = [
    [0, 1, 2, 3],
    [10, 11, 12, 13],
    [18, 19, 20, 21],
    [30, 31, 32, 33],
]

writer = pq.ParquetWriter(
    PATH,
    pa.schema([
        ("id", pa.int64()),
        ("payload", pa.string()),
    ]),
    version="2.6",
    compression="NONE",
    use_dictionary=False,
    write_statistics=True,
)

try:
    for rg, ids in enumerate(groups):
        writer.write_table(
            pa.table({
                "id": ids,
                "payload": [f"rg{rg}-row{i}" for i in range(len(ids))],
            })
        )
finally:
    writer.close()

manifest = {
    "case": "id_ge_20",
    "predicate": "id >= 20",
    "expected_total_row_groups": 4,
    "expected_candidate_row_groups": [2, 3],
    "expected_pruned_row_groups": [0, 1],
    "expected_matching_ids": [20, 21, 30, 31, 32, 33],
    "negative_control_row_group": 2,
    "negative_control_reason":
        "min=18,max=21 overlaps predicate; group cannot be rejected from min/max",
}

(ROOT / "expected.json").write_text(
    json.dumps(manifest, indent=2, sort_keys=True) + "\n"
)
Writing each four-row table separately through one ParquetWriter gives the fixture explicit row-group boundaries. ParquetFile exposes num_row_groups, metadata, and explicit read_row_group / read_row_groups operations for inspecting and reading those units.
A related Refonte Learning page on SQLite WAL backup committed-row validation uses an independent expected-state ledger to prevent a superficially valid artifact from defining its own acceptance criteria. Its database semantics are unrelated to Parquet; the useful overlap is the testing discipline of separating expected state from the success signal under examination.
Preserve the negative control
The negative control is RG2:
values: 18, 19, 20, 21
statistics: min=18, max=21
predicate: id >= 20
The group contains matching and nonmatching rows. Its maximum does not contradict id >= 20, so statistics cannot eliminate the whole group.
Expected result: RG2 remains in the statistics-selected candidate list, and row-level filtering later returns only 20 and 21.
Rejection criterion: a test claims “statistics pruning worked” merely because 18 and 19 are missing from the final table. Their absence proves filtering, not row-group skipping.
Now inspect metadata before any filtered scan:
# inspect_metadata.py
from pathlib import Path
import json
import pyarrow.parquet as pq

path = Path("parquet-pruning-lab/fixture.parquet")
pf = pq.ParquetFile(path)

rows = []
for rg_id in range(pf.num_row_groups):
    rg = pf.metadata.row_group(rg_id)
    col = rg.column(0)
    stats = col.statistics
    rows.append({
        "row_group": rg_id,
        "num_rows": rg.num_rows,
        "is_stats_set": col.is_stats_set,
        "has_min_max": None if stats is None else stats.has_min_max,
        "min": None if stats is None else stats.min,
        "max": None if stats is None else stats.max,
    })

print(json.dumps(rows, indent=2))
PyArrow documents the metadata path used here and shows RowGroupMetaData, column metadata and statistics including has_min_max, min, max, and null count.
The expected metadata ledger is:
[
  {"row_group": 0, "num_rows": 4, "has_min_max": true, "min": 0,  "max": 3},
  {"row_group": 1, "num_rows": 4, "has_min_max": true, "min": 10, "max": 13},
  {"row_group": 2, "num_rows": 4, "has_min_max": true, "min": 18, "max": 21},
  {"row_group": 3, "num_rows": 4, "has_min_max": true, "min": 30, "max": 33}
]
Status: EXPECTED / NOT EXECUTED.
Reproduce the misleading success and run the controlled comparison
First reproduce the signal that creates the diagnostic ambiguity:
# misleading_success.py
import pyarrow.parquet as pq

path = "parquet-pruning-lab/fixture.parquet"

result = pq.read_table(
    path,
    filters=[("id", ">=", 20)],
    use_threads=False,
)

print(result.to_pydict())
assert result["id"].to_pylist() == [20, 21, 30, 31, 32, 33]
The expected result has six rows instead of sixteen. PyArrow’s read_table API says rows that do not match the filter predicate are removed from scanned data and supports within-file filtering. Its Parquet guide separately documents row-group skipping from statistics. Both mechanisms can contribute to the same returned table.
Therefore:
16 source rows -> 6 returned rowsdoes not establish:
2 source row groups -> skippedThe final count is an effect-level observation. It does not identify which row groups were eliminated before data scanning.
The controlled comparison needs three paths.
Path A: explicit all-group read plus post-read filtering.
# post_read_control.py
import pyarrow.compute as pc
import pyarrow.parquet as pq

path = "parquet-pruning-lab/fixture.parquet"

pf = pq.ParquetFile(path)
all_groups = pf.read_row_groups(
    list(range(pf.num_row_groups)),
    columns=["id", "payload"],
    use_threads=False,
)

post = all_groups.filter(pc.field("id") >= 20)

assert all_groups.num_rows == 16
assert post["id"].to_pylist() == [20, 21, 30, 31, 32, 33]ParquetFile.read_row_groups() accepts an explicit list of row groups and reads those groups. That makes Path A the post-read control: the harness itself requests every row group before the Arrow table filter is applied.
Path B: ask Parquet metadata which row groups remain possible.
# candidate_groups.py
import json
import pyarrow.dataset as ds

path = "parquet-pruning-lab/fixture.parquet"
expr = ds.field("id") >= 20

dataset = ds.dataset(path, format="parquet")
fragments = list(dataset.get_fragments())
assert len(fragments) == 1

candidate_fragments = fragments[0].split_by_row_group(filter=expr)

candidate_ids = []
for frag in candidate_fragments:
    # each returned fragment represents a row-group subset;
    # row_groups exposes the selected row-group metadata.
    candidate_ids.extend(rg.id for rg in frag.row_groups)

print(json.dumps(candidate_ids))
assert candidate_ids == [2, 3]
The documented contract for split_by_row_group(filter=...) is exactly what this validation needs: it splits a Parquet file fragment by row group and excludes row groups whose metadata contradict the optional predicate, using Parquet row-group statistics.
Path C: normal filtered Dataset scan.
# filtered_scan.py
import pyarrow.dataset as ds

path = "parquet-pruning-lab/fixture.parquet"
expr = ds.field("id") >= 20

dataset = ds.dataset(path, format="parquet")
table = dataset.to_table(
    columns=["id", "payload"],
    filter=expr,
    use_threads=False,
)

assert table["id"].to_pylist() == [20, 21, 30, 31, 32, 33]
The Dataset API documents that filter expressions are pushed into partition information or internal metadata such as Parquet statistics when possible; otherwise filtering occurs on loaded record batches.
The point of the three-way comparison is not to benchmark speed. It is to establish different propositions:
Path | What it can establish |
Explicit all-group read + Arrow filter | correct answer obtainable with no row-group exclusion |
split_by_row_group(filter) | metadata says RG0/RG1 contradict predicate, RG2/RG3 remain candidates |
Filtered scan | user-facing result is correct under the production-style filter |
A Refonte Learning article on Java periodic-task exception validation makes an adjacent distinction between a visible executor signal and the actual task lifecycle. Its useful connection is the validation method; it does not document Arrow behavior.
Assert the failure boundary
The acceptance test should fail when metadata and final results are accidentally conflated:
assert candidate_ids == [2, 3]
assert set(candidate_ids) != {3}  # RG2 is the required negative control.
A second assertion verifies the difference between candidate rows and returned rows:
pf = pq.ParquetFile(path)
candidate_table = pf.read_row_groups(candidate_ids, use_threads=False)

assert candidate_table.num_rows == 8
assert table.num_rows == 6
Expected interpretation:
candidate row groups: 2, 3
rows physically represented by candidates: 8
rows satisfying predicate: 6
That difference is the proof that row-group statistics pruning and post-read row filtering are distinct stages of the reasoning. Statistics can discard RG0 and RG1. RG2 cannot be discarded by its min/max and therefore requires row-level evaluation.
Status for all three paths: EXPECTED / NOT EXECUTED.
Test failure cases, capture raw evidence, and reconcile actual state
A validation fixture that proves only its happy path is fragile. The following boundary cases should be part of the manifest before execution.
Case | Change | Expected row-group candidate set | Expected final IDs | Status |
C1 | id >= 20 | [2,3] | 20,21,30,31,32,33 | EXPECTED / NOT EXECUTED |
C2 | id > 33 | [] | none | EXPECTED / NOT EXECUTED |
C3 | id >= 18 | [2,3] | 18,19,20,21,30,31,32,33 | EXPECTED / NOT EXECUTED |
C4 | id == 19 | [2] | 19 | EXPECTED / NOT EXECUTED |
C5 | statistics disabled on write | cannot approve pruning from min/max | same logical result as C1 | EXPECTED / NOT EXECUTED |
C6 | overlapping RG2 negative control | RG2 retained | only 20,21 from RG2 | EXPECTED / NOT EXECUTED |
C2 is useful because every row group’s maximum is below the requested value. If statistics exist and the filter can be evaluated from them, the filtered fragment list should be empty.
C5 is more important operationally. Write an otherwise identical fixture with write_statistics=False:
writer = pq.ParquetWriter(
    path,
    schema,
    version="2.6",
    compression="NONE",
    use_dictionary=False,
    write_statistics=False,
)
The correct conclusion is not “PyArrow definitely reads all groups” unless you separately instrument and establish that fact. The safe conclusion is narrower: the min/max evidence required by this acceptance protocol is missing, so statistics-pruning acceptance is not demonstrated. The scanner may have other applicable optimizations in other fixtures, and the Dataset contract permits fallback filtering after records are loaded.
Capture evidence before interpretation:
mkdir -p parquet-pruning-lab/evidence

python runtime.py \
  > parquet-pruning-lab/evidence/runtime.json

python inspect_metadata.py \
  > parquet-pruning-lab/evidence/metadata.json

cp parquet-pruning-lab/expected.json \
   parquet-pruning-lab/evidence/expected.json

python candidate_groups.py \
  > parquet-pruning-lab/evidence/candidates.json

python misleading_success.py \
  > parquet-pruning-lab/evidence/filtered-result.txt

python post_read_control.py \
  > parquet-pruning-lab/evidence/post-read-control.txt

sha256sum parquet-pruning-lab/fixture.parquet \
  > parquet-pruning-lab/evidence/fixture.sha256

sha256sum parquet-pruning-lab/evidence/* \
  > parquet-pruning-lab/evidence/artifacts.sha256
The evidence ledger should preserve provenance rather than just pass/fail:
Evidence ID | Artifact | Assertion | Classification |
E01 | runtime.json | exact runtime identity | observation after execution |
E02 | fixture.sha256 | tested file identity | observation after execution |
E03 | metadata.json | four row groups; statistics present; exact min/max | observation after execution |
E04 | expected.json | independent expected candidate and result sets | predeclared expectation |
E05 | candidates.json | filtered metadata candidate IDs | observation after execution |
E06 | filtered result | returned row IDs | observation after execution |
E07 | post-read control | same logical IDs after explicit all-group read | observation after execution |
E08 | negative-control assertion | RG2 retained despite partial mismatch | observation after execution |
E09 | no-statistics case | required pruning evidence unavailable | observation after execution |
E10 | decision record | ACCEPT / REPAIR / RERUN / HOLD | reviewer decision |
Before execution, E01–E10 are NOT EXECUTED except E04, which is an EXPECTED manifest, not observed state.
Detect missing evidence
A missing artifact must not silently become a false value.
from pathlib import Path

required = [
    "runtime.json",
    "fixture.sha256",
    "metadata.json",
    "expected.json",
    "candidates.json",
    "filtered-result.txt",
    "post-read-control.txt",
    "artifacts.sha256",
]

missing = [
    name for name in required
    if not Path("parquet-pruning-lab/evidence", name).is_file()
]

if missing:
    raise SystemExit(f"HOLD: missing evidence: {missing}")
Boundary case: filtered rows look correct, but metadata.json or candidates.json was not retained.
Expected decision: HOLD.
The reason is simple: a correct logical answer alone cannot discriminate statistics pruning from post-read filtering.
Reconciliation then compares four independent quantities:
assert manifest["expected_candidate_row_groups"] == candidate_ids
assert manifest["expected_matching_ids"] == filtered_ids
assert filtered_ids == post_read_filtered_ids
assert metadata_min_max == [
    (0, 3),
    (10, 13),
    (18, 21),
    (30, 33),
]
Do not derive expected_candidate_row_groups by asking PyArrow for the candidate groups and writing that result back into the expected file. That destroys independence.
A related Refonte Learning article on pandas missing-key row reconciliation asks whether apparently plausible output omitted source rows and uses an independent population reconciliation. Its mechanism is pandas grouping semantics, rather than Parquet metadata pruning.
Separate documentation, observation, inference, repair, and rerun safety
The evidence packet should classify every statement. Experienced reviewers should be able to tell which claims come from the format/API contract and which came from one run.
Documented behavior. Parquet stores file metadata separately from column data and exposes row-group/column-chunk structure. PyArrow exposes column statistics and documents filter-based row-group skipping from min/max statistics. split_by_row_group(filter) documents exclusion of row groups whose statistics contradict the predicate. Dataset scanners document both pushdown where possible and loaded-batch filtering otherwise.
Expected result. For this synthetic fixture, RG0 and RG1 have maximum values lower than 20; RG2 spans 18–21; RG3 spans 30–33. Therefore the predeclared expected candidate set for id >= 20 is RG2/RG3. This is fixture arithmetic, not a report of a PyArrow run.
Observation. Only values captured by an executed fixture belong here: actual pyarrow version, actual metadata, actual candidate IDs returned from the fragment API, actual result IDs, actual hashes.
Inference. If the executed candidate list is [2,3], the metadata is the expected four-range layout, and the normal filtered scan returns the declared six rows, it is reasonable to infer that statistics prove RG0/RG1 unnecessary for that predicate in this fixture. The inference is bounded to the tested file, filter, runtime and API path. The supporting contract is split_by_row_group(filter) itself.
Do not turn that into “no bytes from RG0/RG1 were ever fetched from storage” unless you add I/O-level instrumentation appropriate to your filesystem and reader. Metadata-level row-group exclusion and byte-level transport accounting are related but different evidence questions. This playbook’s release gate is intentionally scoped to row-group eligibility from Parquet statistics versus row-level filtering.
Measure the repair boundary
The smallest safe repair depends on the failed assertion.
If statistics is None or has_min_max is false for the target column, repair the fixture or upstream writer configuration if statistics are part of the production contract. PyArrow’s metadata API gives you the evidence to detect that boundary.
If metadata ranges differ from the manifest, do not change the manifest to make the run green. Rebuild the fixture from a clean directory and verify its identity.
If candidate row groups differ from the independently expected set, HOLD and investigate the predicate, schema, statistics representation, runtime version and API semantics.
If candidate groups are correct but final row IDs are wrong, the failure is downstream of candidate pruning: filter semantics, fixture contents or result reconciliation require investigation.
If the filtered result is correct but the candidate-set artifact is absent, the repair is evidence capture, not a change to the data path.
If only the negative control fails, reject the test harness. A harness that cannot distinguish “row group cannot be ruled out” from “every row matches” cannot validate this mechanism.
Rollback and rerun are intentionally simple because the fixture is isolated:
rm -rf parquet-pruning-lab
python build_fixture.py
python inspect_metadata.py
python candidate_groups.py
python filtered_scan.py
python post_read_control.py
A rerun must produce a new evidence directory or overwrite only a disposable, explicitly owned one. Never mix an old expected.json, new Parquet file, and stale candidates.json.
Hash the fixture before every run. If the file hash changes, treat it as a different specimen even if the filename is identical.
A related Refonte Learning article on Ansible check-mode coverage validation separates “task appeared in the run” from “validator actually executed.” Its focus is configuration-management validation rather than data-format behavior.
Release gate and limitations
The final release decision must be explicit.
Decision | Evidence rule | Required action |
ACCEPT | exact runtime; expected metadata; expected candidate groups; expected result rows; negative control retained; post-read control agrees logically; evidence complete | approve only the tested version/file/filter contract |
REPAIR | cause is identified in fixture, writer settings, evidence capture, or validation logic | make the smallest change, rebuild from clean state, then rerun all controls |
RERUN | environment or artifact changed but no semantic defect is established | create a fresh evidence packet under the new identity |
HOLD | missing evidence, version drift, contradictory metadata, candidate-set mismatch, negative-control failure, or unexecuted acceptance suite | do not claim row-group pruning validation |
The fixture cases are EXPECTED / NOT EXECUTED, so the operational status is:
DECISION: HOLD

Reason:
The documented behavior and executable acceptance design are established,
but no synthetic test run is represented here as observed evidence.

Required transition:
Execute the pinned fixture, populate E01-E10, reconcile actual candidate
row groups and final rows, then choose ACCEPT / REPAIR / RERUN / HOLD.
The documented contract does not establish an observed test result.
The limitations are equally important. This protocol validates min/max row-group statistics for a deliberately simple int64 predicate in one local Parquet file. It does not claim identical selectivity for strings, timestamps, decimals, nested columns, null-heavy columns, corrupted files, encrypted files, remote object stores, partition pruning, page-index pruning, Bloom filters or arbitrary compound expressions. PyArrow’s current Parquet documentation explicitly notes, for example, that its reader does not currently use Parquet Bloom filters during read filtering, so Bloom-filter behavior should not be smuggled into a statistics-pruning conclusion.
Likewise, pq.read_table(..., filters=...) and Dataset APIs can perform filtering beyond metadata elimination. The scanner contract expressly allows post-load filtering when pushdown cannot be applied.
The acceptance boundary should therefore be written like this:
Proven:
For the pinned PyArrow runtime and synthetic fixture, row groups whose
recorded min/max contradict the predicate are absent from the
filter-qualified row-group fragment set, while an overlapping group
remains and receives row-level filtering.

Not proven:
Universal physical I/O elimination, every Parquet optimization,
every predicate type, every filesystem, or behavior outside the
captured version boundary.
Operational ownership
Assign ownership before approval:
Artifact or decision | Owner |
fixture generator | test author |
expected manifest | reviewer independent of scan-result generation |
runtime/package provenance | platform or build owner |
Parquet writer settings | data producer owner |
metadata and candidate capture | acceptance operator |
negative-control integrity | test reviewer |
release decision | named release authority |
evidence retention | release engineering |
Ownership matters because “rerun until green” is not a release policy. A candidate-set mismatch should be investigated by someone authorized to decide whether the behavior, fixture, or release boundary changed.
For engineers developing this kind of evidence discipline more broadly, Refonte Learning currently lists a Data Engineering Program. Its catalog page describes it as an entry-level Data Engineering program and currently lists a three-month period, a 12–14-hours-per-week dedication, a virtual internship component, and topics including data pipelines, big-data analytics, Hadoop, storage, data governance, security and data protection. The program page also lists a student requirement.
Reproducible fixtures, explicit state contracts, data-pipeline validation and reconciliation are operational data-engineering skills. The program page is not evidence for any PyArrow behavior.
Acceptance criteria
The fixture combines four controlled Parquet row groups, independently declared min/max expectations, a deliberately overlapping negative-control group, an explicit all-row-group read followed by post-read filtering, and split_by_row_group(filter) as independent state evidence.
That makes the release criterion unambiguous:
A smaller filtered table is insufficient.
ACCEPT requires independent evidence that:
the expected statistics exist;
the declared impossible row groups are excluded from the
statistics-qualified candidate set;the overlapping negative-control row group remains a candidate;
row-level filtering then removes only its nonmatching rows;
the observed evidence reconciles with a manifest written before
the scan result was known.
PyArrow already documents filter pushdown, Parquet already documents metadata, and Dataset APIs already expose row-group filtering. The engineering contribution here is a bounded release-acceptance workflow that refuses to mistake the right answer for proof of how the reader arrived there.