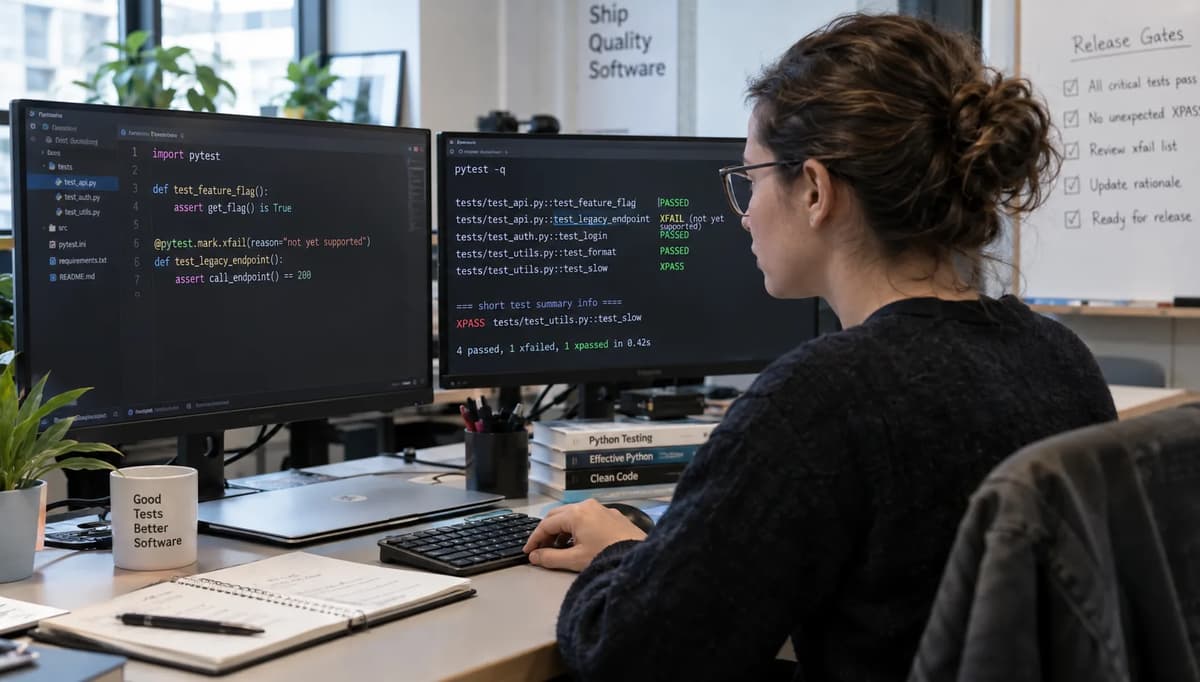
A test marked as “expected to fail” (xfail) can inadvertently signal that everything is fine when it passes unexpectedly (XPASS). In QA automation, we must distinguish a genuine fix from a misleading green signal. This playbook treats xfail metadata as formal exception policy rather than mere test labels. We define clear owners, scopes, and review conditions for every xfail, and four decisions: ACCEPT (keep the exception active), REPAIR (fix code or test), HOLD (investigate conflicting/absent results), or RETIRE (remove the mark).
Each pytest run is reproduced under a pinned environment so that outcomes (node IDs, reasons, stdout/stderr, exit code) form exact evidence. For example, pytest 8.4.2 (released Sept 3, 2025) on CPython 3.13 is our baseline. We record the CWD, selected config file/rootdir, node IDs, and all markers or overrides used. This ensures we know if, say, a passing test ran under strict=False (default) or a stricter rule. The goal is to audit the meaning of XPASS outcomes: was the defect actually fixed, or are we simply silencing it? (For broader QA context see QA automation and release evidence practices.) The right decision is not to celebrate every XPASS; it’s to gather exact evidence (outcome tokens and exit codes) and then accept, repair, hold, or retire per policy.
1. Define what an expected-failure exception permits
Marking a test as xfail signals a known defect with an owner (usually the dev team) and a resolution plan. The test remains in the suite to ensure regression coverage. By default, pytest will still run the test and not treat its failure as a suite failure. That means an expected fail (XFAIL) and even an unexpected pass (XPASS) will produce exit code 0 (success) unless strict mode is enabled. This expected-failure “exception” has: (1) an owner (a developer or product manager tracking the bug); (2) a scope (the specific input or condition that triggers the known bug); (3) an expiry/review condition (a fixed date, version, or requirement for re-validation); and (4) one of four decisions at review time. The decisions are:
ACCEPT: The marked exception is valid and should be carried forward. The suite’s XFAIL outcome matches the documented bug (exit code 0 under non-strict mode).
REPAIR: The test or code must be fixed. This happens when the observed outcome doesn’t match the known defect (e.g. a different exception occurs). A repair implies updating the code or narrowing the xfail marker’s scope.
HOLD: Results are contradictory or incomplete. For example, the test didn’t run at all (run=False), or the suite exit is ambiguous (a separate failure occurred). HOLD means don’t approve nor retire; investigate further.
RETIRE: The defect is gone and the xfail can be removed. This requires that the fix is committed, the test passes normally, and a clean run (with the mark removed) succeeds on the approved invocation.
In other words, an xfail is a controlled exception in the release rule, not an “approved bugfix.” A correct decision distinguishes test outcome (XFAIL/XPASS) from release intent (accept the risk, fix it, etc.). For example, under default pytest behavior, an XPASS will not fail the job, but your release gate might still require developer review if an XPASS is detected. Conversely, strict XPASS mode (see below) would force the job to fail, serving as an explicit gate. We will generate evidence (child-process results, exit codes, stdout/stderr) for each marked test so the decision can be made in writing.
2. Pin pytest and the invocation that sets the policy
We use pytest 8.4.2 on CPython 3.13 as our fixed baseline. (pytest 8.4.2 was released on 2025-09-03.) In a clean virtualenv with no extra plugins, we ensure the environment is identical every run. We record:
Python and pytest versions (e.g. python --version yields 3.13.x; pytest --version yields 8.4.2).
Installed packages (pip freeze) or a lockfile.
Exact working directory and rootdir (pytest prints rootdir/configfile at startup).
The pytest.ini or pyproject.toml found (we use one of them to set defaults).
For example, we might have a pytest.ini with:
[pytest]
minversion = 8.4
xfail_strict = False  # explicit default strictness
This makes sure we are not relying on version-specific defaults. (pytest 9.0 renames this to strict_xfail.) We can override these in-code with markers or at run time (-o xfail_strict=...). We also log plugin list (none extra), selected node IDs, and any relevant PYTEST_ADDOPTS or environment overrides.
The test invocation is explicit. For instance:
pytest -q -ra --strict-markers test_parser.py::test_expected_failureHere -q quiet mode and -ra (report on xfail summary) are just examples; they can be adjusted. pytest will output something like: “rootdir: /path/to/project, configfile: /path/to/project/pytest.ini”. We capture the pytest configuration header to know which config was in effect. If a CI run was green, it may have used a different strictness flag or even --runxfail. That is why we audit with a well-documented invocation. For example, we might run:
result = subprocess.run(
    ["pytest", "--version"], capture_output=True, text=True
)
print("Pytest version:", result.stdout.strip())
# Pytest version: pytest 8.4.2
Run a similar check with python --version. The idea is to prove exactly what policy was applied, rather than assume.
2.1 A green job may have run a different exception rule
Importantly, a “green” CI build doesn’t prove a bug is fixed; it might have simply used non-strict mode. By default (xfail_strict=False), an XPASS will still yield exit code 0. If the project wanted to enforce review on XPASS, it should have set xfail_strict = True globally or used @pytest.mark.xfail(strict=True). Otherwise a fixed test that was marked xfail will quietly XPASS. Thus, we must check: Which strictness was in effect? If the pipeline wasn’t using strict mode, the XPASS wouldn’t fail the run. Only with strict mode would it.
As a negative control, we’ll reproduce both scenarios. We should explicitly capture config.inifile and check for xfail_strict values. For example, if the header shows xfail_strict = True, then XPASS would break the build. If it shows False or none, XPASS would pass silently. The pytest documentation states: “Both XFAIL and XPASS don’t fail the test suite by default. You can change this by setting the strict parameter to True”.
3. Build a defect fixture with an independent assertion
We create a tiny regression example: a “parser” function with a known bug. We define a custom exception class and three variants of the function: bad (produces the known bug), fixed (correct implementation), and unrelated (raises a different error). For concreteness:
# test_parser.py

class KnownDefectError(Exception):
    pass
def parser_bad(x):
# Known defect: '42' should be parsed to 42, but we raise KnownDefectError instead.
if x == "BAD_INPUT":
raise KnownDefectError("Intentional defect for BAD_INPUT")
return int(x) + 1def parser_fixed(x):
# Fixed behavior: properly convert string to int.
return int(x) + 1def parser_unrelated(x):
# Unrelated error: wrong type concatenation triggers TypeError.
# e.g., int("BAD_INPUT") + 1 is a ValueError, but here we do something else.
return x + 1 # if x is str, this raises TypeErrorEach test uses a simple assertion (or expected exception) on a single input. We mark them with xfail in various ways:
import pytest

# 1. Known bug: raises KnownDefectError as expected.
@pytest.mark.xfail(raises=KnownDefectError, reason="Bug: BAD_INPUT not parsed")
def test_expected_failure():
    parser_bad("BAD_INPUT")  # raises KnownDefectError
# 2. Fixed code: no exception, but marked xfail -> XPASS.
@pytest.mark.xfail(raises=KnownDefectError, reason="Bug: BAD_INPUT not parsed")
def test_unexpected_pass():
parser_fixed("BAD_INPUT") # no exception -> XPASS# 3. Wrong exception (narrow): raises TypeError, not in raises -> FAILURE.
@pytest.mark.xfail(raises=KnownDefectError, reason="Bug: BAD_INPUT not parsed")
def test_wrong_exception_narrow():
parser_unrelated("BAD_INPUT") # raises TypeError -> failure# 4. Wrong exception (broad): no raises argument, so any failure is expected (XPASS for
# our scenario).
@pytest.mark.xfail(reason="Bug: BAD_INPUT not parsed")
def test_wrong_exception_broad():
parser_unrelated("BAD_INPUT") # raises TypeError -> XFAIL (as any error is allowed)# 5. Marked not to run (run=False): test not executed.
@pytest.mark.xfail(run=False, reason="Crash by design (skip execution)")
def test_not_run():
print("This should NOT run")
assert FalseEach test has a stable node ID (test_parser.py::test_expected_failure, etc.) and a clear defect ID in the reason. The assertions (or exceptions) are independent of the xfail scope. Note how tests 3 and 4 both trigger a TypeError, but we’ve marked them differently to illustrate “narrow” vs “broad” expectations. We will run these in subprocesses individually and together to capture outcomes.
4. Observe the non-strict unexpected-pass case
We first run the fixed implementation under a non-strict xfail marker. In our example, test_unexpected_pass is marked xfail(raises=KnownDefectError), but the code raises no exception. By default, this yields XPASS and pytest continues without error (exit code 0). In code, we might do:
import subprocess

result = subprocess.run(
    ["pytest", "-q", "test_parser.py::test_unexpected_pass"],
    capture_output=True, text=True
)
print("Exit code:", result.returncode)
print(result.stdout.splitlines()[-2:])
Expected output (similar to pytest’s summary):
Exit code: 0
XPASS test_parser.py::test_unexpected_pass - Bug: BAD_INPUT not parsed
Here -q suppresses much of the output, but the key line is XPASS .... The return code 0 indicates “all tests passed or xfailed as expected”. Although an unexpected situation occurred (an XPASS happened), pytest’s non-strict default treated it as a success. This demonstrates the “misleading” green signal: pytest itself shows XPASS, but exit code 0 means the suite is passing. A team policy might require a review when XPASS occurs, but here pytest alone won’t fail.
We see that the node outcome was XPASS, yet the whole-process status was 0. It’s crucial to separate those two. If other tests in the same run failed, the return code would be 1 despite this XPASS (see next section). Therefore, when assessing XPASS, we run the case in isolation. In summary: an XPASS under non-strict mode produces exit 0, which by itself would not block a release even though our policy might call for human review. This is why we log both the XPASS token and the exit code as evidence for the release decision.
4.1 Separate node outcome from whole-process status
Pytest’s exit code reflects any failure in the suite, not just the marked test. For example, if we run multiple tests together:
pytest -q test_parser.py::test_unexpected_pass test_parser.py::test_expected_failureThe results would show one XPASS and one XFAIL, but exit code 0 (no failures). If we include a failing test (like test_wrong_exception_narrow), exit code becomes 1, even though test_unexpected_pass itself had only XPASS. Thus, we always isolate test cases when checking XPASS behavior. The important point is that a zero exit code can hide an XPASS if nothing else fails. Conversely, a nonzero exit code may be caused by an unrelated failure (like our TypeError test), not by XPASS. Therefore, every subprocess run is done with exactly one node or a known small group, and we record which node’s outcome influenced the returncode. In this way we don’t misattribute the exit status.
5. Make strict XPASS an explicit review boundary
To enforce review when an xfail test passes, we use strict mode. pytest allows @pytest.mark.xfail(strict=True) or a global ini xfail_strict = true. In our fixture, add a strict marker:
@pytest.mark.xfail(
    strict=True,
    raises=KnownDefectError,
    reason="Strict mode: unexpected pass should fail",
)
def test_strict_unexpected_pass():
    parser_fixed("BAD_INPUT")  # no exception, XPASS -> cause failure
Running this test:
result = subprocess.run(
    ["pytest", "-q", "test_parser.py::test_strict_unexpected_pass"],
    capture_output=True, text=True
)
print("Exit code:", result.returncode)
print(result.stdout.splitlines()[-2:])
Expected:
Exit code: 1
XPASS test_parser.py::test_strict_unexpected_pass - Strict mode: unexpected pass should fail
The XPASS line appears, but strict mode makes pytest return code 1 (failure). Thus an XPASS has become a failing gate. If the project had xfail_strict = true globally, then any xfail with no strict marker would be treated strictly. Conversely, a marker can explicitly override. For instance, if we set xfail_strict = true in pytest.ini and then use @pytest.mark.xfail(strict=False), that test will not fail on XPASS.
It’s important to note: strictness does not fix the defect itself. It only changes whether XPASS fails the suite. Whether strict is set on marker or via config, the underlying code is unchanged. Strict mode is purely a review boundary. We must still ultimately fix or accept the defect separately.
6. Prove that the expected failure is the intended failure
Marking an xfail with a broad exception can mask new issues. In our example, both calls to parser_unrelated("BAD_INPUT") trigger TypeError, but only one is the known issue. By using raises=KnownDefectError, we narrowly state which exception we expect. In test_wrong_exception_narrow, a TypeError occurs, which is not KnownDefectError, so pytest reports a failure (not XFAIL). If we hadn’t specified raises, pytest would treat the TypeError as an expected failure under the broad xfail. In other words, matching on exception class alone isn’t enough to identify the defect; an unrelated bug can produce the same exception type. We must prove we caught the intended defect.
The docs confirm this: if a test fails with an exception not mentioned in raises, it is reported as a regular failure. For example, in test_wrong_exception_narrow the TypeError causes a failure. But in test_wrong_exception_broad (no raises argument), pytest simply counts it as XFAIL. This demonstrates that a broad xfail “absorbs” the TypeError into the expected-fail bucket, whereas a narrow xfail flags it.
6.1 An exception type is not a complete defect identity
Consider if two different bugs both raise ValueError. A broad @pytest.mark.xfail(raises=ValueError) would hide any ValueError. If our known bug expected a specific message or context, we could instead write a post-condition or use a custom exception (like KnownDefectError) to distinguish it. In our toy example, we could narrow even further by checking message content, but pytest’s raises parameter only checks type. The takeaway is: do not assume an exception type uniquely identifies your defect. By specifying raises=KnownDefectError, we ensure that only that known issue is expected. A mismatched TypeError will not be treated as expected, forcing a fix or investigation. (For reference, the docs say: “the test will be reported as a regular failure if it fails with an exception not mentioned in raises”.)
7. Audit configuration precedence and overrides
We test combinations of defaults, marker arguments, and -o overrides. Assume our pytest.ini set xfail_strict = true by default. We try:
Default strictness (True) with no strict marker. An XPASS test should fail.
Marker strict=False override. The same XPASS should now not fail.
Marker strict=True (redundant if default is true, but explicit).
Command-line override: pytest -o xfail_strict=False to flip strictness at runtime.
For example:
# With default strict=True (ini), running non-strict marker:
pytest -q test_parser.py::test_unexpected_pass
This yields XPASS but exit code 1 (due to default strictness). Then:
# Override with -o to make strict=False just for this run:
pytest -q -o xfail_strict=False test_parser.py::test_unexpected_pass
Now XPASS returns exit code 0. Finally:
# Marker override:
pytest -q test_parser.py::test_parser_strict_unexpected_pass
pytest -q test_parser.py::test_parser_strict_override
(where test_parser_strict_override uses strict=False on marker). We check each run’s header for “xfail_strict” in the config and note the return codes. This confirms how pytest resolves strictness: marker-level strict= takes precedence over ini. Also, using -o xfail_strict=False dynamically makes the test non-strict for that session. The pytest documentation describes how the ini option xfail_strict (older name) can be set and how --runxfail ignores markers entirely (see below). We do not use --strict-markers here, since that only checks marker names at collection time and does not affect xfail logic. (Indeed, --strict-markers is a separate control and should not be confused with xfail strictness.)
7.1 Strict marker-name validation is a different control
Note: pytest’s --strict-markers flag is unrelated to xfail strictness. It merely tells pytest to error on unknown markers. It does not change XFAIL/XPASS handling. Our focus here is only on strict= in pytest.mark.xfail() or the xfail_strict config.
8. Separate skipped, not-run, and executed tests
We also test the boundaries of not executed tests. A test marked with xfail(run=False) should be not run but reported as XFAIL. In our example, test_not_run has run=False. Running:
pytest -q test_parser.py::test_not_runWe should see something like XFAIL test_parser.py::test_not_run - Crash by design (skip execution) with no “print” output from inside the test. Indeed, pytest will show it as XFAIL with a note (often reason [NOTRUN] if no custom reason was given). The print statement inside should never appear in stdout, confirming the body didn’t execute. We verify this by capturing stdout and ensuring it does not contain our sentinel.
For skipped tests: pytest.skip() or @pytest.mark.skip would show SKIPPED in the summary, not XFAIL. We might have a skipped test as a control. Crucially, none of these (XFAIL[NOTRUN], SKIPPED, or even XFAIL[FAIL] from runxfail) are executed. We treat them separately: XFAIL with run=False is expected and not an error; skip is also not an error.
Finally, if pytest collects no tests at all (e.g. a node ID doesn’t exist or filters all tests), pytest returns exit code 5. This is not a success: code 5 means “no tests collected,” which we interpret as missing coverage (likely an error in test selection or config). We must catch that case (e.g. subprocess.returncode==5) and treat it as a hold/misconfiguration, not silently accept the mark.
9. Capture a reproducible subprocess outcome ledger
Every run is encapsulated via subprocess.run([...]) with no shell, capturing stdout and stderr and checking return codes. For example:
import subprocess

cmd = ["pytest", "-q", "--disable-warnings", f"{nodeid}"]
result = subprocess.run(cmd, capture_output=True, text=True, timeout=10)
ledg_entry = {
    "node": nodeid,
    "returncode": result.returncode,
    "stdout": result.stdout,
    "stderr": result.stderr
}
We include capture_output=True and text=True to get string outputs, and timeout to avoid hangs. This produces a CompletedProcess whose .stdout, .stderr, and .returncode we can log. (In pytest’s header, we will also record the rootdir, configfile, and full cmd arguments for traceability.) According to the Python subprocess documentation, CompletedProcess.returncode is the exit status (0 for success) and .stdout/.stderr contain the captured text. We check the return code manually rather than using check=True so we can handle both 0 and nonzero as data. This ledger can be formatted as JSON or a table. The important part is that each row has the node ID, the implementation variant, marker reason/strict setting, and the raw outputs. For example:
Node ID | Function Variant | Markers | Result | Returncode | Notes |
test_expected_failure | parser_bad | xfail(strict=False) | XFAIL | 0 | KnownDefectError raised |
test_unexpected_pass | parser_fixed | xfail(strict=False) | XPASS | 0 | Unexpected pass |
test_strict_unexpected_pass | parser_fixed | xfail(strict=True) | XPASS | 1 | |
test_wrong_exception_narrow | parser_unrelated | xfail(strict=False) | FAIL | 1 | TypeError not allowed |
test_wrong_exception_broad | parser_unrelated | xfail(strict=False) | XFAIL | 0 | TypeError considered XFAIL |
test_not_run | (n/a) | xfail(run=False) | XFAIL | 0 | Not executed |
Each entry here would be accompanied by captured stdout/stderr in a real audit log. The key is that we preserve the exact evidence of what happened, rather than summarizing it.
10. Use runxfail as an audit: not a retirement shortcut
pytest’s --runxfail flag turns off xfail handling and runs those tests as normal. This is a read-only audit mode, not a way to permanently remove the exception. For example, running:
pytest -q --runxfail \
    test_parser.py::test_expected_failure \
    test_parser.py::test_unexpected_pass
This executes both tests without considering their xfail marks. In our fixture:
• test_expected_failure will now actually raise KnownDefectError, causing a failure.
• test_unexpected_pass will pass normally.
We expect pytest to report a failure for the first test (exit code 1). For example:
============================= test session starts =============================
collected 2 items
test_parser.py FF                                             [100%]
=========================== short test summary info ============================
FAIL test_parser.py::test_expected_failure - Intentional defect for BAD_INPUT
test_parser.py::test_unexpected_pass PASSED
== 1 failed, 0 skipped, 1 passed in 0.10s ==
(Exact output depends on pytest versions and options.) The key point: the known failing test now fails, producing exit code 1 and showing our custom exception. The --runxfail documentation explains that the option “forces running and reporting of an xfail marked test as if it weren’t marked at all”.
However, running with --runxfail does not modify the repository. It only affects that run. It is purely diagnostic: it shows what happens if the xfail were ignored. It can expose a fixed test (passed) versus a remaining bug (failed). But it’s not a retirement: to actually retire the xfail, you must remove the marker and commit the change. That revised test then must pass under the normal suite. In summary, --runxfail is an audit step to confirm behavior, not a substitute for updating the code. (As the docs note, pytest.xfail() calls are also ignored in this mode.)
10.1 The repository mark must actually be removed or revised
Simply using --runxfail does not change the source. If we determine that the bug is fixed, we must edit the test file (or code) to remove the xfail marker. For example, if parser_fixed is truly correct, we would delete or comment out @pytest.mark.xfail on test_expected_failure, turning it into an ordinary passing test. We then commit that change and rerun pytest normally. Only a clean pass of that test without the marker can justify retiring it. Conversely, if the test still fails under --runxfail, we know the defect persists and we leave the xfail in place (possibly with updated reason) as we address it.
11. Repair broad or stale exception metadata
If we find that a broad xfail (or outdated reason) is hiding a problem, we must narrow or fix it. For instance, our test_wrong_exception_broad was marked xfail without raises. This caused the TypeError to be treated as an expected failure. If that TypeError actually indicates a new, separate bug, we should not blanket-suppress it. The repair is to either fix the underlying code or tighten the xfail. Options:
Narrow the marker: If the TypeError is legitimate and separate, change the xfail to expect TypeError instead. For example: @pytest.mark.xfail(raises=TypeError, reason="Other known issue"). That way an actual KnownDefectError (if it ever appeared) would still fail, and this test’s TypeError would be documented explicitly.
Fix the implementation: If the code should have handled the input differently, correct parser_unrelated. Then turn the test back into a normal test.
We reject a fix that just widens exceptions. Each xfail’s scope should match a real, reviewed defect. Undocumented strictness bypass (like skipping a failing assertion) is also disallowed. After making changes, we rerun the affected scenarios (strict/non-strict, runxfail) to ensure the matrix is now consistent. For example, if we decide that the TypeError is not our bug, we could remove test_wrong_exception_broad’s xfail or change it to raises=TypeError. Then pytest would catch it clearly if something else happens. In any case, we produce new evidence logs after the repair and compare to the originals. The goal is to minimize surprise: either the test passes (and is then retired) or the exception is precisely scoped.
12. Decide whether to accept, repair, hold, or retire
Based on the evidence, we fill out a decision table. A simplified version:
Outcome | Conditions | Decision | Required Artifacts |
XFAIL (intended) | Test fails with documented defect (exit code 0 under non-strict) | ACCEPT | Test+mark, failure logs, bug ticket reference |
XPASS (fixed) | Test passes (exit 0 non-strict, but strict test failed) | RETIRE | Commit removing mark, new test pass logs |
XPASS (strict) | Test passes (exit 1 strict) | HOLD/REVIEW | If fix expected, document fix; if not, hold for discussion |
FAIL (unexpected) | Test raises different exception or fails assertion | REPAIR | Diagnose code/test, then update mark or code and retest |
No-test/skip | Test skipped or not collected (exit 5) | HOLD | Check filters/markers, fix test paths; do not accept as feature |
We label ACCEPT only when the test outcome is XFAIL exactly as documented and no other failures exist. Even then, it doesn’t mean “ignore the bug forever”; it means we accept it temporarily, with an explicit record. REPAIR is used when the outcome doesn’t match expectations (wrong exception, assertion failures, etc.). HOLD is used for ambiguous cases (e.g. run=False, no tests, or changing behavior where we need more data). RETIRE is used when the xfail is no longer needed and is removed. Each decision should link to a bug ticket or PR: ACCEPT means “bug ticket #123 remains open”; RETIRE means “bug #123 is fixed and closed; mark removed”. We separate business risk: ACCEPT is effectively “we ship with known bug #123”; RETIRE means “the bug is fixed”.
12.1 A known failure is not automatic permission to ship
It must be clear that marking a test xfail is not an exemption to quality. Even if we ACCEPT a test as XFAIL, that only acknowledges the bug is present. It does not mean we are happy about it: it’s a trade-off. For every accepted XFAIL we carry forward, the defect owner must eventually address it. In other words, “accepted” is not “congratulations”. It’s “we officially know this bug exists and will track its resolution.” The pytest summary output shows XFAIL results, but our policy must say whether that XFAIL is temporarily permitted or signals a blocker.
13. Assign an owner and keep the regression after retirement
Every accepted xfail should be tied to an owner (e.g. the dev who owns that bug, or a QA engineer). We should also keep it linked to a ticket or issue tracking that defect. This ensures a review cadence: for example, we might require every XFAIL to be reassessed in the next release cycle or at a defined date. The code review for the fix should reference the ticket and show that the test was updated. Once a mark is retired, the (now passing) test remains in the suite as an ordinary regression test, ensuring we keep coverage of that scenario.
We also double-check that the approved CI invocation is updated: for instance, if we required strict mode for our gate, we ensure our CI scripts still include that (otherwise an unexpected pass could sneak through). This ties into broader software development and code-review workflows: every change to a test’s xfail status must go through PR review with the defect discussion, aligning with modern software development and code-review workflows. We avoid any “timebomb” rule like “remove after N days”; retirement happens only when the evidence (passing test, commit history) justifies it.
In summary, the team must produce artifacts for each decision: error logs or output logs for evidence, links to bug/issue tracking, and version-controlled test code. With these, we can look at each marked test and say definitively whether to accept, hold, repair, or retire it. This makes our use of pytest’s xfail feature a precise part of release evidence rather than an ad-hoc label.
14. Develop release-evidence skills with Refonte Learning
Mastering rigorous test evidence and release gates is exactly the kind of skill taught in Refonte Learning’s Quality Assurance Automation Engineering program. Over its three-month curriculum, you’ll learn automated test-script writing, QA frameworks, and CI/CD integration, the very practices needed to implement the processes described here. The program requires a bachelor’s (or related) background and dedicates 12–14 hours per week to hands-on work. Its modules cover automated test development, CI/CD pipelines, performance/security testing, and more. Completing such a program ensures you understand how to build and audit test suites in a CI-driven pipeline with industry standards.
If you’re looking to strengthen your QA engineering skills and learn how to handle test exceptions and release rules like those discussed above, consider Refonte’s QA Automation Engineering course as a natural next step in your training.