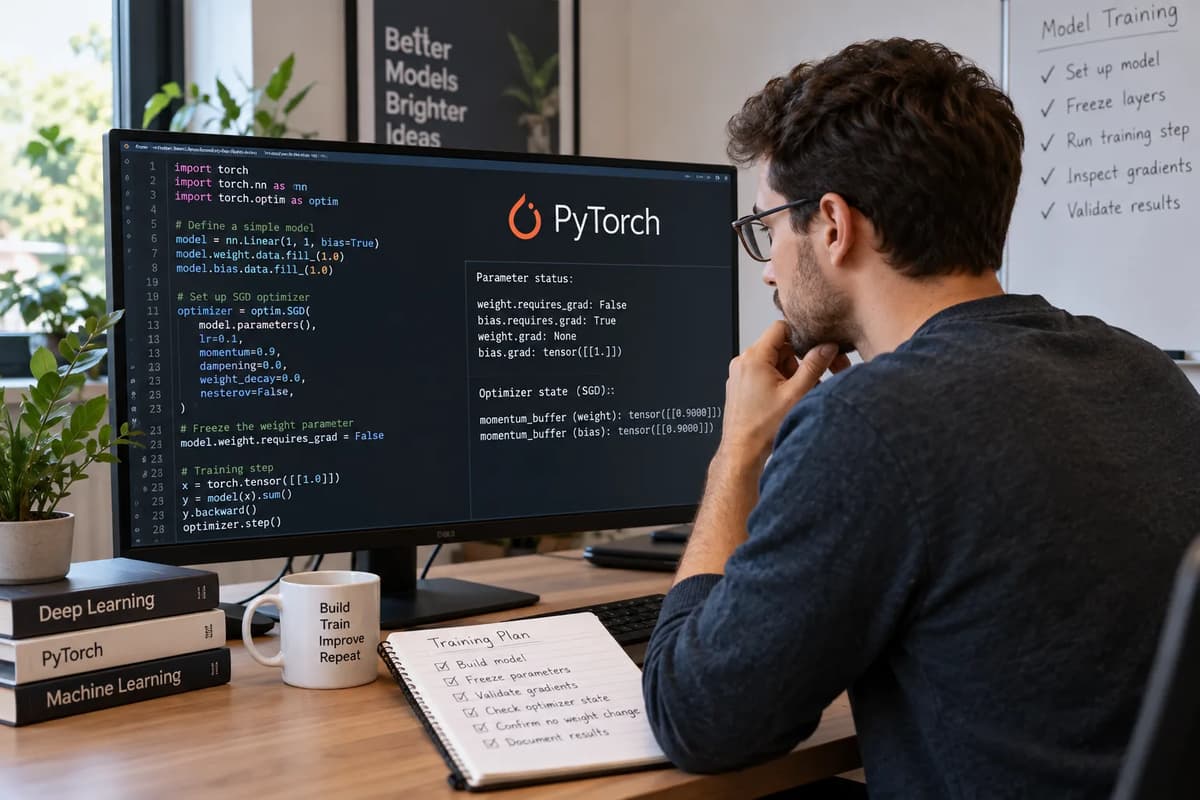
A parameter can show requires_grad=False and still change at the next optimizer.step() when an existing optimizer is retained. That is not evidence that PyTorch ignored the flag. It is evidence that three controls were collapsed into one word: whether autograd records a new gradient, what is already stored in .grad, and whether the parameter remains owned by an optimizer with state.
PyTorch 2.8 documents those boundaries separately. Tensor.requires_grad_ changes whether autograd records operations for the tensor; the autograd note says only leaves requiring gradients accumulate into .grad during backward. Optimizer.zero_grad explicitly distinguishes a zero gradient from None, including different optimizer behavior. SGD then applies its momentum state when a parameter participates in a step.
This playbook fixes the documentation reference deliberately at PyTorch 2.8. It does not claim 2.8 is the latest release as of the September 25, 2026 research cutoff. The proposed laboratory is CPU-only float32, uses no downloaded data, pretrained weights, mixed precision, distributed training, schedulers or custom optimizers, and has not been presented here as an executed experiment. Its purpose is narrower: determine whether one selected Linear(1,1) weight is numerically unchanged across a controlled freeze boundary while an existing SGD optimizer is retained.
Define the frozen-weight invariant before the next step
The target is model.weight, not the entire biased Linear module. The bias remains trainable deliberately. For this acceptance test, “frozen” therefore has one operational meaning:
Across every optimizer step in the declared frozen phase, the target weight after the step must be exactly equal to its owned before-step value.
That invariant is stricter than checking weight.requires_grad is False. PyTorch documents requires_grad_() as an in-place change to autograd recording; it does not document that call as removing a parameter from optimizer parameter groups, deleting an old .grad, or erasing optimizer state.
This distinction matters whenever code moves from one training phase to another. The conceptual reasons for freezing layers belong in broader transfer-learning and fine-tuning foundations. That Refonte Learning page describes freezing and later fine-tuning at a model-development level; this article begins one layer below that abstraction, at the exact mutation boundary between backward and optimizer.step().
The evidence required here is deliberately per-parameter. Record the target value, requires_grad, gradient category, optimizer membership and SGD momentum immediately around the relevant step. Retain the bias as a positive control: it should keep participating in backward and should change under SGD.
That also separates a diagnostic experiment from an acceptable implementation. Deliberately retaining a stale target gradient is useful because it exposes the failure mode. It is not a recommended freeze policy. Likewise, intentionally converting the stale gradient to a zero tensor is useful because it isolates momentum behavior. The production transition is accepted only when the declared frozen target remains unchanged under the optimizer configuration that the training run actually uses.
Pin the tiny model and the SGD configuration
The fixture is intentionally trivial:
Linear(1, 1, bias=True)
weight = 1.0
bias = 1.0
x = [[1.0]]
objective = model(x).sum()
With x=1, both initial scalar gradients are 1. This objective is not proposed as a useful learning task. It exists because the derivative can be inspected without a dataset or statistical interpretation.
The optimizer configuration is fixed as:
torch.optim.SGD(
model.parameters(),
lr=0.1,
momentum=0.9,
dampening=0.0,
weight_decay=0.0,
nesterov=False,
maximize=False,
foreach=False,
differentiable=False,
fused=False,
)
PyTorch 2.8 documents the SGD arguments and states that its first momentum buffer is initialized from the first gradient rather than from zero. It also documents foreach and fused as independently selectable implementations, so this fixture sets them explicitly rather than allowing implementation selection to become an uncontrolled variable.
The wider choice of languages, environments and ML frameworks belongs in the wider AI development toolkit. This test needs none of that breadth: one Python process, one CPU float32 module and one optimizer are enough.
There is an important provenance constraint. This commissioning brief does not supply an observed Python build, installed PyTorch build, operating-system string, torch.__config__ output or Git commit for an executed fixture. Inventing those fields would convert a proposed lab into fabricated evidence. An actual acceptance run must capture them before interpreting its numerical ledger.
A suitable execution preflight is:
python pytorch_frozen_sgd_validation.py > frozen-sgd-run.json
The fixture should be committed first. The harness below refuses to create acceptance evidence from a dirty Git tree, records the exact commit, captures the installed Python and PyTorch builds and records torch.__config__.show().
from future import annotations
import json
import platform
import subprocess
import sys
from typing import Any
import torch
from torch import nn
COMMISSIONING_BATCH = "2026-09-25"
WORKING_FILE = "pytorch-frozen-parameters-sgd-gradient-state-validation-prompt.txt"
BASE_SGD = {
"lr": 0.1,
"momentum": 0.9,
"dampening": 0.0,
"weight_decay": 0.0,
"nesterov": False,
"maximize": False,
"foreach": False,
"differentiable": False,
"fused": False,
}
def run_git(*args: str) -> str:
result = subprocess.run(
["git", args],
check=False,
capture_output=True,
text=True,
)
if result.returncode != 0:
raise RuntimeError(
f"git {' '.join(args)} failed: {result.stderr.strip()}"
)
return result.stdout.strip()
def provenance() -> dict[str, Any]:
dirty = run_git("status", "--porcelain")
if dirty:
raise RuntimeError(
"Working tree is not clean; commit the fixture before acceptance."
)
return {
"commissioning_batch": COMMISSIONING_BATCH,
"working_file": WORKING_FILE,
"fixture_commit": run_git("rev-parse", "HEAD"),
"python": sys.version,
"pytorch": torch.__version__,
"pytorch_git_version": getattr(torch.version, "git_version", None),
"torch_config": torch.__config__.show(),
"os": platform.platform(),
"uname": platform.uname()._asdict(),
"cuda_available": torch.cuda.is_available(),
"torch_cuda_build": torch.version.cuda,
"execution_device": "cpu",
"dtype": "torch.float32",
}
def make_fixture(momentum: float = 0.9):
model = nn.Linear(
1, 1, bias=True, device="cpu", dtype=torch.float32
)
with torch.no_grad():
model.weight.fill_(1.0)
model.bias.fill_(1.0)
x = torch.tensor([[1.0]], dtype=torch.float32, device="cpu")
options = dict(BASE_SGD)
options["momentum"] = momentum
optimizer = torch.optim.SGD(model.parameters(), *options)
return model, optimizer, x, options
def member_of(optimizer, parameter) -> bool:
return any(
parameter is candidate
for group in optimizer.param_groups
for candidate in group["params"]
)
def grad_record(parameter) -> dict[str, Any]:
grad = parameter.grad
if grad is None:
return {"category": "none", "value": None}
if torch.count_nonzero(grad).item() == 0:
return {"category": "zero_tensor", "value": float(grad.item())}
return {"category": "nonzero_tensor", "value": float(grad.item())}
def momentum_record(optimizer, parameter):
state = optimizer.state.get(parameter, {})
buffer = state.get("momentum_buffer")
return None if buffer is None else float(buffer.detach().item())
def warmup(model, optimizer, x):
model(x).sum().backward()
optimizer.step()
torch.testing.assert_close(
model.weight.detach(),
torch.tensor([[0.9]], dtype=torch.float32),
rtol=0.0,
atol=1e-6,
)
def run_primary(mode: str) -> dict[str, Any]:
model, optimizer, x, options = make_fixture(momentum=0.9)
warmup(model, optimizer, x)
model.weight.requires_grad_(False)
if mode == "retain":
# Preserve the target's stale grad; clear only bias noise.
model.bias.grad = None
expected = 0.71
elif mode == "zero":
optimizer.zero_grad(set_to_none=False)
expected = 0.81
elif mode == "none":
optimizer.zero_grad(set_to_none=True)
expected = 0.90
else:
raise ValueError(f"Unknown mode: {mode}")
model(x).sum().backward()
before_weight = model.weight.detach().clone()
before_bias = model.bias.detach().clone()
record = {
"scenario": mode,
"requires_grad_before_step": model.weight.requires_grad,
"grad_before_step": grad_record(model.weight),
"optimizer_member": member_of(optimizer, model.weight),
"momentum_before_step": momentum_record(optimizer, model.weight),
"weight_before": float(before_weight.item()),
"bias_before": float(before_bias.item()),
}
optimizer.step()
after_weight = model.weight.detach().clone()
after_bias = model.bias.detach().clone()
record.update(
{
"weight_after": float(after_weight.item()),
"bias_after": float(after_bias.item()),
"grad_after_step": grad_record(model.weight),
"momentum_after_step": momentum_record(
optimizer, model.weight
),
"target_exactly_unchanged": torch.equal(
before_weight, after_weight
),
"bias_changed": not torch.equal(before_bias, after_bias),
}
)
torch.testing.assert_close(
after_weight,
torch.tensor([[expected]], dtype=torch.float32),
rtol=0.0,
atol=1e-6,
)
if mode == "none":
assert torch.equal(before_weight, after_weight)
return record
def run_no_momentum(mode: str) -> dict[str, Any]:
model, optimizer, x, options = make_fixture(momentum=0.0)
warmup(model, optimizer, x)
model.weight.requires_grad_(False)
optimizer.zero_grad(set_to_none=(mode == "none"))
model(x).sum().backward()
before = model.weight.detach().clone()
optimizer.step()
after = model.weight.detach().clone()
return {
"scenario": f"no_momentum_{mode}",
"optimizer_options": options,
"grad_before_step": grad_record(model.weight),
"momentum_after_step": momentum_record(
optimizer, model.weight
),
"weight_before": float(before.item()),
"weight_after": float(after.item()),
"target_exactly_unchanged": torch.equal(before, after),
}
def run_unfreeze(reset_momentum: bool) -> dict[str, Any]:
model, optimizer, x, = makefixture(momentum=0.9)
warmup(model, optimizer, x)
# Accepted frozen boundary: no target gradient participates.
model.weight.requires_grad_(False)
optimizer.zero_grad(set_to_none=True)
model(x).sum().backward()
frozen_before = model.weight.detach().clone()
optimizer.step()
frozen_after = model.weight.detach().clone()
assert torch.equal(frozen_before, frozen_after)
# Begin a bounded unfreeze transition.
optimizer.zero_grad(set_to_none=True)
model.weight.requires_grad_(True)
if reset_momentum:
optimizer.state[model.weight].pop("momentum_buffer", None)
model(x).sum().backward()
before = model.weight.detach().clone()
momentum_before = momentum_record(optimizer, model.weight)
optimizer.step()
after = model.weight.detach().clone()
expected = 0.80 if reset_momentum else 0.71
torch.testing.assert_close(
after,
torch.tensor([[expected]], dtype=torch.float32),
rtol=0.0,
atol=1e-6,
)
return {
"scenario": (
"unfreeze_reset_momentum"
if reset_momentum
else "unfreeze_retain_momentum"
),
"new_target_grad": grad_record(model.weight),
"momentum_before_unfreeze_step": momentum_before,
"weight_before": float(before.item()),
"weight_after": float(after.item()),
}
def main() -> None:
evidence = {
"provenance": provenance(),
"primary": [
run_primary("retain"),
run_primary("zero"),
run_primary("none"),
],
"no_momentum": [
run_no_momentum("zero"),
run_no_momentum("none"),
],
"unfreeze": [
run_unfreeze(False),
run_unfreeze(True),
],
}
print(json.dumps(evidence, indent=2))
if name == "__main__":
main()
Every reported value produced by that program would be an observed run value. Until the script is actually executed under a recorded commit and environment, the numeric values discussed below remain arithmetic expectations, not measurements.
Warm up each scenario to create real optimizer state
Each arm begins with a newly constructed model and optimizer. Reusing one arm after another would contaminate the experiment because the very quantities under investigation (.grad, momentum and parameter values) are mutable.
At initialization, w=1, b=1, and x=1, so:
output = w*x + b = 2
d(output.sum())/dw = 1
d(output.sum())/db = 1
After the first backward(), the target therefore has a gradient tensor containing 1. The first SGD step uses that gradient. PyTorch 2.8 specifies that its initial momentum buffer is initialized to the first gradient, so the target's buffer is expected to become 1. With learning rate 0.1, the first weight update is:
v1 = 1
w1 = 1 - 0.1 * 1 = 0.9
The key detail is what remains afterward. optimizer.step() does not serve as gradient cleanup. Unless a separate clearing operation occurs, the existing weight.grad tensor remains populated. Meanwhile, the optimizer now has per-parameter state containing the target momentum buffer. PyTorch's documented SGD formulation and initialization rule are the basis for those expectations.
Warmup is consequently not cosmetic. Starting from a never-stepped optimizer would remove the residual conditions the test is designed to expose. There would be no stale weight gradient and no target momentum buffer.
Keep one parameter trainable for a meaningful backward
Only model.weight is frozen:
model.weight.requires_grad_(False)
The bias remains requires_grad=True.
PyTorch's autograd mechanics state that an operation is recorded when at least one relevant input requires gradients and that gradients are accumulated into leaf tensors that require them. Keeping the bias trainable therefore leaves a valid differentiable path through the new forward pass.
This avoids conflating two unrelated conditions. A test that removes every differentiable leaf and then discovers that backward() has no usable gradient graph is testing its graph construction, not whether a stale target gradient can influence optimizer.step().
The bias also provides a useful positive control. During the frozen-target phase, a changed bias demonstrates that another legitimate parameter participated in the backward/step cycle. A target that remains unchanged while nothing else updates would be weaker evidence because the entire step might simply have been bypassed.
Capture values independently of the live parameter
Before every decisive step, capture:
before = model.weight.detach().clone()
Do not retain only:
before = model.weight
The latter is another reference to the same live Parameter. If SGD mutates the parameter in place, inspecting the reference afterward does not reconstruct its earlier value.
An owned detached clone is therefore test instrumentation for this mutation boundary. The acceptance oracle can then use:
torch.equal(before, after)
This article does not extend that point into checkpoint aliasing, delayed serialization or “best model” capture workflows. Those are separate lifecycle problems. Here the clone has one job: preserve the bytes needed to decide whether one optimizer step changed the selected target.
Freeze the weight while retaining its old gradient
The first independent transition deliberately preserves the target's gradient from warmup.
Immediately after warmup the expected target state is:
weight ≈ 0.9
requires_grad True
weight.grad tensor([[1.]])
momentum_buffer tensor([[1.]])
optimizer member yes
The transition then performs:
model.weight.requires_grad_(False)
model.bias.grad = None
It does not clear model.weight.grad.
That distinction is consistent with the PyTorch APIs. requires_grad_(False) controls future autograd recording and backward accumulation for the leaf; the documented call is not a gradient-deletion API. PyTorch's autograd note explains that a frozen leaf will not have its .grad updated by the new backward pass. Nothing in that statement implies that a pre-existing .grad tensor is retroactively erased.
A new forward and backward therefore needs no new target gradient for the old tensor to remain visible to SGD. The bias obtains a fresh gradient and proves that the backward pass occurred. The target remains an optimizer member, has its old nonzero gradient and has momentum state.
The expected next target update follows directly from the documented momentum equation:
v2 = 0.9 1 + 1 = 1.9
w2 = 0.9 - 0.1 1.9 = 0.71
Thus, under the documented PyTorch SGD momentum update, requires_grad=False and weight≈0.71 can coexist after the step in this deliberately failing control.
The engineering conclusion is precise: the freeze flag can be working correctly at the autograd boundary while the training-phase transition is still unacceptable at the optimizer boundary.
Compare a zero gradient with no gradient
The other two primary arms start from independent warmups and retain the same SGD momentum configuration. After freezing weight, they differ only in how the existing gradient is cleared.
The zero-tensor arm runs:
optimizer.zero_grad(set_to_none=False)
The None arm runs:
optimizer.zero_grad(set_to_none=True)
PyTorch 2.8 explicitly documents that these are behaviorally different. With set_to_none=True, parameters that receive no new gradient after backward remain None; the Optimizer.zero_grad documentation also says optimizers distinguish a gradient of zero from no gradient, with one participating in a step and the other being skipped. The 2.8 method signature shows set_to_none=True as its default, but this laboratory never relies on that default: the choice is written explicitly in each arm.
For the frozen weight, the expected pre-step ledger is therefore:
Transition | requires_grad | Target .grad before step | Optimizer member | Momentum before step |
retain | False | nonzero tensor, 1 | yes | 1 |
set_to_none=False | False | zero tensor, 0 | yes | 1 |
set_to_none=True | False | None | yes | 1 |
The membership row is intentionally unchanged. Calling zero_grad does not reconstruct the optimizer. The experiment is about retaining it.
Explain the approximate 0.71, 0.81 and 0.9 outcomes
The retained case has already yielded the prediction:
v2 = 0.9*1 + 1 = 1.9
w2 = 0.9 - 0.1*1.9 = 0.71
For the zero-gradient arm, the current gradient is zero but the old momentum buffer exists:
g2 = 0
v2 = 0.9*1 + 0 = 0.9
w2 = 0.9 - 0.1*0.9 = 0.81
This is the essential PyTorch SGD zero gradient momentum boundary: zero target gradient does not imply zero target update when momentum remains active under this configuration. The formula is the documented PyTorch SGD momentum formula, not a generic assertion about every optimizer.
For the None arm, PyTorch's zero_grad documentation says the absence of a gradient leads to the skip behavior rather than the zero-gradient step behavior. The expected target therefore stays at its post-warmup value:
before second step ≈ 0.9
after second step = before second step
The target momentum buffer is also expected to remain at its previous value because the target was skipped under the documented Optimizer.zero_grad behavior rather than processed through another momentum recurrence. That expectation must still be recorded and checked in an actual run rather than assumed from the final weight alone.
These expected outcomes, approximately 0.71, 0.81 and unchanged 0.9, answer the headline question. No, setting requires_grad_(False) alone is not sufficient evidence that an already optimizer-owned parameter will remain numerically unchanged on the next step when its old .grad is still present.
Separate exact invariance from numeric prediction tolerance
Two different assertions are required.
For hand-derived decimal predictions, use a deliberately small float32 tolerance:
torch.testing.assert_close(
actual,
torch.tensor([[0.81]], dtype=torch.float32),
rtol=0.0,
atol=1e-6,
)
Decimal 0.81 is not the acceptance invariant. It is an arithmetic prediction expressed through float32 computation.
For the frozen-target oracle, use exact before/after equality:
assert torch.equal(before, after)
That distinction prevents a dangerous test design such as:
torch.allclose(before, after, atol=1e-3)
where a sufficiently permissive tolerance could classify a small unauthorized mutation as “frozen.”
The invariant asks a binary question: did this target tensor change at this optimizer step? The arithmetic checks ask a different question: did the deliberately failing controls move by approximately the amount predicted by this SGD configuration?
Keeping those oracles separate makes the failure informative without weakening the release criterion.
Use a no-momentum control to isolate the mechanism
The 0.81 arm attributes movement to a zero gradient combined with retained momentum. A clean control changes exactly one optimizer option:
momentum=0.0
Everything relevant to the weight update remains fixed: CPU, float32, learning rate 0.1, dampening 0, weight decay 0, no Nesterov, no maximize, foreach=False, fused=False, the same model, the same warmup structure and the same fixed input.
Run independent zero-tensor and None arms under that optimizer. In the zero-tensor arm, the expected target update is now:
g = 0
delta_weight = -0.1 * 0 = 0
With weight_decay=0, there is no other term in this configured SGD update to move the parameter. The None arm is likewise expected to remain unchanged because it is skipped. The PyTorch SGD documentation shows both the momentum and weight-decay terms in the update rule, which is why both options must be recorded when interpreting the control.
This comparison strengthens the diagnosis:
momentum=0.9 + zero gradient -> expected movement to ≈0.81
momentum=0.0 + zero gradient -> expected exact invariance
It does not justify the broad rule “zero gradients are safe for frozen parameters.” This laboratory deliberately has weight_decay=0, uses one documented SGD configuration and excludes other optimizers. Different stateful update rules or nonzero regularization options require their own analysis.
Likewise, the no-momentum control does not repair the primary training plan by changing the optimizer to momentum=0. Its purpose is causal isolation. If production training is supposed to use momentum 0.9, acceptance must be performed with momentum 0.9.
Audit optimizer membership and state alongside autograd
A freeze audit is incomplete unless it answers, for the same parameter object:
Does autograd require a new gradient?
What is currently in .grad?
Is the object in an optimizer parameter group?
What optimizer state is attached to it?
PyTorch defines SGD's params input as the parameters or parameter groups to optimize. Changing a leaf's requires_grad flag is a separate operation from changing those parameter groups.
Audit membership by object identity, not by a convenient numerical index:
any(
model.weight is p
for group in optimizer.param_groups
for p in group["params"]
)
Attach the semantic name weight from the model-side inspection so the ledger remains understandable.
That discipline becomes even more important around serialization. PyTorch's Optimizer.state_dict documentation says optimizer state is stored per parameter, while the parameter itself is not stored there. Parameter groups contain IDs associating state with group entries; on load, PyTorch matches saved IDs with actual parameters by zipping them in order, without additional identity verification.
Therefore, a serialized optimizer ID is not a self-validating semantic name. Neither is “the state dict loaded successfully” evidence that state was associated with the intended live parameter objects.
For this laboratory, there is no need to rebuild the optimizer at all. Keeping the existing optimizer is part of the question. In a larger repair, if an engineer intentionally constructs new parameter groups, removes frozen targets or later reloads optimizer state, the preservation/reset policy and parameter correspondence must be explicit evidence. Silent reconstruction is not an acceptable shortcut.
Build a step-by-step mutation ledger
The core artifact should be a mutation ledger, not an overall training metric.
At minimum, each decisive row needs:
Field | Purpose |
scenario and phase | identifies the independent transition |
semantic parameter name | avoids anonymous optimizer IDs |
requires_grad | records autograd intent |
gradient category/value | distinguishes nonzero, zero and None |
optimizer membership | records update ownership |
momentum before/after | exposes stateful update behavior |
value before/after | supplies the mutation oracle |
invariant verdict | converts evidence into a decision |
For the proposed primary scenarios, the expected, not yet observed target ledger is:
Scenario | Grad before step | Momentum before | Weight before | Expected after | Frozen invariant |
retain stale grad | 1 | 1 | ≈0.9 | ≈0.71 | fail |
zero tensor | 0 | 1 | ≈0.9 | ≈0.81 | fail |
None | None | 1 | ≈0.9 | exactly unchanged | pass |
zero, momentum 0 control | 0 | none | ≈0.9 | exactly unchanged | control pass |
Those expectations combine the zero_grad skip distinction with PyTorch's documented SGD momentum recurrence.
The bias should appear in the same run evidence as a positive control. Its exact value is secondary, but it should demonstrate that the new backward produced a real trainable gradient and the optimizer performed an update. If both target and bias remain unchanged unexpectedly, do not announce a successful freeze; investigate whether the intended training step happened at all.
This is complementary to model-evaluation evidence and its limits. Evaluation metrics address whether a model performs adequately for a task; this ledger addresses whether the training mechanism obeyed a parameter-level mutation constraint.
Reject a healthy loss curve as freeze evidence
A decreasing objective cannot certify this invariant.
In the tiny fixture, both weight and bias contribute to the same scalar output. In a real model, thousands or billions of permitted parameters may compensate for movement in a parameter that was supposed to remain fixed. An aggregate training loss therefore answers a different question.
The same reasoning applies to a printed gradient norm. A target gradient norm of zero means the tensor's gradient values are zero. Under the configured momentum experiment, that condition is exactly the ≈0.81 failing arm.
Nor is requires_grad=False itself the final oracle. It verifies the intended autograd flag, and PyTorch documents what that flag means for recording and gradient accumulation, but the test still needs an independent value comparison around optimizer.step().
The minimum release evidence is consequently conjunctive: intended target flag, declared target gradient state, known optimizer membership/state, exact target invariance, and continued activity of an intended trainable parameter.
Keep forward-mode and buffer questions outside this test
This fixture should stay narrow.
PyTorch's autograd documentation treats requires_grad, no-grad mode, inference mode and evaluation mode as distinct mechanisms; in particular, it notes that .eval() is not a mechanism for disabling gradient computation.
Those facts are useful boundaries, not invitations to expand the laboratory. There is no eval()/no_grad()/inference_mode() matrix here. There is no Dropout or BatchNorm test. There are no registered buffers in the tiny Linear fixture whose mutation must be certified.
Accordingly, a passing frozen-weight ledger certifies only the selected parameter under the specified optimizer step. It does not certify every mutable object in a realistic module.
That bounded claim is important operationally. “The target parameter stayed exactly unchanged” is defensible evidence. “The model was completely frozen” would require a broader inventory of parameters, buffers and state that this experiment intentionally does not perform.
Repair the freeze transition explicitly
The minimal repair for a target that remains in the existing optimizer is to make the phase boundary explicit:
def freeze_target_for_retained_optimizer(parameter) -> None:
parameter.requires_grad_(False)
parameter.grad = None
When the optimizer owns several parameters, the equivalent optimizer-level clearing operation can be used when that is the declared transition policy:
optimizer.zero_grad(set_to_none=True)
model.weight.requires_grad_(False)
Order can be made consistent with the training codebase's transition contract; the key in this fixture is the final pre-step condition: the frozen target is requires_grad=False and its .grad is None.
A repaired test then performs a new forward, backward and optimizer step and proves:
before = model.weight.detach().clone()
optimizer.step()
after = model.weight.detach().clone()
assert torch.equal(before, after)
Under PyTorch 2.8's documented zero_grad behavior, the frozen parameter receives no new gradient during backward and therefore remains None; optimizers distinguish that condition from a zero gradient by skipping the parameter.
That is a phase-transition repair, not a claim that requires_grad=False was broken. The repair closes the gap between new-gradient policy and the existing gradient tensor.
A second possible architecture is a deliberately constructed optimizer whose parameter groups exclude frozen targets. PyTorch exposes parameter groups explicitly and even documents adding parameter groups as layers become trainable during fine-tuning. But changing optimizer construction is not automatically safer: removing and later re-adding a parameter forces a decision about its optimizer state.
Do not “repair” the freeze by casually rebuilding SGD from all currently trainable parameters if that silently discards momentum for parameters that were supposed to retain it. A new optimizer is new state unless state is deliberately transferred and validated. If state is loaded, the documented Optimizer.state_dict parameter-association behavior means correspondence must be audited rather than inferred from successful deserialization.
For the defined use case of retaining an existing optimizer, the smaller repair is preferable as an acceptance experiment: clear the target gradient to None, retain declared optimizer state, step, and prove exact invariance.
Choose what unfreezing should do to momentum
Successful freezing introduces another state-policy question: what happens when the target becomes trainable again?
Consider the accepted frozen path. Warmup creates:
weight ≈ 0.9
momentum_buffer = 1
The target then enters the frozen phase with .grad=None. The frozen optimizer step skips it, so the proposed ledger expects its old momentum buffer to remain available.
Now unfreeze:
model.weight.requires_grad_(True)
optimizer.zero_grad(set_to_none=True)
model(x).sum().backward()
The new target gradient is again 1.
If the training owner intentionally retains old target momentum, the predicted update is:
old momentum = 1
new gradient = 1
v = 0.9*1 + 1 = 1.9
weight: 0.9 -> approximately 0.71
If the declared policy is instead reset target momentum, the transition can explicitly remove that target's buffer before the new trainable step:
optimizer.state[model.weight].pop("momentum_buffer", None)
PyTorch's SGD documentation says a newly initialized momentum buffer takes the first gradient value, so the prediction becomes:
fresh momentum = 1
weight: 0.9 -> approximately 0.8
Neither result is universally “correct.” They encode different training semantics.
The important reliability requirement is that the difference not be accidental. A hidden optimizer reconstruction might reset momentum without anyone deciding to. An untouched optimizer might preserve momentum even though the training design expected a fresh phase. The owner of the fine-tuning policy must declare one of those behaviors, and regression tests should encode the corresponding numerical expectation.
Recover only from an approved phase boundary
When an unauthorized target update has already occurred, changing requires_grad or clearing .grad afterward does not retroactively certify the preceding model state.
Preserve the failed ledger first. It identifies exactly which parameter, gradient category, momentum state and step produced the mutation.
For this tiny deterministic fixture, recovery is uncomplicated: construct a new Linear(1,1), restore explicit weight=1 and bias=1, construct a new optimizer with the declared configuration, repeat the single warmup and then apply the repaired freeze boundary. Starting over is clearer than attempting to reverse 0.71 or 0.81 manually because the test itself is cheap and deterministic.
Real training runs have a harder recovery rule. Resume only from an approved phase boundary whose model state and required optimizer state are compatible with the intended transition. A saved set of weights alone does not establish the same future SGD trajectory when momentum state matters. PyTorch documents momentum as per-parameter optimizer state, while its optimizer state-dict documentation explains how saved state is associated with live parameters.
That is where model deployment and versioning context becomes relevant operationally: the training artifact that progresses toward release should have a traceable approved origin. The deployment discussion is broader than this optimizer test, but versioning discipline does not become less important at a training-phase boundary.
Do not claim an exact training resumption unless the evidence supports it. Restoring model values while discarding, remapping or resetting optimizer state can produce a different subsequent trajectory.
If no approved compatible boundary exists, the correct decision is hold rather than invent continuity. If an unacceptable step contaminated a state that must not be used, restart from the last approved state after fixing the transition.
Decide accept, repair, hold or restart
The decision should follow evidence, not intuition about what “frozen” usually means.
Observed condition | Decision | Required action |
requires_grad=False, retained nonzero .grad, target moves | Repair phase transition | Clear target grad to None; rerun from clean independent state |
requires_grad=False, zero tensor, momentum active, target moves | Repair phase transition | Use declared skip policy such as .grad=None; preserve failing control |
requires_grad=False, .grad=None, expected membership/state, exact target invariance, bias updates | Accept | Retain ledger as acceptance evidence |
zero tensor with momentum 0 stays unchanged | Control passes | Use only as causal evidence; do not substitute it for primary configuration |
frozen target unexpectedly absent/present in optimizer relative to policy | Hold | Repair membership definition and rerun |
trainable bias fails to update | Hold | Establish that backward/step actually occurred before evaluating target |
optimizer was reconstructed but target-state correspondence is unverified | Hold | Verify mapping and state policy or restart from an approved construction |
target changed during an already-consumed unapproved phase | Restart from approved state | Fix transition, then recover from compatible model/optimizer evidence |
required pre-step ledger is missing | Hold | Reproduce from an approved boundary; do not infer the missing state |
The primary three-arm expectations make the distinction concrete.
The retained-gradient arm is expected to fail at approximately 0.71. It demonstrates that stopping future autograd accumulation does not erase the gradient tensor already attached to the parameter.
The zero-gradient arm is expected to fail at approximately 0.81. It demonstrates that “gradient norm equals zero” is not sufficient evidence for invariance when this SGD momentum state participates.
The None arm is expected to leave the target exactly unchanged from its own pre-step value. PyTorch 2.8 explicitly distinguishes None from a zero tensor in optimizer behavior.
The no-momentum comparison is not another production candidate; it explains why the zero-tensor primary arm moved.
Acceptance also requires the positive control. A frozen target that did not move is useful evidence only when the intended trainable part of the step remained alive. In this fixture, that is the bias.
Finally, “optimizer membership” is neither inherently good nor inherently bad during a freeze. A target may legitimately remain in the existing optimizer if .grad=None causes the declared skip behavior and its stored momentum is intentionally retained for later unfreezing. Another design may deliberately remove it from parameter groups. What is unacceptable is an undeclared discrepancy between the training policy and the live optimizer.
That is why the decision vocabulary separates repair from restart. Repair addresses code or transition semantics before continuing. Restart addresses training state that has already crossed an unapproved mutation boundary.
Assign training-policy and regression-test ownership
A reliable phase transition has three owners.
The training-policy owner defines semantics: which exact parameters freeze, whether they remain optimizer members, what .grad condition is required while frozen, and whether target momentum is retained or reset upon unfreezing.
The implementation owner turns that policy into code. For the retained-optimizer policy in this article, that means setting the selected parameter's requires_grad flag, clearing stale target gradients to None at the boundary, and avoiding silent optimizer reconstruction.
The reviewer verifies numerical evidence rather than merely reviewing the API calls.
This fits naturally with broader software testing and delivery practices: phase-transition behavior should be represented by an executable regression fixture rather than an unwritten convention. The linked Refonte Learning page discusses version control, testing and delivery tooling at a wider software-engineering level; the ML-specific requirement here is the mutation oracle around optimizer steps.
Rerun the fixture after changes that can invalidate its assumptions: optimizer options, parameter-group construction, model parameter selection, PyTorch build, fixture code or the order in which freeze, gradient clearing, backward and step occur.
Retain both failing controls. A regression suite containing only the corrected None arm can pass even if the suite later stops exercising the mechanism that motivated it. The stale-gradient ≈0.71 control and zero-gradient/momentum ≈0.81 control establish that the fixture can still detect the prohibited behaviors it claims to guard against.
Record the exact fixture commit and environment with each acceptance run. PyTorch's public API documentation is the fixed 2.8 reference for this article, but an installed binary is an independently recorded execution fact. A later substantive framework-version change should trigger revalidation rather than silently inheriting a result obtained under another build.
The acceptance artifact should therefore let another engineer answer: what code ran, under which build, which optimizer configuration was live, which parameter object was tested, what its gradient and momentum were before the step, and whether its value changed.
Strengthen the AI-engineering foundations behind phase changes
Freeze/unfreeze reliability sits at the intersection of autograd, optimizer state, numerical testing and model-development policy. Refonte Learning's verified AI Engineering page lists neural networks and deep learning, model development and optimization, reinforcement learning, scaling and practical projects; its FAQ names TensorFlow, PyTorch and Keras. The published page lists a three-month format at 12–14 hours per week. Those facts do not establish that this specific SGD residual-gradient laboratory is part of the curriculum.
Engineers strengthening those broader foundations can inspect the published curriculum while keeping specialist acceptance evidence where it belongs: in reproducible training tests.
For this phase boundary, the release question remains deliberately small and measurable. After freezing the selected weight, clone its value before every in-scope optimizer step and require exact equality afterward. requires_grad=False records the autograd intent; .grad=None, optimizer membership and momentum explain whether SGD can still act. Acceptance belongs to the measured parameter invariant, not to the flag alone.