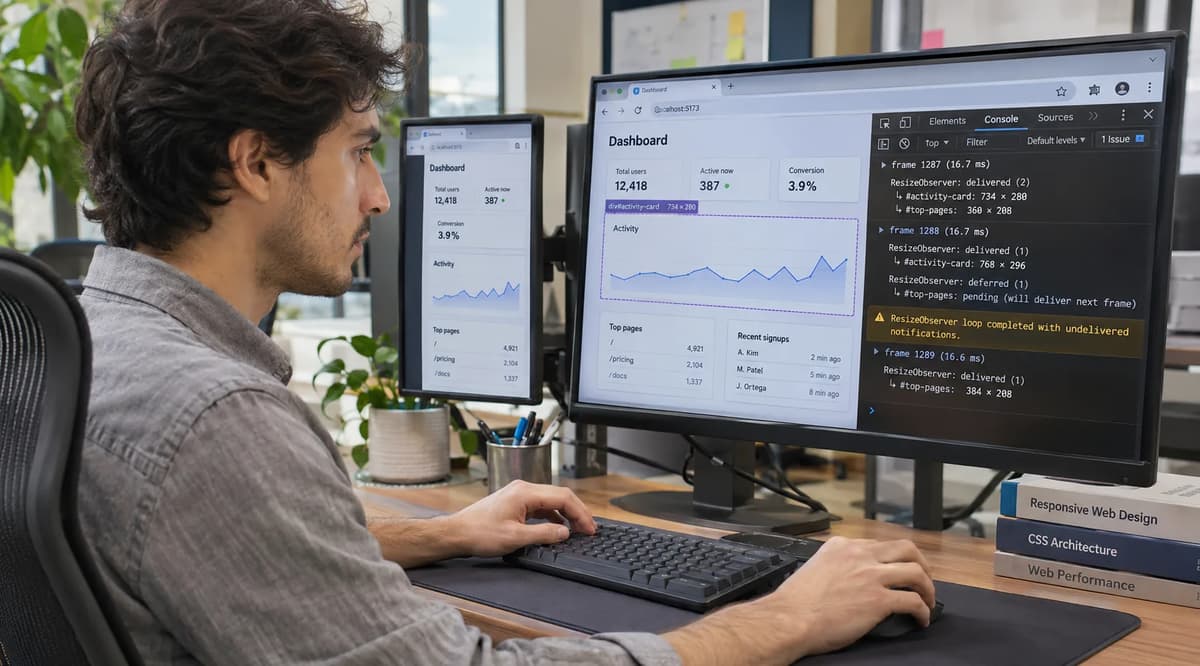
When a ResizeObserver callback inadvertently resizes elements in a cycle, the browser may fire a “ResizeObserver loop completed with undelivered notifications.” error on the Window. This error is not thrown like an exception, but delivered as a Window error event, deferring any skipped observations to the next frame. In practice, a developer may observe that some style changes appear applied while others silently slipped to the next frame. The “success” of the callback (it didn’t crash) is thus misleading: critical layout updates may be missing. The goal is to know exactly which DOM updates took effect and which did not.
In this operational context, we need a rigorous testing playbook. We will construct a disposable test fixture with pinned browser versions, synthetic DOM changes, and an independent expected-case manifest. Each case will record expected-versus-observed outcomes in an evidence ledger. We include a negative control case to verify no false alarms. Finally we decide ACCEPT/REPAIR/RERUN/HOLD based on whether the delivered layout matches the spec and our oracle.
This structured approach mirrors acceptance testing in other domains (e.g. Kubernetes topology spread scheduling tests resilience or scikit-learn model evaluation defines exact success criteria), but focused on ResizeObserver behavior.
1: Define the acceptance contract
Acceptance must be more than “no uncaught exception.” We require explicit statements of what delivered changes should be. The contract is: when a ResizeObserver loop error occurs, the delivered layout changes exactly match those predicted by spec for that frame. Concretely:
· Expected delivered updates: We list which element sizes/styles should be updated synchronously (per spec, delivered in that frame).
· Expected skipped updates: Any deeper or cyclic adjustments should be deferred. For example, if a parent and child resize each other, only the deeper-child changes occur in the same frame; the parent’s change is skipped (deferred to the next frame).
· Error event: We assert that the Window error event with message “ResizeObserver loop completed with undelivered notifications” should fire only when a loop is detected. If it does not fire but we predicted a loop, that’s a test failure. Conversely, if it fires unexpectedly (no real loop), we reject the test.
· State reconciliation: The final DOM state after all frames (including deferred frames) must match an independent oracle. The oracle is defined before running tests, based on logic or spec reading. Any mismatch between observed state and the oracle is a defect.
· Decision points: Each case yields a verdict (PASS/FAIL) on meeting the contract. Only if all required cases pass (with no missing evidence) do we ACCEPT the behavior as documented. If a case fails according to our evidence, we consider REPAIR or HOLD. A RERUN is needed for any incomplete or inconclusive result.
For example, similar acceptance-driven tests have been used elsewhere: in Kubernetes topology spread scheduling the “acceptance criterion” was that every domain retains a viable Pod placement under failure. In Machine Learning model evaluation the article insists on an evaluation contract specifying prediction task, metric, and baseline beforehand. By analogy, we define our ResizeObserver contract first, then verify it.
2: Record the versioned baseline
To make this test reproducible, we pin the environment. The baseline setup is:
· Browsers: Chrome (Chromium) and Firefox at known versions supporting ResizeObserver (tested on Chrome 146.0.x and Firefox 115.0 in Nov 2026). Record exact user agents via navigator.userAgent or chrome://version. Store these in version.txt.
· JavaScript engine: Node.js 20.8.0 and npm for any build tools. (Exact Node version captured via node -v in version.txt.) This ensures any headless scripts or bundlers behave consistently.
· Fixture files: All HTML/CSS/JS code is self-contained (no external CDN) so that asset changes cannot drift. We include version comments (e.g. <!-- Chrome 146.0 / Node 20.8.0 -->) in our test files as evidence.
Acceptance assertion: The reported versions in the evidence (e.g. navigator.userAgent and node -v) must match our pinned versions. If we later run tests on different versions, we should rerun or mark as needing retest. Version mismatches would invalidate comparison to our manifest (which is written for the pinned spec behavior).
For instance, in SQL database testing, the act of capturing sqlite3 --version into evidence was a required precondition. Similarly, we log and retain our browser/Node versions. Failing to capture or a mismatch leads to an INVALID PRECONDITION and we would RERUN under the correct version.
Isolate the negative control
Assertion: In a negative control scenario (no callback-induced loop), the loop error must not fire. For example, if the observer merely resizes a child (deeper element) without ever resizing a parent/sibling in the same callback, then by design only deeper nodes are affected and the spec’s loop-check passes. We choose such a case: e.g. an observer on a container that adjusts a child’s height based solely on the container’s new size. This should be safe (only writing to a deeper element).
Rejection condition: If the negative control produces a Window error event, that indicates our test fixture or baseline is wrong. We would abort (HOLD) and re-evaluate the fixture logic. For instance, if we accidentally triggered a depth-violating change, the error event would fire and contradict our “no-loop” contract. In that case, we mark the negative control as FAIL, fix the fixture (so that only safe changes occur), then rerun all tests.
We document the negative control assertion like this: “ResizeObserver should not fire a loop error when only non-cyclic child-size adjustments occur.” The test will listen for window.addEventListener('error', ...) and assert no event arrives.
3: Build the disposable test fixture
We create an HTML+JS fixture that synthetically triggers ResizeObserver callbacks. The fixture is self-contained and can be spun up in a headless browser or dev tools. Key features:
· DOM Structure: A container #parent with two nested children #child1 and #child2. This yields a three-level depth: parent (depth1), child1 (depth2), child2 (depth3).
· Initial Styles: We assign fixed initial widths/heights (e.g. parent 200×100px, children 50×50px) via inline CSS. This sets known contentBox sizes.
· Observers and Callbacks: We attach three ResizeObservers: one on each element. Each callback deliberately resizes another element:
· Observer on #parent: when parent changes, increase #child1’s width by +50px.
· Observer on #child1: when child1 changes, increase #child2’s width by +50px.
· Observer on #child2: when child2 changes, increase #parent’s width by +50px.
This creates a cycle: parent ⇒ child1 ⇒ child2 ⇒ parent. In code:
HTML fixture
<!-- case-1-loop.html (EXPECTED / NOT EXECUTED) -->
<div id="parent" style="width:200px;height:100px;background:lightblue;">
<div id="child1" style="width:50px;height:50px;background:coral;"></div>
<div id="child2" style="width:50px;height:50px;background:coral;"></div>
</div>
JavaScript for the fixture
const parent = document.getElementById("parent");
const child1 = document.getElementById("child1");
const child2 = document.getElementById("child2");
// Helper to parse and increment inline width
function incWidth(el, delta) {
const style = getComputedStyle(el);
el.style.width = (parseFloat(style.width) + delta) + 'px';
}
// Observer on parent: on parent resize, resize child1
new ResizeObserver(entries => {
entries.forEach(entry => {
incWidth(child1, 50);
console.log("Parent callback: child1 increased");
});
}).observe(parent);
// Observer on child1: on child1 resize, resize child2
new ResizeObserver(entries => {
entries.forEach(entry => {
incWidth(child2, 50);
console.log("Child1 callback: child2 increased");
});
}).observe(child1);
// Observer on child2: on child2 resize, resize parent
new ResizeObserver(entries => {
entries.forEach(entry => {
incWidth(parent, 50);
console.log("Child2 callback: parent increased");
});
}).observe(child2);
// Start the cycle by resizing parent once
parent.style.width = "300px";
// Listen for the loop-error event
window.addEventListener('error', e => {
console.error("Error event:", e.message);
});
// After callbacks (using rAF), log final sizes for evidence
requestAnimationFrame(() => {
console.log("Final sizes:",
parent.clientWidth, child1.clientWidth, child2.clientWidth);
});
This fixture simulates a callback-induced resize cycle. The initial manual change (parent.style.width=300px) triggers the chain. By spec, this should hit the loop limit and fire the error event.
Negative control fixture: We create a second HTML (case-2-safe.html) that breaks the synchronous loop by deferring the parent resize. For example, we use requestAnimationFrame in the child2 callback so the change happens on the next frame, avoiding same-frame recursion. This fixture should produce no error event.
Isolation: Each case’s HTML is separate and uses fresh elements. We ensure no case modifies the others’ DOM. We also disable display:none or transforms to avoid hiding elements (ResizeObserver ignores display: none).
Version comments: At the top of each fixture file we include comments like <!-- Tested on Chrome 146, Firefox 115 -->.
The result is a disposable test bed: by opening case-1-loop.html in a browser (or via Puppeteer/Playwright script), we can watch console logs and the error event. Every callback prints a message, so we can trace which observers ran. The final size log (inside rAF) acts as our observed output. All console output (including errors) should be captured to evidence files.
4: Author the independent expected-case manifest
Before running any tests, we write down what we should observe for each case. This manifest (like an oracle) is independent of the browser’s output. For clarity, we define each case with an ID, scenario, expected outcomes, and expected errors. For example:
manifest.tsv (EXPECTED / NOT EXECUTED)
case | description | expect_error | expected_delivered | expected_skipped |
C01_loop | Parent→child1→child2 cycle | Yes | parent.width (initial), child1.width, child2.width | child2→parent update |
C02_safe | Deferred-parent update (negative control) | No | parent.width (initial), child1.width, child2.width | none |
C03_simple | Single-depth resize (valid case) | No | parent.width (initial), child1.width | none |
· C01_loop: We expect a loop error. Delivered changes (in the errored frame) are the parent’s initial manual resize (to 300px) plus the child1 and child2 increments. The child2→parent update should be skipped due to the error.
· C02_safe: With the deferred update, no loop error. All intended changes (parent initial 300px, child1 +50, child2 +50) should occur synchronously in two frames. No skips.
· C03_simple: A simpler case: only parent changes child1, child1 changes itself (no cycle). No error and no skipped changes.
Each entry lists the expected_delivered layout changes (which widths/styles should have changed by the end of the frame) and expected_skipped (what a loop scenario would skip). This manifest is our truth: it was written from reasoning about depth rules, not by inspecting any actual run. It is not derived from the code’s output; that must come later. (This follows best practice: the SQLite UPSERT playbook similarly writes a .tsv oracle in advance.)
5: Reproduce the misleading success signal
For case C01, the following output is expected; the case has not been executed. The browser should log the intermediate messages and error. The key is checking if the observed console output matches the manifest expectation. We anticipate:
· The parent and child1 and child2 callbacks will print their messages before the error. According to our design, console output should be:
Parent callback: child1 increased
Child1 callback: child2 increased
Child2 callback: parent increased
· Immediately after, a window.error event with message “ResizeObserver loop completed with undelivered notifications” should appear.
· Our final size log (in the next animation frame) should report: parent.clientWidth=300, child1.clientWidth=100 (50+50), child2.clientWidth=100 (50+50). The attempted parent increment (+50 from child2) is skipped, so parent remains at 300.
Expected outcome (from manifest): An error event is fired (Yes). Delivered changes: parent width=300, child1=100, child2=100. Skipped: parent’s +50 update (so parent stays 300).
If instead we see no error or different sizes, that indicates a problem. For example, if the console shows only two callbacks, the loop aborted early; or if parent became 350, the skip didn’t happen (contradicting spec). Any deviation causes FAIL.
We log these observations (ideally in files like stdout.txt and stderr.txt). For this case, we would mark observations versus expected.
6: Run the contrasting valid case
Next we test C02, the negative control (deferred update) and C03, the simple non-loop case. In C02, since we used requestAnimationFrame in the child2 callback (breaking the same-frame cycle), the loop-error should not fire. The delivered changes per frame would be: parent→300, child1→100, child2→100 across two frames. We must see no Window error event. Final sizes should be (parent=300, child1=100, child2=100).
In C03 (a control with no cycle), perhaps we only resized child1 from parent and didn’t involve child2 or back-edge. We should also see no error, and all changes delivered immediately (since depths only go deeper).
Expected outcome: Both C02 and C03 should NOT trigger a loop error. If an error appears here, that violates our negative-control assertion (and would be a strong red flag). Otherwise, we verify final sizes against the oracle (they should match manifest).
Assertion: We explicitly assert that in these cases the Window error event must not fire. If it does (e.g. an unexpected “loop completed” message), we record a failure. Conversely, if the final sizes do not match the expected values (even without an error), we mark FAIL.
7: Test failure and boundary inputs
We also consider failure modes and boundary conditions. For example: what if an element is given display: none or zero size? ResizeObserver does not report for display:none, which could skip observations entirely. We should include a case C04 with one element set to display:none or dimension zero. In this case, no callbacks should fire for that element (and certainly no loop error since nothing happens). The expected behavior: listeners on hidden elements get no entries.
Another boundary: extremely large size or recursive styles (doesn’t strictly affect ResizeObserver, but check for overflow). Possibly test a deeply nested chain beyond three elements to see if depth logic holds (just for stress).
These are more sanity checks; we expect no new kind of behavior. If any unexpected error occurs (e.g. console error in devtools), we record it. However, these cases are not core “acceptance criteria”; they mainly check fixture robustness.
8: Capture a complete per-case evidence ledger
We tabulate all the evidence and decisions per case. Each row records Case ID, purpose, expected outcome, and execution status. For example:
Case | Purpose | Expected Outcome | Execution Status | Decision |
C01_loop | Cycle-resize triggers loop | parent+child1+child2 resized, error thrown, parent’s second update skipped | EXPECTED / NOT EXECUTED | HOLD |
C02_safe | Deferred update (negative control) | parent+child1+child2 resized, no error | EXPECTED / NOT EXECUTED | HOLD |
C03_simple | Single-depth resize (no loop) | parent+child1 resized, no error | EXPECTED / NOT EXECUTED | HOLD |
C04_hidden | Element with display:none | No resize events (nothing changes) | EXPECTED / NOT EXECUTED | HOLD |
Integrity | Consistency of final DOM state | No unexpected elements/styles | EXPECTED / NOT EXECUTED | HOLD |
Version | Runtime version pinning | Chrome 146, Firefox 115, Node 20.8 | EXPECTED / NOT EXECUTED | HOLD |
Each “EXECUTION STATUS” is labeled EXPECTED / NOT EXECUTED because these cases have not been executed. This ledger would normally be filled after running tests, but we prepare the schema in advance. If a future run were done, one would replace these with PASS/FAIL and remove the “NOT EXECUTED” flag.
Detect incomplete evidence: A critical check is that every case has some result. If any case were missing (e.g. no log output captured), we would consider the evidence incomplete. For example, if the loop error in C01 never appears and our log has no “Error:” line, that would violate our contract (“error must fire”) and we would mark that evidence missing (REQ RERUN or HOLD).
9: Reconcile expected and observed state
Once tests run, we compare the observed outputs to the manifest. For each case, we check:
· Elements’ final sizes: Match the manifest. For C01, final sizes should be parent=300, child1=100, child2=100. If we instead saw parent=350, that would contradict our expectation (the skip didn’t happen).
· Presence of error event: Occurred exactly when and where expected. C01 should see it, C02/C03/C04 should not.
· Sequence of events: The order of console logs should match our causal chain. If “Child2 callback” appears before “Child1 callback”, something is wrong in our observer ordering.
If all observed values match the manifest, each case passes. If any discrepancy is found (size, missing log, extra error, etc.), the case fails. For instance, if C01’s observed data showed (300, 150, 100) instead of (300, 100, 100), we’d identify that the parent was erroneously resized by child2. That would be a bug in either our understanding or the browser’s implementation.
In short, we reconcile by checking each column of the table: expected vs actual for size and error. Any failure yields a FAIL for that case. We do not simply accept a zero error code; we need data matching our oracle. This mirrors the SQLite acceptance (comparing final DB state to the independent manifest).
10: Distinguish documented guarantees from observations
The ResizeObserver spec and MDN document clearly define the loop behavior: deeper-only delivery and deferred notifications. We explicitly compare the documented guarantee to our observed results. For example: MDN states that “Resize events that don’t meet that condition are deferred to the next paint”. In our case, C01 should defer the parent’s last update to the next frame. If our observed result matches that (we see the skip), we have confirmed the spec. If not, there’s a violation of the spec promise.
We also review authoritative docs: the CSS Working Group specification provides the exact loop-error algorithm. We cite these norms as our contract. In the observed data, we tag whether the spec’s promise held. Any departure (e.g. browser never fires the error at all, contrary to spec) would be logged as an unsupported guarantee.
Prove the repair does not widen scope: If a repair is needed (see next section), we must ensure it doesn’t affect unrelated behavior. For instance, if we fix C01 by adding requestAnimationFrame, we must check C03 (the simple case) still passes. If our fix unexpectedly prevented even safe changes, that would “widen scope” of the repair incorrectly. We explicitly assert: “After repair, negative-control behavior remains correct.” If a supposedly safe case now fails, the repair widened scope inappropriately and we need a more targeted fix.
11: Implement a bounded repair
Given our findings, we evaluate fixes. The goal is minimal change to satisfy the contract without altering valid behavior. A known pattern (from MDN) is to defer writes to break the same-frame loop. For C01, we could modify the callback on child2 to use requestAnimationFrame(() => incWidth(parent,50)) instead of changing parent immediately. This defers the parent update to the next frame, avoiding an in-sync cycle. In code, that changes one line:
// In child2 observer callback:
new ResizeObserver(entries => {
entries.forEach(entry => {
// Original: incWidth(parent, 50);
requestAnimationFrame(() => {
incWidth(parent, 50);
console.log("Child2 callback (rAF): parent increased");
});
});
}).observe(child2);
This repair is bounded: it only delays the one write, not removing any logic. We then re-run the same tests. Now we expect C01 to no longer trigger the loop error (the cycle is broken). The new expected behavior (if we change C01 this way) is identical to our C02 manifest: no error, all three changes applied over two frames.
After applying the fix, we verify C01 again: it should match C02’s previous expected outcomes. We also check that C02 and C03 still behave as before (they should; they already had no error). If the fix changed their outcome, that signals an over-broad repair. For example, if adding rAF prevented child1 from resizing at all, that’s too much.
Explicit assertion: After the fix, we assert “no unintended side-effects.” We compare post-repair observed state for each case to its original manifest. The only expected difference is that C01’s error is gone. If we detect any additional changes (extra logs, missing updates, etc.), we mark the repair as failing “boundedness.”
12: Validate recovery and safe reruns
We must ensure that after an error or a previous run, the system can be safely re-tested. In particular:
· State rollback: If the loop error left the DOM in a partial state, we should be able to restore it (e.g. reload the page) and rerun the observers. For example, if C01 ended early, we reload and reapply parent.style.width=300px to try again. This checks idempotence.
· Rerun stability: If a case is fixed or rerun, we expect the same outcome each time. We document that the repair fix does not require special ordering. (In SQLite testing, this is akin to verifying that a rollback probe does not change scope.)
Concretely, after each test run we either refresh the fixture or create a fresh DOM instance. We then run the observers again. The outcomes should be consistent with the manifest or with the repaired manifest. This ensures no hidden state is interfering. For example, after observing the loop error in C01, we might programmatically disconnect and reconnect the observers and try resizing again; it should consistently skip that parent update.
We also capture artifacts from the failed run before retrying. For instance, if C01 errored, we save the console log and final DOM snapshot. This “failed-run artifact” ensures we don’t lose evidence. Only after saving it do we clear the state. This way we can compare before/after.
Assign the evidence owner
Each part of evidence should be traceable to an engineer. In practice we note who “owns” the review of a case or manifest: e.g., QA Engineer Jane checks C01 loop test, DevOps Specialist Raj checks version pin. If we find a mismatch, the responsible owner is known. In our notes, we annotate each case or table row with initials or team (as in a review checklist). For example, “C01: JS Engineer” or “Fixture integrity: QA”. If evidence is incomplete, that owner will be asked to rerun or correct it.
13: Apply the ACCEPT / REPAIR / RERUN / HOLD matrix
Finally we use a decision matrix to draw the conclusion, similar to the SQLite playbook approach. The criteria are: evidence completeness, manifest match, negative control pass, and integrity. Summarizing:
Outcome | Status | Decision | Meaning |
All cases executed, negative control passed, observed state matches manifest (loop error behaved as documented) | Complete/OK | ACCEPT | Behavior matches the spec for this release. |
Some case shows documented contract violation with only limited scope (e.g. only C01 mismatches) | Complete enough | REPAIR | Behavior deviates: code or contract needs fix. |
Test execution failed, setup incomplete, or versions wrong | Invalid/incomplete | RERUN | Insufficient evidence; rerun tests. |
Contradictory or ambiguous results (e.g. unexpected error in neg control) | Contradictory | HOLD | Results unclear or out-of-scope; further review. |
For this unexecuted fixture, the decision is HOLD. Indeed, before running any code, we cannot declare ACCEPT or REPAIR. This matches the guidance in similar playbooks: an unexecuted fixture remains on HOLD because calling it ACCEPT would invent results. We will only move off HOLD once we have actual, complete evidence.
For completeness, here is the rule formula (adapted from SQLite) we intend for the future:
ACCEPT = pinned_versions_ok
AND all_cases_executed
AND manifest_matches_observed
AND negative_control_passes
AND no_unexpected_errors
AND integrity_verified
Any unmet condition can push us to RERUN, REPAIR, or HOLD as defined above.
14: Connect the practice to Refonte Learning
This playbook illustrates an advanced frontend testing practice. While the Refonte Frontend Development program focuses on core web skills (HTML5, CSS3, JavaScript, React, etc.), the debugging and validation techniques shown here go deeper. Frontend engineers may encounter layout-feedback issues like this in complex UI components. Mastery of browser devtools (for listening to Window error events) and writing test fixtures is encouraged for senior roles.
For readers interested in structured learning, Refonte’s Frontend Development program offers projects and mentorship in modern web technologies (HTML, CSS, JavaScript ES6+, React, responsive design). That curriculum builds the foundation for understanding how to debug rendering issues. However, the specific ResizeObserver behavior is an edge case beyond any standard course outline; it’s a great candidate for self-study or on-the-job learning after completing a formal program. Engineers who finish a frontend program are better prepared to write the kinds of automated tests shown here, even if the course did not explicitly cover ResizeObserver loops.
Final decision: As of now, with no executed evidence, we must HOLD. We have a clear plan and artifact design; the documented contract is based on official spec. Once the tests are run with our fixture, we will follow the matrix above to decide ACCEPT or REPAIR. Until then, the conservative action is to treat this as a live issue under investigation.