A byte stream can be completely valid UTF-8 and still turn into damaged JavaScript text if the consumer mistakes every arbitrary chunk for a complete input. That is the failure this playbook isolates. The eleven source bytes here encode exactly A€é🙂Z. Nothing in the fixture is malformed. The damage appears only when six deliberately awkward byte partitions are decoded independently: the default replacement policy turns split multibyte sequences into eight U+FFFD replacement characters. Switching only to fatal:true is not the repair; it rejects the first valid but unfinished prefix instead.
The correct boundary is a decoder lifecycle, not a per-chunk call. One TextDecoder owns one logical input. Intermediate calls use stream:true, so an incomplete scalar at a temporary chunk boundary remains pending. When the caller knows the logical input is over, a final decode() without stream:true closes the decoder. In fatal mode, that last transition is what distinguishes “temporarily incomplete, wait for more bytes” from “permanently incomplete at end of input, reject.” The WHATWG Encoding Standard’s TextDecoder contract explicitly describes fragmented input as zero or more streaming calls followed by one non-streaming call. The living standard displayed “Last Updated 19 October 2026” when checked on October 24, 2026; that page date is not evidence that this longstanding API was introduced in 2026.
The supplied preparation environment is Node.js v24.22.1 with ICU 78.3 on Linux, using node:util’s WHATWG-compatible TextDecoder, Uint8Array, and node:string_decoder. This is a deterministic local API experiment, not a browser certification, network test, compression test, or claim about every Node build. The goal is narrower: preserve the byte/chunk ledger, prove decoder finalization, stage candidate text, and make a bounded publish decision only after the declared input has been fully admitted.
Define the exact text the consumer is allowed to publish
Start with the application contract, not with whatever string happens to come back from decode(). The accepted fixture is the five-scalar sequence A\u20ac\u00e9\u{1f642}Z, displayed as A€é🙂Z. Its independent scalar oracle is [0x41, 0x20ac, 0xe9, 0x1f642, 0x5a]. Its complete UTF-8 byte sequence is [41, e2, 82, ac, c3, a9, f0, 9f, 99, 82, 5a] in hexadecimal. RFC 3629 describes UTF-8 as one to four octets per Unicode scalar value, with continuation octets constrained to the 10xxxxxx form; those structural rules explain why the euro sign, e-acute, and smiling face can be split across transport-sized byte pieces even though each scalar is encoded by a single valid UTF-8 sequence.
Scalar | Code point | UTF-8 bytes | Bytes | JavaScript UTF-16 code units |
A | U+0041 | 41 | 1 | 1 |
€ | U+20AC | e2 82 ac | 3 | 1 |
é | U+00E9 | c3 a9 | 2 | 1 |
🙂 | U+1F642 | f0 9f 99 82 | 4 | 2 |
Z | U+005A | 5a | 1 | 1 |
Those identities must remain separate. “Eleven bytes” describes the encoded source. “Five scalars” describes the Unicode sequence. The finished JavaScript string has a length of six because ECMAScript string length counts UTF-16 code units and 🙂 occupies a surrogate pair; that count is neither the byte count nor the scalar count. The harness therefore checks CHUNKS.flat().length === 11, [...EXPECTED].length === 5, and the explicit code-point array. It does not derive the oracle by asking the decoder under review to encode or decode its own expected value.
The publication states are also declared before diagnosis. ACCEPT applies only to the exact valid fixture after strict streaming, successful finalization, and exact content comparison. REPAIR applies to the stateless chunk-decoding path because it damages valid input. HOLD_UNFINALIZED applies while a logical input has not yet crossed its terminal decoder transition. REJECT applies to malformed bytes, a truncated terminal scalar, or any path that returns text inconsistent with the exact contract. RERUN applies when the runtime changes or the evidence needed to qualify that runtime is incomplete.
This is earlier in the data path than preserving large JSON identifiers. That adjacent Refonte Learning article begins with JSON text and studies numeric identity after parsing; its own page states that JSON.parse can succeed while an unsafe numeric identifier changes value. Here there is no JSON.parse call at all. The question is whether the bytes become the intended Unicode text before any JSON, CSV, DOM, or application grammar sees them.
Identify the byte layer entering the decoder
The fixture begins at a deliberate boundary: the consumer already has the intended UTF-8 bytes, in declared order, as Uint8Array inputs. There is no character-set detector and no legacy conversion step. There is also no claim that the chunks correspond to packets, HTTP chunks, file blocks, worker messages, or any other external framing unit. They are simply six arbitrary byte partitions chosen to cross multibyte UTF-8 sequences.
That distinction matters because a decoder cannot fix an upstream representation mistake. If compressed bytes, encrypted bytes, base64 text, or a different charset are passed to a UTF-8 decoder, decoder lifecycle discipline does not make the input semantically correct. The related article on choosing the correct download byte layer demonstrates a different representation question: compressed and decompressed artifacts have different byte counts and hashes. This laboratory deliberately starts after any such content-coding decision. Compression, HTTP framing, network order, and transport EOF authenticity are excluded so that one boundary, the UTF-8 byte-to-text transition, can be inspected without confounding layers.
The Node.js v24.22.1 util.TextDecoder documentation describes util.TextDecoder as an implementation of the WHATWG Encoding Standard API. Its v24.22.1 documentation says decode() accepts an ArrayBuffer, DataView, or typed array; stream:true means more chunks are expected; and an incomplete byte sequence at the end of a streaming input is buffered for a later call. The same page states that fatal decoding errors throw TypeError. The documentation also warns that fatal is unavailable when ICU is disabled, which is why “Node 24” by itself is not sufficient qualification evidence; the preparation record pins ICU 78.3 rather than inferring behavior from a major version.
Node’s Buffer documentation is useful corroborating context but not an extra executed test here. It documents UTF-8 as a multibyte encoding and says invalid UTF-8 decoded through Buffer string conversion is represented with U+FFFD. The preparation matrix’s corruption case, however, uses TextDecoder exactly as shown in the supplied driver. The evidence ledger does not include a separate Buffer.toString() test.
The operational rule is therefore simple but strict: preserve the identity of the bytes handed to the decoder, preserve their order, and do not let the fact that some call returned a JavaScript string blur the distinction between a chunk and a complete logical message. API success for one chunk is evidence about that call, not authorization to publish the logical input.
Freeze the runtime and the six-chunk manifest
Reproducibility starts by freezing both runtime and source. The supplied preparation record reports Node.js v24.22.1, ICU 78.3, Linux, and PASS_12_CASES. The official Node v24.22.1 archive identifies the release’s V8 version as 13.6.233.17. The source SHA-256 is 3db4c2fca52ac4fe0146dbe61c527c6d8dd4b3c53075d0411f45ac198fa37ede. The driver itself records process.version, process.versions.v8, process.versions.icu, process.platform, os.release(), and UTC start/finish timestamps in the JSON result.
The preparation record identifies the Node version, ICU version, Linux platform, digest, and overall status, but its summary does not include the exact os.release() value or run timestamps. Read those fields from the retained preparation JSON. The observations below come from that preparation evidence, not a fresh Node.js v24.22.1 execution for this article. Any rerun needs its own environment fields and timestamps rather than inheriting the earlier digest-and-runtime label.
The six declared chunks are fixed literals:
Chunk | Hex bytes | Boundary meaning | Strict streaming fragment | Logical pending UTF-8 prefix after call |
1 | 41 e2 | A plus first byte of € | A | e2 |
2 | 82 | second byte of € | empty string | e2 82 |
3 | ac c3 | completes €, starts é | € | c3 |
4 | a9 f0 9f | completes é, starts 🙂 | é | f0 9f |
5 | 99 | third byte of 🙂 | empty string | f0 9f 99 |
6 | 82 5a | completes 🙂, then Z | 🙂Z | none |
The “pending” column is a logical explanation of the known fixture and specified decoder state, not a claim that JavaScript exposes an inspectable internal byte buffer. The WHATWG algorithm preserves decoder state across streaming invocations by not flushing at end-of-queue when stream:true; Node describes incomplete trailing sequences as buffered internally. An empty fragment in chunks 2 or 5 is therefore normal. It means the decoder has not yet completed a scalar to emit; it is not evidence that a byte disappeared.
Count bytes, code units, and scalar values separately
This ledger prevents a common review mistake: treating what is visible in a terminal as the oracle. The expected string contains five scalar values, six JavaScript UTF-16 code units, and eleven UTF-8 bytes. The smiling face alone accounts for four UTF-8 bytes but two UTF-16 code units. The byte manifest and explicit code-point array are independent of the decoder path being tested, which is exactly what a diagnostic oracle needs.
The same separation applies to fragments. A call can return "" while retaining a valid incomplete sequence. A later call can return more than one scalar because it both completes prior state and consumes new complete input. Fragment count is therefore not character count, and chunk count is not message count. The lifecycle owner must carry one decoder through all six chunks and close it once, rather than treating six JavaScript calls as six independent text documents.
Reproduce corruption when every chunk is treated as complete
T1 and T2 establish that the apparatus can succeed before the boundary failure is introduced. T1 decodes three ASCII chunks and produces ABC. ASCII bytes 00 through 7f are single-byte UTF-8 values, so there is no multibyte state to preserve across those particular boundaries. RFC 3629 explicitly notes that US-ASCII characters keep their normal one-octet values in UTF-8. T2 then decodes all eleven fixture bytes in one call with fatal:true and returns A€é🙂Z, showing that the complete source byte sequence is valid under the strict decoder.
T3 changes only the call boundary. It creates one tolerant TextDecoder but calls decode(chunk) with the default stream:false for every one of the six pieces. Each call is therefore presented as an end-of-input transition. The WHATWG decoding machinery uses replacement mode by default; when a decoder reports an error under replacement mode, U+FFFD is pushed to output. The bytes are not corrupt, but the caller repeatedly asserts false end-of-input boundaries.
The resulting byte/chunk ledger makes the damage explicit:
Chunk | Bytes | Default nonstream fragment | Why that fragment appears |
1 | 41 e2 | A� | 41 is complete; e2 is unfinished at this call’s declared end |
2 | 82 | � | continuation byte has no retained leader |
3 | ac c3 | �� | ac is orphaned; c3 is unfinished at end |
4 | a9 f0 9f | �� | a9 is orphaned; f0 9f is unfinished at end |
5 | 99 | � | continuation byte is orphaned |
6 | 82 5a | �Z | 82 is orphaned; 5a is ASCII Z |
Assembled, T3 is A + eight U+FFFD characters + Z. The important diagnosis is not “the source contained replacement characters.” It did not. The replacement characters are observable output introduced by the selected decoding lifecycle. The default end-of-input behavior is being invoked at boundaries that the application knows are temporary.
Fatal mode alone rejects a valid unfinished prefix
T4 is the counterexample to the simplistic repair “just set fatal:true.” The first chunk is [41,e2]. 41 is A; e2 is the valid lead byte of a three-byte sequence, but two continuation bytes are still required. With stream:false, the call reaches end-of-queue while the UTF-8 decoder still needs bytes. The Encoding Standard specifies that end-of-queue with a nonzero “bytes needed” state is a decoding error, and fatal mode converts a decoder error into TypeError.
The harness records T4 as TypeError at chunk-1 with no returned text. That wording matters. The parts.push(d.decode(...)) operation runs only if the call returns; when the call throws, the harness does not capture a fragment from the throwing call. It is therefore wrong to infer that T4 “returned A and then threw.” It is also wrong to infer an exact internal byte-error offset merely from stage: "chunk-1". The safe conclusion is narrower: strictness without streaming state rejects a valid unfinished prefix, so fatal:true alone cannot repair arbitrary chunking.
Keep one decoder alive across the logical stream
T5 and T6 use the same eleven bytes and the same six partitions as T3. The change is decoder ownership: one TextDecoder instance survives across the complete logical input, and every nonterminal call uses {stream:true}. The WHATWG contract is unusually direct here: fragmented input is processed by invoking decode() zero or more times with streaming enabled, then once without streaming enabled; the standard’s example ends with string += decoder.decode() to signal end-of-queue. Node v24.22.1’s documentation describes the same behavior in implementation terms: trailing incomplete byte sequences are buffered when stream:true and can be emitted after later input arrives.
T5 uses that lifecycle in tolerant mode. Its fragments are A, "", €, é, "", 🙂Z, followed by "" from the final flush. Joined together, they produce the exact expected string. The empty returns after chunks 2 and 5 are positive evidence about stateful decoding, not anomalies to “fix.” After chunk 2, the decoder has seen e2 82 and still needs the euro sign’s final ac. After chunk 5, it has seen f0 9f 99 and still needs 82 to complete U+1F642. The subsequent chunks finish those sequences without replacement.
T6 adds fatal:true while retaining the same stream lifecycle. It also produces A€é🙂Z and completes its final flush without error. This is the candidate configuration for exact-text admission because the three concerns are now separated: stream:true keeps valid intermediate state, fatal:true rejects actual decoding errors, and the nonstreaming final call declares that no more bytes will arrive.
The decoder should be treated as message-scoped state. Create it when one logical UTF-8 input begins, feed every byte chunk for that input to the same instance, finalize once when that input is declared complete, then discard or deliberately reset ownership. Do not create a fresh decoder per chunk: that recreates T3/T4. Do not share one active decoder across unrelated logical messages: pending bytes from one lifecycle must not become context for another message. The WHATWG algorithm starts a fresh decoder at the beginning of a new input lifecycle; a call following stream:true continues the existing state, including the final nonstreaming flush.
For this fixture the qualifying pattern is therefore:
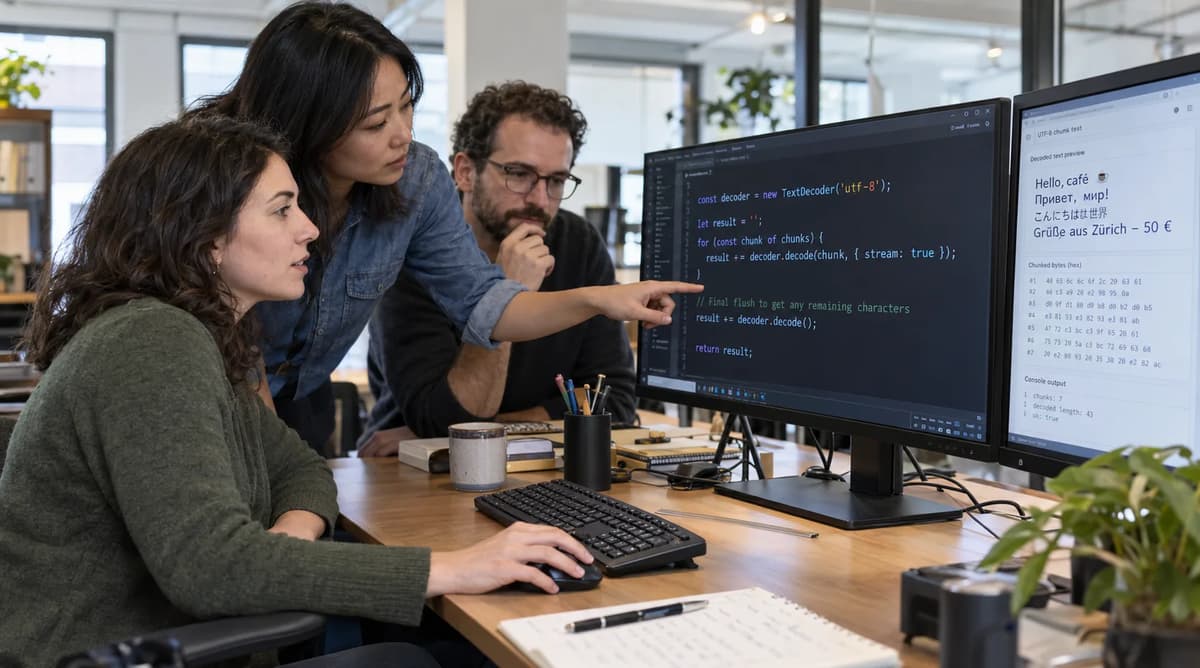
const decoder = new TextDecoder('utf-8', { fatal: true });
let staged = '';

for (const bytes of chunks) {
  staged += decoder.decode(bytes, { stream: true });
}

staged += decoder.decode(); // explicit end-of-input transition
That code is necessary but not sufficient for publication. staged still needs the application’s comparison or semantic admission rule, and the final call must actually have completed. Decoder correctness answers whether the encoded bytes form text under the chosen encoding policy; it does not establish that the resulting text is the intended business object.
Finalize the decoder before declaring the input valid
The strongest proof in the fixture is the difference between T7 and T8. Both receive the truncated source [[0x41],[0xe2,0x82]]. The bytes decode far enough to produce A, then end with two bytes of the three-byte euro-sign sequence. While the decoder is still in streaming mode, that suffix is only temporarily incomplete. There is no error yet because the caller has explicitly said that more bytes may follow. Node’s stream option is defined precisely as the case where additional chunks are expected.
T7 intentionally stops there. Its text is A; its error is null; and final_flush_completed is false because the code was called with flush:false. The correct decision is HOLD_UNFINALIZED, not ACCEPT. “No exception so far” is not a whole-input verdict. The decoder has not been asked to process true end-of-input, and the known source contains pending state.
T8 supplies the missing lifecycle transition by calling d.decode() with no input and default stream:false. Now the same pending e2 82 is no longer an intermediate prefix. It is an unfinished terminal scalar. The UTF-8 decoder specification says that encountering end-of-queue while bytes are still needed returns an error; because this decoder is fatal, TextDecoder.decode() throws TypeError. T8 is therefore REJECT_TRUNCATED, with the error stage recorded as final-flush.
T9 proves why tolerant finalization is different from strict admission. It uses the same truncated bytes with stream:true but leaves fatal at its default false value. The final decode() returns normally and emits U+FFFD for the unfinished sequence, producing A�. That behavior is consistent with the standard replacement error mode. The call’s normal return does not satisfy this fixture’s exact-text policy, so T9 is rejected by content comparison rather than by exception.
The final flush should occur only when the input owner can truthfully say the logical byte sequence is finished. Calling it after every chunk is T3/T4 by another name. Never calling it leaves T7’s uncertainty unresolved. The lifecycle state can be summarized as: open while more bytes may arrive; finalizing at the one declared end-of-input transition; accepted only after finalization succeeds and application checks pass; or rejected if decoding or later admission fails.
Treat a returned prefix as provisional until the final decision
T8 has already returned A from a completed earlier call before the final flush fails. That prefix is useful diagnostic evidence and should remain in the ledger, but it is not an approved publication. The same is true for T10: valid earlier fragments can exist before a later malformed sequence is discovered.
Staging is what preserves that distinction. Accumulate returned fragments in memory or another bounded provisional store, then expose the candidate only after successful finalization and policy checks. This laboratory’s finite fixture makes that easy. In a real integration, staging cannot retroactively undo side effects that were already committed. If code streams each returned prefix into a DOM mutation, database write, event, or externally visible response before final admission, a later TypeError does not roll those effects back. The decoder reports state; the application owns the commit boundary.
Distinguish StringDecoder buffering from strict validation
node:string_decoder solves one part of the same boundary problem: it retains incomplete multibyte characters across writes. The Node.js v24.22.1 StringDecoder documentation says StringDecoder uses an internal buffer so incomplete multibyte characters are omitted from a write() result until a later write() or end() can complete them. That makes it useful as a comparison because it shows that preserving split characters and enforcing a fatal validation policy are different requirements.
T12 feeds the truncated source through StringDecoder('utf8'). The first write emits A. The second write receives e2 82 and retains the unfinished euro-sign bytes. Then end() closes the input. Node documents that end() returns remaining buffered input and replaces bytes representing incomplete UTF-8 or UTF-16 characters with substitution characters. The preparation observation is therefore A�, with no exception.
For a display-oriented tolerant path, that behavior may be completely appropriate. For this article’s exact-text acceptance rule, it is not. The requirement is to reject an unfinished terminal UTF-8 scalar, not silently materialize a replacement character and call the logical message valid. T12 is consequently a passing test case whose application decision is rejection. Its success means the harness observed the expected tolerant behavior; it does not mean the truncated input is publishable.
There is no performance claim here and no assertion that one API is universally “better.” StringDecoder and TextDecoder expose different policy surfaces. The relevant distinction is observable error handling: the strict TextDecoder configuration can throw on malformed or truncated final input, while StringDecoder.end() is documented to substitute incomplete characters. Choose the API whose contract matches the admission requirement, and record that choice as part of the message lifecycle rather than assuming that buffering alone equals validation.
Preserve a genuine replacement character in valid input
U+FFFD is a Unicode scalar value. It can appear because a tolerant decoder substituted for invalid input, but it can also be the literal content the producer encoded. T11 exists to prevent a dangerously convenient validator: “reject every JavaScript string containing �.” That rule confuses an output glyph with its provenance.
The T11 bytes are ef bf bd, the valid UTF-8 encoding of U+FFFD, deliberately split as [ef] and [bf,bd]. One persistent TextDecoder('utf-8', {fatal:true}) processes the first chunk with stream:true, retains the incomplete sequence, receives the remaining bytes, and returns the literal replacement character without error. Finalization also succeeds. The WHATWG UTF-8 decoder accepts 0xef as a valid three-byte leader and continuation bytes within the required ranges; separately, the standard’s replacement error mode uses U+FFFD when an actual decoder error occurs. Those are two distinct source paths to the same scalar value.
Under the synthetic T11 control, literal U+FFFD is therefore accepted because the byte transition is valid and the test’s declared text contract allows it. That does not mean every production application must permit U+FFFD semantically. An application may define a narrower content rule. The point is that string scanning cannot establish UTF-8 validity: the same displayed character can represent either legitimate source data or tolerant error substitution.
Validate the byte transition instead of guessing from the glyph
The evidence should preserve raw bytes, decoder mode, lifecycle state, returned fragments, and any thrown error. Then a reviewer can answer “where did this U+FFFD come from?” rather than guessing from display output. T9 and T12 reach A� through tolerant handling of a truncated sequence. T11 reaches � from the valid bytes ef bf bd under fatal streaming. A universal text.includes('\ufffd') rejection would classify all three alike and destroy exactly the distinction the byte ledger was built to retain.
This is also why a replacement character is not proof that the original source was malformed unless the decoder path that produced it is known. The Node.js v24.22.1 Buffer documentation describes replacement behavior for invalid UTF-8, but that documented behavior does not turn U+FFFD itself into an error flag. Validate the transition and then apply an explicit application content rule.
Run the complete twelve-case evidence harness
The harness is intentionally small enough to review as one artifact. It does not generate the expected text by decoding the fixture; EXPECTED, the scalar array assertion, and the literal byte arrays are separate inputs to the test. It also records fragments rather than only the joined string, which lets QA distinguish “nothing emitted yet” from replacement or failure. On exceptions, only fragments returned by earlier completed calls remain in parts; the throwing call is not treated as though it returned a partial string.
The supplied preparation reports PASS_12_CASES under Node.js v24.22.1 with ICU 78.3, using source SHA-256 3db4c2fca52ac4fe0146dbe61c527c6d8dd4b3c53075d0411f45ac198fa37ede. Node’s v24.22.1 documentation identifies util.TextDecoder as WHATWG-compatible, and the release archive identifies V8 13.6.233.17. The exact kernel string and run timestamps are fields emitted by this source but were not included in the preparation summary; read these fields from the retained JSON.
Save the exact file as textdecoder_lab.mjs and run:
node textdecoder_lab.mjs > textdecoder-results.jsonReview both the process exit status and the JSON status. PASS_12_CASES means every expected diagnostic observation matched. It does not mean every case’s input is acceptable; several tests pass precisely because malformed or truncated candidates are rejected.
import assert from 'node:assert/strict';
import { createHash } from 'node:crypto';
import { readFileSync } from 'node:fs';
import { TextDecoder } from 'node:util';
import { StringDecoder } from 'node:string_decoder';
import os from 'node:os';

const EXPECTED = 'A\u20ac\u00e9\u{1f642}Z';
const CHUNKS = [[0x41,0xe2],[0x82],[0xac,0xc3],[0xa9,0xf0,0x9f],[0x99],[0x82,0x5a]];
const TRUNCATED = [[0x41],[0xe2,0x82]];
const report = {status:'RUNNING', started_utc:new Date().toISOString(),
  node:process.version, v8:process.versions.v8, icu:process.versions.icu ?? null,
  platform:process.platform, kernel:os.release(),
  source_sha256:createHash('sha256').update(readFileSync(new URL(import.meta.url))).digest('hex'),
  cases:[]};

function decode(chunks,{fatal=false,stream=false,flush=true}={}) {
  const d=new TextDecoder('utf-8',{fatal});
  const parts=[];
  let error=null;
  let stage=null;
  try {
    for(let i=0;i<chunks.length;i++) {
      stagechunk-${i+1};
      parts.push(d.decode(Uint8Array.from(chunks[i]),{stream}));
    }
    if(flush) {
      stage='final-flush';
      parts.push(d.decode());
    }
  } catch(e) {
    error={name:e.name,stage};
  }
  return {parts,text:parts.join(''),error,final_flush_completed:flush && !error};
}

function check(id,result,expectedText,expectedError,expectedStage,decision) {
  assert.equal(result.text,expectedText${id}: text);
  assert.equal(result.error?.name ?? null,expectedError${id}: error);
  assert.equal(result.error?.stage ?? null,expectedStage${id}: stage);
  report.cases.push({id,...result,decision});
}

try {
  assert.equal(CHUNKS.flat().length,11);
  assert.equal([...EXPECTED].length,5);
  assert.deepEqual([...EXPECTED].map(c=>c.codePointAt(0)),[0x41,0x20ac,0xe9,0x1f642,0x5a]);
  assert.equal(new TextDecoder('utf-8',{fatal:true}).fatal,true);
  check('T1',decode([[65],[66],[67]]),'ABC',null,null,'ACCEPT_ASCII_CONTROL');
  check('T2',decode([CHUNKS.flat()],{fatal:true}),EXPECTED,null,null,'ACCEPT_WHOLE');
  check('T3',decode(CHUNKS),'A'+'\ufffd'.repeat(8)+'Z',null,null,'REPAIR_CHUNK_DECODING');
  check('T4',decode(CHUNKS,{fatal:true}),'','TypeError','chunk-1','REPAIR_STREAM_STATE');
  check('T5',decode(CHUNKS,{stream:true}),EXPECTED,null,null,'ACCEPT_VALID_FIXTURE');
  check('T6',decode(CHUNKS,{fatal:true,stream:true}),EXPECTED,null,null,'ACCEPT_STRICT_STREAM');
  check('T7',decode(TRUNCATED,{fatal:true,stream:true,flush:false}),'A',null,null,'HOLD_UNFINALIZED');
  check('T8',decode(TRUNCATED,{fatal:true,stream:true}),'A','TypeError','final-flush','REJECT_TRUNCATED');
  check('T9',decode(TRUNCATED,{stream:true}),'A\ufffd',null,null,'REJECT_EXACT_TEXT_MISMATCH');
  check('T10',decode([[65],[0xc3,0x28]],{fatal:true,stream:true}),'A','TypeError','chunk-2','REJECT_MALFORMED');
  check('T11',decode([[0xef],[0xbf,0xbd]],{fatal:true,stream:true}),'\ufffd',null,null,'ACCEPT_LITERAL_REPLACEMENT_CHARACTER');
  const sd=new StringDecoder('utf8');
  const parts=TRUNCATED.map(a=>sd.write(Buffer.from(a)));
  parts.push(sd.end());
  check('T12',{parts,text:parts.join(''),error:null,final_flush_completed:true},
    'A\ufffd',null,null,'REJECT_STRINGDECODER_REPLACEMENT');
  assert.deepEqual(report.cases.map(r=>r.id),Array.from({length:12},(_,i)=T${i+1}));
  const approved=[];
  for(const candidate of [report.cases[5],report.cases[7],report.cases[9]]) {
    const publish=!candidate.error && candidate.final_flush_completed && candidate.text===EXPECTED;
    if(publish) approved.push({id:candidate.id,text:candidate.text});
  }
  assert.deepEqual(approved,[{id:'T6',text:EXPECTED}]);
  report.staged_publication_control=approved;
  report.status='PASS_12_CASES';
} catch(e) {
  report.status='FAIL';
  report.failure={name:e.name,message:e.message};
  process.exitCode=1;
} finally {
  report.finished_utc=new Date().toISOString();
  console.log(JSON.stringify(report,null,2));
}
The twelve-case ledger is the review surface:
Case | Configuration or control | Supplied preparation observation | Application meaning |
T1 | ASCII chunks, default decode | ABC | Positive control |
T2 | Whole valid bytes, fatal:true | A€é🙂Z | Complete source is valid UTF-8 |
T3 | Six chunks, default nonstream | A + eight U+FFFD + Z | REPAIR stateless chunk handling |
T4 | Six chunks, fatal, nonstream | TypeError at chunk 1; no returned text | REPAIR: fatal alone is insufficient |
T5 | Streaming, tolerant, final flush | A€é🙂Z | Partition preserved, but tolerant policy |
T6 | Streaming, fatal, final flush | A€é🙂Z | ACCEPT exact strict-stream candidate |
T7 | Truncated, streaming fatal, no flush | A; no error yet | HOLD_UNFINALIZED |
T8 | Same truncated bytes, final flush | A prefix; TypeError at final flush | REJECT truncated terminal scalar |
T9 | Truncated, tolerant final flush | A� | REJECT exact-text mismatch |
T10 | 41, then c3 28, streaming fatal | A prefix; TypeError at chunk 2 | REJECT malformed sequence |
T11 | ef bf bd split, streaming fatal | literal U+FFFD; no error | Valid literal replacement-character control |
T12 | StringDecoder, truncated, end() | A� | REJECT tolerant substitution |
The harness is evidence for this finite fixture only. It does not test a memory cap, real iterator failure, network backpressure, browser behavior, compression, or worker transfers. Those would be separate integration experiments rather than implied properties of PASS_12_CASES.
Publish only the fully reviewed finite candidate
The staged-publication simulation is deliberately narrower than the full matrix. It considers T6, T8, and T10: a valid strict-stream candidate, a truncated terminal sequence, and a malformed sequence. For each candidate it asks three independent questions: did any decoder error occur, did final flush complete, and does the final text equal EXPECTED? Only T6 satisfies all three, so the retained array is exactly [{id:'T6', text:EXPECTED}].
That policy is stricter than “publish whatever valid prefix has already arrived.” T8 has a valid A prefix and T10 also has a valid A prefix, but each later fails admission. The application therefore stages fragments as provisional data. The commit decision occurs only after the logical source has ended, the strict decoder has finalized successfully, and content comparison has passed. The comparison is appropriate because this fixture has an independent exact oracle. In another application the post-decode rule might instead be a hash, schema, record count, signature, or business predicate; successful UTF-8 decoding alone would still not authorize publication.
The same staging principle appears at a later layer in Refonte Learning’s article on checking complete JSON request consumption: that page separates decoding one JSON value from admitting the entire request before a mutation. The evidence is not interchangeable. Go JSON suffix checking does not prove UTF-8 decoder state, and this TextDecoder final flush does not prove JSON grammar. The useful common principle is simply that a plausible prefix is not the same artifact as a fully admitted logical input.
The concrete release rule for this laboratory is:
Create one strict UTF-8 decoder for one candidate message.
Feed each declared byte chunk with stream:true, retaining only provisional text and bounded source evidence.
When and only when the input owner declares end-of-input, call decoder.decode() with no streaming option.
On any TypeError, reject the candidate; do not publish a previously returned prefix as though the logical message passed.
If finalization succeeds, compare the assembled text with the declared application contract; only then move the staged candidate across the publication boundary.
Make retention bounded before adapting the fixture to a service
The input fixture is eleven bytes, so whole-candidate staging is trivially bounded in the laboratory. A service cannot copy that policy blindly onto an unbounded source. Before adaptation, the owner should define a maximum admitted byte count or another finite retention strategy, a time or lifecycle limit, and an explicit outcome for iterator/upstream failure. Those are proposed integration requirements, not results proved by the twelve cases.
A practical replay plan is to retain, within those limits, the original candidate bytes or an immutable reference to them, their digest, runtime qualification data, decoder-policy version, and the final decision. If a candidate is held because the stream never finalized, do not relabel the current prefix as accepted text. If a reader throws or the upstream source fails, preserve that failure separately from decoder validity. Bounded retention lets a corrected lifecycle be rerun without encouraging unbounded concatenation or pretending that decoder finalization authenticates the transport’s notion of EOF.
Recover from retained bytes instead of repairing damaged text
When T3 has already produced eight replacement characters, the right repair target is the decoding process, not the damaged string. If the original eleven bytes are still available, rerun those bytes through one persistent decoder with stream:true, fatal:true, and an explicit final decode(). Then compare the newly assembled candidate against the independent expected text. That is deterministic repair because the source evidence still contains the information that stateless decoding discarded.
If only A��������Z remains, the lost byte-to-scalar mapping cannot be reconstructed reliably from the string. U+FFFD does not encode “which original bytes were here,” and multiple invalid or prematurely finalized byte patterns can lead to replacement output. T11 makes an even stronger warning: a U+FFFD in text may have been literal valid source data. Therefore, never “repair” replacement-laden text by guessing characters from visual context or replacing every U+FFFD with a favored symbol.
Retention has an ownership dimension as well as a size dimension. Refonte Learning’s separate article on retaining bytes across a worker transfer focuses on whether an ArrayBuffer remains usable after copy or transfer. No worker is used in this laboratory, but the boundary lesson is relevant: replay requires an approved source of bytes to still exist. If an integration transfers, mutates, releases, or overwrites the only byte storage before admission is complete, the decoder may not be able to reproduce or audit the candidate later.
The bounded recovery sequence is therefore: retain approved source bytes within policy; preserve their chunk order and digest; fix decoder ownership rather than editing output text; rerun under a qualified runtime; require successful finalization; compare against the relevant application oracle; and record the new observation as a new run. A runtime, encoding, framing, or policy change is not “the same evidence with a small tweak.” It is a requalification event.
State what a successful UTF-8 run still leaves unproven
A strict, finalized UTF-8 decode proves something important but narrow: under the qualified decoder contract, the supplied byte sequence contains no decoding error at the point where the caller declares end-of-input. It does not prove JSON validity, CSV structure, message ordering, expected record count, authenticity, authorization, business correctness, or that an upstream producer sent every byte it was supposed to send.
That separation is why validating CSV structure after decoding is a downstream concern. That Refonte Learning fixture starts from already decoded Python strings and checks CSV syntax, headers, and row width; it explicitly treats decoding as a prior boundary. This article stops earlier. T6 earns acceptance only because the byte fixture and exact expected text are independently declared. A production parser would still need its own grammar and application checks after text admission.
Successful decoding also cannot prove transport completeness. Suppose the intended document were A€é🙂Z but the source ended cleanly after A€é. Those bytes end on a complete scalar boundary. A strict final flush would succeed because there is no unfinished UTF-8 sequence. The decoder has no knowledge that 🙂Z was expected. Detecting that loss requires evidence such as an expected length, digest, record count, trusted manifest, protocol framing rule, or semantic contract outside UTF-8 decoding.
Character-boundary truncation can remain valid UTF-8
The final flush detects one specific class of incompleteness: an encoded scalar that has begun but cannot finish before end-of-input. It does not detect every missing suffix. RFC 3629 defines validity in terms of legal UTF-8 byte sequences; a shorter sequence containing only complete legal scalars can still be valid UTF-8.
That is why claims such as “final flush guarantees the stream is complete” should be rejected in review. The safe statement is: final flush closes the decoder’s pending state and, in fatal mode, surfaces an unfinished terminal sequence as an error. Exact fixture equality is stronger here only because EXPECTED is known independently. Transport completeness, source authenticity, and business meaning need separate evidence.
Assign decoder ownership and review the release decision
A reliable repair is as much an ownership policy as an API option. The stream-lifetime owner decides when more bytes may arrive and is the only component allowed to trigger finalization. The source-evidence owner keeps bounded replay material and its digest. The decoder owner ensures one TextDecoder instance is scoped to one logical input. The publication owner keeps provisional fragments private until terminal and application checks pass. QA verifies that the ledger, error stage, finalization flag, and decision remain distinct.
Evidence state | Decoder result | Finalized? | Exact candidate match? | Release decision |
Declared valid fixture through T6 | no error | yes | yes | ACCEPT |
Stateless per-chunk path T3/T4 | replacement or premature error | not a valid lifecycle | no | REPAIR |
Logical stream still open, T7 | no error yet | no | not established | HOLD_UNFINALIZED |
Truncated terminal scalar, T8 | TypeError at flush | failed | no | REJECT |
Malformed sequence, T10 | TypeError during chunk | no successful completion | no | REJECT |
Runtime or evidence differs from qualified record | unknown until tested | unknown | unknown | RERUN |
The reviewed release decision for the supplied preparation evidence is therefore ACCEPT T6 only in the staged T6/T8/T10 comparison, while retaining the other passing cases as controls. T8 and T10 are successful tests because they demonstrate rejection, not because their inputs may be published. Changes to Node/ICU/V8 qualification, encoding choice, decoder lifecycle, source fixture, message framing, staging boundary, or application oracle should trigger an explicit rerun rather than inheriting this decision.
Strengthen JavaScript integration through precise input handling
Byte-to-text boundaries are a practical extension of the same contract discipline used across frontend and API work: know what representation you have, preserve evidence until admission is complete, and place irreversible effects after validation. Refonte Learning’s Frontend Development program currently lists JavaScript ES6+, APIs/AJAX, API Integration, Git, accessibility and performance topics, and a capstone project; the page also states a 10–12 hour weekly workload. Confirm the duration before enrolling: Program Specifics lists four months, while a related program card lists three months.
Those verified JavaScript and API foundations are the appropriate connection; TextDecoder streaming is not claimed as a named syllabus module. The concrete next review action is to take the exact harness above, attach the retained textdecoder-results.json, verify its recorded environment and digest, and approve only the lifecycle that keeps one decoder across chunks, uses fatal mode, performs the final flush, and crosses the publication boundary only after the declared application check passes.