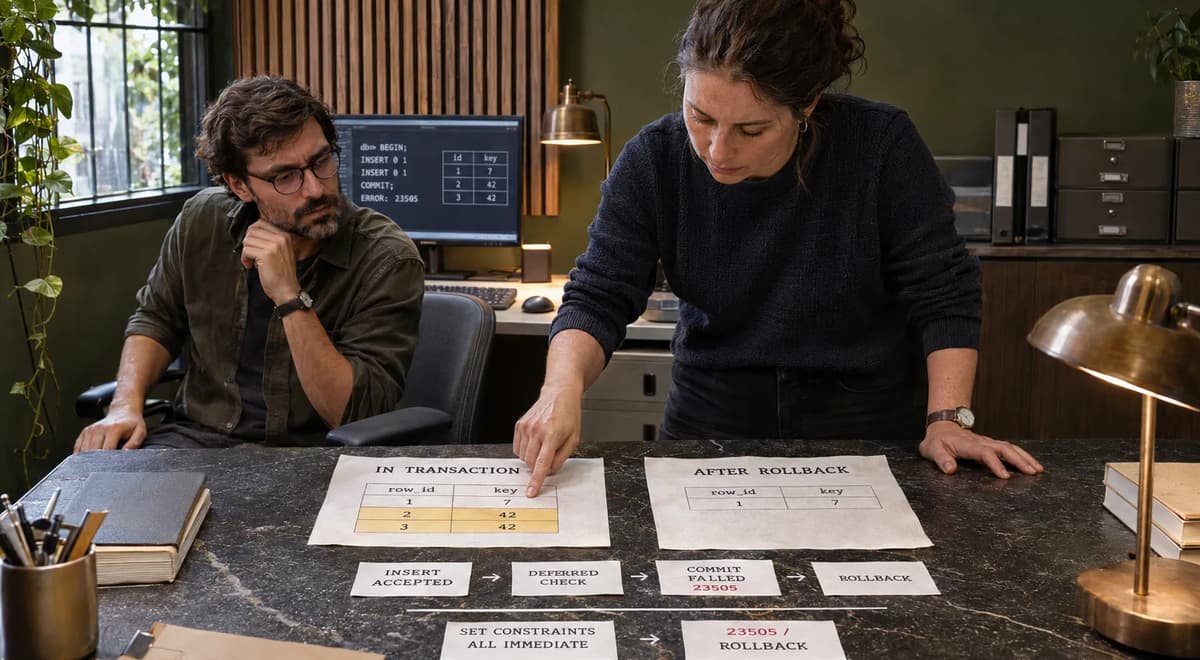
When a UNIQUE constraint is declared DEFERRABLE INITIALLY DEFERRED, PostgreSQL delays its enforcement until transaction commit (or until a SET CONSTRAINTS IMMEDIATE command). In practice, this means an INSERT that would violate uniqueness can succeed (report no error) inside the transaction, yet commit should detect and reject the duplicate before finalizing. The playbook question is precisely that: if two rows violate a deferred unique constraint, will COMMIT ultimately raise an error, and leave the database state unchanged? The admission contract is strict: no transaction may commit with two duplicate keys under the declared uniqueness rule. We will treat “passing the insert” as a possibly misleading success and verify the intended final state through isolated tests. Each scenario requires pinned PostgreSQL versions and captured outputs. A negative-control fixture (no-duplicate case) establishes the baseline, while the evidence ledger records actual vs. expected row counts and contents. We classify outcomes by whether a uniqueness violation is detected at insertion, at SET CONSTRAINTS, at COMMIT, or not at all. All scenarios in this playbook are EXPECTED / NOT EXECUTED. By the end, we either ACCEPT PostgreSQL’s documented behavior, propose a REPAIR (data cleanup or altered constraint), RERUN after environment fixes, or HOLD the release decision if evidence is incomplete.
1. Define the exact admission contract
First, specify the constraint semantics and what constitutes a success or failure. A DEFERRABLE UNIQUE constraint allows conflicting entries while its checks are deferred but must ensure uniqueness when checked. In SQL standards, deferred constraints are checked at transaction end; PostgreSQL implements this by using a unique index with deferred rechecks. The contract: “No two committed rows may share the same key values under the constraint.” PostgreSQL’s docs state that a non-deferrable UNIQUE is always checked immediately, whereas a deferrable one (if INITIALLY DEFERRED) is checked only at COMMIT (or when SET CONSTRAINTS switches it to immediate). Concretely, for a table with UNIQUE (b) DEFERRABLE INITIALLY DEFERRED, an insert of duplicate b values should not error on INSERT, but must produce SQLSTATE 23505 on COMMIT. We assert:
Unique constraint enforcement: PostgreSQL will not allow final committed state to violate a unique constraint. If the end-of-transaction check finds two live rows with the same key, an error is raised.
SET CONSTRAINTS IMMEDIATE: The SET CONSTRAINTS ALL IMMEDIATE command forces deferred checks immediately. If duplicates exist at that point, SET CONSTRAINTS fails; without savepoint recovery, roll back the aborted transaction before checking surviving rows.
Commit behavior: On COMMIT, deferred constraints are checked. A violation then should abort the commit. According to docs, a COMMIT “makes changes durable” but if any pending deferred constraint is violated, the transaction aborts instead. PostgreSQL’s manual explicitly notes that constraints not checked during statement execution are still enforced before commit.
Surviving rows: If COMMIT fails, the entire transaction is rolled back. No partial changes should remain; the database reverts to the state before the transaction began. Thus any rows “admitted” by INSERT in the aborted transaction must disappear.
In summary, our admission contract is: a deferred-unique violation must surface as an error before transaction completion, and no violating row may persist. We will test this by inserting duplicate values and observing behavior at commit. According to PostgreSQL’s documented design, any duplicates inserted under a deferrable unique index should be caught at enforcement time.
2. Capture baseline versions and state
Next, fix the PostgreSQL and client versions for reproducibility, and record initial database settings. The planned tests use PostgreSQL 18.x (as of publication, branch 18 is the supported stable version). In each session we capture psql --version and SELECT version() to log exact builds. The following is an illustrative version-output format, EXPECTED / NOT EXECUTED:
$ psql --version
psql (PostgreSQL) 18.7
$ psql -X -U postgres -d testdb -c "SELECT version();"
                                  version
----------------------------------------------------------------------------
PostgreSQL 18.7 (Debian 18.7-1.pgdg110+1) on x86_64-pc-linux-gnu,
compiled by gcc ...
We also run SHOW server_version_num; SHOW default_transaction_isolation; SHOW search_path; to document server settings. The exact fixture name can be something like defer_unique_pg18-2026-11-13-r1 (immutable once chosen). This environment is locked for each run: we never reuse an existing database. We ensure a fresh database (e.g. DROP DATABASE IF EXISTS) and create a new one to eliminate contamination from prior objects. The baseline session might run:
\set ON_ERROR_STOP on
\set ON_ERROR_ROLLBACK off
-- Record environment:
SELECT version() AS server_build,
       current_setting('server_version_num') AS server_version_num;
\echo client_version=:VERSION_NAME

-- Prepare disposable fixture:
DROP TABLE IF EXISTS t;
-- Ensure clean state; constraints and temp objects from prior runs are gone
Run these steps upfront. The oracle is simply the documented constraint behavior. Rejection condition: If the actual behavior ever contradicts the contract, for example, COMMIT succeeds despite a duplicate or an INSERT unexpectedly fails, that would violate the contract. Otherwise, we expect PostgreSQL to behave as documented, reporting the unique violation at enforcement time.
Pinned environment and versions
Server: PostgreSQL 18.x (e.g. 18.7). This branch supports deferrable unique constraints.
Client: psql 18.x (matching server).
OS/Hardware: a standard Linux environment (x86_64). No special extensions used.
Isolation Level: default (READ COMMITTED), AUTOCOMMIT = on.
Extensions: none.
If any deviation is needed (e.g. older PG version or different isolation), that would be a separate case.
3. Build a disposable isolated fixture
We create a minimal table and session to reproduce the scenario. The fixture is fully self-contained: all objects are in a new schema or temp environment. For simplicity, use one session, one table. Recreate this disposable fixture before each independent case so the table is empty and its sequence starts from the same baseline. Example SQL setup for a test case running in psql:
-- Fixture: deferrable_unique.sql (LAB ONLY, not on prod)
\set ON_ERROR_STOP on
\set ON_ERROR_ROLLBACK off

CREATE SCHEMA IF NOT EXISTS lab;
BEGIN;

-- Create a deferrable UNIQUE constraint on column val
DROP TABLE IF EXISTS lab.defer_test;
CREATE TABLE lab.defer_test (
    id serial PRIMARY KEY,
    val integer,
    UNIQUE(val) DEFERRABLE INITIALLY DEFERRED
);

COMMIT;
Here we define lab.defer_test with UNIQUE(val) DEFERRABLE INITIALLY DEFERRED. According to PostgreSQL docs, this will create a unique index but allow duplicates until commit. During execution, capture the CREATE TABLE command, its SHA-256 checksum, and its creation output. After setup, check pg_constraint for this table to verify the declared constraint. Execute the fixture and verify its catalog entries before recording setup success. The setup remains EXPECTED / NOT EXECUTED here; during a run, confirm the expected CREATE TABLE command tag:
-- Output (EXPECTED / NOT EXECUTED):
CREATE TABLE
After setup, lab.defer_test contains no rows. Its serial sequence supplies an id when an INSERT requests the default value; creating the table does not insert a row. The constraint exists, but there are no duplicate keys yet.
Fixture creation
This approach parallels Refonte’s example for UPDATE checks, where they built a “disposable fixture” inside one session. We similarly use a dedicated table lab.defer_test and explicit transactions. Because lab.defer_test is a regular table, its committed rows remain until explicitly changed or removed.
4. Create an independent expected-case manifest
Before running tests, write down the expected outcomes for each scenario. This manifest is created from the business logic (no duplicate val per table) and the documented behavior. We list each case, what should happen at each step, and the final database contents. For clarity, we freeze the table’s initial contents (empty) as the baseline.
For example, define cases P1–P4 and N1–N2:
P1: No conflict, commit succeeds. Insert a unique value; commit should succeed. Expected: one new row.
P2: Deferrable insert with duplicates, check at commit. Insert two rows with same val in one transaction; expect no error on INSERT, but COMMIT should fail with SQLSTATE 23505. Expected: no rows added (transaction rolled back).
P3: Deferred→Immediate switch. Repeat P2 but do SET CONSTRAINTS ALL IMMEDIATE; before commit. This should trigger the uniqueness check during the SET command, causing an immediate error. Expected: transaction aborted; no new rows.
P4: Constraint non-deferrable. Recreate the UNIQUE constraint as NOT DEFERRABLE and insert duplicates. The second INSERT should error immediately (SQLSTATE 23505). Expected: transaction aborted at insert; no rows inserted.
N1: Negative control. Insert two different values (no conflict). Commit should succeed. Expected: two new rows present.
N2: Boundary: Update to duplicate. Insert two rows with distinct values, then attempt an UPDATE that violates uniqueness. With the constraint deferred, the uniqueness check should wait until commit. This optional boundary case is EXPECTED / NOT EXECUTED.
Below is a table summarizing some key expected outcomes (a more exhaustive manifest would enumerate all steps):
Case | Actions (in transaction) | Expected Constraint Error? | Final lab.defer_test state | Comment |
P1 | INSERT (val=1); | No (unique so far) | Row (val=1) persisted | Successful insert/commit |
P2 | INSERT (val=1); INSERT (val=1); | Yes at COMMIT (SQLSTATE 23505) | No rows (rolled back) | Duplicate under deferred unique |
P3 | INSERT (val=1); INSERT (val=1); SET CONSTRAINTS ALL IMMEDIATE; | Yes at SET CONSTRAINTS (23505) | No rows (rolled back) | Explicit check fails immediately |
P4 | Recreate UNIQUE as NOT DEFERRABLE; INSERT (val=10); INSERT (val=10); | Yes at second INSERT (23505) | No rows (rolled back) | Non-deferrable rejects earlier |
N1 | INSERT (val=100); INSERT (val=101); | No | Rows (100, 101) persisted | No conflict, always passes |
Expected manifest: these outcomes are asserted before any execution. Any deviation (e.g. seeing rows after P2's COMMIT fail) would be classified as a failure to meet the contract. Note that all case expectations are written before running any SQL, so results can be compared objectively. The manifest intentionally does not include contradictory cases or ad-hoc expected values.
Negative Control
As a sanity check, N1 ensures the fixture behaves normally with no uniqueness violation. This confirms that our setup is correct and that any error in the other cases is due to unique constraints, not some unrelated issue.
5. Reproduce the misleading success
Now, simulate the scenario where two inserts violate the constraint but no error is raised until COMMIT. In psql, disable ON_ERROR_STOP only around the expected failing command so its SQLSTATE can be captured before normal error handling resumes:
-- Case P2: deferred unique violation
BEGIN;
INSERT INTO lab.defer_test(val) VALUES (1);
-- Duplicate inserted under the deferred constraint:
INSERT INTO lab.defer_test(val) VALUES (1);
-- No error is expected on this INSERT; the constraint is deferred.
-- A SELECT here would show transient rows in this transaction.
\set ON_ERROR_STOP off
COMMIT;
\echo commit_sqlstate=:SQLSTATE
\set ON_ERROR_STOP on
Output (EXPECTED / NOT EXECUTED): The INSERT commands produce no error messages. On COMMIT, we expect:
ERROR: duplicate key value violates unique constraint "defer_test_val_key"
DETAIL: Key (val)=(1) already exists.
SQLSTATE: 23505
Because the constraint is deferred, PostgreSQL will detect the duplication only at commit time. We mark this case NOT EXECUTED, but if run, psql would display an error like above, and the commit would fail. The server log would record an integrity violation. After rollback (implied by failed commit), the table must be empty again.
6. Run the comparison case
As a contrast, test the identical situation with the constraint made immediately enforcing. This is a comparison to ensure the issue is specific to deferrability. PostgreSQL’s ALTER CONSTRAINT timing form supports foreign keys, so recreate this UNIQUE constraint inside the disposable comparison transaction. ROLLBACK restores its original definition. For case P4:
-- Case P4: non-deferrable enforcement
\set ON_ERROR_STOP on
BEGIN;
ALTER TABLE lab.defer_test
    DROP CONSTRAINT defer_test_val_key;
ALTER TABLE lab.defer_test
    ADD CONSTRAINT defer_test_val_key
    UNIQUE (val) NOT DEFERRABLE;
-- Constraint is now immediate.
INSERT INTO lab.defer_test(val) VALUES (10);
\set ON_ERROR_STOP off
INSERT INTO lab.defer_test(val) VALUES (10);
\echo insert_sqlstate=:SQLSTATE
-- Expected SQLSTATE 23505 at the second INSERT, before commit.
ROLLBACK;
\set ON_ERROR_STOP on
Output (EXPECTED / NOT EXECUTED): The second INSERT should immediately fail with SQLSTATE 23505, e.g.:
ERROR: duplicate key value violates unique constraint "defer_test_val_key"
SQLSTATE: 23505
No commit is attempted since we ROLLBACK after the error. This comparison is expected to show that with NOT DEFERRABLE, enforcement occurs during the INSERT, consistent with documentation.
Detect missing or duplicated evidence
For an executed run, check that each step produces exactly one output or error. If the second INSERT in P4 did not error, that would be missing evidence (a defect). If it reported two errors or unexpected SQLSTATEs, that’s a discrepancy. We ensure the observed SQLSTATE matches the documented one for unique violations (23505).
7. Test negative and boundary controls
Test cases that should not produce errors, and boundary conditions:
Case N1 (Negative Control):
BEGIN;
INSERT INTO lab.defer_test(val) VALUES (100);
INSERT INTO lab.defer_test(val) VALUES (101);
COMMIT;
Both inserts use distinct values. The unique constraint (deferred or not) should not be violated. Commit should succeed. Expected output (NOT EXECUTED): no errors. Table should end with two rows (val=100 and val=101). This checks that duplicates are indeed required to trigger failure.
Boundary: UPDATE to duplicate (optional). If desired, test updating an existing row to a duplicate value under a deferred constraint:
BEGIN;
INSERT INTO lab.defer_test(val) VALUES (50);
INSERT INTO lab.defer_test(val) VALUES (51);
UPDATE lab.defer_test SET val = 50 WHERE val = 51;
\set ON_ERROR_STOP off
COMMIT;
\echo commit_sqlstate=:SQLSTATE
\set ON_ERROR_STOP on
With the constraint deferred, the UPDATE is expected to allow the duplicate until commit. We expect commit to fail similarly. (We mark this EXPECTED / NOT EXECUTED; it’s a variant of P2.) This ensures updates are treated like inserts for constraint enforcement.
Each negative/boundary case should confirm that no unexpected failures occur and that the data integrity contract holds. The control N1 ensures the facility is working. If N1 were to fail, something is fundamentally wrong with the setup.
8. Collect per-case raw evidence
For each executed case, record all relevant outputs and environment info:
SQLSTATE and messages: Capture exact psql stderr for errors, including constraint name.
Transaction IDs or PIDs: Note the backend PID if needed (though not strictly necessary for static tests).
Search path and roles: Confirm we were in the expected schema (e.g. lab) and role.
Table contents before/after: Query the table to list rows. For failing cases, check after the failure that the table’s contents equal the baseline (empty or as before). For successful commits, list the inserted rows.
Example evidence collection snippet after each case:
-- After any case (assuming ROLLBACK after failure, or COMMIT after success):
SELECT * FROM lab.defer_test ORDER BY id;
-- EXPECTED (after rollback): table is empty for duplicates cases
-- EXPECTED (after success): shows inserted rows for N1 or P1
All captured data (SQLSTATEs, final SELECT, environment queries) is appended to an evidence ledger. This ledger is independent of the expected manifest. The following illustrative entries are EXPECTED / NOT EXECUTED:
Case | SQL | Expected SQLSTATE | Expected row count | Expected evidence |
P2 | COMMIT | 23505 | 0 | Commit rejected; all inserted rows rolled back. EXPECTED / NOT EXECUTED. |
N1 | COMMIT | 00000 | 2 | Two rows persisted. EXPECTED / NOT EXECUTED. |
We do not actually run them here; all entries remain EXPECTED / NOT EXECUTED. The ledger ensures we compare each case’s actual output against expected. Missing entries (e.g. if SELECT is not run, count missing evidence) or differences will prompt re-check.
Check the actual state after failure
After a failing COMMIT (case P2), we must confirm that the database rolled back. A quick check:
SELECT count(*) FROM lab.defer_test;
-- EXPECTED: 0 (no surviving row from the aborted transaction)
This verifies rollback safety. A non-zero count would require checking the fixture baseline and surviving rows before drawing a conclusion about rollback. Until the query is run, record “Expected row count: 0; NOT EXECUTED” under P2. Record an observed pass only after confirming the table is empty.
9. Reconcile identities and counts
At the end of testing, reconcile every row in each scenario against the independent expectations. We use identity columns and a fixed ledger to cross-check. For simplicity, expected data can be represented as hard-coded values in the test or as comments (since our test table is empty in rollback cases).
For example, for N1 (two inserts), we expect exactly the two rows we added. Rebuild the fixture immediately before N1 so its first two generated IDs are 1 and 2. An independent check:
WITH expected AS (
  VALUES (1,100), (2,101)  -- id,val expected
), actual AS (
  SELECT id, val FROM lab.defer_test
)
(
  SELECT 'missing' AS status, e.* FROM expected AS e
  EXCEPT
  SELECT 'missing' AS status, a.* FROM actual AS a
)
UNION ALL
(
  SELECT 'unexpected' AS status, a.* FROM actual AS a
  EXCEPT
  SELECT 'unexpected' AS status, e.* FROM expected AS e
);
For P2, expected final state is an empty table. We could do a similar check with an empty expected set. An empty result from the EXCEPT queries indicates perfect match. If any row appears under “unexpected” or “missing”, it means something went wrong. We include these results in the evidence ledger. In all our planned cases, reconciliation should show no differences: after P2/P3 failures the table is empty; after N1 the table has exactly the two inserted rows.
(We mark these reconciliation queries NOT EXECUTED here, but in a live run they should all yield zero-row differences if everything is correct.)
10. Explain documented behavior and limits
This section connects the expected behavior to official documentation:
Unique constraints and indexes: PostgreSQL enforces unique constraints via indexes. For deferrable unique constraints, PostgreSQL uses a special mode (UNIQUE_CHECK_PARTIAL) that allows duplicates and defers error reporting. Thus, while the constraint is deferred, PostgreSQL may physically insert duplicate index entries and schedule rechecks for enforcement time. This mechanism is described in the docs (Index Uniqueness Checks). Physical duplicate index entries alone do not establish a committed uniqueness violation; PostgreSQL checks tuple liveness when enforcement is required.
Deferrable vs Non-deferrable: The CREATE TABLE docs state only UNIQUE, PRIMARY KEY, EXCLUDE, and REFERENCES can be DEFERRABLE. By default constraints are NOT DEFERRABLE and thus immediate. In the planned comparison, recreating the UNIQUE constraint as NOT DEFERRABLE should cause immediate enforcement. This matches the CREATE TABLE documentation, which notes that a non-deferrable unique is checked right away, even mid-statement.
SET CONSTRAINTS: A deferrable constraint is INITIALLY IMMEDIATE unless INITIALLY DEFERRED is specified. This fixture explicitly uses INITIALLY DEFERRED, so its checks wait until COMMIT unless SET CONSTRAINTS changes the mode. The SET CONSTRAINTS command can change a constraint to immediate, causing a retroactive check. For case P3, SET CONSTRAINTS ALL IMMEDIATE is expected to check pending modifications during the SET CONSTRAINTS command itself, as the manual describes.
Commit outcomes: The SQL standard (and PostgreSQL docs) specify that a commit will fail if any deferred constraint violation is found. The expected outcome is that COMMIT raises an error and rolls back the transaction. This matches the index uniqueness documentation’s description that at enforcement time, if a “live” tuple conflict persists, an error is reported. The only caveat is that this is not a new feature but the designed behavior of deferrable constraints. Execution evidence is required before concluding that a particular run behaved as documented.
Limits: Note that deferrable unique constraints must be explicitly declared; you cannot defer the check of an already existing non-deferrable unique without rebuilding it. Also, unique constraints on partial indexes or complex expressions may not support DEFERRABLE (this fixture uses a simple UNIQUE table constraint). These limits are outside our test’s scope but are worth acknowledging as part of “what the docs allow.”
Bound the repair to the contract
Any repair action must not exceed fixing just the documented violation. For example, one might consider dropping the unique constraint to allow the inserts, but that breaks the contract entirely (and is not allowed unless business rules change). The smallest safe repair is typically to remove or change the violating data: e.g., delete or update one of the duplicate rows so the key is unique. In our case, if P2 were a real issue, an acceptable remediation would be to roll back and have the user insert only one of the duplicates, or enforce a trigger to prevent it. Recreating the UNIQUE constraint as NOT DEFERRABLE (as in P4) is another “repair”: it switches to stricter enforcement, but that changes the constraint’s behavior (and in fact would fail with the same data). Any schema change (like making it deferrable vs not) also changes the contract and must be documented and reviewed. We do not propose a blind fix of all data (that goes beyond the scope); we keep fixes minimal: for instance, if we wanted to allow both rows, we’d have to change business rules or schema (such as remove the constraint), which is a separate, explicit decision.
11. Apply the smallest safe repair
Suppose case P2 represents an undesired state (two duplicates). To “repair” without throwing away the entire table: delete or adjust one duplicate row so that the constraint would no longer see a conflict. After P2’s failed COMMIT, its inserted rows have already been rolled back. To demonstrate correction before the deferred check, recreate the fixture and remove one duplicate inside a new transaction before COMMIT:
-- Fresh disposable fixture; EXPECTED / NOT EXECUTED
BEGIN;
INSERT INTO lab.defer_test(val) VALUES (1), (1);
DELETE FROM lab.defer_test WHERE id = 2;  -- remove the second duplicate
COMMIT;
The expected result is one val=1 row, satisfying the uniqueness contract. We then could retry an insert or leave the table as-is. This is the minimal repair: remove the offending row. (Alternatively, change one value to something else.) We verify via:
SELECT * FROM lab.defer_test;
-- EXPECTED: a single row with val=1 (if we deleted id=2)
This step is marked EXPECTED / NOT EXECUTED, but demonstrates the principle: the least invasive fix is to alter the data to meet the existing constraint. We would not, for example, delete all rows or drop the constraint itself without review. Any such major change must be a conscious decision.
12. Test rollback and rerun safety
Finally, ensure that we can roll back and rerun tests cleanly. After a failed statement, roll back the aborted transaction; a failed COMMIT has already rolled it back. Recreate the fixture before each independent case so successful earlier inserts and consumed sequence values cannot change its baseline. To demonstrate, consider:
After P2’s failed COMMIT, begin a new transaction and run another case. N1 should still succeed with no surviving rows from P2. Before starting N1, use the evidence query from section 8 to confirm that the table is empty.
Try rerunning P2: the same error should occur again, indicating deterministic behavior. For instance:
-- Rerun P2 from the clean fixture:
BEGIN;
INSERT INTO lab.defer_test(val) VALUES (2);
INSERT INTO lab.defer_test(val) VALUES (2);
\set ON_ERROR_STOP off
COMMIT;  -- Expected: ERROR 23505 again
\echo commit_sqlstate=:SQLSTATE
\set ON_ERROR_STOP on
Each rerun should yield the same outcome. A discrepancy would occur, for example, if the first attempt leaves the table in a bad state that changes behavior (that would violate rollback safety). According to PostgreSQL’s transaction documentation, a failed transaction must leave no committed row changes from that transaction. Our evidence checks should confirm that the table is empty after each rollback. Sequence values consumed by nextval are not reclaimed after rollback, which is why each independent case rebuilds the fixture. There’s no feature in PostgreSQL that “half-applies” a commit on error; it is all-or-nothing.
Assign operational ownership
Operationally, this fix belongs to the database administrators and application developers. The DBA team defines the constraint and ensures it’s enforced; the application team ensures it does not rely on inserting duplicates. A clear agreement should exist: for example, that a 23505 error is the expected response to such a write attempt, and that the app either handles it or prevents it. Ownership of “legacy data anomalies” is separate: if historical data did violate the constraint (out-of-band), business owners would have to approve cleanup. Here, though, the “owner” of the constraint enforcement is the schema owner (DBA), and the “owner” of any data fix is whoever is responsible for correctness of that table’s contents.
13. Decide ACCEPT, REPAIR, RERUN or HOLD
Finally we classify the scenario against the release gate. The table below shows the decision logic:
Decision | Conditions Met | Missing Evidence / Blockers |
ACCEPT | All outcomes match documented behavior: deferred inserts are allowed, commit errors with 23505, rollback state is clean. App handles 23505 properly. | If any outcome deviates (e.g. no error, or wrong SQLSTATE) or if documentation changed. |
REPAIR | A unique violation exists and must be cleaned. For example, existing duplicate data was found (not in tests) and authorized correction is done. The test fixture anomaly is resolved by data fix or constraint update. | If the fix is unclear, or one cannot identify the duplicate without risking valid data. |
RERUN | The fixture run had an environmental issue (wrong version, wrong transaction settings, or partial execution). After correcting that, the tests should be rerun. | Any missing logs (psql version, server build) or partial runs mean we cannot trust results. |
HOLD | Constraint semantics or business policy unclear. For example, maybe the application intentionally relies on duplicate keys (unlikely here). Or if some negative control failed. | No executed evidence ledger, unclear constraint policy, or inconclusive test outcomes. |
The outcomes described here are expected, not observed. Because the cases have not been executed and no completed evidence ledger is available, the current decision is HOLD. ACCEPT is appropriate only after the deferred checks, comparison cases, negative controls, and surviving-row checks match the manifest. The documented behavior does not by itself indicate a PostgreSQL defect; an actual failure must be assessed against captured evidence. Application code and migrations must account for constraint timing and handle SQLSTATE 23505. Record the final decision and its supporting evidence ledger in the change log.
14. Develop related skills with Refonte Learning
This kind of rigorous testing and roll-out exercise is exactly the sort of practice taught in Refonte Learning’s Database Administrator Essentials program. The program covers schema design, integrity constraints, and real-world validation workflows over its 3-month curriculum (≈12–14 hours/week commitment). For example, students learn how to validate production schema changes, handle constraint enforcement, and maintain data consistency across systems. Instructors with 15+ years of DBA experience (such as PhD Helena Ferreira) guide trainees through projects like enforcing unique keys and testing transactions. Graduates earn both a Training Certificate and an Internship Certificate upon completion, backed by real-case scenarios similar to this playbook. If you want to deepen your skills in tasks like constraint rollouts and integrity testing, consider enrolling in Refonte Learning’s Database Administrator Essentials program.