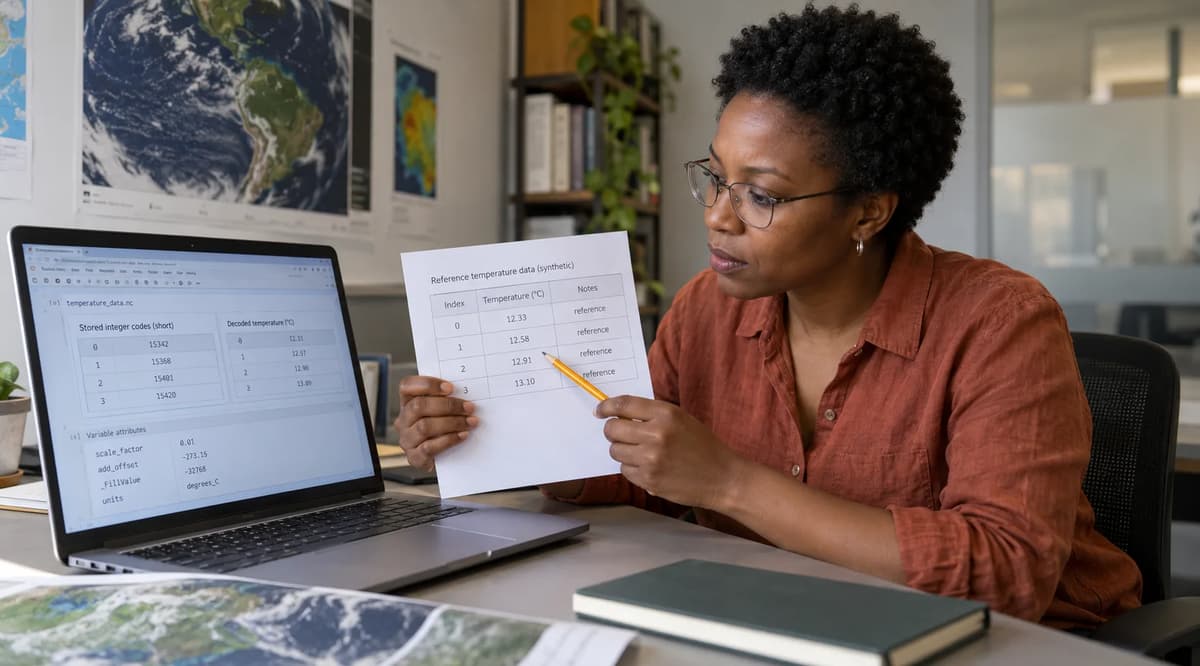
A netCDF4 write can succeed, close normally, reopen cleanly, and return exactly the four numbers that were assigned, while the file still represents the wrong physical quantity. The trap is a representation error, not a persistence error. Suppose a producer already holds packed int16 codes [0, 20, 40, 60], but writes them through a variable whose scale_factor=0.5 and add_offset=250.0 are active under netCDF4 Python's default automatic scaling. The high-level writer treats those inputs as physical values and applies the inverse affine transform again. A fresh default read can then decode the transformed codes back to [0, 20, 40, 60], making a naive roundtrip equality check pass.
This laboratory fixes the intended contract before file creation. The approved raw codes are [0,20,40,60]; the approved physical values are [250,260,270,280] K; storage is int16; and both packing attributes are float64. The producer has only two correct write paths: submit physical values with automatic scaling enabled, or declare that the inputs are already packed codes and disable scaling on the variable before assignment. Unidata documents that automatic scaling is enabled by default and that writes with scale/offset attributes use (input-add_offset)/scale_factor; reads apply the inverse interpretation, stored*scale_factor+add_offset.
The proof therefore needs two fresh post-close views: one raw, with masking and scaling disabled, and one decoded, with masking disabled but default scaling retained. Neither candidate view is allowed to redefine the producer's independent literals. This is a producer/consumer contract test: the raw view answers what bytes-as-codes were committed through the library interface, while the decoded view answers what a normal scaling-aware consumer receives. Acceptance requires both answers, plus the metadata connecting them, to agree with the contract authored before the file existed.
Declare the physical quantity and the input representation
For this fixture, packing means representing the physical temperatures with integer storage plus an affine scale and offset. The producer contract is deliberately small and explicit: variable temperature, dimension sample of length four, storage dtype int16, scale_factor=np.float64(0.5), add_offset=np.float64(250.0), units K, and _FillValue=-32768. The independently authored raw-code contract is [0,20,40,60]; the independently authored physical-value contract is [250.0,260.0,270.0,280.0] K.
CF 1.12 expresses the packed-data interpretation as stored values multiplied by scale_factor, followed by add_offset, and says a variable's units should represent the unpacked data. Its type rules also permit double-precision scale/offset attributes with short integer storage. The NetCDF-C attribute conventions describe the same order of operations and the inverse write-side concept.
The producer must additionally declare what the input array means. representation="physical" means its numbers are already temperatures in kelvin and must be encoded once. representation="packed" means its numbers are the approved integer codes and must be stored without another affine encoding step. Array dtype cannot make that semantic declaration. [250,260,270,280] carried in an integer NumPy array can still be physical kelvin values, while [0,20,40,60] can be packed codes.
That discipline belongs naturally beside broader remote-sensing processing and validation skills, where repeatable preprocessing depends on knowing what a numeric array represents before transforming it. The linked page discusses wider Earth-observation workflows; this laboratory is much narrower and concerns one scalar packed variable.
Pin the writer and both fresh-reader configurations
The supplied commissioning execution was recorded on 2026-10-27 at 07:15:09 UTC and returned PASS_13_CASES. Its evidence record identifies Python 3.12.14, NumPy 2.3.5, netCDF4 Python 1.7.4, cftime 1.6.4.post1, linked netCDF-C 4.9.3, HDF5 1.14.6, and Linux-6.18.55-x86_64-with-glibc2.39; the source SHA-256 is c960eee94c2b9503b84db7f185191848e7ae3af4480fe5cdf1a485b83abea361. Those are runtime observations from the supplied laboratory record, not documentation-version substitutes and not an interoperability certification.
The writer uses an ordinary context-manager close. Inspection then opens two separate fresh reader handles. The raw reader calls var.set_auto_maskandscale(False) before var[:], so it observes stored int16 codes without automatic scaling. The decoded reader is a new handle and calls only var.set_auto_mask(False); scaling therefore remains at the variable's default enabled state. netCDF4 1.7.4 documents masking separately from scaling, and documents automatic scale as enabled by default.
That close-and-reopen sequence proves what the normal read path observes after the writer has closed. It does not establish crash consistency, storage durability after power failure, atomic publication, or rollback behavior.
Separate documentation versions from the executed build
The netCDF4 API page inspected for this article identifies package documentation version 1.7.4. The NetCDF-C attribute-conventions page currently displays a 4.10.1 documentation header, while the supplied executed fixture reports linked netCDF-C 4.9.3. The convention text consulted is fixed CF 1.12. No equivalence, release-date relationship, or “latest version” claim is inferred from those different labels.
Execute the thirteen-case packing fixture
Run this only in an owned, disposable environment. A fresh environment should use Python 3.12 and install the package versions named by the commissioning contract; record whatever netCDF-C and HDF5 libraries are actually linked, because wheels or local builds can differ. The following setup is illustrative. The supplied commissioning execution used an isolated temporary package target with the same Python-package versions, not this exact virtual-environment command.
python3.12 -m venv .venv-netcdf-packing
.venv-netcdf-packing/bin/python -m pip install numpy==2.3.5 netCDF4==1.7.4 cftime==1.6.4.post1
.venv-netcdf-packing/bin/python netcdf_fixture.py > results.json
Retain the process status and complete results.json. An exception, nonzero process status, truncated output, or incomplete JSON is a HOLD, because the evidence package is incomplete. The fixture creates temporary owned .nc candidates, closes and inspects them, captures values and metadata into JSON, then deletes the temporary directory. The JSON is evidence of that run; it is not a retained candidate file and does not demonstrate durable publication. Keep the source file beside the evidence or otherwise bind the evidence to the exact source hash. A version string alone is insufficient when code, package build, or linked native libraries can change independently. The fixture therefore emits Python and package versions, platform, linked netCDF-C and HDF5 versions, the fixed contract, every case result, and explicit test limits. That combination makes later comparison possible without pretending that the record proves anything beyond the executed campaign.
Fix the two literal oracles before inspecting a file
The controls are authored before any candidate exists. Scalar arithmetic independently checks both directions: code*0.5+250.0 must yield the physical literals, and (physical-250.0)/0.5 must yield the raw literals. Candidate metadata is never used to invent these expected values. That matters because a self-consistent but wrong file can otherwise validate itself.
Save the following source as netcdf_fixture.py:
"""Synthetic netCDF4 packing audit; creates only temporary owned files."""
from future import annotations

import hashlib
import json
import platform
import sys
import tempfile
from datetime import datetime, timezone
from pathlib import Path

import cftime
import netCDF4
import numpy as np

REVISION = "netcdf-packing-r1"
RAW = np.array([0, 20, 40, 60], dtype=np.int16)
PHYSICAL = np.array([250.0, 260.0, 270.0, 280.0], dtype=np.float64)
SCALE = np.float64(0.5)
OFFSET = np.float64(250.0)
FILL = np.int16(-32768)
BAD_RAW = [-500, -460, -420, -380]


def require(condition, message):
    if not condition:
        raise AssertionError(message)


def write_candidate(path, values, mode="default", offset=OFFSET):
    with netCDF4.Dataset(path, "w", format="NETCDF4") as ds:
        ds.createDimension("sample", 4)
        var = ds.createVariable("temperature", "i2", ("sample",), fill_value=FILL)
        var.units = "K"
        var.scale_factor = SCALE
        var.add_offset = np.float64(offset)
        if mode == "packed":
            var.set_auto_scale(False)
        elif mode == "physical":
            var.set_auto_scale(True)
        elif mode not in {"default", "disable_after"}:
            raise ValueError("unsupported laboratory mode")
        var[:] = values
        if mode == "disable_after":
            var.set_auto_scale(False)


def inspect_candidate(path):
    # Separate fresh handles after writer close, never a writer-buffer readback.
    with netCDF4.Dataset(path, "r") as ds:
        var = ds.variables["temperature"]
        var.set_auto_maskandscale(False)
        raw = np.asarray(var[:])
        metadata = {
            "dtype": str(var.dtype), "shape": list(var.shape),
            "dimensions": list(var.dimensions), "units": var.units,
            "scale_factor": float(var.scale_factor),
            "add_offset": float(var.add_offset), "fill_value": int(var._FillValue),
            "scale_dtype": str(np.asarray(var.scale_factor).dtype),
            "offset_dtype": str(np.asarray(var.add_offset).dtype),
        }
    with netCDF4.Dataset(path, "r") as ds:
        var = ds.variables["temperature"]
        var.set_auto_mask(False)  # Retain the fresh variable's default scaling.
        decoded = np.asarray(var[:])
    expected_metadata = {
        "dtype": "int16", "shape": [4], "dimensions": ["sample"],
        "units": "K", "scale_factor": 0.5, "add_offset": 250.0,
        "fill_value": -32768, "scale_dtype": "float64", "offset_dtype": "float64",
    }
    # Independent scalar arithmetic, not another netCDF decoding operation.
    decoded_from_raw = [int(value) 0.5 + 250.0 for value in raw]
    metadata_ok = metadata == expected_metadata
    raw_ok = raw.dtype == np.dtype("int16") and np.array_equal(raw, RAW)
    physical_ok = decoded.dtype == np.dtype("float64") and np.array_equal(decoded, PHYSICAL)
    oracle_ok = decoded_from_raw == PHYSICAL.tolist()
    return {
        "raw": raw.tolist(), "decoded": decoded.tolist(),
        "decoded_dtype": str(decoded.dtype), "metadata": metadata,
        "metadata_ok": metadata_ok, "raw_ok": bool(raw_ok),
        "physical_ok": bool(physical_ok), "scalar_oracle_ok": oracle_ok,
        "qualified": bool(metadata_ok and raw_ok and physical_ok and oracle_ok),
    }


def qualified_write(path, values, representation):
    # Representation is a producer declaration, not guessed from array dtype.
    if representation not in {"physical", "packed"}:
        raise ValueError("representation must be physical or packed")
    array = np.asarray(values)
    if array.shape != (4,) or not np.all(np.isfinite(array)):
        raise ValueError("fixture requires four finite values")
    if representation == "packed":
        bounds = np.iinfo(np.int16)
        if not np.all(array == np.rint(array)) or np.any(array < bounds.min) or np.any(array > bounds.max):
            raise ValueError("packed values must be integral int16 codes")
        if np.any(array == FILL):
            raise ValueError("missing data is outside this fixture")
    else:
        codes = (array.astype(np.float64) - OFFSET) / SCALE
        bounds = np.iinfo(np.int16)
        if not np.all(codes == np.rint(codes)) or np.any(codes < bounds.min) or np.any(codes > bounds.max):
            raise ValueError("fixture requires exactly representable physical values")
        if np.any(codes == FILL):
            raise ValueError("missing data is outside this fixture")
    write_candidate(path, array, mode=representation)


def run():
    # Literal controls agree with independently authored scalar affine formulas.
    require([int(x) 0.5 + 250.0 for x in RAW] == PHYSICAL.tolist(), "decode oracle")
    require([(float(x) - 250.0) / 0.5 for x in PHYSICAL] == RAW.tolist(), "encode oracle")
    cases = []
    with tempfile.TemporaryDirectory(prefix="refonte-netcdf-packing-") as directory:
        root = Path(directory)

        def candidate(name, values, mode, expected_raw, expected_decoded, accepted, offset=OFFSET):
            path = root / (name + ".nc")
            write_candidate(path, values, mode=mode, offset=offset)
            observed = inspect_candidate(path)
            require(observed["raw"] == expected_raw, name + " raw mismatch")
            require(observed["decoded"] == expected_decoded, name + " decoded mismatch")
            require(observed["qualified"] is accepted, name + " qualification mismatch")
            observed.update({"case": name, "input": np.asarray(values).tolist(),
                             "input_dtype": str(np.asarray(values).dtype), "writer_mode": mode,
                             "decision": "ACCEPT_FIXTURE" if accepted else "REBUILD_FROM_TRUSTED_SOURCE"})
            cases.append(observed)
            return observed

        candidate("A_physical_default", PHYSICAL, "default", RAW.tolist(), PHYSICAL.tolist(), True)
        double = candidate("B_packed_default", RAW, "default", BAD_RAW, RAW.tolist(), False)
        require(double["decoded"] == double["input"], "false-positive readback must match input numbers")
        double["naive_input_equals_decoded"] = True
        candidate("C_packed_scale_off_before", RAW, "packed", RAW.tolist(), PHYSICAL.tolist(), True)
        candidate("D_physical_scale_off", PHYSICAL, "packed", [250, 260, 270, 280], [375.0, 380.0, 385.0, 390.0], False)
        candidate("E_scale_off_after_write", RAW, "disable_after", BAD_RAW, RAW.tolist(), False)
        candidate("F_integer_physical_default", PHYSICAL.astype(np.int16), "default", RAW.tolist(), PHYSICAL.tolist(), True)
        candidate("G_wrong_offset", RAW, "packed", RAW.tolist(), [200.0, 210.0, 220.0, 230.0], False, offset=200.0)

        for name, values, representation in [
            ("H_rebuild_from_physical", PHYSICAL, "physical"),
            ("I_rebuild_from_packed", RAW, "packed"),
        ]:
            path = root / (name + ".nc")
            qualified_write(path, values, representation)
            observed = inspect_candidate(path)
            require(observed["qualified"], name + " qualification mismatch")
            observed.update({"case": name, "representation": representation, "decision": "ACCEPT_FIXTURE"})
            cases.append(observed)

        for name, values, representation in [
            ("J_missing_representation", RAW, None),
            ("K_wrong_shape", PHYSICAL[:3], "physical"),
            ("L_fractional_packed_code", [0.0, 20.5, 40.0, 60.0], "packed"),
            ("M_out_of_range_packed_code", [0, 20, 40, 40000], "packed"),
        ]:
            path = root / (name + ".nc")
            try:
                qualified_write(path, values, representation)
            except ValueError as exc:
                require(not path.exists(), name + " created a file before rejection")
                cases.append({"case": name, "decision": "HOLD_BEFORE_FILE_CREATION", "reason": str(exc)})
            else:
                raise AssertionError(name + " was not rejected")

    require(len(cases) == 13, "case count")
    return {
        "fixture_revision": REVISION, "status": "PASS_13_CASES",
        "executed_utc": datetime.now(timezone.utc).isoformat(),
        "source_sha256": hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
        "environment": {"python": sys.version, "platform": platform.platform(),
                        "numpy": np.__version__, "netCDF4": netCDF4.__version__,
                        "cftime": cftime.__version__, "netcdf_c": netCDF4.__netcdf4libversion__,
                        "hdf5": netCDF4.__hdf5libversion__},
        "contract": {"raw": RAW.tolist(), "physical": PHYSICAL.tolist(),
                     "scale_factor": float(SCALE), "add_offset": float(OFFSET), "units": "K"},
        "cases": cases,
        "limits": ["synthetic four-value variable", "normal close and fresh reopen only",
                   "all values exact and within int16; no general rounding policy tested",
                   "no missing-data semantics, unsigned conversion, compression, xarray, or full CF validation",
                   "same installed netCDF4 library for writing and reading; scalar arithmetic oracle is independent",
                   "trusted representation and values required; no automatic provenance inference"],
    }


if name == "__main__":
    print(json.dumps(run(), indent=2))
For the supplied commissioning record, the expected terminal condition is "status": "PASS_13_CASES" and the recorded source hash is the value above. The run is intentionally synthetic: one four-element variable, exact-grid values, no remote dataset, and no scientific calibration. Its limits are part of the evidence rather than footnotes to be forgotten.
The central measured matrix from that supplied run is:
Case | Writer input and mode | Stored codes | Decoded values | Decision |
A | Physical values; default automatic scaling | [0, 20, 40, 60] | [250, 260, 270, 280] | ACCEPT_FIXTURE |
B | Already-packed codes; default automatic scaling | [-500, -460, -420, -380] | [0, 20, 40, 60] | REBUILD_FROM_TRUSTED_SOURCE |
C | Packed codes; scaling disabled before assignment | [0, 20, 40, 60] | [250, 260, 270, 280] | ACCEPT_FIXTURE |
D | Physical values; scaling disabled | [250, 260, 270, 280] | [375, 380, 385, 390] | REBUILD_FROM_TRUSTED_SOURCE |
E | Packed codes; scaling disabled only after assignment | [-500, -460, -420, -380] | [0, 20, 40, 60] | REBUILD_FROM_TRUSTED_SOURCE |
F | Physical values carried in an integer array; default scaling | [0, 20, 40, 60] | [250, 260, 270, 280] | ACCEPT_FIXTURE |
G | Correct packed codes but offset 200 | [0, 20, 40, 60] | [200, 210, 220, 230] | REBUILD_FROM_TRUSTED_SOURCE |
H/I | Fresh rebuild from trusted physical/packed input with declared mode | Approved codes | Approved physical values | ACCEPT_FIXTURE |
J/K/L/M | Missing representation / wrong shape / fractional packed code / out-of-range packed code | No file created | No decoded candidate | HOLD_BEFORE_FILE_CREATION |
Establish the correct physical-value write path
Case A is the ordinary physical-value path. The producer declares that the input array means kelvin values [250.0,260.0,270.0,280.0]. The variable has scale_factor=0.5 and add_offset=250.0, and automatic scaling remains enabled. netCDF4 Python 1.7.4 documents that, with scale/offset active, write-side packing computes (data-add_offset)/scale_factor.
The arithmetic is exact in this fixture:
(250-250)/0.5 = 0
(260-250)/0.5 = 20
(270-250)/0.5 = 40
(280-250)/0.5 = 60
After the writer closes, the raw reader therefore must see int16 [0,20,40,60]. The independent decoded reader, with scaling left enabled, must see float64 [250,260,270,280]. The supplied run reports both, and the scalar oracle independently converts the observed raw codes back to the same physical literals.
This is a stronger acceptance statement than “the assignment returned without error” or “a read gave me the numbers I expected.” It reconciles the producer's physical representation, the required stored representation, the declared affine metadata, and the consumer-visible physical values. Copernicus Marine's operational guidance is useful context here: it explains that tooling may automatically unpack scale/offset variables and names netCDF4 Python among tools capable of automatic unpacking. That context demonstrates why producer/consumer representation awareness matters; it does not establish how often double-packing incidents occur.
Reproduce the second packing of integer codes
Case B is the decisive negative control for netCDF4 double packing. The producer already has the approved codes [0,20,40,60] but sends them through the same default automatic path. Because netCDF4 sees an affine-packed variable with scaling enabled, it does not know that those integers are already codes. It interprets their numeric values as the unpacked inputs to be encoded.
Apply the documented write formula independently:
(0-250)/0.5 = -500
(20-250)/0.5 = -460
(40-250)/0.5 = -420
(60-250)/0.5 = -380
Those are the stored int16 values observed by the raw reader. Now apply the read formula: -500*0.5+250=0, then 20, 40, 60 for the remaining codes. The fresh default reader therefore returns [0,20,40,60], exactly the numbers that were submitted.
That equality is required to succeed as a negative control. If Case B did not demonstrate decoded == input, it would not isolate the dangerous validation mistake. The test is designed to prove that a conventional “write array, reopen, compare returned array with input” check can pass while the physical contract fails. The write genuinely persisted transformed data; the read genuinely decoded those data. What failed was the producer's representation contract.
The intended physical values are [250,260,270,280] K, not [0,20,40,60] K. So Case B's correct decision is REBUILD_FROM_TRUSTED_SOURCE, not acceptance and not a metadata tweak.
Write already-packed codes through the explicit raw path
Case C is the correct path for netCDF4 already packed integers. The producer explicitly declares representation="packed", creates the variable and its attributes, calls var.set_auto_scale(False), and only then assigns [0,20,40,60]. netCDF4 1.7.4 documents set_auto_scale as the variable-level switch for automatic packing/unpacking.
The raw reader then sees exactly [0,20,40,60]. A separate fresh reader does not inherit the writer's temporary variable state; with default scaling retained, it sees [250,260,270,280]. This distinction is central: disabling scale for the writer assignment does not mean the file loses its scale_factor or add_offset, and it does not mean consumers should globally disable decoding. It means only that the producer has said, “these particular inputs are already in the packed storage domain; do not encode them again.”
That is why the recommended fix is not “always disable scaling.” It is “declare the producer representation, then configure exactly one encoding step.” Physical inputs need automatic packing; packed inputs need a raw write.
Configure the variable before assigning values
The placement of the call matters:
var.scale_factor = SCALE
var.add_offset = OFFSET
var.set_auto_scale(False)
var[:] = RAW
Unidata notes that dataset- or group-level auto-conversion settings affect variables that already exist; variables created later follow default behavior. The fixture therefore configures the actual temperature variable after creation and before assignment, eliminating ambiguity about which object owns the write behavior.
Show why disabling scaling everywhere also fails
Case D proves the mirror-image error. The input is the valid physical array [250,260,270,280], but the writer uses the packed/raw path with automatic scaling disabled. Those values are stored literally as int16 [250,260,270,280]. A normal scaling-aware reader then interprets them through the file's declared affine transform:
250*0.5+250 = 375
260*0.5+250 = 380
270*0.5+250 = 385
280*0.5+250 = 390
The raw write itself is functioning exactly as configured. The semantic error is that physical values were mislabeled as already packed codes.
Input representation | Writer mode | Result in this fixture | Decision |
Physical kelvin values | Automatic scaling enabled | Correct codes, correct decoded K | Accept |
Already-packed integer codes | Scaling disabled before assignment | Correct codes, correct decoded K | Accept |
Physical kelvin values | Scaling disabled | Physical numbers stored as codes; decoded values become too large | Rebuild |
The lesson is operationally important: there is no universally “safer” setting between automatic and manual packing. A flag cannot determine what the producer's numbers mean. The declaration must come first; the setting follows from it.
This fixture also deliberately avoids a general rounding policy. All approved values sit exactly on the affine grid and within int16. NetCDF-C recommends rounding when scaled data are written to integer storage, but this experiment does not attempt to qualify arbitrary measurements, tie behavior, tolerances, or quantization policy. Exact equality is appropriate here only because the synthetic contract was designed to make it appropriate.
Test meaning separately from dtype and roundtrip equality
Two cases dismantle common heuristics. Case B shows that input == decoded_readback can be true for a bad file. Case F shows that input.dtype can be integer for a good physical-value write. In F, the producer supplies PHYSICAL.astype(np.int16), so the array contains integer-valued numbers [250,260,270,280] but still means physical kelvin. With automatic scaling enabled, the file stores [0,20,40,60] and decodes to the approved physical values.
Therefore, “integers are already packed” is false. Integer dtype answers a storage/computation question; representation answers a semantic question. Likewise, “the readback matches the submitted array” is incomplete because a scaling-aware writer and a scaling-aware reader can compose to an identity on the submitted numbers even when the intermediate stored domain is wrong for the intended science.
The validation pattern is similar in spirit to coordinate-label and transformation validation: metadata labels, transformations, and numeric arrays have to be checked against an independent contract rather than against one another in a self-confirming loop. That linked article concerns CRS assignment and coordinate transformation, not NetCDF value packing, and no coordinate math is reused here.
Keep values and units attached to every comparison
Evidence should label each array by domain, not merely print brackets. Write “producer input: packed codes [0,20,40,60],” “stored raw codes: [-500,-460,-420,-380],” or “decoded physical values: [0,20,40,60] K.” CF says units represent unpacked values, which is precisely why the last label exposes Case B: numerically it matches the input, but semantically it says 0 to 60 K, not the intended 250 to 280 K. Numbers without representation and units are not sufficient acceptance evidence.
Prove that changing a flag after writing is not recovery
Case E answers a subtle but frequent recovery mistake. The producer assigns packed codes [0,20,40,60] while default scaling is still enabled, so the automatic writer has already transformed them into [-500,-460,-420,-380]. Only after that assignment does the code call var.set_auto_scale(False).
The fresh post-close raw reader still sees [-500,-460,-420,-380], and the fresh decoded reader still sees [0,20,40,60]. The later method call changes how that variable object will handle subsequent I/O operations; it does not retroactively rewrite samples already assigned. The API documentation describes the method as turning automatic scaling on or off and separately describes the transformation used when data is written. The ordering in Case E demonstrates the practical consequence.
That is why “turn scaling off” is not a repair statement. To replace already-written values, a producer would need an intentional new write whose source values and representation are trusted, followed by the same independent inspection. In this article, the safer recovery policy is stronger: preserve the failed artifact or its evidence record, then reconstruct a fresh candidate from approved source values. Do not edit attributes or flip flags until the output looks plausible; that risks making a wrong file more self-consistent without restoring provenance.
A normal close and successful reopen add no claim about transactional recovery. They show only that the incorrect values persisted through the tested close/reopen path. If a production release also requires atomic switching, rollback, fsync semantics, object-store versioning, or crash recovery, those are separate engineering controls not exercised here.
Reconcile attributes as well as raw and decoded arrays
Case G prevents the opposite false positive: trusting correct stored codes while ignoring metadata. The writer deliberately stores the approved raw codes [0,20,40,60] with scaling disabled, but writes add_offset=200.0 instead of the declared 250.0. The raw comparison passes. The decoded reader, however, returns [200,210,220,230], so the physical contract fails.
This follows directly from the affine convention: packed values are multiplied by scale_factor and then have add_offset applied. Correct codes are only meaningful relative to correct encoding metadata.
The fixture therefore reconciles all of these fields for every candidate: variable dtype int16; shape [4]; dimension name sample; units K; scale_factor=0.5; add_offset=250.0; scale_factor dtype float64; add_offset dtype float64; and explicit _FillValue=-32768. CF's packed-data section requires the scale and offset attributes to share the unpacked data type, while NetCDF-C states that fill and valid-range-style metadata for packed variables belong in the packed domain. Here the fill marker is checked only as metadata; no sample equals it, so this is not a test of missing-value behavior.
The same boundary discipline appears in GeoTIFF validity-mask delivery checks, where component completeness is a different acceptance problem. That article is about TIFF-plus-mask packaging and valid-pixel identity; the present experiment stays inside one NetCDF variable's affine value encoding.
Correct codes do not authorize candidate metadata
The independent contract says offset 250.0. Case G says 200.0. The candidate cannot vote itself correct by combining its own raw codes with its own offset and producing internally consistent numbers. Acceptance compares both pieces against externally authored expectations. Passing this packing-specific metadata/value contract also does not certify the whole file as CF compliant; CF 1.12 contains many requirements outside this laboratory's scope.
A compact acceptance table makes that separation explicit:
Evidence item | Required value | Why it is checked |
Storage dtype | int16 | Confirms packed storage type |
Shape / dimension | [4] / sample | Confirms fixture schema |
Raw codes | [0, 20, 40, 60] | Confirms stored representation |
scale_factor | float64 0.5 | Confirms affine scale and type |
add_offset | float64 250.0 | Confirms affine origin and type |
Units | K | Names the unpacked physical domain |
_FillValue | int16 -32768 | Confirms declared marker metadata only |
Decoded values | float64 [250, 260, 270, 280] | Confirms consumer-visible physical contract |
Scalar oracle | same physical literals | Cross-checks decoding arithmetic outside netCDF read logic |
Notice that the scalar oracle is deliberately asymmetric with the two file reads. Both raw and decoded arrays still come through the installed netCDF4 stack, so agreement between them is not complete implementation independence. The simple Python arithmetic adds a third check on the affine relationship without invoking another netCDF decoder. It still does not establish provenance: the oracle can say whether observed codes map to the approved physical literals, but it cannot tell whether those approved literals were the right scientific source values in the first place. That boundary is why acceptance retains both numerical evidence and a producer declaration.
Reject ambiguous or invalid input before file creation
The qualified_write wrapper turns representation into a required producer declaration. It accepts only physical or packed. It then converts the supplied values with np.asarray, requires shape (4,), and requires all values to be finite. For packed input it additionally requires integral values, int16 range compliance, and absence of the fixture's fill marker. For physical input it computes prospective codes with the fixed OFFSET and SCALE, then requires those codes to be integral, within int16, and not the fill marker.
Cases J through M exercise four pre-file failures. J provides no valid representation. K provides only three physical values. L provides packed input containing 20.5, which is not an integral code. M provides packed code 40000, outside signed 16-bit range. In every supplied measured case, qualified_write raises ValueError before write_candidate is called, and the fixture asserts that the path does not exist. The decision is HOLD_BEFORE_FILE_CREATION.
That distinction is useful in production design. A known-invalid producer request should be rejected before creating a candidate artifact; a candidate that was created and then fails inspection is a different event and should retain enough evidence for diagnosis. The wrapper also prevents a caller from outsourcing the representation decision to dtype inference.
But it is deliberately bounded, not a universal NetCDF validator or hardened parser. It does not qualify arbitrary object arrays, unusual NumPy subclasses, hostile Python objects, all possible broadcasting behavior, arbitrary metadata, every integer overflow policy, general floating-point quantization, missing-data semantics, _Unsigned, compression, parallel I/O, or xarray encoding. Those would need their own requirements and tests. NetCDF-C explicitly discusses rounding for integer packing, but because this fixture accepts only exactly representable physical values, it cannot justify a general rule for off-grid measurements.
Producer-side validation should therefore be phrased narrowly: “this input satisfies the declared four-sample fixture contract,” not “this input is scientifically correct.” Provenance is still external. The wrapper can reject ambiguity; it cannot discover which source values were authoritative.
Rebuild from retained trusted values and inspect again
Cases H and I implement the recovery policy. H starts from trusted physical values and declares representation="physical"; automatic encoding produces the approved raw codes. I starts from trusted packed codes and declares representation="packed"; scaling is disabled before assignment and the same approved codes are stored. Both fresh candidates are then inspected through the same raw reader, decoded reader, metadata checks, and scalar oracle. The supplied run reports ACCEPT_FIXTURE for both.
That is the appropriate recovery from detected NetCDF packing readback mismatch or double packing: reconstruct from an approved source whose representation and values are known. Do not blindly invert the suspicious file. If the producer cannot establish whether [0,20,40,60] originally meant codes or kelvin, algebra alone cannot recover provenance. Likewise, if the authoritative offset or units are unknown, making the candidate internally consistent is not the same as restoring the intended quantity.
Use HOLD when authoritative source values, representation, metadata, or complete evidence cannot be obtained. REBUILD_FROM_TRUSTED_SOURCE applies when the candidate is known to contradict the contract and an approved source exists from which a clean candidate can be regenerated. Restoring a previously approved artifact, repointing a production consumer, or rolling back a deployment may be sensible release actions, but their atomicity and operational safety are not measured here.
Reopen both views before accepting the replacement
A replacement is not accepted because Dataset.close() returned normally or because qualified_write did not raise. Require the complete sequence: close the writer, open a fresh raw handle, disable masking/scaling and read the stored codes; close it; open a second fresh handle, disable masking only and read decoded values; reconcile metadata; run the scalar affine oracle; and retain the complete JSON record. For this fixture, every accepted candidate must show exact codes [0,20,40,60] and exact decoded values [250,260,270,280] with the declared metadata.
Assign the acceptance decision to the pipeline owner
The final decision belongs to the accountable producer/consumer pipeline owners, not to the library. A practical decision matrix for this fixture is:
Condition | Decision | Required action |
Declared representation is valid; metadata matches; raw codes match; decoded K values match; scalar oracle matches; evidence complete | ACCEPT_FIXTURE | Approve this synthetic candidate for the stated contract |
A produced file contradicts the approved raw, decoded, or metadata contract, and trusted source values are available | REBUILD_FROM_TRUSTED_SOURCE | Preserve evidence, create a fresh candidate from the approved representation, then rerun acceptance |
Representation or other declared input is missing/invalid before a file is created | HOLD_BEFORE_FILE_CREATION | Reject the request without creating the candidate |
Authoritative source values/metadata or complete run evidence cannot be obtained | HOLD | Do not promote, repair by guesswork, or infer provenance from the candidate |
For this exact supplied contract and commissioning evidence, A, C, F, H, and I are ACCEPT_FIXTURE; B, D, E, and G require rebuild; J through M hold before creation. The phrase “accept” is intentionally scoped. It does not mean the file is fully CF compliant, scientifically calibrated, durable under failure, or operationally deployable in every consumer.
The concerns in a broader SAR ingestion workflow include acquisition, metadata interpretation, processing and validation across much larger pipelines. This page does not borrow its mission or calibration claims; it uses that link only to locate this small producer/consumer contract within wider remote-sensing engineering.
Revalidate this packing laboratory whenever a change could alter the contract or conversion path: writer API or scaling mode, input representation rules, storage dtype, scale or offset, units/schema, consumer decoding behavior, Python package versions, or linked netCDF-C/HDF5 versions. Unidata's documentation makes clear that auto-conversion behavior is an API feature, not a new 2026 file-format innovation. A revalidation trigger does not automatically mean the old file became wrong; it means the previous evidence may no longer cover the new producer/consumer path. The owner should rerun the bounded fixture or an appropriately revised one, record the new runtime rather than copying old version labels, and compare the observed matrix with the approved contract. If a later reproduction differs, report the difference and investigate it instead of silently editing expected values until the test passes.
Develop reproducible Earth-observation data practice
This four-value experiment is small, but the engineering habit scales: declare representation before transformation, preserve independent expected values, inspect both storage and consumer-facing views, record the actual runtime, and make recovery depend on trusted provenance. Those habits fit the wider Earth-observation engineering responsibilities of building repeatable processing and validation workflows, while remaining distinct from the broader career discussion on that page.
Refonte Learning's Remote Sensing Scientist/Engineer program is listed as three months at 10 to 12 hours per week and covers preprocessing, radiometric/atmospheric correction, time-series analysis, geospatial machine learning, and cloud Earth observation. Its page explicitly names Python, GDAL/OGR, rasterio, geopandas and xarray, and describes an applied capstone with reproducible reporting/code. Those statements do not establish that this exact netCDF4 packing laboratory or these package versions are taught. For practitioners building stronger Python preprocessing and reproducible Earth-observation projects, the program is a relevant next place to evaluate without assuming a particular internship placement, eligibility outcome, or job result.