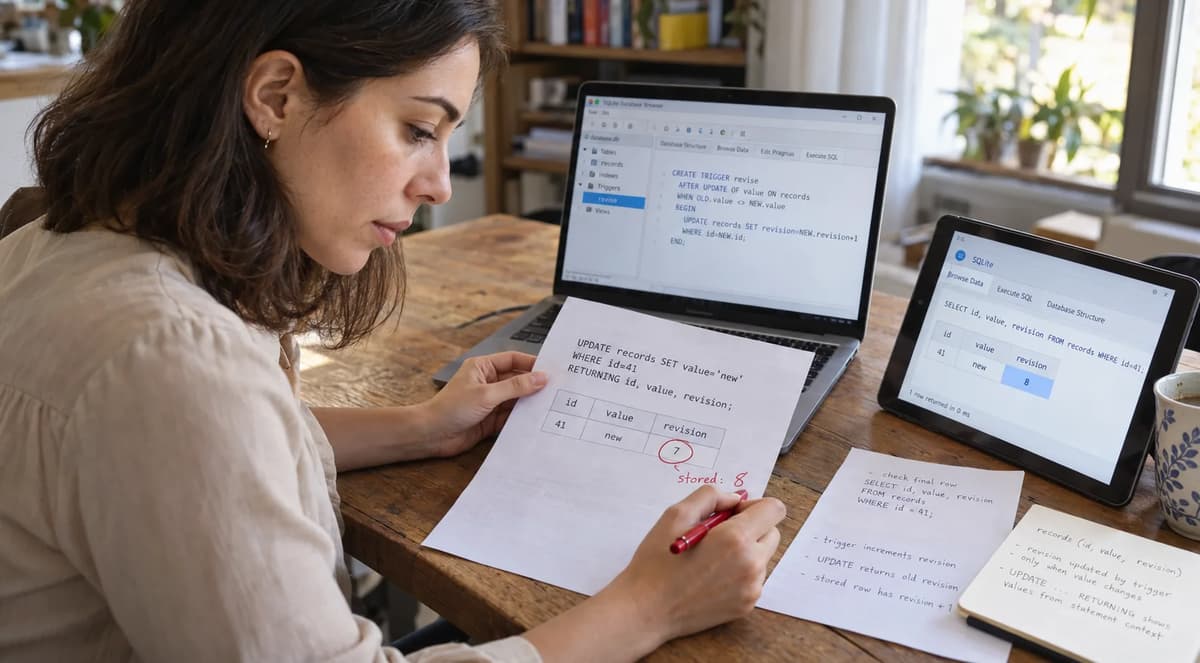
An ordinary one-row UPDATE ... RETURNING can give a backend a tuple that is internally consistent, fully fetched, and still wrong for the response contract the application actually cares about. In the commissioning run at the center of this playbook, case D02 updates row 41 from old to new. The top-level command returns (41, 'new', 7). An AFTER UPDATE OF value trigger then increments the stored revision, so the same transaction reads (41, 'new', 8). COMMIT succeeds, a fresh read-only connection later observes revision 8, and the Python tuple captured from RETURNING remains revision 7. That is expected SQLite behavior, not evidence of corruption: SQLite documents that RETURNING reports values seen by the top-level statement and does not include subsequent changes made by triggers.
The engineering question is therefore not “did UPDATE affect one row?” It is: what is this response allowed to mean? If the caller requires the stored row after the trigger, the command-reported tuple is insufficient in D02. If a deliberately narrower contract says “receipt from the top-level command,” the tuple may be valid, but it must be named that way and must not masquerade as the final stored revision. If the required row is missing or differs from the independently declared expected tuple, the response must be held.
The scope here is intentionally bounded: CPython 3.12.14 linked to SQLite 3.53.1, one disposable local file per case, one synchronous caller, an ordinary table with a stable integer key, explicit SQL transactions, journal_mode=DELETE, recursive_triggers=ON, and no concurrent writer. The supplied laboratory was commissioned as a dated diagnostic run on October 31, 2026; this article does not claim an independent rerun. The goal is a practical response decision, not a universal statement about durability, concurrency, ORMs, drivers, or distributed publication.
Define what a returned revision is allowed to represent
Start with the caller contract, not with the convenience of the SQL syntax. In this playbook, a changed-row request means exactly one stable requested ID, value new, and a revision that represents the row after the chosen trigger has applied its revision rule. For the normal revision trigger, that desired tuple is (41, 'new', 8). That contract is materially different from “return whatever the top-level UPDATE reports.”
This is also deliberately not another batch identity problem. Refonte Learning’s earlier article on keyed SQLite batch receipts addresses mapping batch inputs to generated IDs and the limits of lastrowid/executemany. Here there is one stable key and one ordinary UPDATE; the uncertainty is the field values represented by the response after an AFTER trigger, not which row the caller meant. The neighboring article itself makes the useful distinction that a RETURNING row is statement evidence, while transaction resolution is separate evidence.
That gives the backend three legitimate choices. It may build a checked stored-row response by selecting the row inside the still-owned transaction and validating the entire tuple against an independent expectation. It may intentionally expose a top-level-command receipt, provided the API names that narrower meaning and consumers do not treat it as post-trigger state. Or it may hold the response contract when the expected row is absent, has the wrong values, or cannot be tied to a successful transaction outcome.
Do not collapse these choices into a row-count rule. A one-row RETURNING result can still be stale, D07 proves it can coexist with a row that the trigger subsequently deletes, and D04 proves a correct provisional readback can later be rolled back. SQLite’s RETURNING documentation separately states that returned output is not itself a commit event; in an explicit transaction, changes remain pending until transaction resolution.
Establish the row identity and independent expected state
The fixture begins with an authored baseline:
(41, 'old', 7)For the standard revision-trigger cases, the declared changed row is independently authored as:
(41, 'new', 8)That independence matters. A validator that runs SELECT, receives (41, 'new', 9), and then decides “9 must be correct because that is what the database returned” is not validating a response contract; it is merely echoing observation. D06 exists to catch exactly that mistake. Its trigger increments by two, the readback becomes (41, 'new', 9), and the gate rejects it because the intended contract was revision 8.
The stable primary key is equally important. Row 41 remains row 41 throughout the qualified cases, so the same-transaction readback can use WHERE id=? without a second identity-reconciliation problem. That is a narrow assumption, not a generic property of trigger-driven writes. If a trigger can change the lookup key, fan a write into several response rows, or redirect identity through another table, this validator is no longer qualified.
This is the same discipline that broader SQL result contracts and data grain require: state the expected key, row grain, and output meaning before interpreting query results. Refonte’s SQL article recommends declaring output grain and key semantics so reviewers can compare actual results with an explicit expectation rather than infer intent after the fact.
For changed-row cases, acceptance therefore requires all of the following at once: exactly one candidate tuple; the requested ID 41; the expected logical value new; and the expected revision 8. Full tuple equality is stronger than row count, existence, or “revision increased.” The fixture’s UPDATED constant is authored before execution and is never copied from the observed table.
D08 is intentionally different. Its request value is old, matching the baseline. The trigger has WHEN OLD.value <> NEW.value; because that predicate is false, no revision bump is expected. (41, 'old', 7) is therefore the correct tuple for that one no-change request. It is not a fallback that would permit a changed-row request to settle for the old state.
Pin the trigger and the transaction owner
Environment identity is part of the evidence. The commissioning record names CPython 3.12.14 and the separately linked SQLite 3.53.1. Python exposes the linked SQLite runtime version through sqlite3.sqlite_version; that value is distinct from the Python interpreter version, so both belong in the ledger. The autocommit connection argument was added in Python 3.12.
Each case creates a fresh file, forces PRAGMA journal_mode=DELETE, enables PRAGMA recursive_triggers=ON, creates an ordinary table, inserts the same baseline, and stores the trigger DDL in sqlite_schema. The ordinary revision trigger is conceptually:
CREATE TRIGGER revise
AFTER UPDATE OF value ON records
WHEN OLD.value <> NEW.value
BEGIN
  UPDATE records
  SET revision = NEW.revision + 1
  WHERE id = NEW.id;
END;
SQLite documents the pieces that matter here. UPDATE OF value means the trigger is eligible when value appears on the left side of the top-level SET list. For UPDATE triggers, both OLD.column and NEW.column are available, and a WHEN clause controls whether the trigger body executes. AFTER places the trigger action after the row modification associated with the triggering statement.
The Python connections use autocommit=True, but the unit of work is still explicit SQL: BEGIN, the update and readback, then COMMIT or ROLLBACK. Python’s sqlite3 documentation says that with autocommit=True, Connection.commit() and Connection.rollback() have no effect; explicit SQL transaction control is therefore intentional here. Connection.in_transaction is used as a low-level check that the SQL transaction is active or resolved at the expected points.
That setup keeps transaction ownership visible. There is one caller, no pool, no callback that can resolve someone else’s unit of work, and no executescript() entry path. The laboratory does not test concurrent writers, lock escalation, crash recovery, WAL behavior, busy handling, or commit-failure injection. Those omissions are not defects in the experiment; they are the boundary that lets the eight cases answer one precise question about response semantics.
Run the eight-case laboratory
The source below is the commissioned fixture exactly. Its recorded SHA-256 is f1594b846e5de19a39ad5d37ddae5922b308a873fd1e3b6e66ff628a21e187d7. The commissioning note reports execution on October 31, 2026 at 07:15 UTC under CPython 3.12.14, SQLite 3.53.1 and Linux, producing PASS_8_CASES with exit code 0. This article does not claim to have independently rerun that exact runtime; a source or runtime change needs a fresh qualification rather than inheriting the old pass.
Run command:
python db_returning_fixture.py > db_returning_results.json"""Owned SQLite UPDATE RETURNING versus AFTER-trigger readback laboratory."""
import hashlib, json, platform, sqlite3, tempfile
from datetime import datetime, timezone
from pathlib import Path
BASELINE = [(41, 'old', 7)]
UPDATED = [(41, 'new', 8)]
SELECT = 'SELECT id, value, revision FROM records WHERE id=?'
UPDATE = 'UPDATE records SET value=? WHERE id=? RETURNING id,value,revision'
def require(ok, label):
if not ok:
raise AssertionError(label)
def trigger_sql(kind):
if kind == 'none':
return None
action = ('DELETE FROM records WHERE id=NEW.id;' if kind == 'delete'
else 'UPDATE records SET revision=NEW.revision+' +
('2' if kind == 'plus2' else '1') + ' WHERE id=NEW.id;')
return ('CREATE TRIGGER revise AFTER UPDATE OF value ON records '
'WHEN OLD.value <> NEW.value BEGIN ' + action + ' END;')
# Expected records are authored literals, never copied from the observed table.
CASES = [
('D01', 'none', 41, 'new', 'receipt', 'COMMIT',
[(41, 'new', 7)], [(41, 'new', 7)], [(41, 'new', 7)], True),
('D02', 'plus1', 41, 'new', 'receipt', 'COMMIT',
[(41, 'new', 7)], UPDATED, UPDATED, False),
('D03', 'plus1', 41, 'new', 'readback', 'COMMIT',
[(41, 'new', 7)], UPDATED, UPDATED, True),
('D04', 'plus1', 41, 'new', 'readback', 'ROLLBACK',
[(41, 'new', 7)], UPDATED, BASELINE, True),
('D05', 'plus1', 999, 'new', 'readback', 'ROLLBACK',
[], [], BASELINE, False),
('D06', 'plus2', 41, 'new', 'readback', 'ROLLBACK',
[(41, 'new', 7)], [(41, 'new', 9)], BASELINE, False),
('D07', 'delete', 41, 'new', 'readback', 'ROLLBACK',
[(41, 'new', 7)], [], BASELINE, False),
('D08', 'plus1', 41, 'old', 'readback', 'COMMIT',
BASELINE, BASELINE, BASELINE, True),
]
def exercise(directory, spec):
identity, kind, key, value, policy, ending, er, es, ef, eg = spec
path = directory / (identity + '.sqlite')
db = sqlite3.connect(path, autocommit=True)
try:
journal = db.execute('PRAGMA journal_mode=DELETE').fetchone()[0]
db.execute('PRAGMA recursive_triggers=ON')
recursive = db.execute('PRAGMA recursive_triggers').fetchone()[0]
require(journal == 'delete' and recursive == 1, identity + ' settings')
db.execute('CREATE TABLE records(id INTEGER PRIMARY KEY, value TEXT NOT NULL, revision INTEGER NOT NULL)')
db.executemany('INSERT INTO records VALUES(?,?,?)', BASELINE)
ddl = trigger_sql(kind)
if ddl:
db.execute(ddl)
schema = db.execute("SELECT name,sql FROM sqlite_schema WHERE type='trigger' ORDER BY name").fetchall()
require(db.execute('SELECT * FROM records').fetchall() == BASELINE, 'baseline')
db.execute('BEGIN')
cursor = db.execute(UPDATE, (value, key))
returned = cursor.fetchall()
cursor.close()
stored = db.execute(SELECT, (key,)).fetchall()
require(returned == er and stored == es, identity + ' observed rows')
require(db.in_transaction, identity + ' provisional state')
candidate = list(returned if policy == 'receipt' else stored)
expected_candidate = ([(41, 'new', 7)] if kind == 'none' else
BASELINE if value == 'old' else UPDATED)
gate = len(candidate) == 1 and candidate == expected_candidate
require(gate == eg, identity + ' candidate gate')
db.execute(ending)
require(not db.in_transaction, identity + ' end state')
finally:
if db.in_transaction:
db.execute('ROLLBACK')
db.close()
reader = sqlite3.connect(path.as_uri() + '?mode=ro', uri=True, autocommit=True)
try:
reopened = reader.execute('SELECT id,value,revision FROM records ORDER BY id').fetchall()
finally:
reader.close()
require(reopened == ef, identity + ' reopened state')
# D02 intentionally commits a correct row while retaining a stale receipt.
published = candidate if gate and ending == 'COMMIT' and candidate == reopened else []
if identity == 'D02':
require(returned != reopened and published == [], 'commit does not rewrite receipt')
if identity == 'D04':
require(candidate == UPDATED and published == [], 'rollback invalidates candidate')
decision = ('ACCEPT_COMMITTED_SNAPSHOT' if published else
'DISCARD_ROLLED_BACK_CANDIDATE' if gate else 'HOLD_RESPONSE_CONTRACT')
return {'case': identity, 'trigger': kind, 'trigger_schema': schema,
'journal_mode': journal, 'recursive_triggers': recursive,
'requested_key': key, 'returning': returned, 'same_transaction_readback': stored,
'candidate_policy': policy, 'candidate': candidate, 'candidate_gate': gate,
'transaction_end': ending, 'reopened': reopened, 'published': published,
'decision': decision, 'status': 'PASS'}
if name == '__main__':
started = datetime.now(timezone.utc).isoformat()
require(sqlite3.sqlite_version_info >= (3,35,0), 'RETURNING support required')
with tempfile.TemporaryDirectory(prefix='refonte-returning-') as owned:
rows = [exercise(Path(owned), case) for case in CASES]
require([r['case'] for r in rows] == ['D%02d' % i for i in range(1,9)], 'case inventory')
print(json.dumps({'status':'PASS_8_CASES', 'python':platform.python_version(),
'sqlite':sqlite3.sqlite_version, 'platform':platform.platform(),
'started_utc':started, 'finished_utc':datetime.now(timezone.utc).isoformat(),
'source_sha256':hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
'normal_temporary_cleanup_completed':True, 'cases':rows}, indent=2))The fixture first refuses SQLite older than 3.35.0 because that is the release where SQLite introduced RETURNING on March 12, 2021. It also depends on the Python 3.12 autocommit connection argument. SQLite’s maintained RETURNING page records both the feature baseline and the key trigger limitation; this is an established engine behavior being used in a contemporary response contract, not a new 2026 SQLite feature.
Each CASES tuple contains the case ID, trigger kind, requested key, requested value, candidate policy, transaction ending, expected RETURNING rows, expected same-transaction stored rows, expected reopened rows, and expected candidate-gate Boolean. Those expectations are literals or named authored constants. They are not populated from whatever the test happens to observe.
The commissioning ledger is compact enough to review as one matrix:
Case | Trigger/request | RETURNING | Same-transaction readback | End; reopened row | Decision |
D01 | No trigger; new | new/7 | new/7 | COMMIT; new/7 | ACCEPT_COMMITTED_SNAPSHOT |
D02 | +1; new; receipt policy | new/7 | new/8 | COMMIT; new/8 | HOLD_RESPONSE_CONTRACT |
D03 | +1; new; readback policy | new/7 | new/8 | COMMIT; new/8 | ACCEPT_COMMITTED_SNAPSHOT |
D04 | +1; new; readback policy | new/7 | new/8 | ROLLBACK; old/7 | DISCARD_ROLLED_BACK_CANDIDATE |
D05 | +1; key 999 | empty | empty | ROLLBACK; row 41 old/7 | HOLD_RESPONSE_CONTRACT |
D06 | +2; new | new/7 | new/9 | ROLLBACK; old/7 | HOLD_RESPONSE_CONTRACT |
D07 | delete; new | new/7 | empty | ROLLBACK; old/7 | HOLD_RESPONSE_CONTRACT |
D08 | +1; request old | old/7 | old/7 | COMMIT; old/7 | ACCEPT_COMMITTED_SNAPSHOT |
PASS_8_CASES means the observed rows and decisions matched the fixture’s authored expectations. It does not mean every response was accepted. D02, D05, D06 and D07 are passing diagnostics specifically because the policy rejects or holds their candidate. The published field is only a local Python list modeling a decision; there is no HTTP response, event bus, cache, or cross-system atomicity test.
The use of fetchall() and cursor.close() is deliberate: the caller consumes the complete RETURNING result before readback. If execution is interrupted, throws before producing the full JSON ledger, or leaves an expected case missing, the evidence set is incomplete. In a release review, incomplete evidence should be treated as HOLD, not reinterpreted as a successful empty result.
Locate the difference between calculation and emission
D02 is the core case because it separates three events that are easy to conflate. First, the top-level UPDATE changes value to new and its RETURNING expression captures revision 7. Second, the AFTER trigger runs and changes the stored revision to 8. Third, the already computed RETURNING output is delivered to the caller as (41, 'new', 7). SQLite documents both sides of that sequence: all database modification actions occur before RETURNING output is emitted, yet values emitted by RETURNING reflect the top-level statement and do not include subsequent trigger changes.
That distinction resolves the apparent paradox. A fully consumed RETURNING result can disagree with a same-transaction SELECT without either result being “half executed.” The command receipt answers what the top-level statement computed. The readback answers what the connection currently stores after the trigger’s work. They are two different response surfaces over one completed statement inside an unresolved transaction.
The limitation is old enough to be a design constraint, not an edge case introduced by the 2026 runtime. SQLite has supported RETURNING since 3.35.0 in 2021, and the maintained documentation explicitly calls out AFTER-trigger changes.
The trigger does not wait for the next SELECT
Do not narrate D02 as though fetchall(), cursor.close(), the subsequent SELECT, or COMMIT wakes up a deferred AFTER trigger. SQLite says RETURNING output is embargoed until the statement’s database modification actions have completed. The trigger’s revision update has already occurred by the time the application begins receiving those result rows.
fetchall() consumes the result set; cursor.close() releases the cursor; neither is the cause of revision 8. The same-transaction SELECT simply observes the post-trigger row that already exists in the connection’s pending transaction. COMMIT later resolves that transaction. It does not reach backward into Python and rewrite a tuple that was already materialized as (41, 'new', 7).
This timing language matters in reviews. Saying “the trigger runs after fetch” leads developers toward the wrong repair, such as fetching later or adding arbitrary cursor operations. The real repair is contractual: if the response needs post-trigger values, obtain and validate a post-trigger stored-row candidate.
Compare the no-trigger control with the revision trigger
D01 controls the most basic alternative explanation. With no trigger, the update changes value to new, leaves revision 7 alone, and both surfaces agree on (41, 'new', 7). That is correct because this schema has no rule promising a revision increment. D01 is not a production recommendation to remove the trigger; it proves that the mismatch in D02/D03 is introduced by the changed trigger contract, not by tuple comparison, transaction ownership, or the stable-key lookup itself.
D02 and D03 then hold the SQL update constant while enabling the plus1 AFTER trigger. Both receive the same RETURNING tuple, new/7, and both read back new/8. The only policy difference is which evidence becomes the response candidate. D02 chooses the receipt and therefore fails the declared stored-row contract. D03 chooses the readback and passes the tuple gate.
This is distinct from the conflict semantics in Refonte’s article on SQLite replacement and child-row preservation. That neighboring problem is about REPLACE/UPSERT behavior and related-row preservation; this playbook uses a plain stable-key UPDATE and an AFTER trigger that changes revision or, in one negative control, deletes the row. The scopes should not be merged simply because both involve “a write that changes more than expected.”
Keep the statement and trigger responsibilities separate
The statement is responsible for SET value=? WHERE id=?. The normal trigger is responsible for revising revision when OLD.value <> NEW.value. SQLite’s trigger documentation defines OLD and NEW for UPDATE triggers and explains that UPDATE OF value is keyed to the named column appearing in the SET list.
That separation is useful because it stops reviewers from attributing revision 8 to the RETURNING clause itself. RETURNING id,value,revision does not request “the final row after all trigger effects”; SQLite documents the opposite limitation for subsequent trigger changes.
Nothing in this fixture qualifies multiple-trigger ordering, BEFORE-trigger mutation, views, multi-row UPDATEs, or identity-changing triggers. Those are separate response contracts and must be tested separately rather than inferred from this one-trigger ordinary-table result.
Read the intended stored row inside the same transaction
D03 is the positive repair path for a product whose response means “the stored row after this trigger.” The caller fully consumes the UPDATE’s RETURNING result, then, without giving up transaction ownership, executes:
SELECT id, value, revision
FROM records
WHERE id=?;
For key 41, the readback is exactly [(41, 'new', 8)]. The candidate policy chooses that stored tuple, not the stale receipt. The gate then checks both cardinality and complete equality with the independently authored expected row. Only because len(candidate) == 1 and candidate == UPDATED does the provisional candidate pass.
The same connection is important in this bounded design because the transaction is still open. SQLite’s RETURNING documentation distinguishes the statement’s completed modifications from transaction commit: inside an explicit transaction, changes are pending even after the statement has finished. The readback is therefore a view of the writer’s current transaction state, which is exactly the state the owner must validate before choosing COMMIT or ROLLBACK.
Do not turn that into a rule that every UPDATE everywhere needs a follow-up SELECT. If the application’s documented response is a top-level-command receipt and consumers understand that trigger changes are excluded, a readback may be unnecessary. Conversely, if a response must carry post-trigger fields, the SELECT is not optional merely because the RETURNING tuple looked plausible.
The critical word is checked. A readback does not become publishable because it came from the database. The application still owns the expected row semantics. D06 and D07 prove why a SELECT with no independent oracle is only observation, not acceptance.
A stable lookup key is part of the qualification
This validator depends on id=41 remaining the identity of the intended row. The trigger bodies modify only revision or delete that same ID; they never rewrite the key. That makes a single equality check over one lookup sufficient for this experiment.
If trigger code can change the key, insert replacement rows under new keys, update several logical records, or return a response assembled from more than one row, the one-key predicate is no longer enough. The correct response is not to generalize len(candidate) == 1 until it happens to pass. The correct response is to redesign the oracle around the actual identity contract and requalify the new workflow.
The same caution applies to batches and multi-row statements. This article explicitly excludes result ordering, executemany identity reconstruction, and multi-row UPDATE behavior. A one-row stable-key validator is strong because its assumptions are narrow and visible.
Refuse absent rows and unexpected trigger effects
D05, D06 and D07 are the refusal controls that prevent “read it back” from turning into “trust whatever came back.” They fail for three different reasons, and those reasons should remain distinguishable in logs and review.
D05: no matching requested key. The request uses ID 999. The top-level UPDATE matches nothing, RETURNING is empty, and the same-transaction readback for 999 is empty. Row 41 remains at the baseline. A zero-row result here is not a successful response carrying an empty object; it is evidence that the required row contract was not met.
D06: wrong trigger result. The trigger is deliberately altered to add 2 instead of 1. RETURNING is still (41, 'new', 7), but stored readback is (41, 'new', 9). Cardinality alone would pass. A loose “revision increased” check would also pass. Exact tuple equality correctly rejects the row because the declared expected revision is 8.
D07: row deleted after the top-level UPDATE. The command still reports (41, 'new', 7), but the AFTER trigger deletes row 41. The same-transaction readback is empty. This is the strongest demonstration that a nonempty RETURNING tuple cannot prove the required row exists after trigger processing. SQLite explicitly says RETURNING reports rows directly modified by the top-level statement and not additional changes caused by triggers.
All three cases roll back. That is a fixture policy chosen to keep failed response semantics from becoming committed state while preserving the distinction among no match, unexpected trigger logic, and deliberate deletion. D02 is the intentional diagnostic exception: it commits correct stored data despite a stale response candidate to prove that commit does not repair the response tuple.
Choose the refusal before publishing a response
The gate is intentionally small:
gate = len(candidate) == 1 and candidate == expected_candidateThe first half rejects absence and multiplicity. The second half rejects the wrong ID, wrong value, or wrong revision even when there is exactly one row. D06 is why both halves are necessary.
HOLD_RESPONSE_CONTRACT is a local decision label, not a universal incident taxonomy. It means the fixture lacks evidence to release the required response under its declared semantics. It does not claim every missing row is a security issue, every unexpected trigger is data corruption, or every application must roll back in the same way.
The operational principle is narrower: do not publish a success-shaped response first and investigate its row semantics later. Decide whether the evidence meets the contract while the transaction owner still controls the outcome whenever the workflow allows that decision.
Resolve the transaction before releasing a checked candidate
D03 has a provisional candidate (41, 'new', 8) that passes the stored-row gate, but the fixture still does not model it as published until after COMMIT. Once SQL COMMIT finishes, the connection reports no active transaction. A new mode=ro connection opens the same file and reads (41, 'new', 8). Only when the checked candidate equals that reopened observation does the local published list contain the row.
SQLite’s transaction documentation says a manually started transaction ordinarily persists until COMMIT or ROLLBACK. The RETURNING documentation separately warns that statement modifications inside an explicit transaction are not the same thing as committed database state. Those boundaries justify treating the same-transaction readback as provisional evidence and the resolved transaction as a separate stage.
D02 proves why successful commit is not enough to rehabilitate the wrong candidate. Its stored row is correct at revision 8 and that correct row commits. But its candidate policy kept the original RETURNING receipt (41, 'new', 7). The fresh reader sees revision 8, the candidate does not match, and published remains empty. This is the article’s central diagnostic: correct data can commit while the response tuple originally captured by the application remains stale.
The explicit ownership model is intentionally held constant, unlike the separate problem covered in Python executescript transaction boundaries. That article tests an API entry path that can cross a pending transaction boundary under legacy control. Here, no executescript() call exists; the mismatch appears inside a valid caller-owned SQL transaction because RETURNING excludes subsequent AFTER-trigger value changes.
Commit cannot refresh a tuple already held by the caller
Once Python has materialized (41, 'new', 7), COMMIT changes the transaction outcome, not the historical contents of that Python object. SQLite’s RETURNING rule says the emitted values are those seen by the top-level statement, excluding subsequent trigger changes, while its transaction rules make commit a separate boundary.
The fresh read-only connection is therefore evidence about the database after resolution, not a mechanism that transforms the earlier receipt. In this quiescent lab it confirms that D03’s checked candidate matches the committed row and D02’s receipt does not.
Do not overstate that observation. The fixture does not test a failed COMMIT, filesystem crash durability, concurrent writers changing the row immediately after commit, external event delivery, cache publication, or atomicity between SQLite and another system. A reopened read proves one bounded post-resolution snapshot under the recorded local conditions. It is not a claim that the row can never change again.
Invalidate provisional candidates on rollback
D04 is the necessary counterweight to D03. It performs the same update and the same valid readback: RETURNING is new/7, the trigger leaves new/8, and the readback candidate exactly matches the expected tuple. The candidate gate passes. Then the case deliberately executes SQL ROLLBACK.
After rollback, a new read-only connection sees the baseline (41, 'old', 7). The local published list remains empty and the decision is DISCARD_ROLLED_BACK_CANDIDATE. This is why “the SELECT was correct when we ran it” is not enough. A same-transaction candidate is evidence about pending state. If the owner later chooses rollback, that candidate can remain useful diagnostically, but it cannot be represented as the successful stored outcome of the transaction.
SQLite’s transaction page defines the manual transaction boundary in terms of BEGIN persisting to COMMIT or ROLLBACK, and Python’s in_transaction exposes whether the low-level SQLite transaction is active. The fixture checks the flag before and after resolution so a response decision cannot quietly ignore transaction state.
D08 is a separate control. The requested value is old, which equals the baseline. Because the trigger predicate is OLD.value <> NEW.value, its body does not run. RETURNING, readback and reopened state all remain old/7, and that result is accepted because it is the declared expected state for the no-change request. SQLite’s trigger documentation states that a WHEN clause executes the trigger body only when the expression is true.
Keep the no-change control distinct from a failed update
An application may legitimately define “set the value to its current value” as a successful idempotent request. D08 shows one such contract: request old; expect old/7; commit that unchanged row. That does not imply every unchanged result should be accepted.
For D03, the request is explicitly new and the expected post-trigger row is new/8. If readback instead yielded old/7, it would fail the changed-row contract even though old/7 is acceptable in D08. The expected tuple must follow the request semantics, not a generic preference for whichever state is easier to validate.
This distinction also keeps row-count heuristics in their place. A system can choose different success semantics for idempotent updates, conditional updates, or absent rows, but those choices must be explicit. The fixture does not infer them from whether SQLite happened to report a row.
Reconcile one evidence record for every case
A useful test artifact should let a reviewer reconstruct the decision without rerunning the case mentally. For each case, record: case ID; source digest; Python version; linked SQLite version; platform; journal mode; recursive-trigger setting; stored trigger DDL; requested key and value; transaction state before resolution; complete RETURNING tuples; complete same-transaction readback tuples; candidate policy; candidate tuple; gate result; end command; reopened rows; modeled published rows; and final decision.
The fixture already emits most of that structure as JSON. The case inventory check additionally requires exactly D01 through D08 in order. That matters because a file containing only seven passing cases is not “almost the same evidence.” If D07 disappeared after an exception, the strongest proof that a nonempty RETURNING tuple can coexist with an absent stored row would be missing.
Preserve the source hash with the results. The commissioned digest identifies the exact source bytes that produced the supplied observation. A changed trigger, changed expected tuple, changed transaction mode, or apparently harmless refactor creates a different artifact. It may still be correct, but it needs its own run instead of borrowing the old PASS_8_CASES label.
Treat missing evidence as HOLD. An interrupted process that never emits the JSON ledger is not equivalent to returning: []. A Python exception before COMMIT is not equivalent to a recorded rollback unless the transaction state and cleanup are actually observed. The SQLite transaction documentation itself notes that some errors can affect transaction state differently, which is another reason not to infer the final boundary from an exception class alone.
Finally, preserve evidence before converting it into a release judgment. The matrix can demonstrate the documented stale-receipt behavior and the fixture’s policy gates. It cannot by itself authorize a production rollout across untested versions, pooled connections, different trigger DDL, or external publication mechanisms.
Choose the response contract with a decision matrix
There are three defensible product contracts in this narrow design. The right one depends on what the consumer is promised, not on which implementation requires the fewest lines of code.
Product contract | Required evidence | Accept when | Hold when |
Top-level-command receipt | Complete RETURNING tuple plus transaction outcome | The API explicitly defines the fields as values reported by the top-level SQLite statement and does not claim post-trigger state | A consumer requires post-trigger values, the tuple is missing, or transaction outcome is unresolved |
Checked stored-row response | Same-transaction SELECT on stable key, exact independent tuple oracle, then successful resolution | Exactly one stored row equals the predeclared expected tuple and the resolved observation is consistent with the local publication rule | Row absent, wrong tuple, unstable identity, failed/rolled-back transaction, or incomplete evidence |
No success response | Evidence that required row semantics were not met | Never; this is the refusal state | D05 absence, D06 unexpected revision, D07 deletion, incomplete ledger, or any unqualified mismatch |
D02 belongs in the second row’s HOLD column even though the database commits the correct stored row, because its chosen response candidate is the command receipt. D03 demonstrates the checked stored-row path. D01 and D08 show that a receipt or readback can be acceptable when the declared schema/request contract actually makes that tuple correct.
A bounded cross-engine caution helps prevent the wrong analogy. Refonte’s article on PostgreSQL DO NOTHING and missing RETURNING IDs examines a different PostgreSQL concurrency/snapshot problem. PostgreSQL also has different trigger/RETURNING semantics in relevant write paths; its behavior must be read from PostgreSQL’s own documentation, not transferred from SQLite. The neighbor is useful only as a reminder that an empty or surprising RETURNING result has engine-specific causes.
Assign ownership and define requalification triggers
Response correctness crosses schema and backend ownership, so the review responsibilities should be explicit. Schema owners own the trigger contract: what event fires it, what WHEN predicate means, whether it increments by exactly one, and whether it can delete or redirect the row. Backend owners own response semantics: whether the API exposes a top-level receipt or a stored-row representation, when candidates may be released, and what HOLD means to the caller. Reviewers own the independent comparison: they verify that the expected tuple was authored from the requirement rather than learned from the observed database state.
Requalification should be triggered by any change that can invalidate those assumptions. In this fixture that includes trigger DDL; the stable-key policy; the table response schema; the Python transaction-control mode; the linked SQLite build; the use of recursive_triggers; or a change from the explicit SQL transaction pattern. Changing the expected revision rule from +1 to +2 is not a “small schema tweak” for this response contract: it turns D03’s expected row into D06’s rejection case.
A bounded change-review checklist is enough:
Confirm the source digest and runtime identities before interpreting old results.
Compare stored trigger DDL with the approved trigger contract.
Re-run all eight controls, not only the happy path, after a qualifying change.
Require exact tuples for D01 through D08 and the intended transaction end for each case.
Confirm D02 still demonstrates stale receipt plus correct committed row; otherwise investigate the changed behavior rather than rewriting the expected output from observation.
Confirm D04 still invalidates an otherwise correct provisional readback on rollback.
Treat absent JSON, exceptions without a resolved state, or changed case inventory as HOLD.
Keep external API, cache, queue, concurrency and crash claims outside this laboratory unless separately tested.
Rollback and recovery are local transaction decisions here, not deployment procedures. The playbook does not run a migration, patch a production database, inject commit failure, or prove crash durability. It establishes a response-review discipline: isolate the exact row contract, keep transaction ownership explicit, and requalify when a dependency that affects that contract changes.
Develop database validation practice with Refonte Learning
The durable skill in this exercise is not memorizing that “SQLite RETURNING is stale with triggers.” It is learning to read an engine contract precisely, distinguish statement evidence from stored-row evidence, trace trigger effects, keep transaction ownership visible, and refuse to publish a row representation that the evidence does not support. Those habits transfer to database design review, recovery analysis, security-sensitive data handling and performance work because they force engineers to state what must be true before treating a database result as trustworthy.
Refonte Learning’s Database Administrator Essentials page lists database design and architecture, SQL query optimization, backup and recovery, performance tuning, security, cloud database management, migration/integration, disaster recovery, role-based access control, and monitoring among its competencies. It describes a three-month program at 12 to 14 hours per week, recommends basic programming knowledge, and states an admission prerequisite of working toward a bachelor’s or higher-level degree. Its educational path names relational database fundamentals, advanced SQL, and cloud administration using AWS RDS, Azure SQL, and Google Cloud Spanner; the page also states hands-on projects and a potential internship, and says successful completion offers a Training Certificate and Certificate of Internship.
For engineers who want structured practice around those broader database fundamentals, the program is one option to review. The public page does not establish that SQLite, Python sqlite3, AFTER-trigger/RETURNING reconciliation, or this exact laboratory is part of the syllabus, so this article makes no such claim.